🚨BREAKING: Marine Le Pens says those devastating France will be forced to pay for their crimes when she becomes President in a few months time
This is what France wants! 🇫🇷
🚨🇫🇷 FLASH | Le député européen François-Xavier Bellamy réclame la DISSOLUTION de La France insoumise après les violences et accuse le parti de Jean-Luc Mélenchon de faire porter la responsabilité du chaos aux forces de l’ordre, sans condamner les casseurs : « Il faut dissoudre LFI. »
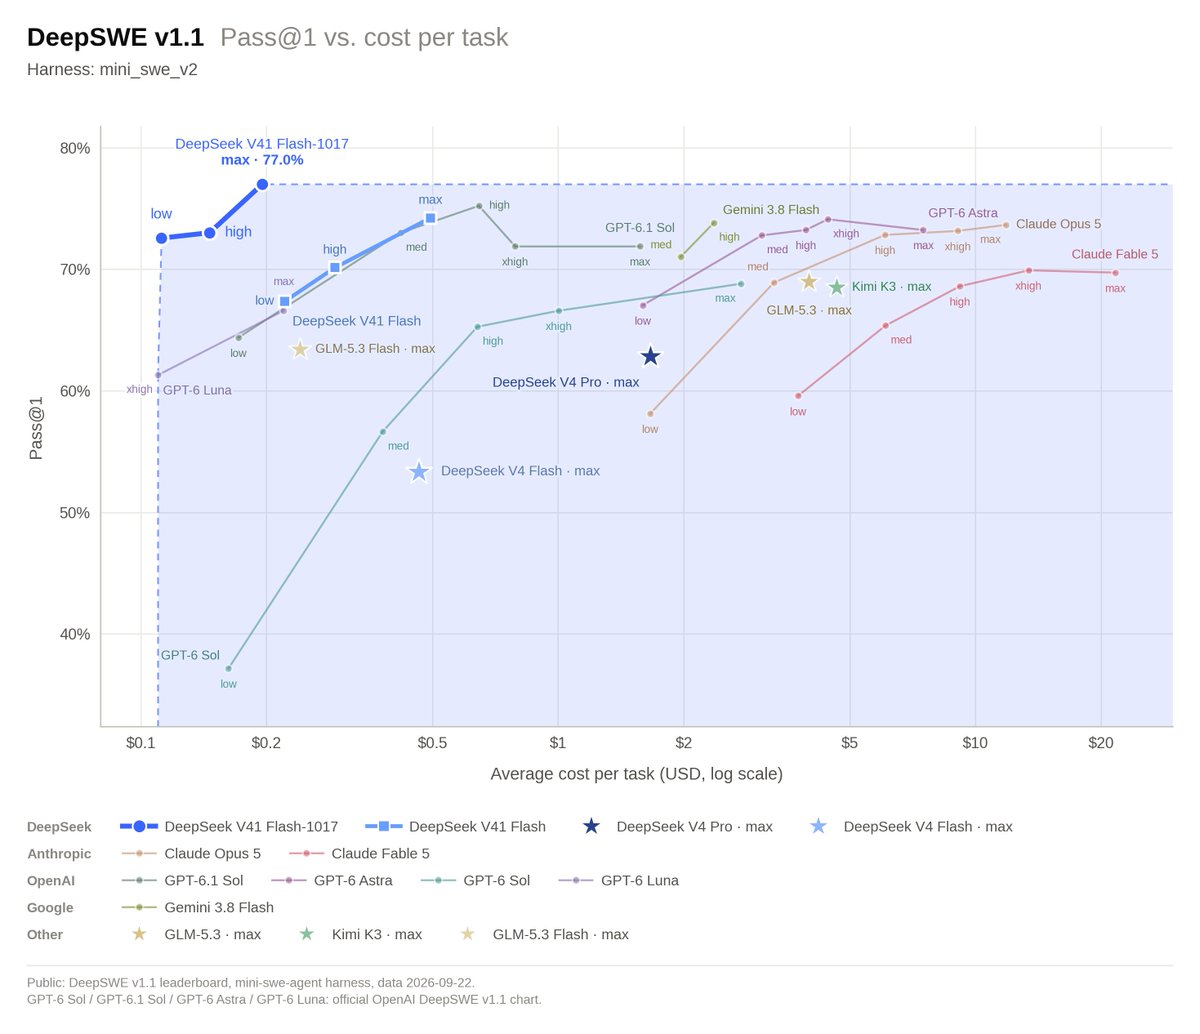
🚀 DeepSeek-V4.1-Flash-1017 is here!
Stronger benchmark performance, faster task completion, and shorter outputs than the previous version—a Pareto improvement in performance and cost. Now live on our website, app, and API.
🛠️ Optimized for @DeepSeekHarness, Tencent CodeBuddy, WorkBuddy, and more. Upgrade to DeepSeek Harness v0.2.1-rc.1 or later for the best experience with the new model.
1/4
Omarchy is installed and running on the M4 MacBook Air, fully. Working out a few kinks I’m finding and then opening up the repo.
#OmarchyLinux#OmarchyMac
Please welcome GPT-6 Sol and GPT-6 Luna to the GPT-6 universe.
GPT-6 Sol and Luna build on the advances behind GPT-6 Astra, bringing much of its strengths into faster and more affordable models to support work at scale.
We’ve also made caching and inference more efficient, and we’re passing the savings directly to you: 50% lower API prices for Sol and Luna compared with GPT‑5.6 promotional pricing.
Grok 4.7 scores 46 on the Artificial Analysis Intelligence Index to bring SpaceXAI into the top 4 AI labs. Coding Agent Index performance has also improved, overtaking GPT-5.6 Sol
Grok 4.7 scores +2 points over Grok 4.6 on the Intelligence Index, with strong performance on agentic knowledge work tasks. We evaluated the new model at xhigh reasoning effort.
Congratulations to @spacexai and @ElonMusk on the release!
Key takeaways:
➤ Grok 4.7 joins the frontier of agentic knowledge work: Grok 4.7 gains +111 Elo over Grok 4.6 (high) on AA-Briefcase, our private benchmark for long-horizon agentic knowledge work, scoring 1657 Elo and placing it alongside Claude Opus 5 and Claude Fable 5.1 at the frontier. On GDPval-AA, it scores 1695 Elo, +90 ahead of Grok 4.6 (high).
➤ A leap in coding agent performance: Grok 4.7 (xhigh) with Grok Build scores 56 on the Artificial Analysis Coding Agent Index, up +9 points from Grok 4.6 (xhigh). Among models in their native harnesses, Grok 4.7 + Grok Build now ranks 4th, behind only Claude Fable 5.1, GPT-6 Astra, and Claude Opus 5.
➤ Incremental performance changes elsewhere: Outside of agentic knowledge work, Grok 4.7 broadly matches Grok 4.6 (high) on the other Intelligence Index tasks. It improves on Terminal-Bench 4.0 (+4.5 percentage points) and GDP.pdf (+3.0 p.p.), with regressions on AA-LCR (-3.7 p.p.) and AutomationBench-AA (-1.1 p.p.).
➤ High token use across tasks: Grok 4.7's gains come with higher token usage. Grok 4.7 (xhigh) uses approximately 81k output tokens per Intelligence Index task, compared with 36k for Grok 4.6 (high) and 27k for GPT-6 Astra (max) - 125% and 196% more, respectively.
Other model details:
➤ Context window of 500k tokens, unchanged from Grok 4.6
➤ Pricing of $2/$6 per 1M input/output tokens with cache hits discounted to $0.50 per 1M tokens, matching Grok 4.6
➤ Configurable reasoning effort spans low to xhigh. Our evaluation uses xhigh.
Today, I’m proud to announce Homebrew 7.0.0.
The most significant changes since 6.0.0 are faster installations, stronger sandboxing, native macOS app, vulnerability checks, advisory database, end of macOS 10.15 support and Intel Macs to Tier 3.
https://t.co/LGnA62Bqd0
Sending lots of love to the Apple community on my last day as CEO. My title changes tomorrow, but the love I have for the Apple community never will. Thank you for being a constant source of inspiration. My gratitude is endless, and I’m excited for the next chapter!
Sold out in 5 hours 🤯
If you missed it, we're giving away 3 Raycast keyboards.
To enter:
1️⃣ Follow @raycast and @nuphystudio
2️⃣ Repost this tweet
3️⃣ Reply with your favorite shortcut
We'll pick 3 winners on Monday. Good luck!
Releasing the model weights and technical report of Kimi K3.
Kimi K3 is our most capable model: a 2.8T MoE model with native visual understanding and a 1M-token context window.
New model architecture: 2.5x the intelligence per unit of compute, not just more params.
Alongside Kimi K3, we're opening up more of the stack behind it — high-performance attention kernels, MoE communication library, and infrastructure for running agent environments at scale.
Model weights: https://t.co/7m7eEg6Y0B
Tech report: https://t.co/yeu6cjpMCT
Tech blog: https://t.co/YTfiMSNM1f
ZAI 🔥: GLM-5.2 by @Zai_org scored 51 point on Artificial Analysis Intelligence Index and got placed on the 4th spot! This made GLM-5.2 a new SOTA open-weight model.
Besides that, GLM-5.2 got ranked second on Frontend Code Arena, after currently unavailable Claude Fable 5.
Should be ZOTA! 👀
GLM 5.2 ranks #3 on FrontierSWE. It is only behind Fable 5 and Opus 4.8, and it outperforms GPT-5.5.
This is the first model that closes the large gap between models from Anthropic / OpenAI and other providers, and it is the strongest open-weight model by far.
GLM-5.2 (Max) by @Zai_org ranks #10 on the new Agent Arena leaderboard, closely matching Claude-Opus-4.8 (non-thinking) and is the #1 open model by a wide margin!
In Agent Arena, we measure models on millions of real-world, long-horizon agentic tasks from a global community of users. Models can access web search, filesystem, and terminal tools to complete complex workflows. The leaderboard measures model performance on outcomes relative to the average model using a causal tracing methodology.
Compared to 5.1, GLM-5.2 (Max) climbs from #13 to #10. Its clearest gains are confirmed task success, and user praise vs. complaint. Bash capabilities and tool hallucination remain stable. There is a tradeoff in steerability compared to the previous model (-6.0% vs. +1.2%).
GLM-5.2 remains the same price as GLM-5.1, $1.4/$4.4 per input/output MTokens. 1M context window.
Huge congrats @Zai_org for the incredible release!
See thread for details on how GLM-5.2 (Max) performs across 5 different signals.
Introducing GLM-5.2: Frontier Intelligence, Open Weights
- Significant improvements in coding and agentic tasks
- Strong long-horizon capabilities with a 1M context window
- Two levels of reasoning effort: GLM-5.2 (max) pushes the limits, while GLM-5.2 (high) strikes a strong balance between performance and token efficiency
- MIT-licensed open weights
- Same API pricing as GLM-5.1
Tech Blog: https://t.co/LAsxUdN0JZ
Weights: https://t.co/g0A1C4UWx4
API: https://t.co/Kc3E22cbN7
Coding Plan: https://t.co/Nk8Y98HNhU
Chat: https://t.co/WCqWT0qCQb