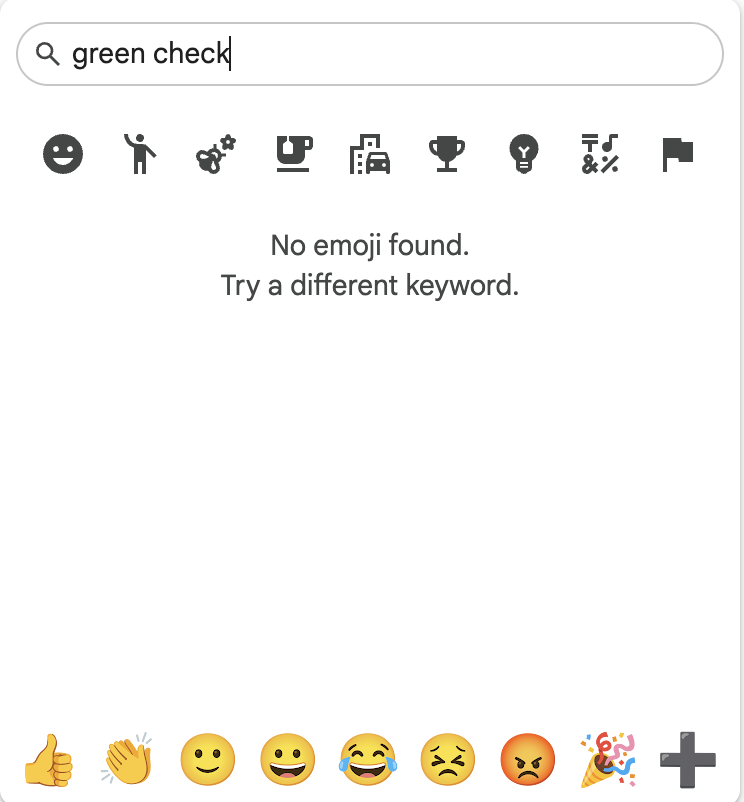
Google integrated Gemini into every single place inside Google Workspace where it doesn't work, and nowhere where it would be useful
Like the emoji picker, so I could find this green check emoji ✅
Does anyone still work at Google who cares about UX, or users, in general?
And what happens when some tests started failing after migration? Who is gonna investigate which weird "feature/bug" of enzyme made the test passed previously and now who is gonna read the business logic of the application to rewrite the test? It's absolutely insane to claim this can be done by a dev in two weeks.
And the companies do the math: if they invest in human workflow, ROI (intelligence growth per dollar spent) is probably 20-30%, but if they invest in agentic workforce workflow, it can easily be 10x.
GPT-5.4 full at xhigh scored 51, exactly where Luna max sits today. GPT-5.4 costs $2.50/$15; Luna now costs $0.20/$1.20. In other words, roughly four months later, OpenAI is selling March’s full flagship intelligence at about one-thirteenth the token price.
GPT-5.4 full at xhigh scored 51, exactly where Luna max sits today. GPT-5.4 costs $2.50/$15; Luna now costs $0.20/$1.20. In other words, roughly four months later, OpenAI is selling March’s full flagship intelligence at about one-thirteenth the token price.
It's so obvious that NVDA has to step up to fund the buildout. They have the balance sheet and they need the slice of recurring revenue from those who put their chips into use once the buildout peaks.
This has to be the norm going forward. Hardware companies need to fund the model (monetization engine) to smooth the buildout, sustain the demand to their hardware, and to own a slice of the engine that prints money when the buildout eventually stabilizes and declines.
SCOOP: Anthropic will purchase up to 2 gigawatts of AMD’s latest-generation chips starting in the first half of 2027.
AMD will also invest up to $5 billion in Anthropic—its first check into the AI firm.
https://t.co/qzIuNvPAsw
I agree with you that this is intuitively true but I think we are pretty good at engineering an O(n^2) problem into O(n), so I wont take that as fully "unpriced".
@labubu_trader@JamesTrvdes I’ve an intuition: light being the connection between servers, it’s O(n^2) to silicon or AI infra buildout, but this is not reflected in the price. The DRAM moment is yet to come and it is likely more violent than the memory run. Am I too naive?
I'd like to do two things: (1) tell you where I think I erred in my original post about Kimi and (2) set the record straight about my views on open-weight AI.
Before I joined OpenAI (and folks who are new followers: I joined the company less than two weeks ago and it is my first job in the technology industry), I often tweeted about the controversy of the day in a cold and analytic fashion. One aspect of my style was saying brutally honest things, including things inconvenient for my 'side' and my beliefs. The post about Kimi was largely written in that vein.
When I said that the USG would probably realize its best option is to do ill-justified soft-law discouragement of Chinese AI, I wasn't proposing it like a good idea. Why on Earth would I do that? Why would I frame something I'm advocating for in such brutal terms? I am trying to describe what I believe will happen, not advocate for anything.
My first mistake: What I now realize is that this style of analysis is no longer tenable. There is simply too much scrutiny on my words, too much temptation to draw conspiracies from my claims, and the like. It is my fault for not realizing this.
Second mistake: I was relatively imprecise, writing, as I usually do, for a fairly high-context audience that was inclined to give me grace rather than pick apart every word. I should not have said, for instance, that open-weight models are unqualifiedly 'decelerationist'; I don't believe that. I only believe specifically that open-weight models decelerate capex spending on the margin, which is straightforwardly true. I did not say it was decelerationist for any other reason than that, and this is the only way in which I think open-weight AI is inherently decelerationist (though it is a big way). In many other ways, open-weight AI is profoundly accelerationist.
Now, to where I stand on open-weight AI. My earliest experiences on the internet were posting in forums about philosophy, music, and movies in the early 2000s. Over time I realizes that forums on different websites had the same underlying forum software; this was the first time it occurred to me that 'software' is a thing people make (I realize this is a simple observation, but we are talking about an 11 year old with no prior exposure to computers).
I looked into the software, and discovered that it was 'open source,' built and maintained for free by thousands of people around the world to facilitate the communication of millions of strangers. This notion struck me as deeply beautiful, and I decided I'd try to help. I began writing technical documentation, and later on, code, for this little forum project. This was how I first learned technical skills. I cherish that time, that software, and I have deep and abiding affinity for open-source software.
The vast majority of the people commenting on my post have very little context for my prior writing. For instance, the fact that I wrote, in 2024, things like:
"those who wish to hoard our software technologies may well be foreclosing on—or perhaps not even understand—the staggering civilizational victory that we earned through openness"
or
"I would like for AI to result in a similar smashing victory for America. To do that, we will need to set the global standard yet again. And to do that, we will almost certainly need to lead in open-source AI, because it is open protocols and open software that tend to define global standards in information technologies."
I stand by these things. When I was in government, I worked alongside my colleagues to develop ideas and rhetoric that was strongly supportive of open-weight AI, and some of this work made it into the current US AI strategy. I stand by that work too.
I also wrote, more than two years ago:
"The day may come when frontier AI really is too dangerous to open source. If so, that will be a sad day. But we’re not there yet. Today’s models are not sufficiently useful—or dangerous—to justify such a drastic shift in public policy."
I think it's pretty clear that we are approaching the point I describe--the point where, absent a major technical safety breakthrough, the national security implications of frontier open-weight model distribution are simply too severe. I don't think we're there yet (as I said in the piece), but the direction of travel is clear, and an analyst must be honest about this. Governments will realize these risks eventually, and when they do, they will have much lower risk tolerance than I have. We see this today with the Trump Administration, which once proudly championed open-source AI and now has a de facto licensing regime for frontier AI that I suspect will make it a challenge (if they still end up enforcing it) to release the weights of models of the "Mythos" tier. Every government will be safetyists once they understand themselves to be in the foxhole.
You don't have to *like* this. I don't. But it is the reality as I see it, and what I have always tried to do with my writing is describe reality as I see it, even when it is inconvenient for me and my preferences.
I intend to continue doing this. I will not be silenced by ignorant and loud critics. Yet I will have to work to find the new register I should adopt in my current job, which clearly changes the nature of my public communications even more than I had thought.
But believe me: I'm not going anywhere. I am not retreating from public writing, and I am not retreating from saying inconvenient things in public. I am unfazed by harsh criticism, and I know that a reaction of this magnitude is in part the result of having struck a chord. Bear with me, and if you can, remember that I am a human being with a six-month old boy to raise, a book to write, a new job, and much more questions than answers about our collective future.
Assuming HBM remains the bottleneck for a long time, with the algorithmic improvements, same amount of HBM will enable more demand for compute and interconnectivity. While the tide is still raising for everyone, proportional wise it's HBM ⬇️ and compute/interconnectivity ⬆️
Funny that both @SemiAnalysis_ and @zephyr_z9 wrote tweets trying to debunk the idea that KDA (Kimi Delta Attention) lowers aggregate HBM demand, but neither one has mentioned the most obvious argument:
It's exceedingly likely that the frontier labs have studied this design-space and either implemented some of KDA's concepts already or discarded them because of specific trade offs.
The original paper laying out KDA was published in October 2025, and it was itself a follow up to a paper from 2024. We've seen open source models from Google and OAI that approach and handle the issue of context management in both similar and different ways.
Yes, Kimi's quality is incremental data saying that KDA is a viable approach. The underlying idea isn't new, and there's zero reason to assume the frontier labs are only learning about this now.
@AlexCorrino If that's the case unfortunately that would be tremendously bullish for A/OAI because the only viable future remaining is US government doing something similar.
Somehow Chinese companies are willing to sink tremendous amount of money into building the open-weight models but giving the margins to those who serving them. I think plausible reasons could be:
1. They have some special technics to make it not expensive to train a model like this and such techniques are not possible for Anthropic or OAI.
2. It's still expensive to train such a model but somehow they do not care or they get the money back from other avenues.
3. Training such a model is already universally not as expensive as we thought.
Imo only 1 is truly bad for A/OAI and I don't think that's the case besides distillation.
Very good piece from Joe but I wish he’d have dug in on the specifics of why less compute would be needed.
The open source models are not necessarily more compute efficient to serve or provide inference for. Kimi K3 looks to cost about the same per task as Sol. We don't know the exact margins OpenAI makes on Sol and we don't know the exact cost Kimi has until they start serving it on places like Open Router later this month. But they have roughly the same cost today, OAI likely has better margins, so it’s possible Kimi requires roughly the same or more compute to serve as Sol.
So there's not going to be any near term decrease in the compute build out from models like Kimi.
The real thing that would change if open-source models keep up with the frontier labs is that it could no longer be economical for the frontier labs to build larger and larger models.
It’s one thing to spend a 11 figures on a new model when you know you will be part of a high margin duopoly. It’s another when you know there are fast-following Chinese companies in the market as well.
Training compute needs are shrinking as a % of the overall compute pie, but they are still significant part of the mix. And fewer or less ambitious new models would drop those needs.
But much more important than that would be the consequence of expecting smaller and less powerful models in the future because that has a direct impact on the implied inference compute demand. Smaller models on average in 2030 mean lower compute cost per token than previously expected.
So it's not that Kimi implies less inference demand is needed in the short term. Quite the opposite in fact because Jevons paradox probably does kick in hard if open source models drive prices down. We know (or at least can make a good guess) that the compute costs of these models don't seem to be that much lower than the Frontier models.
The real important takeaway of OS being just a handful of months behind the frontier is that this might lower the “terminal value of compute” that the market eventually needs.
Is the market sniffing that out? It could very well be.
IMO it's bearish for HBM but bullish for compute and connect. As per-token demand of HBM decreases, the relative value of compute and connect increases.
Similar to the panic over DeepSeek R1, some uneducated people think Kimi K3’s use of linear attention (KDA) is bad for NVIDIA, HBM, DRAM, and networking because it has relatively lower KV-cache requirements. The opposite is true, and we explain why below. 👇️ 1/8🧵