Chem engineer / chemist & founder. Running open models on 4× DGX Spark (will be 8 soon). Writing on local AI: real industrial use & my occasional perspective
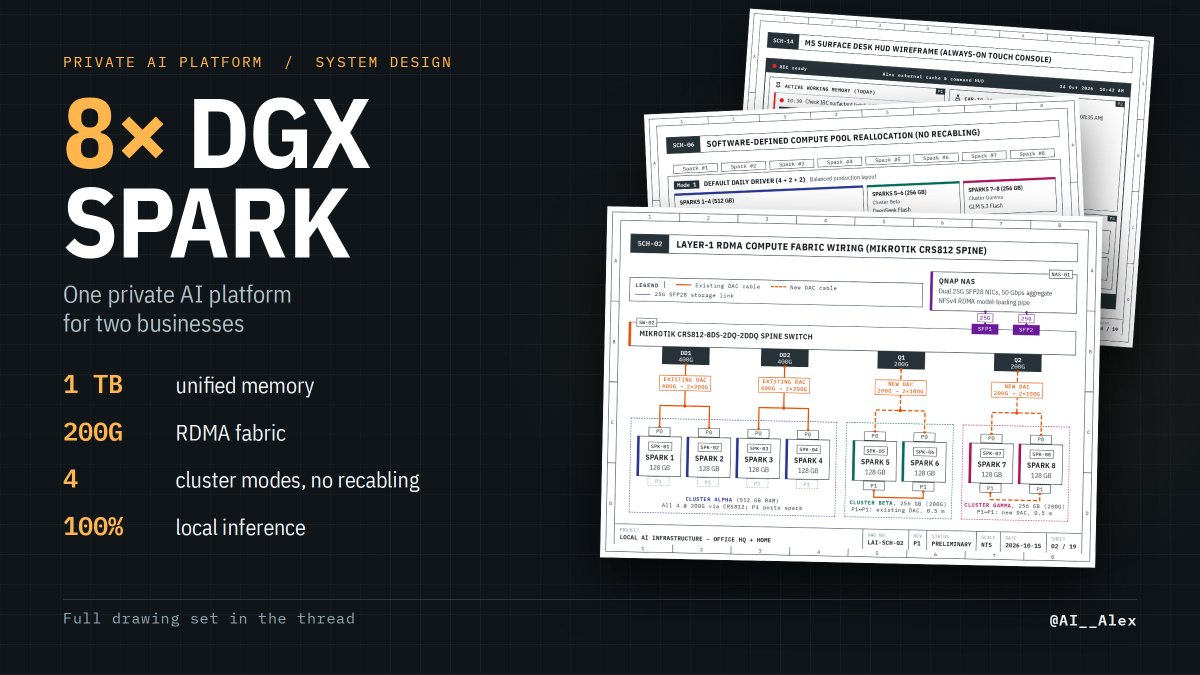
NVIDIA's own tooling clusters up to 4 DGX Sparks on a switch. I've designed for 8: 1 TB unified memory, a 200G RDMA fabric, and four cluster modes switched in software. 100% local inference for two businesses. 18 drawings below. Tell me what you'd change.
@stiankildal@mpawlo@nntaleb Antifragile is my favourite too, but each of his books have been profound. The black swan was my first, nearly 20 years ago, and has had such a huge impact on the way I view the world.
@mpawlo@nntaleb This guy clearly hasn't actually read a Taleb book. I remember reading the black swan in 2008, thinking "why does he keep labouring this point" until I finally had my "ah..." moment and began to understand. Taleb is truly one of the great philosophers of our time.
WAwisely mandated a 15% domestic gas reservation policy as a precondition for LNG project approval, which has resulted in a significant local surplus. In contrast, East Coast LNG projects were all approved without any domestic gas requirements leading to extremely negative consequences. The real issue here is why this was allowed to happen.
Banger paper from Amazon on self-improving agents.
(bookmark it)
CompoundingKernel writes GPU kernels from scratch with over a thousand agents:
- 235 problems, every one with a verified correct kernel
- First place on the public L1, L2 and Quantization boards of SOL-ExecBench on NVIDIA B200
- 4.40x faster than the reference baseline on the 209 public problems
The agents start from each problem's PyTorch definition, with no reference kernels and no official scores. An archive outside the model keeps every correct kernel and its lineage. An LLM controller reads the archive, picks a parent, and gives each child agent one direction. Checks outside the model decide correctness.
The controller beat a UCB-style tree search on 35 of 38 problems at equal wall time. It chose parents about as well, but made 2.4x as many correct attempts. One restart fix raised the fleet's evaluation rate 3.6x.
If you scale an agent search, measure how many reliable evaluations per hour it runs before adding agents.
https://t.co/CgU1PWlYlJ
Chat with Paper: https://t.co/boLrcIzIha
@Morrowmake@plotarmordev@ashxhart I agree, i think that the weights should be 100% truth only. No post training, no behaviour layers, no censorship of terms; just truth. Anything you do to the pure weights is interfering with the cognition potential and accuracy. Everything else should be outside including safety
@edzitron I thought you were supposed to be about facts, Ed Zitron. You're losing credibility by asserting things like this, especially now that the truth is coming out. How objective are you actually? You should disclose to everyone what your short positions are, if you hold any.