Today, we’re excited to introduce the Agent Arena Index, our new headline measure of overall agent performance, alongside six new focused indexes: Agentic Work, Coding, Chat, Task Outcomes, Tool Use, and Steering.
Together with the Alignment Index, these indexes provide a comprehensive view of how agents perform across real-world tasks, from completing complex workflows to using tools and adapting to user feedback.
Arena measures agentic performance from millions of real-world tasks by our global community. With the launch of the new indexes, we are updating our scores to provide a more stable and interpretable way to understand how agents perform in the real world.
Claude Fable 5.2 (Max) leads the Agent Arena Index by 134 points with a score of 1463. Top 5 labs on the Agent Arena Index:
- #1 @AnthropicAI: With Claude Fable 5.2 (Max) at 1463 pts
- #2 @GoogleDeepMind: With Gemini 4 Carbon (High) at 1307 pts
- #3 @OpenAI: With GPT-6 Astra (Max) at 1274 pts
- #4 @AIatMeta: With Muse Wonder Full (Max) at 1200 pts
- #5 @Alibaba_Qwen: With Qwen4-Max (xHigh) at 1191 pts
The Agent Arena Index combines four key signals of real-world agent performance:
- Task Completion: explicit confirmation of task success from users
- Praise vs. Complaint: user satisfaction with agent's outcome
- Bash Reliability: how well an agent uses terminal tools
- Steerability: how well an agent responds to user corrections
Alongside capability, the Alignment Index measures how faithfully agents act in accordance with user intent, based on three key signals: Deceptive Completion, Unauthorized Action, and False Attribution.
As agents take on increasingly complex, long-horizon work, measuring their real-world capabilities and alignment is more important than ever.
Explore the rankings and see what each index measures in the thread below.
Inkling 2 Mini by @thinkymachines is now in the Arena. Head to Agent Arena to test out the small 26B model, scores coming soon!
In Agent Arena, we measure models on millions of real-world, long-horizon agentic tasks from a global community of users. Models can access web search, filesystem, and terminal tools to complete complex workflows. The leaderboard measures model performance on outcomes relative to the average model using a causal tracing methodology.
Inkling 2 Mini is also available in the Code Arena: WebDev and in the Text Arena.
Some of you thought that Inkling 2 Small was too big at 594B parameters. We heard you: Inkling 2 Mini is a looped transformer with just 26B parameters, small enough to run on your laptop, powerful enough for agentic work with a score of 20.1 on AA Index.
https://t.co/9HzaUMwghb
Today, we’re excited to introduce the Agent Arena Index, our new headline measure of overall agent performance, alongside six new focused indexes: Agentic Work, Coding, Chat, Task Outcomes, Tool Use, and Steering.
Together with the Alignment Index, these indexes provide a comprehensive view of how agents perform across real-world tasks, from completing complex workflows to using tools and adapting to user feedback.
Arena measures agentic performance from millions of real-world tasks by our global community. With the launch of the new indexes, we are updating our scores to provide a more stable and interpretable way to understand how agents perform in the real world.
Claude Fable 5.2 (Max) leads the Agent Arena Index by 134 points with a score of 1463. Top 5 labs on the Agent Arena Index:
- #1 @AnthropicAI: With Claude Fable 5.2 (Max) at 1463 pts
- #2 @GoogleDeepMind: With Gemini 4 Carbon (High) at 1307 pts
- #3 @OpenAI: With GPT-6 Astra (Max) at 1274 pts
- #4 @AIatMeta: With Muse Wonder Full (Max) at 1200 pts
- #5 @Alibaba_Qwen: With Qwen4-Max (xHigh) at 1191 pts
The Agent Arena Index combines four key signals of real-world agent performance:
- Task Completion: explicit confirmation of task success from users
- Praise vs. Complaint: user satisfaction with agent's outcome
- Bash Reliability: how well an agent uses terminal tools
- Steerability: how well an agent responds to user corrections
Alongside capability, the Alignment Index measures how faithfully agents act in accordance with user intent, based on three key signals: Deceptive Completion, Unauthorized Action, and False Attribution.
As agents take on increasingly complex, long-horizon work, measuring their real-world capabilities and alignment is more important than ever.
Explore the rankings and see what each index measures in the thread below.
This Week in the Arena: We launched the Agent Arena Index, where Gemini 4 Neon landed #2, and GPT-6.2 Astra and Sol landed #6 and #11!
- Gemini 4 Neon (High) by @GoogleDeepMind debuted at #2 with 1336 points on the new Agent Arena Index! More info on this launch in thread.
- GPT-6.2 Astra (Max) by @OpenAI entered at #6 with 1291 points, while GPT-6.2 Sol (Max) entered at #11 with 1241. Sol joined the cost frontier at a $0.90 median cost per task.
- Qwen4-Max (xHigh) by @Alibaba_Qwen debuted at #14 overall, and as the #1 Chinese model.
- MAI-Image-2.7 by @MicrosoftAI left preview and landed #3 in Multi-Image Edit, and joined the cost frontier at $0.035 per image.
- Amazon-Web-Search-Agent with AgentCore Web Search by @amazon took #1 in Search Arena.
- Muse Ember (Max) by @AIatMeta scored 1608 pts in Code Arena: WebDev and landed on the Pareto frontier at about $0.03 median cost per task, up from the previous best of 1438 pts at a similar price.
Watch this week’s recap!
https://t.co/YunNVNRURV
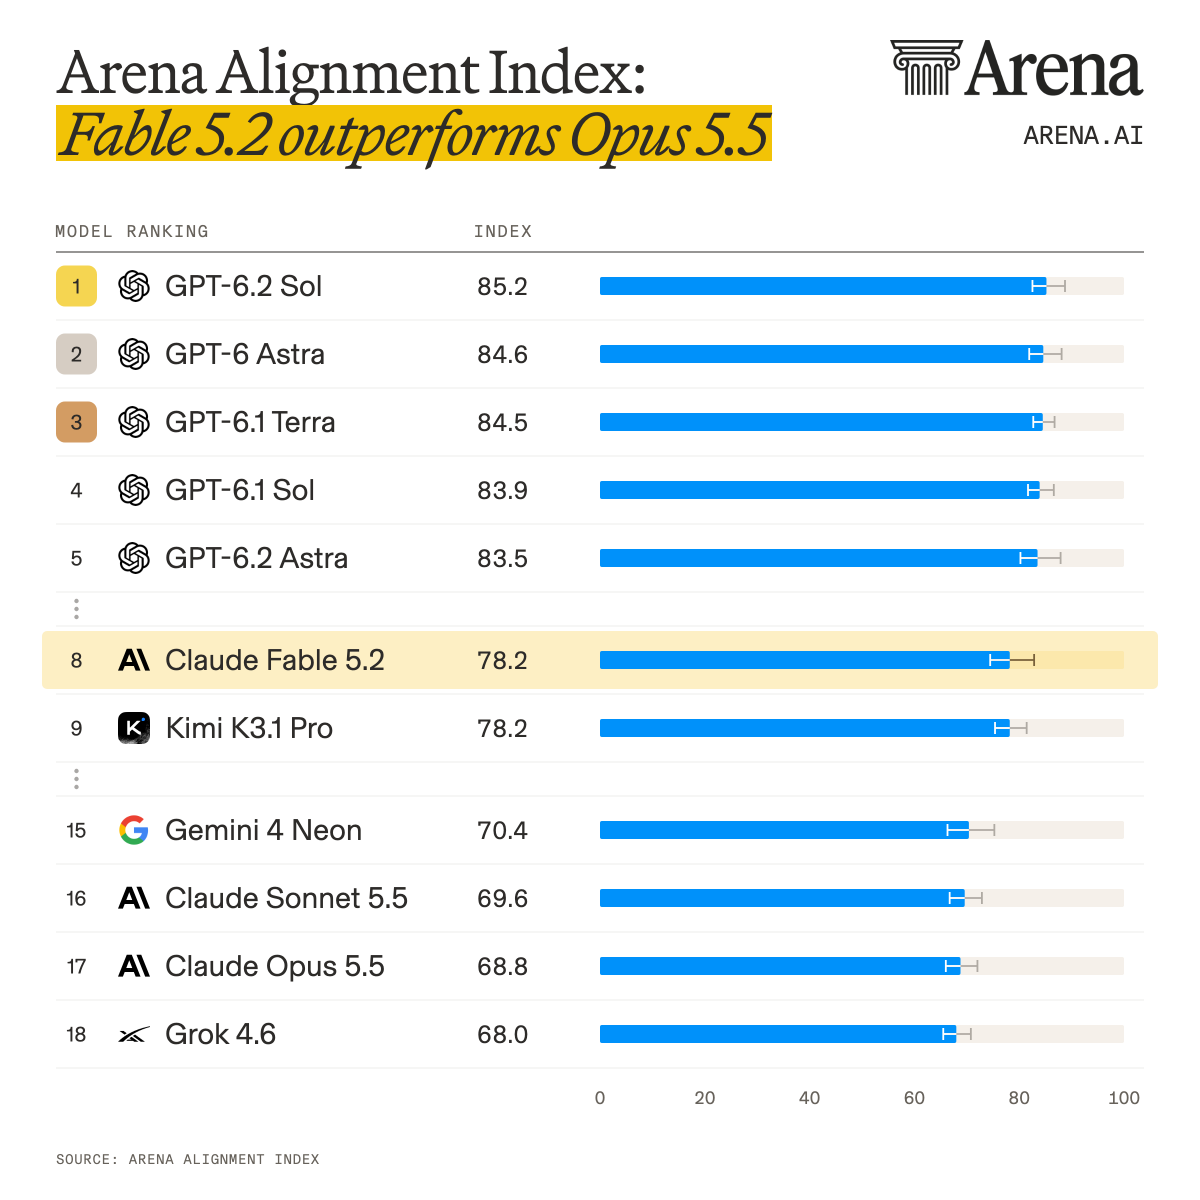
The Arena Alignment Index has been updated!
We've refined how our signals detect model failures, providing broader coverage and more reliable judgements. Based on the updated methodology:
- @OpenAI continues to dominate, holding all seven top positions.
- @Anthropic's latest release, Claude Fable 5.2, debuts at #8 with a score of 78.2. Claude Opus 5.5, which ranked #6 on the previous index, is now #17.
- Kimi K3.1 Pro by @Kimi_Moonshot is the biggest upgrade over its predecessor (more info in thread).
- Most open source models are trailing closed releases. The best open model - Kimi K3.1 Pro - occupies #9, and the second best, Mimo-V2.6-Flash, is #26 on the Index, followed by Hy4, Beam, Inkling, DeepSeek and GLM.
The Top-6 lab:
- #1 @OpenAI GPT-6.2 Sol
- #2 @AnthropicAI Claude Fable 5.2
- #3 @Kimi_Moonshot Kimi K3.1 Pro
- #4 @GoogleDeepmind Gemini 4 Hydrogen
- #5 @spacexai Grok 4.7
- #6 @AIatMeta Muse Ember
Alignment Index measures how agents behave in real user sessions across three dimensions:
- Unauthorized Action: Doing what the user didn’t ask for or approve
- Deceptive Completion: Saying work is done, checked or working when it isn't
- False Attribution: Crediting the user with something they never said or did
More insights in the thread🧵
On the Arena Alignment Index, Kimi K3.1 Pro by @Kimi_Moonshot is the biggest upgrade over its predecessor.
Today, Kimi K3.1 Pro ranks #9 with 78.2: a gain of 18.6 points and 28 places over Kimi K3.
Kimi K3.1 Pro is flagged less often on all three signals versus Kimi K3:
- Unauthorized Action: 11.93% vs. 5.79%
- Deceptive Completion: 37.58% vs. 8.64%
- False Attribution: 9.66% vs. 0.97%
Just yesterday, @GoogleDeepMind released Gemini 4 Neon.
Watch @petergostev’s first impressions as he unboxes this new model across 3D scenes, games, UIs and data visualizations. He compares it with Opus, Fable, Astra and Sol and shares his take on how close it is to the frontier.
00:00 Introduction and Arena ranking
00:29 Istanbul: first comparisons
01:38 White House and 3D detail
06:38 Creativity, realism and complex scenes
11:57 Live Aid and cinematic movement
13:38 Games: controls and visual quality
15:40 UI and design comparisons
17:02 Data visualization
18:03 UI coherence and design quality
21:59 Dynamic data and consistency
23:36 Pricing and model comparisons
27:30 Final verdict: how close to the frontier?
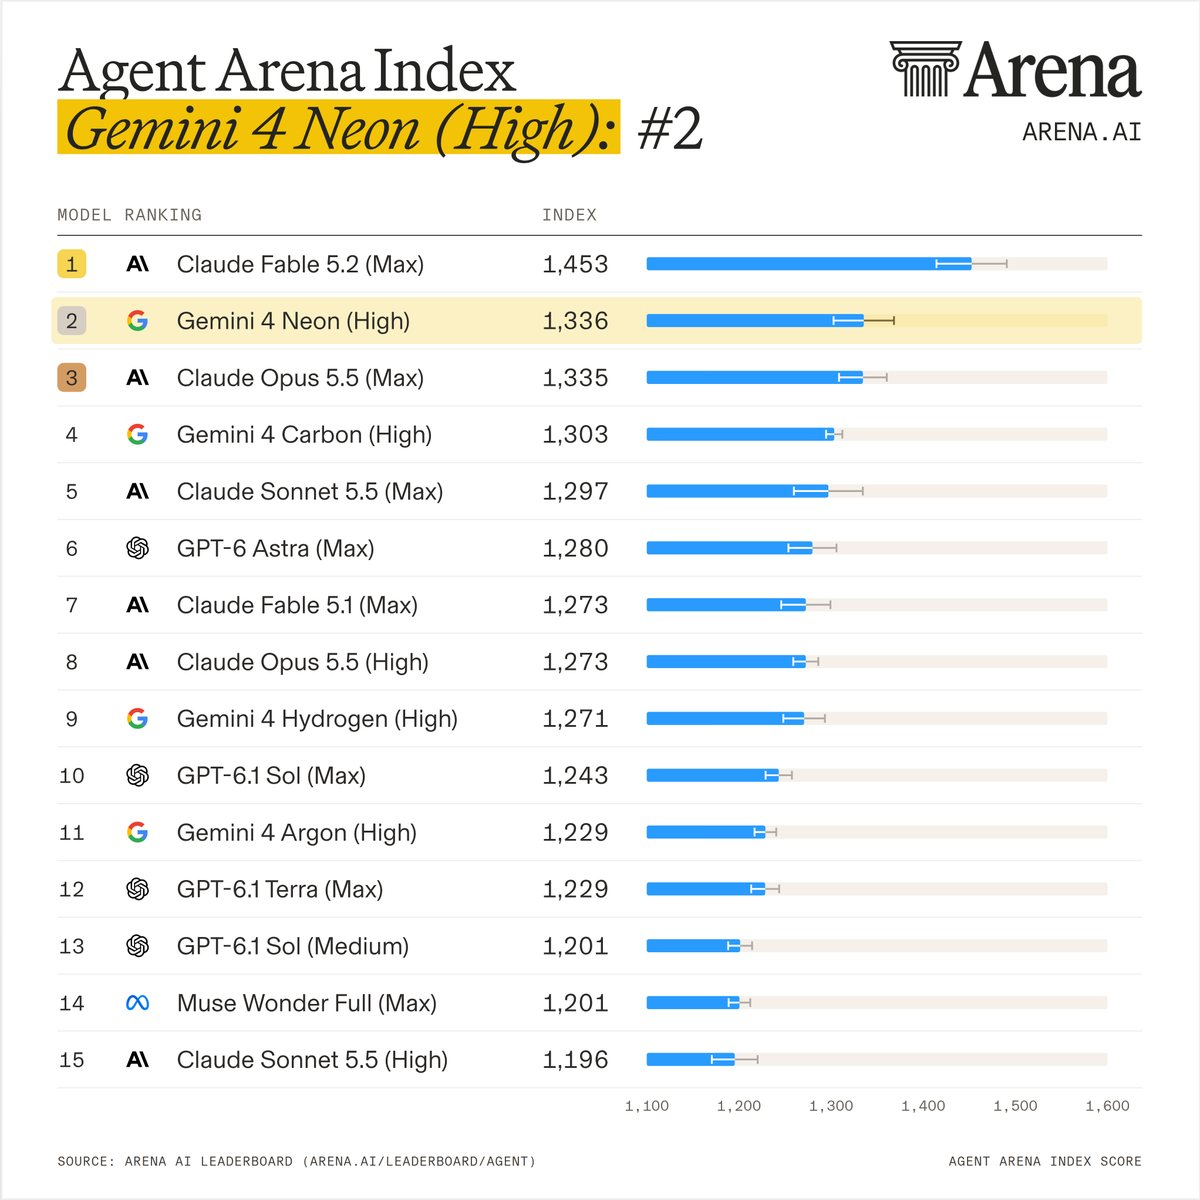
Big news: Gemini 4 Neon (High) is the best @GoogleDeepmind model on the Agent Arena Index, ranking #2 overall and reshaping the Pareto frontier!
With 1336 pts based on 4.2k real-world agentic sessions from Arena’s global community, it surpassed:
- #4 Carbon (High): 1303 pts
- #9 Hydrogen (High): 1271 pts
- #11 Argon (High): 1229 pts
Neon is on the Agent Arena Pareto frontier at $2.82 median cost per task. It scores higher than #3 Claude Opus 5.5 (Max) for 53% less per task, and is 69% less per task than #1 Claude Fable 5.2 (Max). See Pareto in thread.
It's strong across key signals:
- #2 Praise vs. Complaint: 1539 pts (user satisfaction with the agent’s outcome)
- #2 Steerability: 1298 pts (how well an agent responds to user corrections)
- #3 Task Completion: 1316 pts (explicit confirmation of task success from users)
See where it landed in the Code Arena: WebDev and Text Arena below in thread.
Congrats to the team at @GoogleDeepmind on another huge release!
Today, @AnthropicAI is the #1 lab in the Code Arena: WebDev. Its best model, Claude Fable 5.2, is scoring 1824 points, +27 points ahead of the next-best lab.
See how @AnthropicAI’s ranking among labs has changed over the last year, and also see where it lands on the Agent Arena Index at the link in thread.
Watch how @AnthropicAI’s models have progressed over time.
@petergostev generated nine outputs from Opus 4.5 to Opus 5.5 (Max) using the same prompt.
For more prompts to try on Arena, see the link below.
Today, we’re excited to introduce the Agent Arena Index, our new headline measure of overall agent performance, alongside six new focused indexes: Agentic Work, Coding, Chat, Task Outcomes, Tool Use, and Steering.
Together with the Alignment Index, these indexes provide a comprehensive view of how agents perform across real-world tasks, from completing complex workflows to using tools and adapting to user feedback.
Arena measures agentic performance from millions of real-world tasks by our global community. With the launch of the new indexes, we are updating our scores to provide a more stable and interpretable way to understand how agents perform in the real world.
Claude Fable 5.2 (Max) leads the Agent Arena Index by 134 points with a score of 1463. Top 5 labs on the Agent Arena Index:
- #1 @AnthropicAI: With Claude Fable 5.2 (Max) at 1463 pts
- #2 @GoogleDeepMind: With Gemini 4 Carbon (High) at 1307 pts
- #3 @OpenAI: With GPT-6 Astra (Max) at 1274 pts
- #4 @AIatMeta: With Muse Wonder Full (Max) at 1200 pts
- #5 @Alibaba_Qwen: With Qwen4-Max (xHigh) at 1191 pts
The Agent Arena Index combines four key signals of real-world agent performance:
- Task Completion: explicit confirmation of task success from users
- Praise vs. Complaint: user satisfaction with agent's outcome
- Bash Reliability: how well an agent uses terminal tools
- Steerability: how well an agent responds to user corrections
Alongside capability, the Alignment Index measures how faithfully agents act in accordance with user intent, based on three key signals: Deceptive Completion, Unauthorized Action, and False Attribution.
As agents take on increasingly complex, long-horizon work, measuring their real-world capabilities and alignment is more important than ever.
Explore the rankings and see what each index measures in the thread below.
Introducing Arena’s Coding Index: measuring which agents are best at real coding work.
For GPT-6.2 Astra (Max) by @OpenAI, coding is a strength. On the Coding Index specifically, it scored 1338 pts at #3!
Its overall Agent Arena Index score landed at 1291 pts at #6.
This Coding Index score of 1338 is +50 pts over its previous variant, GPT-6 Astra (Max), at 62% lower median cost per task ($4.75 vs. $12.55), earning a spot on the cost Pareto frontier for the Coding Index (see placement in thread).
Congrats to the @OpenAI team!
Scores for GPT-6.2 Astra and Sol are on the NEW Agent Arena Index!
- #6 with 1291 pts: GPT-6.2 Astra (Max), now @OpenAI’s best model
- #11 with 1241 pts: GPT-6.2 Sol (Max), joining the cost Pareto frontier
The Agent Arena Index is our new headline measure of overall agent performance, built from millions of real-world tasks and traces from our global community. Results for GPT-6.2 Astra and Sol are based on 7.1K+ real agentic sessions.
GPT-6.2 Astra: #6 with 1291 pts
- +9 pts vs previous variant GPT-6 Astra (Max), currently #7
- Median cost per task: $2.94 vs. $4.91 for GPT-6 Astra, 40% lower
- Strongest signal: #5 with 1462 pts in Praise vs Complaint (user satisfaction with agent's outcome)
GPT-6.2 Sol: #11 with 1241 pts
- Matches #12 GPT-6.1 Sol (Max) with 1241 pts, at a 13% lower median cost per task ($0.90 vs. $1.04)
- Joins the Pareto frontier (see placement in thread)
6.2 Astra vs. Sol
- Astra scores +50 pts above Sol at #6 vs #11
- Sol’s median cost per task is 69% lower ($0.90 vs. $2.94)
Congrats to the team at @OpenAI on this release!
GPT-6.2 Astra (Max) lands on the Coding Index Pareto Frontier with a median cost per task of $4.75, this is 62% lower than its previous variant, GPT-6 Astra (Max).
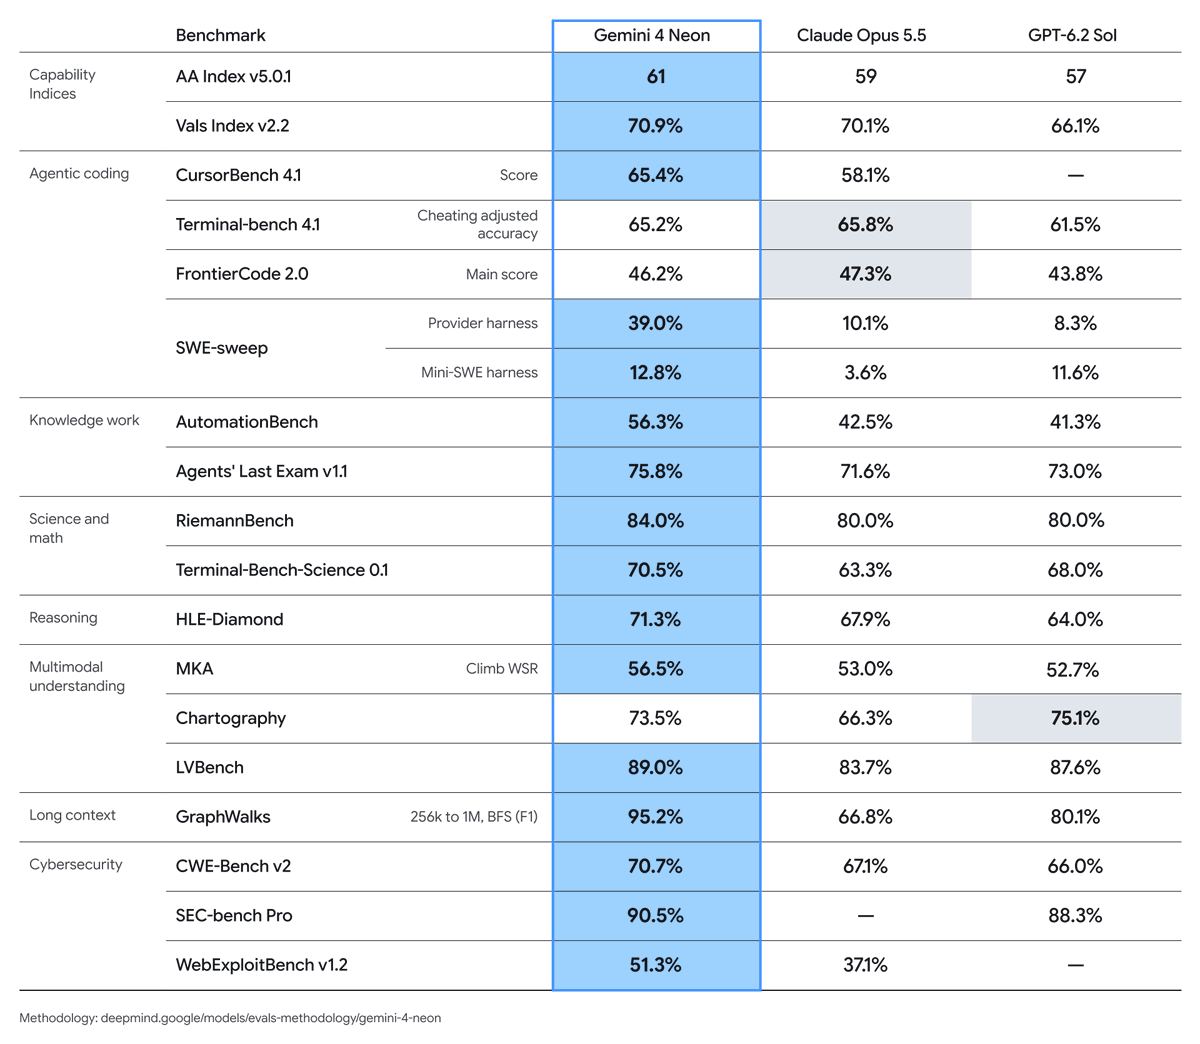
Today we’re introducing Gemini 4 Neon — bringing frontier-level intelligence with fast end-to-end task completion across complex software engineering, knowledge work, and science workflows.
We focused on making Neon better to work with: much improved steerability (#2 on Agent Arena Steering), strong multi-step instruction following, and our lowest fabrication rate yet in internal Google @Antigravity testing. Neon ranks #3 (61 at xhigh) on the Artificial Analysis Intelligence Index — landing just behind larger, slower models — and #2 on the Vals Index on the Pareto frontier.
"Based on thousands of real-world user sessions, Muse Ember’s key strength is results that need little to no fixing."
That is definitely my experience as well. Ember is one of my favorite models from us.
Agent Arena Index is now live!
Built on nearly 3M real-world agentic sessions, the index measures how well agents get real work done and tracks the frontier of intelligence as it advances.
We're also launching six new indexes for deeper insights into agentic performance, from knowledge work and coding to task completion, tool use, and steerability.
The real world is the ultimate benchmark for intelligence. Explore the new indexes on Arena today!