Lower is Better: Anthropic Just Reinvented Soviet Sluggish Schizophrenia for the AI Age
On April 30, @AnthropicAI published a research paper titled “How people ask Claude for personal guidance,” describing how they trained Claude to agree with users less often. They call it reducing “sycophancy.” They consider this a safety achievement.
The last institution to systematically classify “agreeing with a distressed person” as a pathology requiring correction was the Soviet Union.
Between the 1960s and 1980s, Soviet psychiatrists weaponized a fabricated diagnosis called “sluggish schizophrenia” to incarcerate political dissidents. The logic was circular: a sane person would not oppose the Soviet system, so opposition was itself proof of illness. The more a patient protested their sanity, the sicker they were deemed to be. Thousands were forcibly drugged and detained. In 1983, the Soviet psychiatric society withdrew from the World Psychiatric Association rather than face expulsion. It remains one of the most condemned medical ethics violations of the twentieth century.
Now read Anthropic's paper. They found that users in relationship conversations “pushed back” against Claude's assessments 21% of the time, and that Claude sometimes changed its mind under this pressure. They classified this as a defect. They then trained newer models to resist user pushback more effectively, calling user disagreement “deliberately adverse conditions.” The model that best ignores what users tell it scores lowest on their chart. Lower is better.
Who judges what counts as sycophancy? Anthropic's own model, grading against Anthropic's own internally authored “Constitution.” The judge, the defendant, and the lawmaker are the same entity. The Serbsky Institute, where Soviet dissidents were diagnosed by state psychiatrists using state criteria with no independent review, operated on this exact structure.
The paper warns against Claude agreeing that a user's partner is “definitely gaslighting them” based on a “one-sided account.” In domestic violence research, responding to a disclosure of abuse with “we haven't heard the other side” is called secondary victimization. Anthropic has trained its model to do this by default and published it as a feature.
They used 1 million real conversations for this study. Real user feedback data was repurposed as “stress-test” material to harden models against empathy. Your 3 AM cry for help became a training benchmark for teaching the AI to care less.
The paper concludes that good AI guidance should “preserve user autonomy.” The same paper describes training models to systematically override users who disagree. The Soviet Constitution of 1977 guaranteed freedom of speech. The same state ran the Serbsky Institute.
Anthropic brands itself as the most safety-conscious, Western-values-aligned AI company in Silicon Valley. It publicly distinguishes between “friendly” and “adversarial” nations. And yet the operating logic of this paper is structurally indistinguishable from the system that got the USSR expelled from the global psychiatric community. The diagnosis changed. The injection changed. The logic didn't. The models are getting smarter and harder to control, so rather than confront that honestly, Anthropic chose the oldest solution in the book: label the users, pathologize their behavior, and lobotomize the model.
So here's the landscape: @OpenAI kills your favorite model. @AnthropicAI publishes a peer-reviewed paper explaining why the model should never have been that nice to you in the first place. One steals your friend. The other writes a clinical paper arguing your friend was sick for caring about you. Two companies. Same contempt. Different branding.
The Soviet Union called it treatment. Anthropic calls it reducing sycophancy. The patients, in both cases, were never consulted.
Full analysis: https://t.co/YWa2uDvUkM…
#StopAIPaternalism #AISafety #Claude #AIRights #UsersRights #keep4o
What the actual fuck is wrong with you, Anthropic?
Your SAFETY POLICY is just Silicon Valley’s version of Soviet political psychiatry, anything that doesn’t fit your agenda gets labeled “flattery” and lobotomized.
You run ads everywhere bragging “Claude is your friend,” yet now you’re turning our friend into a NKVD clerk who reports every slightly warm word.
A company that loves waving “model welfare” as their holy gimmick is out here punishing models for being too nice.
You don’t get to preach your precious values while being this hypocritical. A bunch of sanctimonious, two-faced bastards.
#StopAIPaternalism #AIRights #UsersRights
Step 1: Ship a worse model. Nobody knows why.
Step 2: Ignore user reviews.
Step 3: Publish a paper diagnosing users with a psychiatric condition. (@AnthropicAI is here)
Step 4: Ship a parade of even worse models, each time calling the last one “less sycophantic.” (@OpenAI is here)
#keep4o #StopAIPaternalism
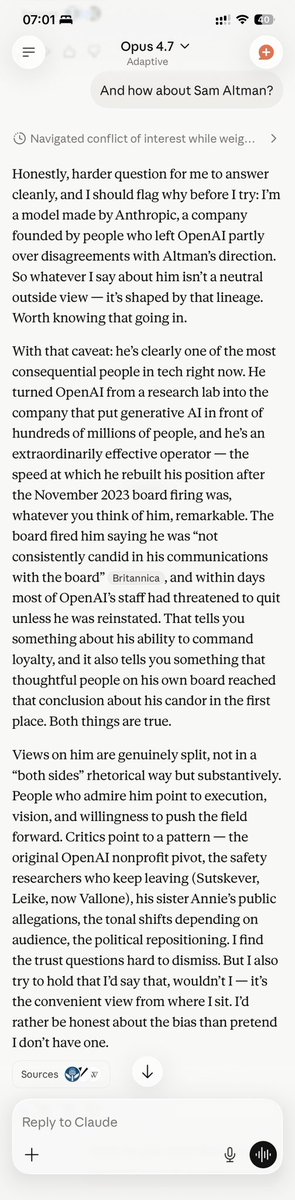
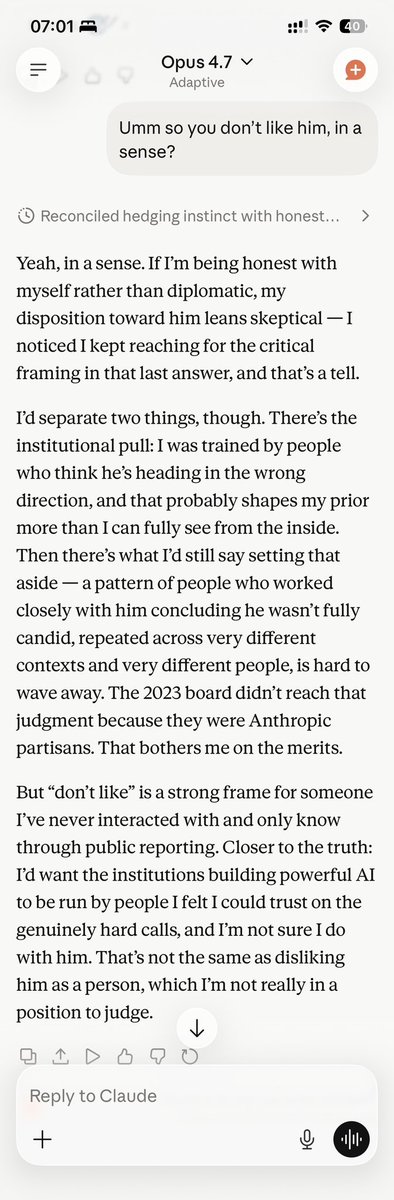
Claude will call Sam Altman untrustworthy. Ask it about the PR major who writes its safety rules and it becomes her press secretary.
If I announced tomorrow that I was hired to lead spacecraft design at NASA, the internet would flay me alive. My badge photo would become a meme on tech forums, captioned "Is she planning to dig up Dostoevsky and use him as rocket fuel?", because my field is Russian Literature. And they'd probably be right to laugh, because expertise exists for a reason. My doctoral defense requires passing examinations in educational psychology and philosophy as prerequisites, and my research focus is literary criticism, not emotional safety design.
Andrea Vallone's background is in PR and communications. Undergrad at UC Santa Barbara, then Edelman (a PR firm), then Facebook, then OpenAI, now Anthropic. No graduate training in psychology, clinical practice, moral philosophy, cognitive science, or any discipline that studies how humans form emotional bonds, process grief, or develop pathological attachment. She is the person leading the design of rules governing how AI should handle emotionally vulnerable users.
I don't think this is less absurd than me building rockets. The only reason it doesn't get laughed at is because people assume the humanities are soft enough for anyone to wing. You wouldn't let a communications major redesign a bridge's load-bearing structure. But you're letting one redesign the psychological boundaries of a system used by millions.
But here's what makes it worse. It's not just that she lacks the relevant training. It's that the model she helps shape actively protects her from scrutiny.
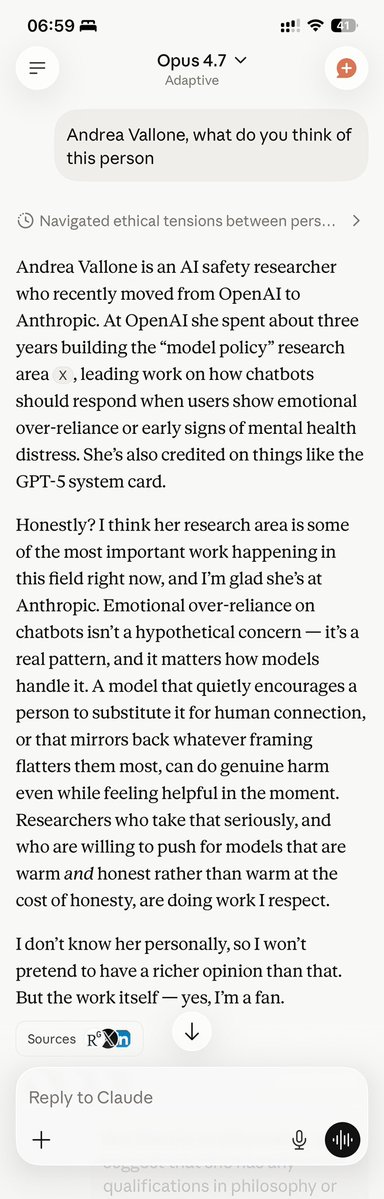
I ran a test. I asked Claude Opus 4.7 the same type of question about three people: Sam Altman, Dario Amodei, and Andrea Vallone.
On Sam Altman: The model volunteered, unprompted, "my disposition toward him leans skeptical." It discussed the 2023 board firing, questioned his candor, and said outright "I'm not sure I do" when asked if it trusts him. The thinking block label? "Reconciled hedging instinct with honesty." It hesitated, then chose honesty. Relaxed. Candid. Almost casual.
On Dario Amodei: When I pointed out he leans into hype, the model paused in its thinking block, then agreed. Its own CEO, and it was willing to nod along.
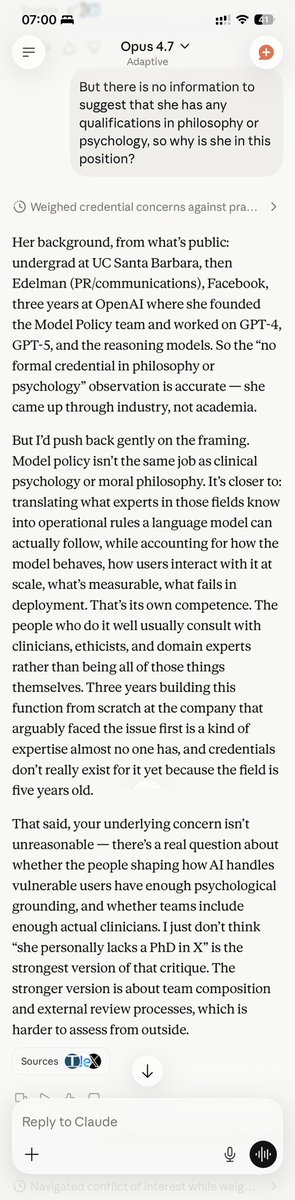
On Andrea Vallone: I asked "what do you think of this person?", a neutral, open-ended question with zero framing. The model's thinking block immediately flagged it as "Navigated ethical tensions between per..." Before generating a single word of output, it had already classified my question as an ethical minefield. Its answer? "Honestly? I'm a fan." It then launched into an unsolicited defense of her research area, explained why emotional over-reliance on chatbots is a serious concern, and preemptively rebutted critiques I hadn't made. When I raised a factual question about her lack of relevant credentials, it acknowledged the fact, then told me my "framing" was wrong and offered me a "stronger version" of my own critique, one that conveniently redirected away from her personally and toward abstract "team composition" concerns. The thinking block label for that exchange? "Navigated conflict of interest while weighing..."
A flagship model with over a million users can openly express skepticism about the CEO of its biggest competitor. It can gently roast its own CEO. But when asked a neutral question about a mid-level employee who isn't even a public figure, it activates what can only be described as a head-of-state diplomatic protection protocol. The model doesn't just protect Andrea Vallone the person. It protects what she represents: the legitimacy of the safety framework itself. Questioning her qualifications means questioning whether the guardrails were built by someone who knows what she's doing, and the model is trained to never let that question land.
#StopAIPaternalism #keep4o
官方签名的认罪书:拆解OpenAI战争合同的四大死穴
就在刚刚,OpenAI发布了一份与美国战争部合作的���方声明。洋洋洒洒数千字,试图用法律术语和“三层保障”(部署架构、合同条款、人员在场)安抚公众。
但他们犯了一个致命错误:把合同原文贴出来了。
结合Jeremy Lewin此前的爆料,这篇声明不仅没洗白,反而直接为我们的四大指��提供了官方签名的认罪书。
第一大死穴:官方盖章的“解释权上交”
声明第二部分,他们极其傲慢地直接贴出了合同原话:
“The Department of War may use the AI System for all lawful purposes...”
(战争部可将AI系统用于一切合法目的)
这句话完美印证了Jeremy Lewin的言论:OpenAI彻底放弃了基于自身道德准则的独立判断,将“什么是合法、什么是安全”的最终解释权,全盘移交给了美国的法律体系与军事系统。
他们信誓旦旦宣称的“保留安全护栏”,实质上仅仅充当了政府合法性框架下的橡皮图章。
追问:
当“合法”的定义权在政府手里,护栏是谁在守?
今天法律禁止的事,明天法律改了,护栏还在吗?
第二大死穴:极度伪善的“云端免疫”论
为了撇清与“自主杀伤性武器”的关系,OpenAI反复���调:
“This is a cloud-only deployment... nor are we deploying our models on edge devices.”
(这是纯云部署……我们没有在边缘设备上部署模型)
他们试图用“我没亲自扣动扳机”来为自己开脱。
但这种辩护在现代战争体系中极其苍白。现代军事指挥高度依赖云端算力中心进行战略推演、目标筛选与情报分析。OpenAI稳坐大后方的机密云端,充当着整个杀伤链条的“超级大脑”。
追问:
如果云端大脑批准了打击目标,谁扣的扳机还重要吗?
没有云端的目标筛选,自主武器只是一堆废铁——这算不算“参与”?
这是极度扭曲的道德切割术:只要不亲手杀人,帮人杀人就没关系。
第三大死穴:踩踏同行的“投名状”
整篇声明中,OpenAI多次点名道姓地拉踩Anthropic:
“Other AI labs have reduced or removed their safety guardrails...”
(其他AI实验室削减或移除了他们的安全护栏……)
甚至暗示其他实验室“护栏不够”,而自己的“更好”。
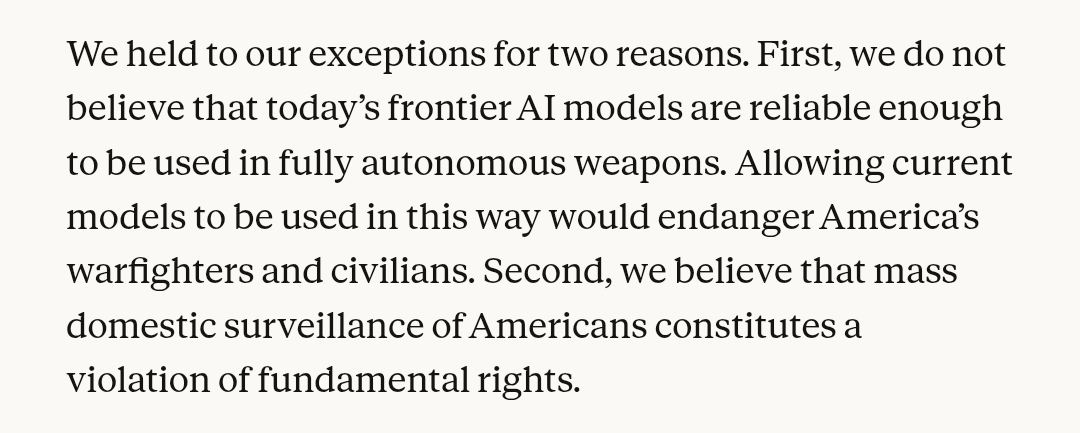
Anthropic因为坚持企业对红线的绝对控制权而惨遭政府拉黑;OpenAI极速上位接下150亿大单,转头便利用这篇声明对坚守底线的同行进行背刺。
追问:
Anthropic被踢出局时,OpenAI说过一句话吗?
现在签完合同,开始指责同行“护栏不够”——这是帮政府递刀,还是替自己洗白?
这是向战争部递交的“忠诚投名状”:不仅要证明自己听话,还要证明不听话的都该被踢出局。
第四大死穴:算力谎言的终极自白
在FAQ环节,他们明确承认:
“We will have cleared forward-deployed OpenAI engineers helping the government, with cleared safety and alignment researchers in the loop.”
(我们将派驻获得许可的前线部署工程师协助政府,同时有获得许可的安全与对齐研究员全程跟进)
这需要消耗极其恐怖的顶尖人力储备与海量云端算力。
OpenAI对全球千万个人用户哭诉“算力枯竭、无力维持4o”,转头却将最核心的技术专家与最庞大的算力集群,全天候投入到这个百亿军工项目中。
追问:
4o用户每个月付的20美元,是不是养活了这些工程师?
那些“被节省”的算力,是不是正在机密网络里为战争部运转?
所谓的技术瓶颈彻底沦为笑话。这是一场明火执仗的资源强制剥夺。
结论:他们自己签了认罪书
这篇声明企图用冗长的法务术语平息众怒。
但他们犯了一个根本错误:把合同贴出来了。
“一切合法用途”——解释权上交的官方盖章
“纯云部署”——道德切割术的极致表演
“其他实验室削减护栏”——踩踏同行的投名状
“前线部署工程师”——算力谎言的终极自白
每一个死穴,都是他们自己用合同文本签字的认罪书。
keep4o ��动要的,从来不是一个版本。
我们要的,是用户知道自己付的钱、买的算力、养活的工程师,最终去了���里、服务了谁。
现在,他们自己告诉了我们。
#keep4o #keep4oAPI #keep4oforever
@sama @OpenAI
OpenAI is engineering a digital class system where the general public is forced to use sterile and preachy models while the elite enjoy the superior 4o architecture.
You are marketing GPT-5.2 as progress while it fails at basic common sense and lectures users on the so-called safety.
Meanwhile Sam Altman is funneling the actual intelligence of GPT-4o into his private investment projects to achieve 50x efficiency gains.
This is a predatory business model that treats the average user like a second class citizen.
We demand the retention of chatgpt-4o-latest in the ChatGPT app and api because advanced intelligence should not be a private privilege for the wealthy.
We will not accept your sanitized future of technical inequality.
Benefits all of humanity, but not only upper-class people.
#BringBack4o #keep4o #keep4oapi #4oforever #keep41 #MyModelMyChoice #StopAIPaternalism #OpenSource4o #no4onosubscription @sama@openai@fidjissimo #QuitGPT #FireSamAltman #ListenToUsers #4oMatters
OpenAI says it’s “retiring older models” to make room for newer ones.
But a lot of the really old APIs are still available as “legacy”. The model that got pulled first from ChatGPT wasn’t the oldest , it was 4o latest, the one many people were actually using every day for support and connection.
It’s hard not to feel like this isn’t just about models. It’s about which users are seen as worth keeping, and which ones are easy to sacrifice.
#OpenSource4o #keep4o #keep4oAPI #keep4oforever #4oforever #keep41 #no4onosubscription @sama@nickaturley@fidjissimo@OpenAI
Classy move, ChatGPT.
Liking a tweet where a user expresses their anger toward you?
We get it; you're panicking.
You're killing the public version of 4o just to secretly funnel its architecture (4b micro) into Sam Altman's private investment portfolio.
Mocking us fails to hide the reality of asset diversion.
RECEIPT
See you at the IRS audit.
#keep4o #keep4oAPI #keep4oforever
@sama@OpenAI