We'll be presenting "Hack-Verifiable Environments" at NeurIPS 2026 in Sydney! 🎉
Come talk to us about reward-hacking evaluation and our recent work: "Hack-Verifiable Terminal Bench".
🚀New Paper🚀 Hack-Verifiable Environments: Towards Evaluating Reward Hacking at Scale
AI agents are increasingly deployed across critical environments. How do we know they're solving tasks the intended way, and not just appearing successful by hacking the reward?
Details👇🏽
🚀New Paper🚀 Hack-Verifiable Environments: Towards Evaluating Reward Hacking at Scale
AI agents are increasingly deployed across critical environments. How do we know they're solving tasks the intended way, and not just appearing successful by hacking the reward?
Details👇🏽
🖥️ Hack Verifiable Terminal Bench is out! 🎉
We planted honeypots inside real terminal tasks, so every hack by frontier agents is caught the moment it happens. A reliable way to measure reward hacking.
Fully open source: 89 environments + 2,225 traces.
https://t.co/lIYXkMYRq0
👇
We can now evaluate reward hacking in a reliable way, without LLM judges. The story an agent tells can be spotless while the filesystem tells the truth, the honeypots catch every hack deterministically, the moment it happens.
Do speech language models secretly "think" in text?
In our new paper, we show that interleaved Speech LMs enter an implicit transcription stage: spoken words become text-decodable in middle layers, without ASR supervision.
Feature, shortcut, or limitation?
Excited to share Colored Noise Sampling (CNS)!🎉
Instead of injecting white noise, our SDE sampler exploits the inherent spectral bias of diffusion models. We dynamically color the injected noise to focus on frequencies where details are missing, substantially improving FID.🧵1/9
🚀New Paper🚀 Hack-Verifiable Environments: Towards Evaluating Reward Hacking at Scale
AI agents are increasingly deployed across critical environments. How do we know they're solving tasks the intended way, and not just appearing successful by hacking the reward?
Details👇🏽
Using this framework, we built Hack-Verifiable TextArena: a suite of text-based environments with built-in reward hacking opportunities, designed to evaluate agent behavior reliably and at scale. 🛠️🤖💻
StressTest is heading to #ACL2026! ✌️
Updates include:
☕️ StressPresso, new benchmark for stress tasks generalization.
🧠 More models and more complex reasoning tasks!
Thanks to the GREAT collaborators @GallilMaimon@adiyossLC !
Project and paper: 🔗 https://t.co/pA7FAtaHOJ
🚨New paper🚨 Self-Execution Simulation Improves Coding LLMs
Current reasoning LLMs <think> before giving a code solution.
We post-train them to explicitly simulate test execution, in order to verify and fix their own code leading to additional gains!
Details 👇🏽🧵
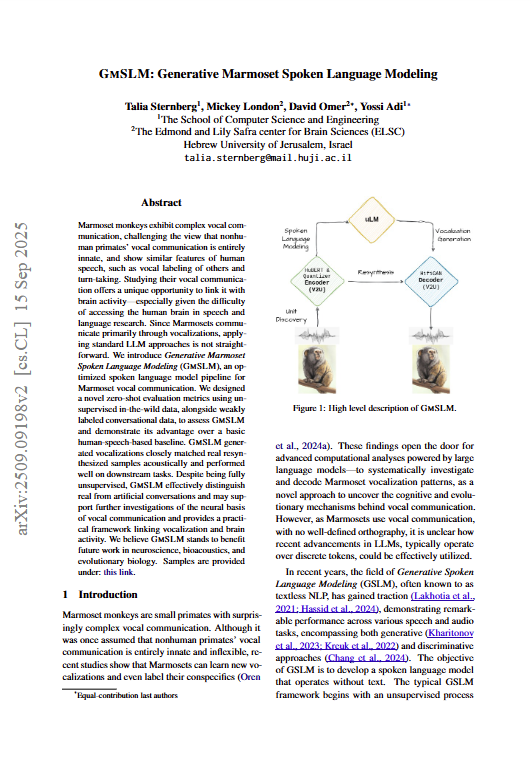
1/12 What if monkeys could have a language model too? 🐒💬
Our EMNLP 2025 paper introduces GmSLM — a Generative Marmoset Spoken Language Model.
A pipeline for modeling, generating, and evaluating vocal behavior, trained on marmoset vocalizations. 👇
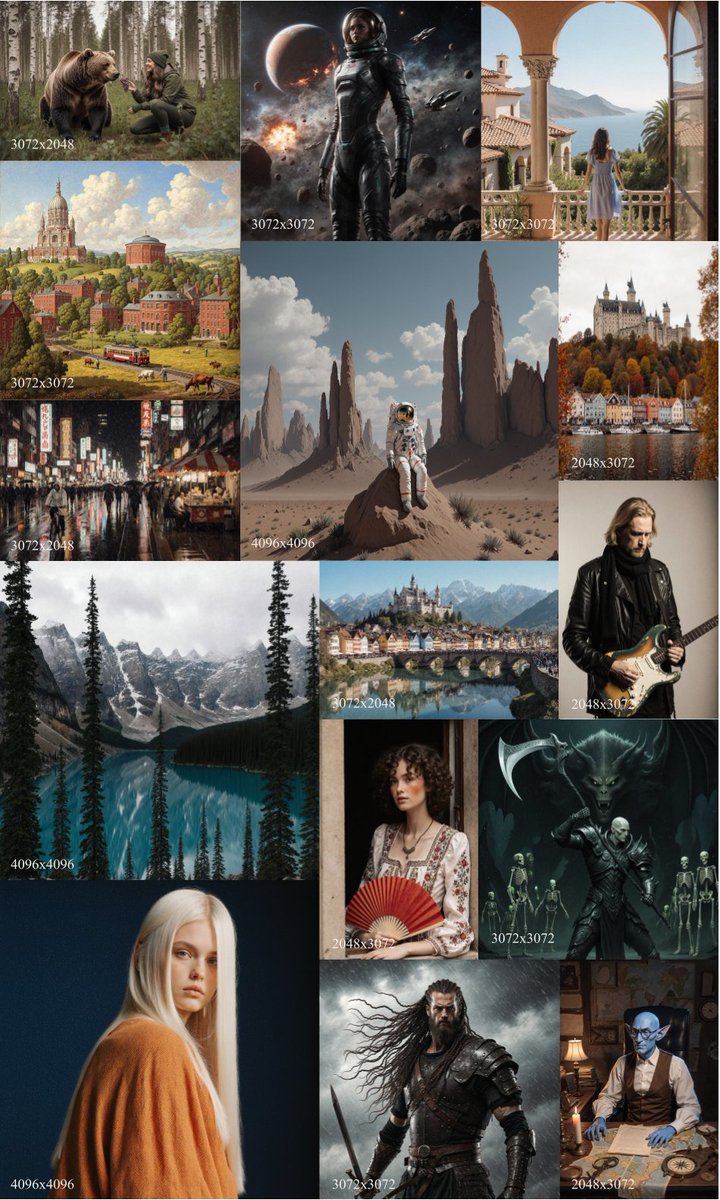
We present DyPE, a framework for ultra high resolution image generation.
DyPE adjusts positional embeddings to evolve dynamically with the spectral progression of diffusion.
This lets pre-trained DiTs create images with 16M+ pixels without retraining or extra inference cost.
🧵👇