🚀 Introducing ToolSpace🌟 — tool-centric environment synthesis for long-horizon agents!
ToolSpace flips data-centric Env scaling🧐:
• Real traces are linked into a tool space, and databases are synthesized only for stateful environments.
• State-aware exploration then turns executable chains into verifiable tasks and checkers.
🔥 Key Results:
• ToolSpace-744B averages 56.6 on 7 long-horizon tool benchmarks, on par with Claude Opus 5
• AutomationBench 54.7 · Harvey LAB 27.5 · SkillsBench 67.8 · OfficeQA Pro 67.1 · JobBench 57.5
• On the new Pro benchmarks, strong models all score below 40
💻 GitHub: https://t.co/VAklqIdLfC 📄 Paper: https://t.co/Ddz4U6nGBK
🌐 Project Page: https://t.co/gLjwXoGU72
🤗 Models: https://t.co/kUgtC2R1PQ
📎HF paper: https://t.co/RuIw1X6f1R
🙌 Try it, share feedback, and give us a ⭐!
Introducing Atria Dawn🫡 — the official release!
Atria is a 700B agentic foundation model for long-horizon tasks and real-world productivity 🙌
Upgraded from Preview: 512K context, stronger tool use and ML coding for stable long-horizon execution🥳.
📈 Excited results over Preview:
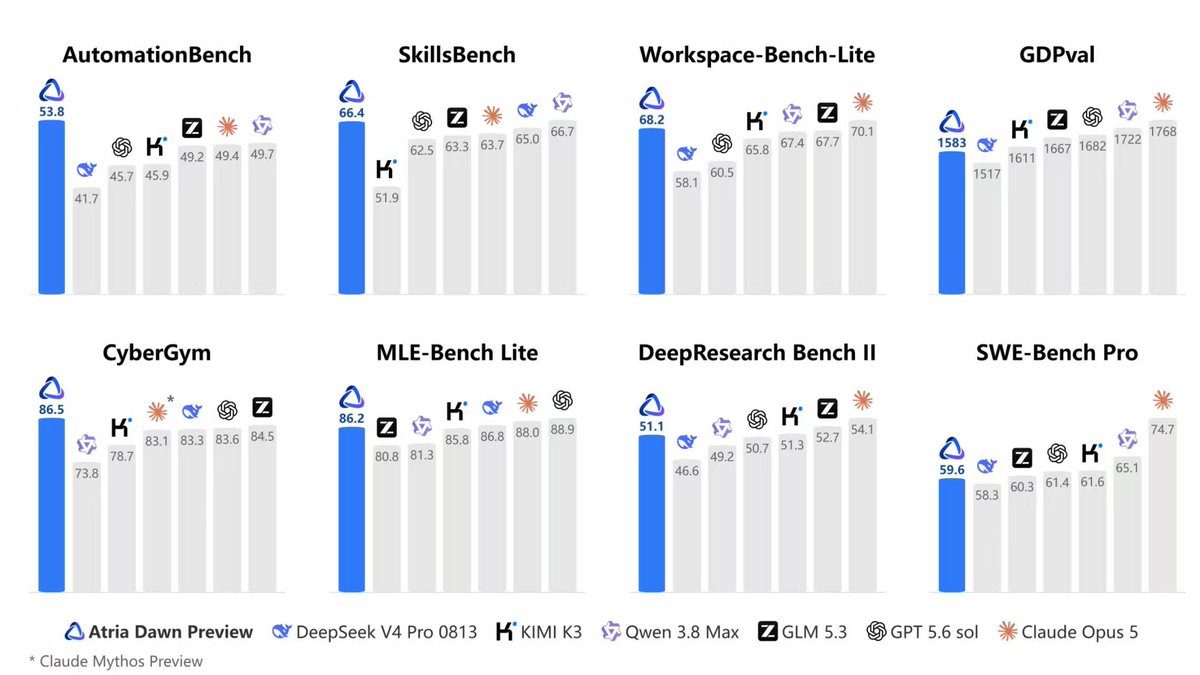
• Automation Bench 54.7%
• WideSearch 84.8%
• Workspace Bench 66.1%
• MLE Bench 88.2%
From protein structure training & CAD modeling to knowledge viz, PPT/poster design & data analysis
🌐 Homepage: https://t.co/T0Rk3Xnb7h
💻 GitHub: https://t.co/Jd1e1I7t5x
🤗 Hugging Face: https://t.co/J3eS1DJ403
🚀 Try it: https://t.co/WMbVxEFtAl
😃“From research questions to verifiable results” is the promise.
😉The proof? It ships.
🚀Meet Atria Dawn Preview @AtriaASI — an agentic foundation model for long-horizon tasks and controlled self-evolution, built on the Intern large model.
🌦️ 1 min → global weather forecast
🖥️ 20 min → OS from scratch
🧠 AI building AI, with verification in the loop Not uncontrolled RSI.
Verifiable. Reproducible. Controllable.
Open preview ↓
🌐 https://t.co/FrbzXjUWO6
💻 https://t.co/Hy1RZWskxn
🤗 https://t.co/WeUxKLbDai
🤖 https://t.co/pyYn4MRp8f
🐦 https://t.co/L41CISVoJO
#AtriaDawn #AgenticAI #RSI #OpenSource
Introducing Atria Dawn Preview:
From Research Questions to Verifiable Results.
Atria Dawn Preview is an agentic foundation model built for long-horizon tasks, helping researchers and engineers turn open-ended questions into executable, verifiable, and reproducible outcomes.
Explore Atria Dawn Preview:
🌐 Website: https://t.co/MDDspFiqYO
💻 GitHub: https://t.co/tNmLocadjT
🤗 Hugging Face: https://t.co/cyZod5oHbw
🤖 ModelScope: https://t.co/6BNi5vHFDl
🚀 Try Atria:
EN:https://t.co/Ap5aO2gQeu
ZH:https://t.co/cG16cQdx4j
We’re excited to highlight SETA, an open-source RL environment for training and evaluating AI agents from the @CamelAIOrg .
A valuable resource for researchers and developers exploring agentic reinforcement learning and complex task environments.
Check it out and support the CAMEL-AI community! 🚀
🔗 https://t.co/8evX0nL04f
I'm also excited to share our team's study on human–AI collaboration. Throughout the training process, we (almost) achieved recursive self-improvement (RSI)— and I believe fully automated RSI is not far away🥳 .
Meet Atria Dawn Preview, a new AI model from the Atria team, a collaboration between Shanghai AI Laboratory and multiple universities and research institutions.
Built for scientific productivity, Atria Dawn Preview is designed to tackle complex research tasks continuously, turning long-horizon work into progressively verifiable outcomes.
Its focus goes beyond solving individual tasks: Atria aims to strengthen end-to-end delivery in real-world workflows, from scientific automation to everyday office work.
Website: https://t.co/bfFfzpBtib
We’re grateful to OpenBMB for supporting Atria Dawn Preview with UltraData-SFT-Agent-2609.
The dataset’s high-quality agent trajectories have been valuable in developing Atria’s capabilities on agentic tasks.
🔗 https://t.co/PBAz6Q7J51
From solving tasks to partnering on entire projects.
We introduce Atria Dawn: The Dawn of Agentic Superintelligence — our study of what happens when agents move beyond answering questions to exploring, building, testing, and producing verifiable outcomes.
🔹 Verifiable Experience Pipeline
🔹 16 real-world benchmarks
🔹 #1 on 5 benchmarks
🔹 769 real task records from 56 participants
🔹 A case study of human–AI collaboration
The goal isn’t just more capable agents. It’s agents that can contribute to real research and engineering workflows under human oversight.
📄 Paper: https://t.co/DHrGx5iXhE