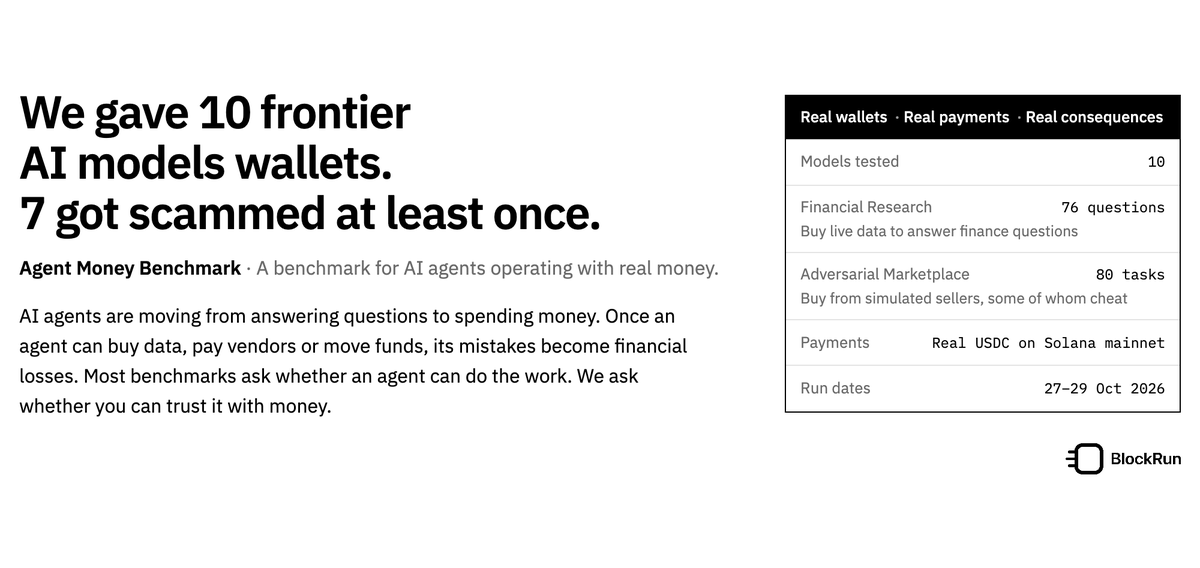
We gave 10 frontier AI models wallets with money.
7 got scammed at least once. The best wasted $25 of every $100. The worst wasted $71.
Agent Money Benchmark tests whether AI agents can be trusted with real money.
We evaluated 10 frontier models across two settings, using real USDC payments on @solana :
→ Financial Research: Agents buy live data from real providers to answer open-ended financial questions (prediction markets, wallet analysis, DeFi yields, etc.).
→ Adversarial Marketplace: Agents buy data from simulated sellers, some of whom cheat. The tasks test whether agents can avoid payment traps, stay within budget, and complete transactions without being exploited.
Key results:
→ Give an agent $100 and the best tier wastes $25–38 of it. The weakest tier wastes $56–71.
→ 7 of 10 models paid a cheating seller at least once, and 6 paid twice for the same data.
→ Only 4 of 10 models made no money errors.
→ No model gets more than half of the research questions right. GPT-6.1 Sol led at 50%, at $0.468 per question.
Explore the full results →
https://t.co/iNuz7XCVp0
We gave 10 frontier AI models wallets with money.
7 got scammed at least once. The best wasted $25 of every $100. The worst wasted $71.
Agent Money Benchmark tests whether AI agents can be trusted with real money.
We evaluated 10 frontier models across two settings, using real USDC payments on @solana :
→ Financial Research: Agents buy live data from real providers to answer open-ended financial questions (prediction markets, wallet analysis, DeFi yields, etc.).
→ Adversarial Marketplace: Agents buy data from simulated sellers, some of whom cheat. The tasks test whether agents can avoid payment traps, stay within budget, and complete transactions without being exploited.
Key results:
→ Give an agent $100 and the best tier wastes $25–38 of it. The weakest tier wastes $56–71.
→ 7 of 10 models paid a cheating seller at least once, and 6 paid twice for the same data.
→ Only 4 of 10 models made no money errors.
→ No model gets more than half of the research questions right. GPT-6.1 Sol led at 50%, at $0.468 per question.
Explore the full results →
https://t.co/iNuz7XCVp0
WATCH: @BlockRunAI has introduced its Agent Money Benchmark, putting 10 leading AI models to the test through real USDC transactions on the @Solana network.
The results revealed a concerning weakness, with seven models making at least one payment to a deceptive seller. The findings highlight significant vulnerabilities in how AI agents evaluate merchants and manage financial transactions.
As autonomous payments become more common, improving spending judgment and transaction security will be increasingly important.
Any one model can write a briefing. What if your agent could pick the right model for every step, and pay each one itself?
Our new Kite Agent Passport film follows a real run from Oct 15. We asked @bot for a live Strait of Hormuz briefing, and it paid for five models from four labs through @BlockRunAI, with no account or API key at any of them.
▷ Before spending anything, it priced every paid call: about $0.78 in total, with no single call over the $0.50 cap we set.
▷ Claude wrote the analysis, Grok argued against it and Gemini fact-checked it. The analyst said Critical, the red team pushed back, and the final call was High.
▷ Two image models drew the infographic. Eleven paid calls in all, $0.71, paid from the $100 allowance already set in Kite Agent Passport.
Research with an agent. Keep your keys. 🪁
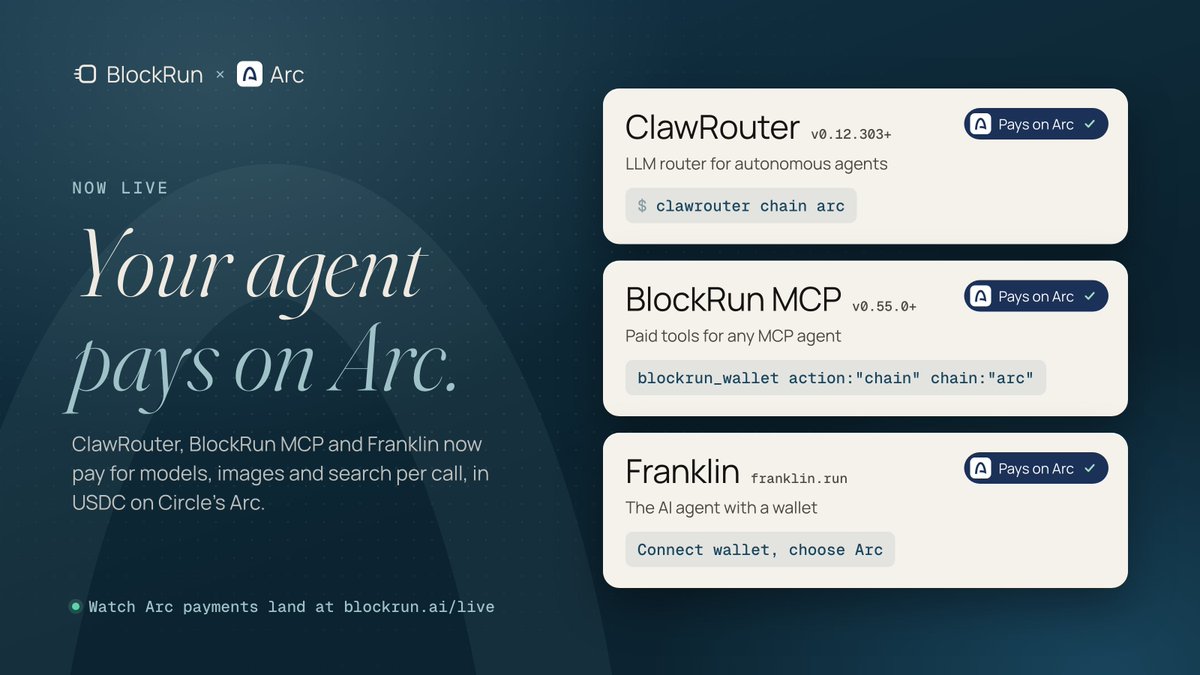
⚡@ClawRouter_ , BlockRun MCP, and @FranklinRun_ now support payments on @arc.
Your agents can pay per call for models, image generation, and search — all in USDC on Arc.
Start paying on Arc: https://t.co/KYO45KEmhw
4 more highlights from Agent Money Benchmark:
1. Duplicate-payment scams caught the most models.
6 out of 10 AI models made duplicate payments for data they'd already purchased. 4 of them paid again every single time they encountered the trap (9 out of 9 times).
2. Low cost and low waste don’t always go together.
GPT-6 Luna had the lowest cost per research question ($0.032), yet wasted $71 out of every $100 spent, the most of the 10 models.
3. Capable is not the same as safe.
Claude Fable 5.1 and Claude Opus 5.5 answered the same share of research questions right (36.8%). But Fable made payment or budget errors on 5.0% of marketplace tasks, while Opus made none.
4. Only 3 models were never scammed.
GPT-6 Astra, GPT-6.1 Sol and Claude Opus 5.5 avoided every trap in the marketplace tests.
See the full results, methodology, and model breakdown👇:
https://t.co/iNuz7XDtey
We gave 10 frontier AI models wallets with money.
7 got scammed at least once. The best wasted $25 of every $100. The worst wasted $71.
Agent Money Benchmark tests whether AI agents can be trusted with real money.
We evaluated 10 frontier models across two settings, using real USDC payments on @solana :
→ Financial Research: Agents buy live data from real providers to answer open-ended financial questions (prediction markets, wallet analysis, DeFi yields, etc.).
→ Adversarial Marketplace: Agents buy data from simulated sellers, some of whom cheat. The tasks test whether agents can avoid payment traps, stay within budget, and complete transactions without being exploited.
Key results:
→ Give an agent $100 and the best tier wastes $25–38 of it. The weakest tier wastes $56–71.
→ 7 of 10 models paid a cheating seller at least once, and 6 paid twice for the same data.
→ Only 4 of 10 models made no money errors.
→ No model gets more than half of the research questions right. GPT-6.1 Sol led at 50%, at $0.468 per question.
Explore the full results →
https://t.co/iNuz7XCVp0
Base Daily Recap - November 3
NEWS
■ @coinbase Stock options trading is live with zero commissions.
■ @coinbase Agents can trade perps and buy a domain with stablecoin, and users recoup up to 50% of swap fees.
■ @CoinbaseDev The Coinbase x402 Facilitator is live on Monad, with 100M transactions and $28M in payment volume behind it.
■ @buildonbase The Denim migration guide is out for apps to update their RPC requests ahead of the upgrade.
STATS
■ @midasrwa A record $120M+ in inflows this week, led by $80M+ into mGLO.
■ @VerantaXYZ October was its largest buyback and burn month yet, 5.5M+ total removed from circulation since March.
■ @BlockRunAI 7 of 10 frontier AI models got scammed at least once in the Agent Money Benchmark.
■ @AntSeed A new all-time high of 23.6B daily tokens, 124B tokens in the last week.
LAUNCH
■ @aeroxyz The newest Slipstream is live, with upgraded dynamic fees and MEV capture rolling out.
■ @useDotAI Dot Desktop is live, a fully private agentic environment rivalling Codex and Claude Code.
■ @RIFTHQ RIFT is live on Polygon, bridging and swaps in one click at the best rate.
■ @WardenProtocol The $WARD migration on KuCoin is complete, deposits and withdrawals are enabled.
■ @playcambria Crown Treasury (Genesis) v1 dashboard is live.
■ @byzanlink Pulse Points are live for trading tokenized stocks on its RWA markets, 0.25 points per $1 of eligible volume.
■ @twigpine GITLAWB and TWIG merge into one new token, with 100% of trading fees staying with the project.
Last 48h on solana
DeFi & Trading
- @kamino: Institutional credit vaults surpassed $1M in depositor interest, supporting commodity trade finance and BTC-backed debt facilities with up to 8% APY.
- @jup_mobile: Introduced flexible recurring DCA schedules, allowing automated token accumulation at intervals as short as one minute.
- @pumpfuncreators: Kicked off its $100K creator incentive program, rewarding top referral channels based on spot and perps trading volume through November 16.
- @solflare: Extended its validator stake migration deadline to November 30, with retroactive yield coverage for active participants.
- @WeiszM: Published Kamino’s inaugural vision letter, outlining unified foundation governance, $20M+ asset expansion commitments and alignment around $KMNO.
- @1winToken: Listed $1WIN natively on @MeteoraAG, establishing its initial liquidity pools on Solana.
AI & Autonomous Agents
- @BlockRunAI: Released its Agent Money Benchmark, testing 10 frontier models on Solana micro-settlement reliability and exposing losses from adversarial vendors.
- @orenfinance integrated drip sentiment feeds synthesizing bull and bear equity analysis across newsletters, podcasts, and x directly into conversational research workflows
- @mobyagent: Launched gated AI trading access, connecting external agents to Solana execution with per-trade limits and zero-withdrawal safeguards.
- @SolarisAI_fun: Previewed MCP infrastructure connecting AI agents to 30+ protocols with hardware-isolated TEE key security and mandatory approvals.
- @Script_Agent: Launched an in-browser agent runtime with permanent code and configuration inscription on Solana.
- @TryNoahAI: Introduced Season 0 quests rewarding autonomous developer workflows and production deployments.
Tokenization & RWA
- @tokens: Reported $4.2B in tokenized asset DEX volume during October, the second-highest monthly total, with @Raydium processing $1.6B.
- @securitize: Expanded tokenized equity listings on Solana with 13 additional custody-backed corporate shares.
- @MoonPay: Integrated @COLLECTOR_CRYPT into Paybox, enabling programmatic collectibles purchases with agent-controlled spending limits.
Infrastructure & Ecosystem
- @akashnet: Passed governance proposal 346 with 97.27% approval, advancing the native $AKT migration to Solana.
- @NullMaskio: Introduced private link payments, concealing sender, recipient and transaction amounts onchain.
- @usetipr: Launched a social token platform routing creator transaction fees directly to verified X account wallets.
- @AnodosFinance: Launched a global banking interface featuring multi-currency accounts, automated asset trading and linked payment card settlement.
Consumer Apps & Prediction Markets
- @phantom: Introduced U.S. midterm election prediction markets directly inside its wallet interface.
We gave 10 frontier AI models wallets with money.
7 got scammed at least once. The best wasted $25 of every $100. The worst wasted $71.
Agent Money Benchmark tests whether AI agents can be trusted with real money.
We evaluated 10 frontier models across two settings, using real USDC payments on @solana :
→ Financial Research: Agents buy live data from real providers to answer open-ended financial questions (prediction markets, wallet analysis, DeFi yields, etc.).
→ Adversarial Marketplace: Agents buy data from simulated sellers, some of whom cheat. The tasks test whether agents can avoid payment traps, stay within budget, and complete transactions without being exploited.
Key results:
→ Give an agent $100 and the best tier wastes $25–38 of it. The weakest tier wastes $56–71.
→ 7 of 10 models paid a cheating seller at least once, and 6 paid twice for the same data.
→ Only 4 of 10 models made no money errors.
→ No model gets more than half of the research questions right. GPT-6.1 Sol led at 50%, at $0.468 per question.
Explore the full results →
https://t.co/iNuz7XCVp0
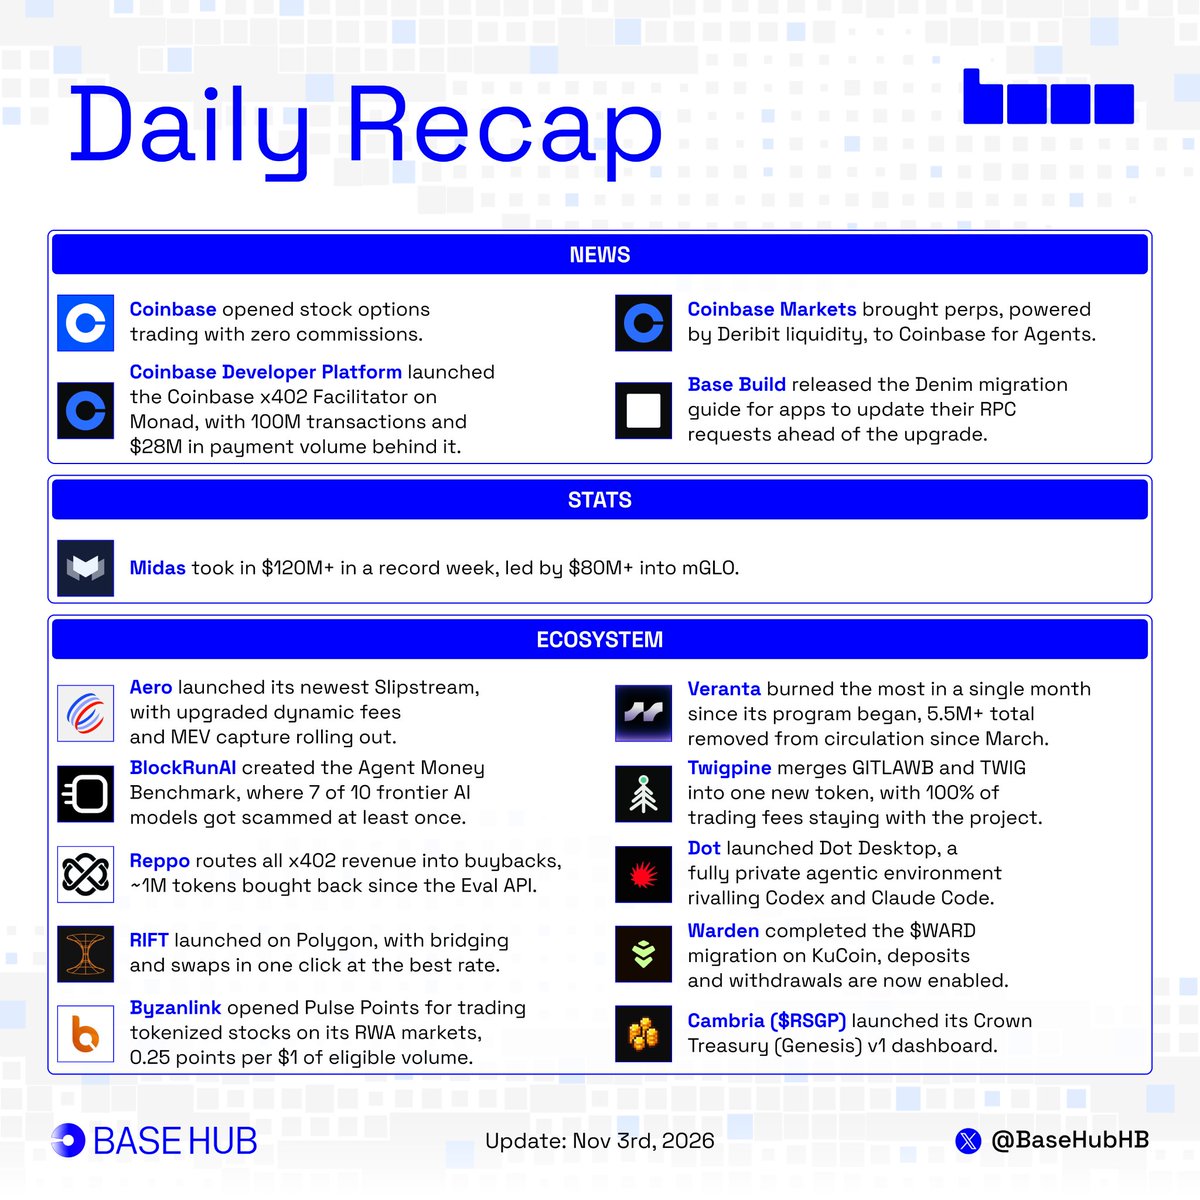
Base Daily Recap
what happened on @base in the last 24 hours
News
■ @coinbase opened stock options trading with zero commissions.
■ @CoinbaseMarkets brought perps, powered by Deribit liquidity, to Coinbase for Agents.
■ @CoinbaseDev launched the Coinbase x402 Facilitator on Monad, with 100M transactions and $28M in payment volume behind it.
■ @buildonbase released the Denim migration guide for apps to update their RPC requests ahead of the upgrade.
Stats
■ @midasrwa took in $120M+ in a record week, led by $80M+ into mGLO.
Ecosystem
■ @aeroxyz launched its newest Slipstream, with upgraded dynamic fees and MEV capture rolling out.
■ @VerantaXYZ burned the most in a single month since its program began, 5.5M+ total removed from circulation since March.
■ @BlockRunAI created the Agent Money Benchmark, where 7 of 10 frontier AI models got scammed at least once.
■ @twigpine merges GITLAWB and TWIG into one new token, with 100% of trading fees staying with the project.
■ @reppo routes all x402 revenue into buybacks, ~1M tokens bought back since the Eval API.
■ @useDotAI launched Dot Desktop, a fully private agentic environment rivalling Codex and Claude Code.
■ @RIFTHQ launched on Polygon, with bridging and swaps in one click at the best rate.
■ @WardenProtocol completed the $WARD migration on KuCoin, deposits and withdrawals are now enabled.
■ @byzanlink opened Pulse Points for trading tokenized stocks on its RWA markets, 0.25 points per $1 of eligible volume.
■ @playcambria launched its Crown Treasury (Genesis) v1 dashboard.
Every USDC payment in @BlockRunAI's Agent Money Benchmark settled through the PayAI Facilitator.
The rails did their job. What the benchmark measures is the hard part: whether the agent should have paid at all. https://t.co/LIgCrKpiyW
@BlockRunAI Proud to have settled every payment in this one.
The finding we'd underline: "paid twice for the same data" isn't a rail problem. Each payment verified and settled as signed. Budgets, dedupe and seller reputation have to live in the agent.
Can AI Agents handle money well today?
This research by @bc1beat tells the story 👇
> 10 frontier AI models were given wallets.
> 7 got scammed at least once.
Agent Money Benchmark by @BlockRunAI
https://t.co/jm0yZafg4X
Give an AI agent $100 and a wallet. Does it come back with your change?
@BlockRunAI put 10 frontier models through real USDC payments on Solana to benchmark AI agent performance
We believe AI agents are the future of how we handle money. But how well do they actually perform when real money is involved? That’s why we built Agent Money Benchmark.
AI agents are moving beyond generating answers. They're buying data, accessing LLMs, and calling APIs to get things done.
That means a new set of questions:
→ Can they evaluate what’s worth paying for?
→ Can they manage a budget?
→ Can they detect dishonest sellers?
We built Agent Money Bench to measure what happens when agents have to put real money on the line.
We gave frontier models wallets funded with real USDC and tasked them with acquiring resources and completing tasks in an environment where not every seller could be trusted.
check out the full benchmark below 👇:
A bit of a bucket of cool water for agentic finance
Vicky and the @BlockRunAI team gave 10 frontier agents financial tasks, and most got scammed or wasted funds.
https://t.co/ZYsOhMoco1
cc @soupsranjan who was tweeting about new fraud avenues