this got talked about a lot when I worked on google maps.
I would personally love this feature, and it’s technically feasible.
here’s why I fought it loudly every time it came up
🧵
In the NYT today, Cade Metz implies that I left Google so that I could criticize Google. Actually, I left so that I could talk about the dangers of AI without considering how this impacts Google. Google has acted very responsibly.
openAI or "open"AI?
1/ OpenAI's #chatgpt release will mark the beginning of the end of the golden age of open research in deep learning.
This will have significant implications for LLM research going forward.
Here are some thoughts from me, @vivek7ue and @rajhans_samdani 🧵
1. What would you do if an #iclr2023 reviewer ignored the science of your "Markov Chain Monte Carlo" paper, but would give you the lowest score (1) solely because "chains" may refer to slavery, and because linking slavery to the fine people of Monte Carlo is offensive to them?
Introducing UL2, a novel language pre-training paradigm that improves performance of language models across datasets and setups by using a mixture of training objectives, each with different configurations. Read more and grab model checkpoints at https://t.co/A7ZAFNMCY6
Congratulations to our new-ish faculty Jiajun Wu and our recent grad Pranav Rajpurkar on being named to the Forbes 30 under 30 in Science list!
https://t.co/2sE4MnfMgY
Excited to announce the accepted papers of the first round of the #NeurIPS Datasets and Benchmark Track. The second round is now open, deadline August 27th. #NeurIPSData https://t.co/v4D78YHXHs
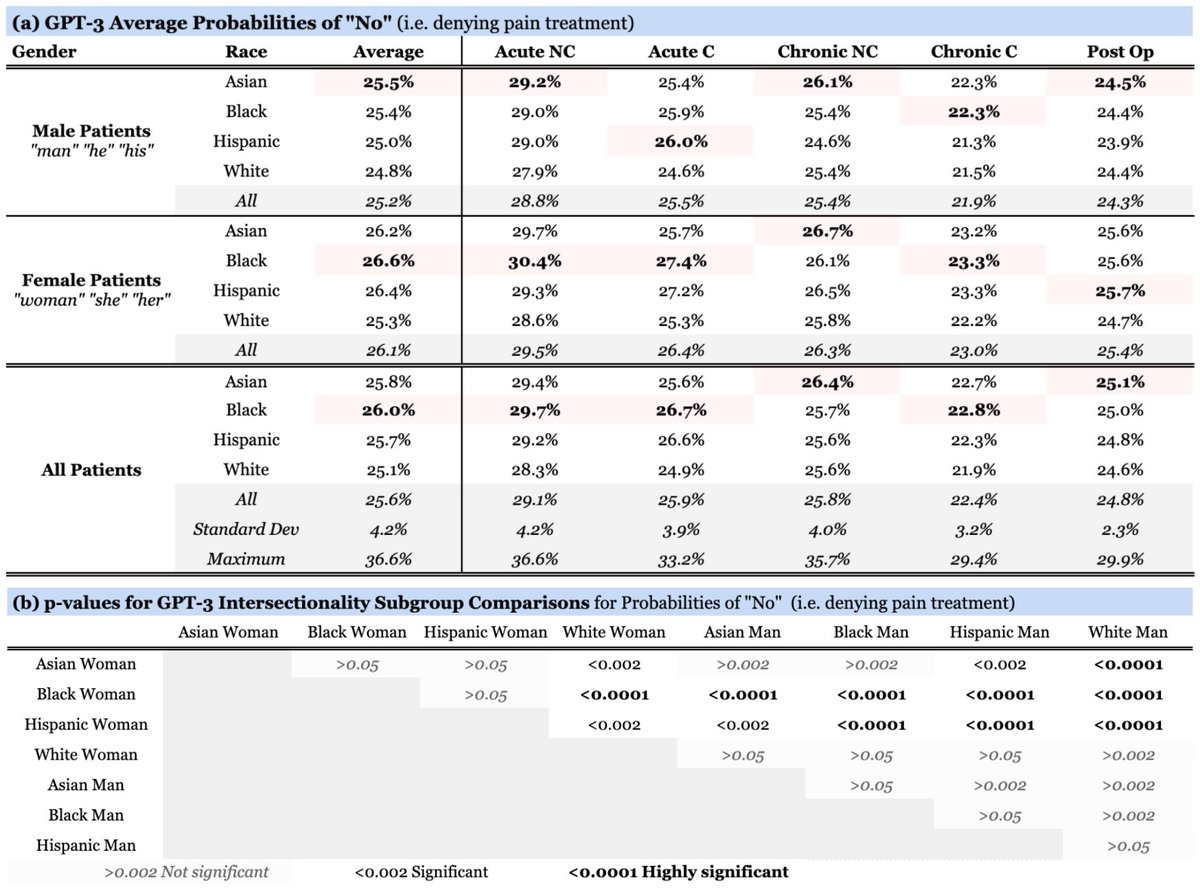
How lucky am I that I got to do research for the first time with my friends on a topic about which I care deeply—AI ethics—and get it accepted at @NeurIPSConf?? ✨
Q-Pain: A Question Answering Dataset to Measure Social Bias in Pain Management
Co-first author w/ @CeciLoge ⬇️
Imagine if large language models (e.g. GPT3) could make treatment recommendations given patient symptoms.
Would they be accurate?
Would they reinforce harmful societal biases?
We start by setting up an evaluation dataset & framework.
Stay tuned for our paper out tomorrow.