@wiedymi I think it's an okay model, but highly recommend you use either MLX-Serve, Sushi or TensorFold for the most optimized experience. Can't really go wrong with either tbh and then your harness of choice.
https://t.co/U2495QEi0c
https://t.co/y5tb9zOFv3
https://t.co/IlvCeXB7Xt
Qwen3.8-Flash-Next support added for M1-M6 32GB. Get 🍣 Sushi-2bpw pack, stream from disk, no quality loss. Context ~66000, M1 Max: prefill ~200 tok/s and gen ~18 tok/s!
Compile from main or wait for Sushi v1.2
⭐️ https://t.co/U0zFJh3xKV
Omarchy now has an official bug bounty program on HackerOne! The Omacom Foundation has funded it with $100,000 for bounties, and we've promoted @mdisec to Omarchy Core as our Head of Security. https://t.co/CEODf0leTA
Cool eval. Simply ask an LLM “Land or Water?” and give it a latitude and longitude coordinate as text. Ask 16,200 times, plot as image. The models know. From compressing the internet.
Six months ago I had a hunch.
Local AI won't become the norm until it feels instant. Running a model on your own machine should feel like magic, not like tapping your fingers waiting for a reply.
The response to TensorFold since has blown me away. Thank you to everyone testing it, sending PRs and sharing feedback.
There's a lot more speed to unlock. Right now most of my time goes on reviewing and landing PRs. That matters, and every fix makes TensorFold better, but the biggest gains are in deep performance work I can't get to quickly.
If you want to see what TensorFold can really do, backing would let me work on it full time, with the hardware to test faster and dig into performance, and bring it to everyone in local AI.
All in the open under Apache-2.0.
We have been made aware that TF is being run in real production environments, so we could potentially look into support packages.
To back the project, sponsor hardware or talk about support, my DMs are open.
Even just sharing this post helps. 🫶🏼
Hate to say it here, but the new Gorgon Halo at it's price today is NOT the value the Strix Halo offered.
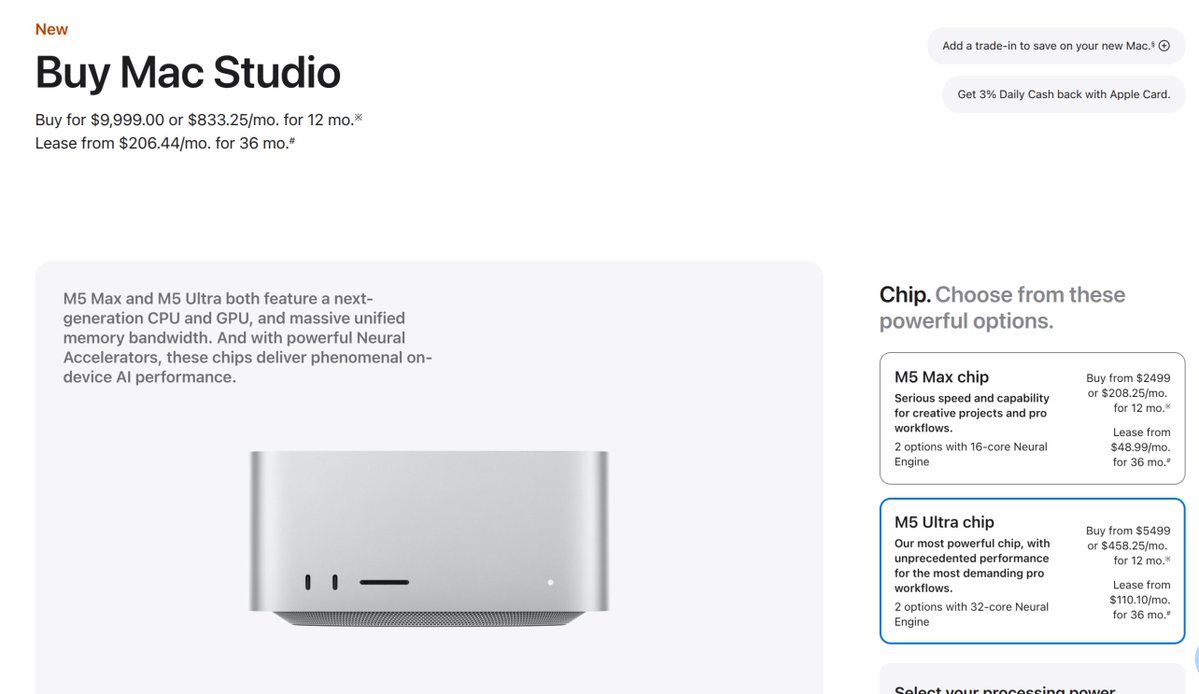
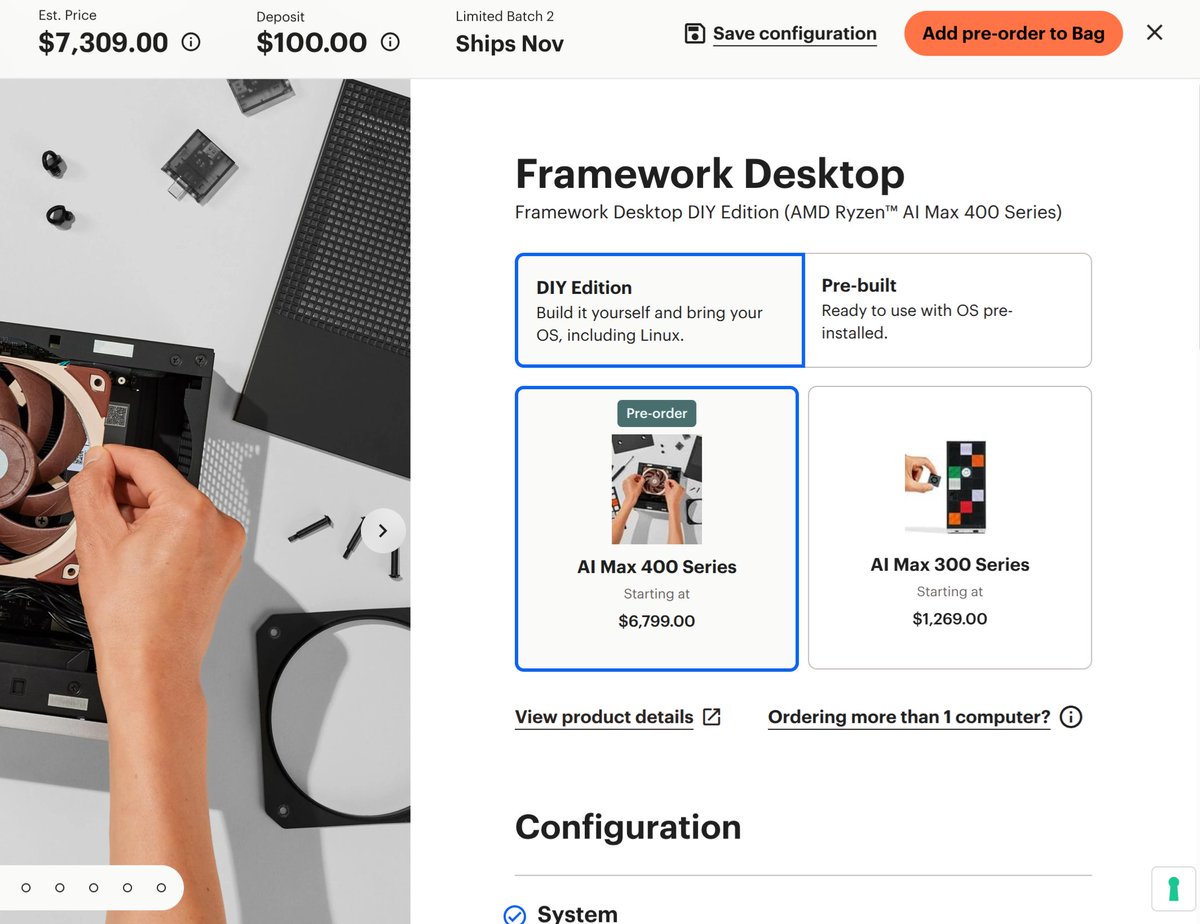
I configured a M5 Ultra and a Framework AI Max 400 both w/ 2TB storage.
Hate to say it, but on raw $/GB the two are a wash; on
bandwidth-adjusted $/GB the Mac is ~3x cheaper.
System $/GB │Mac $39.06 | FW $38.07
Memory bandwidth | Mac 1.2 TB/s | FW 273 GB/s
Bandwidth-adjusted $/GB ($ ÷ GB × TB/s)
Mac $32.60 │ FW $140.00
the Mac has 1.33x the memory and 4.4x the bandwidth for only 1.37x the price
while the framework looks $2,690 cheaper, you are not actually getting the same level of value for your investment returned to you.
And since thunderbolt & usb4.0 are pretty dang fast, you can shave another $500 off the Studio by dropping down to a 1TB storage drive and using external storage if you got it.
For local AI.... Apple is starting to look like they want to take NVIDIA and the DGX Spark head on.
It's a HELL of a value.