I wrote a song about my GPU refusing to run AI locally.
8 months ago it was a joke.
This week it's the news.
Not sure whether to be proud or scared...
@NVIDIAAI Save us from a future with no VRAM! https://t.co/FXwyG8mJpU
I was wondering what would be the collective of sparks. A "Shimmer" of sparks? or something more like a "Flurry of sparks? I don't quite like "cascade" or "shower".
Here are my favorites what is yours:
a shimmer of sparks
a dazzle of sparks
a mischief of sparks
a riot of sparks
@OnlyPromptsxAi A prompt to help me fix graphics in a 2D Sprite game in Unreal engine 5.8 using paper 2D. Prompt for all common issues that can happen when using Paper 2D.
The biggest question of this season: "To buy or not to buy?"
GPUs are sold out almost everywhere. And honestly? With the amazing open models dropping right now, it's obvious this hardware has never been more valuable.
But that raises new questions…
The new Mac Studio? 512GB of unified memory is a slap in the face to Nvidia — nothing they offer comes close on memory.
So the looming question hangs in the air: will Nvidia even try to compete? Or are they comfortable resting on their laurels?
Buy Nvidia? Buy Apple Silicon? Or wait?
But here's the catch — if the memory drought doesn't end soon, waiting might mean nobody can afford anything at all. 🧵👇
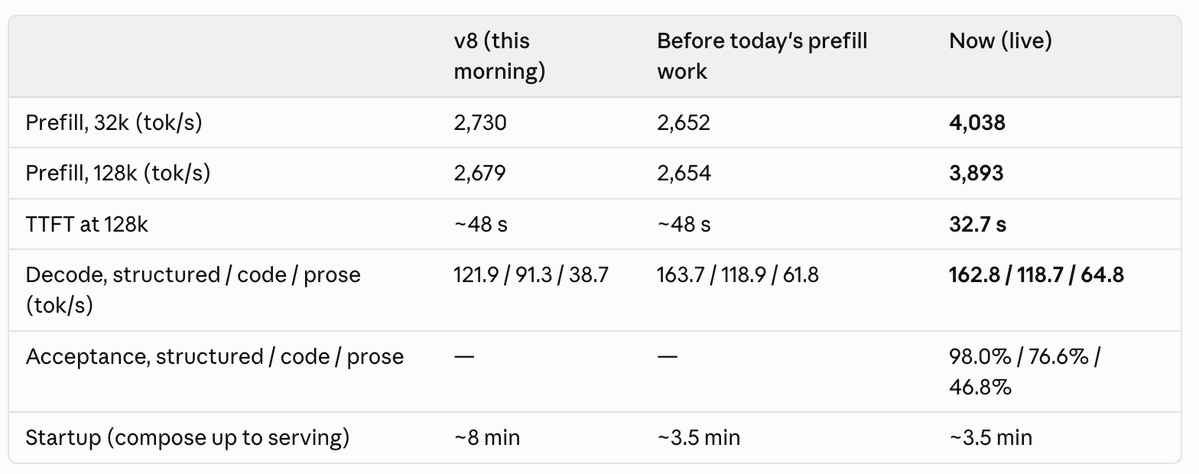
There is a _lot_ of optimization potential left in GLM 5.3 Flash on DGX Sparks. I'm excited to share my MTP approach - I'll be upstreaming it to vLLM once it's fully tested.
Already prefilling almost double what I was before the experiment (!).
TP=4 for now, but stay tuned.
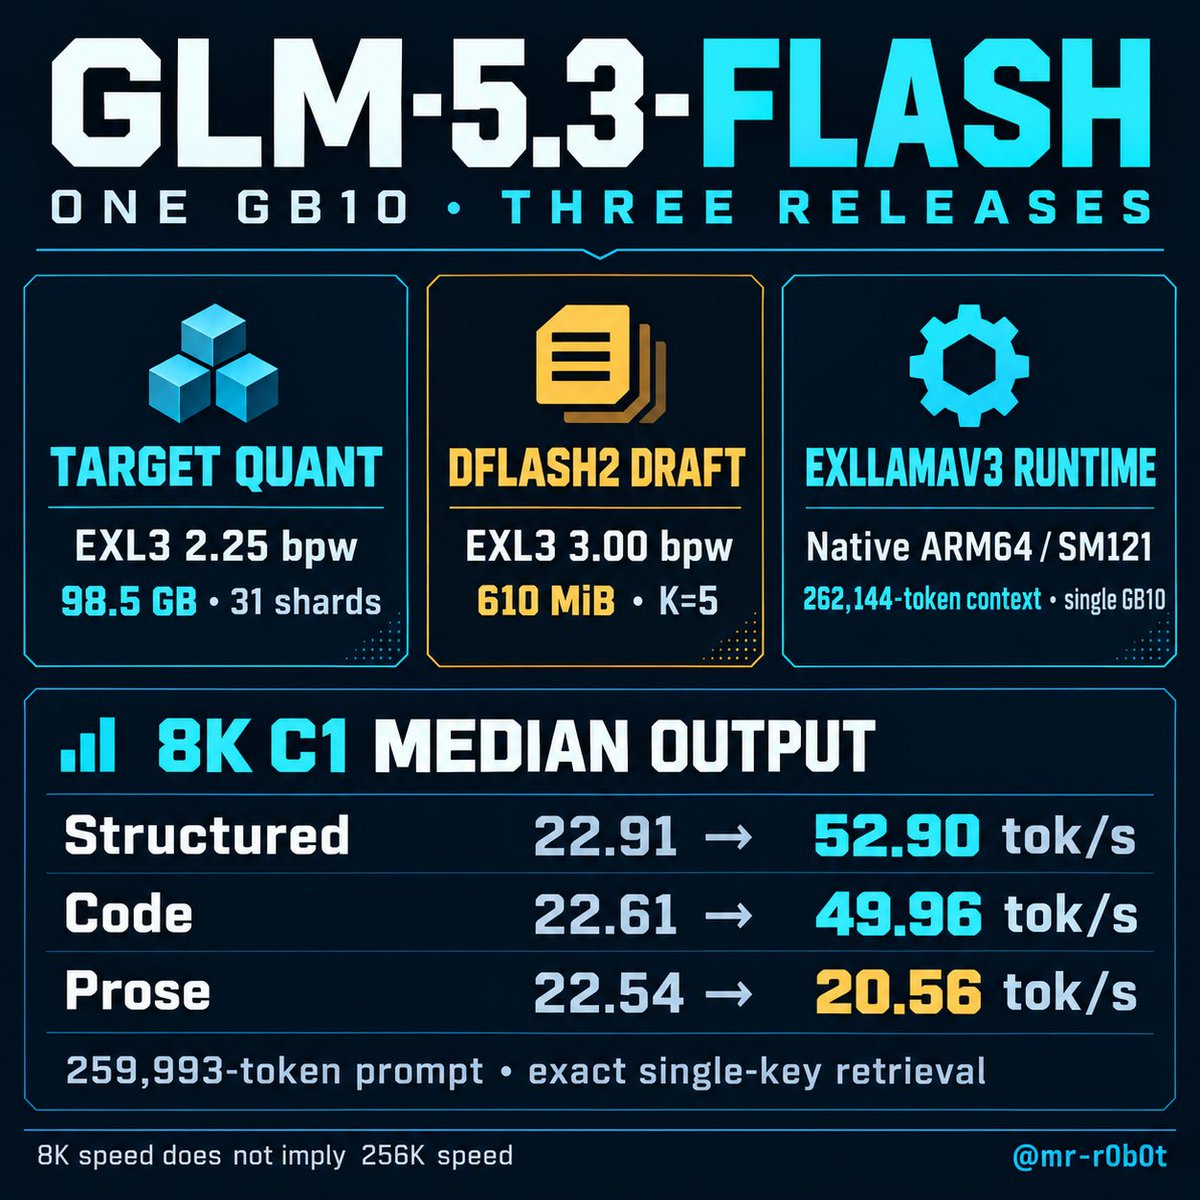
r0b0tlab/GLM-5.3-Flash-EXL3-2.25bpw-sm121 + 3.00bpw DFlash2 drafter + native ExLlamaV3 runtime!
Tested on a single @NVIDIAAI
GB10 ♥️
At 8K C1, code: 22.61→49.96 tok/s with K=5
Exact single-key retrieval at 259,993 prompt tokens
Extended eval suite in progress 🤓
People are addicted to "Us against them" mentality, that is not productive.
I would not have had the money to have used the 6 Billion tokens from the past 2 months if I only had API to use.
At least 1-3 B were from Mia's recipe for GLM 5.3 Flash.
1-2 were smaller models for smaller tasks.
around 1.2B was a combination of Claude, Astra and Deep Seek V4 and V4.1 Flash (API).
I got over 3 times the volume of work that I would have done for less.
Not seeing things from this angle is just wasteful.