We are looking for a Founding AI Researcher to join our team at @luceboxai
if this is you, reply with your best research work
if you know someone, send them this post
why join:
- probably one of the coolest research jobs right now, making large open models run fast on hardware people can actually own is an amazing mission
- you'll be setting the research agenda with us founders. research is really at our core
- you take open problems from idea to result, your experiments, your call
- post-training and fine-tuning open models end to end on our own hardware
- your research ships, into our open source engine (apache 2.0) and into every lucebox
- if you want to learn where gpu time really goes, you can learn it here, if you already love reading kernel code, you can do it here
- you get one Lucebox maxxed completely for you + you will be working with our A100 on site server.
- backed by Y Combinator, and the founders of Hugging Face, Github, LambdaTest.
what might be dealbreakers to some:
- we work in person in Milan, Italy, so we want you here
- you need to be self-driven, there won’t be a more senior researcher to coach you here
- there is a take-home project
- the italian espresso will ruin all other coffee for you
if you made it this far, reply with your best work, or apply at https://t.co/RfJbJiaJgr. bonus points for submitting a PR to our repo (no slop).
One Lucebox now reviews every pull request on our main repository, tells us why a job failed, and runs the Linux jobs we move to it from GitHub Actions.
The code never leaves the office. Our CI bots costed us about $1,340 a month on hosted models. The box costs $8,199 once and about $310 a month to run, and pays for itself in about 7 months.
More info in the article below or here: https://t.co/BadshWNkOg
Introducing AgentWeb: reliable web infrastructure for generalized agents.
47/47 real world tasks on live sites. 1.9s median. $3 total.
Request access: https://t.co/KsgVebkvLT
As Physical AI/SI advances, we plan to redouble our efforts to provide global autonomous insurance coverage that progresses along with technology. Read more about us at @TechCrunch
https://t.co/4xinwiAwae
Inworld is your new favorite inference provider.
We already process tens of trillions of tokens a month because we understand consumer AI different, and we've built our inference from the ground up for it.
Today, the inference top consumer AI apps run on is opening up.
The first Lucebox Zero 495 batch is almost sold out. Only a few units left at https://t.co/cBkaYvqhGe
Huge thank you to every customer who's come through so far. Once batch 1 sells out, new orders move to the next batch at a higher price.
I also updated the image to make pricing clearer, so it now shows the price for each configuration:
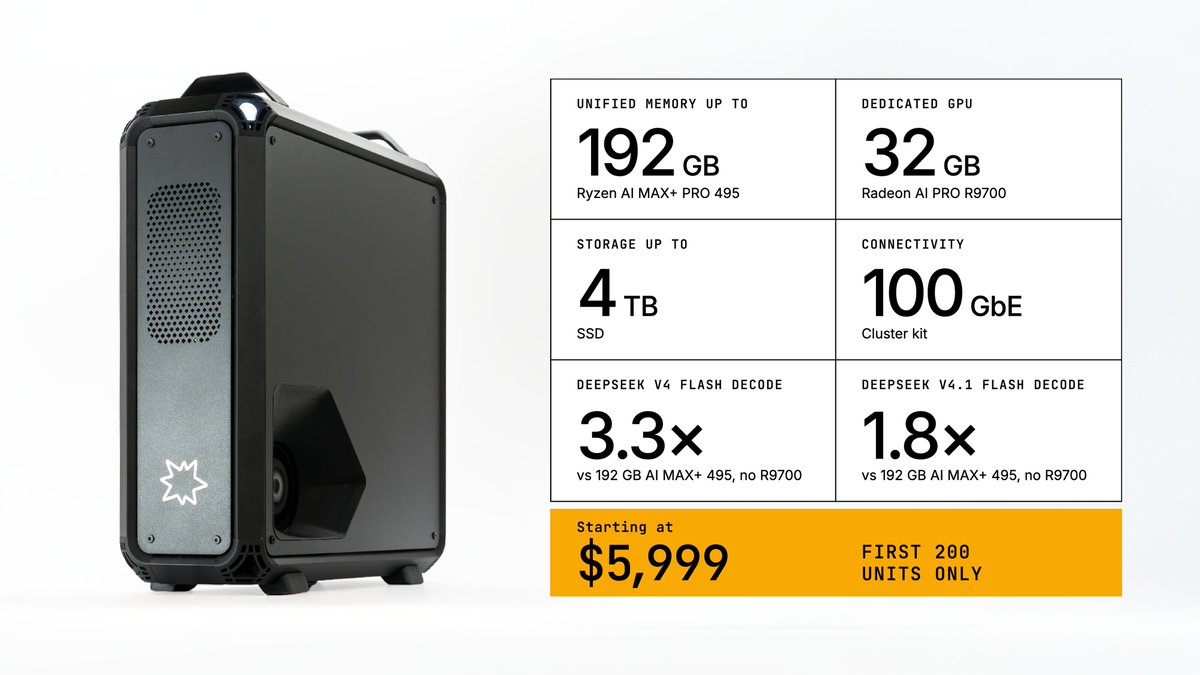
- 128GB + 2TB: $5,999
- 192GB + 2TB: $7,999
- 4TB SSD upgrade : +$250
- Cluster kit: +$799 per machine
Every configuration comes with the 32GB Radeon AI PRO R9700, and we've further optimized it for V4.1 Flash with our new quants. Full details in our latest blog post.
One of the main pieces of feedback we got on the Lucebox Zero 495 is that it's not clear why it matters to have both unified memory and a discrete GPU in the same machine.
It matters a lot. In the article below, we show how the R9700 gets you 3x the speed on a big model like DeepSeek V4.1 Flash.
The Lucebox Zero 495 runs the model across three tiers of memory: the 32 GB on the Radeon AI PRO R9700, the unified memory of the Ryzen AI MAX+ PRO 495, and the SSD.
Each expert lives wherever its usage justifies it. Compared with the same chip without the R9700, a long prompt gets its answer about 3x sooner, and code generation reaches up to 49 tok/s.
Amazing work from: @davideciffa@DeanoC@GeometricAGI@luceboxai
Orders are now open for the new Lucebox Zero 495: https://t.co/RgIKxCDvcs
It’s AMD’s new Ryzen AI MAX+ PRO 495 with up to 192GB of unified memory, plus a 32GB Radeon AI PRO R9700 in the same box.
Lucebox engine split the model by how often each part runs. Dense layers, the hottest experts and the drafter go on the R9700, because nearly every token reads them. The long tail of experts, which most tokens skip, stays in the 495's unified memory. Both chips compute at the same time. 15 tok/s on the 495 alone, 50 with the R9700.
You can get also up to 4TB SSD and 100 GbE cluster kit, installed.
First 200 units are $1,000 off. Deliveries expected in January.