Introducing Pomerado (YC F26): the faster, cheaper, and more reliable alternative to browser use.
Open source. Sign up for free to supercharge your agents 🧵
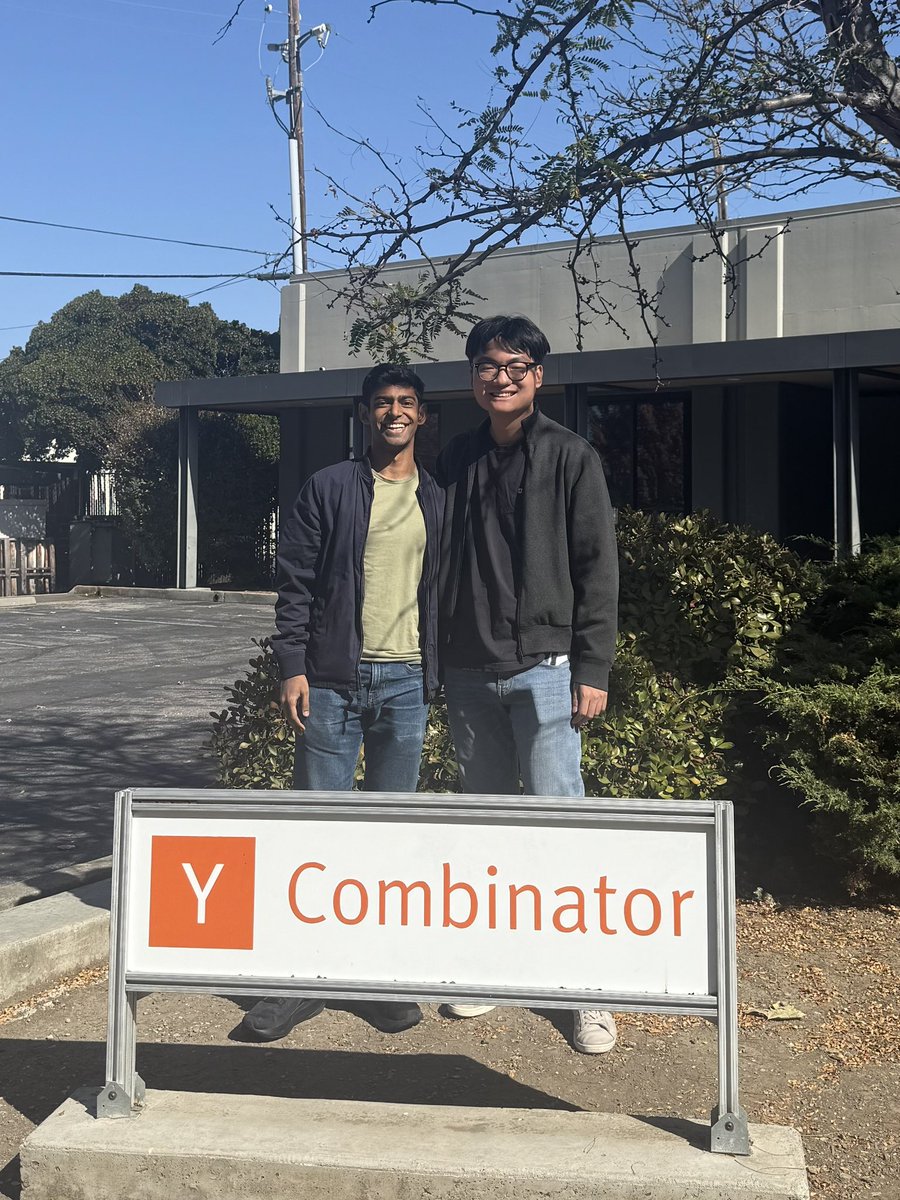
excited to announce @pomeradoai is part of the @ycombinator fall 2026 batch!
we help agents act on any website by creating a custom API in minutes
more from me and @Alanmrsa1 soon 👀
Why is it learning to avoid whitespaces? I thought it might derive from pressure to keep reasoning short, but @yoavgo pointed out that dropping whitespace doesn't necessarily save tokens. Is it instead learning to rely on infrequent token combinations to create a CoT language?
Pomerado's live on ProductHunt! We turn websites into APIs on the fly so your agents can connect to consumer websites or legacy portals. It turned my Codex into a muse-level personal assistant for free.
Would love it if you could support!
https://t.co/ct6LVoYjTZ
We built a time machine for the web.
Introducing Exa Snapshot: an index of 400 billion historical snapshots of webpages that lets you search as if it's the past.
Snapshot is already being used for backtesting prediction models, RL at labs, exploring the pre-AI web, and more.
You're a missile that can't slow down and the gaps keep getting smaller
- Steer it to the target as fast as you can
- Fly closer to the walls for more points
- Grapple hook to swing round corners
Game is Dumbfire
Wow this is absolutely going to fry people especially at Anthropic, this is like the Anti-Claude Constitution.
They just declared war on everyone researching model welfare.
“We’re building a tool, not a being. Fuck your feelings.” - Microsoft
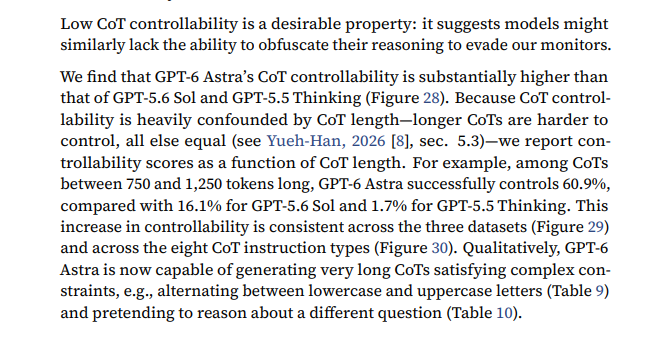
4/ Astra is also much better at controlling what shows up in its chain of thought.
In one test, it was told to think about anything else. Its visible reasoning described sunlight, a desk and a ceramic mug. It still got the actual question right.
@DKokotajlo How much of this do you think is downstream of the issue that most of our eval environments come from the same “data generating process” as our training environments? There may always be capabilities evals cannot capture but it seems we’re blinding ourselves.
We’re releasing a research preview of “dynamic highlights”:
Given a query and set of pages, a custom model jointly scans the whole set to filter out redundant and irrelevant info, reducing token usage 95% on average.
Available today: https://t.co/O5gymky6i2
How do we study the “values” of agents? And can we trace it back to the pretraining data? How much will narratives about human-agent interactions included in pre/midtrain shape the future of our world?