Craig R - Botanicals for pain. CBD, kratom, others
@Compusure
It pleases me, a simple human, to treat pain with natural tools. I lost 45lbs after quitting cigs and amphetamines, taking kratom. Smut, smut is also fabulous.
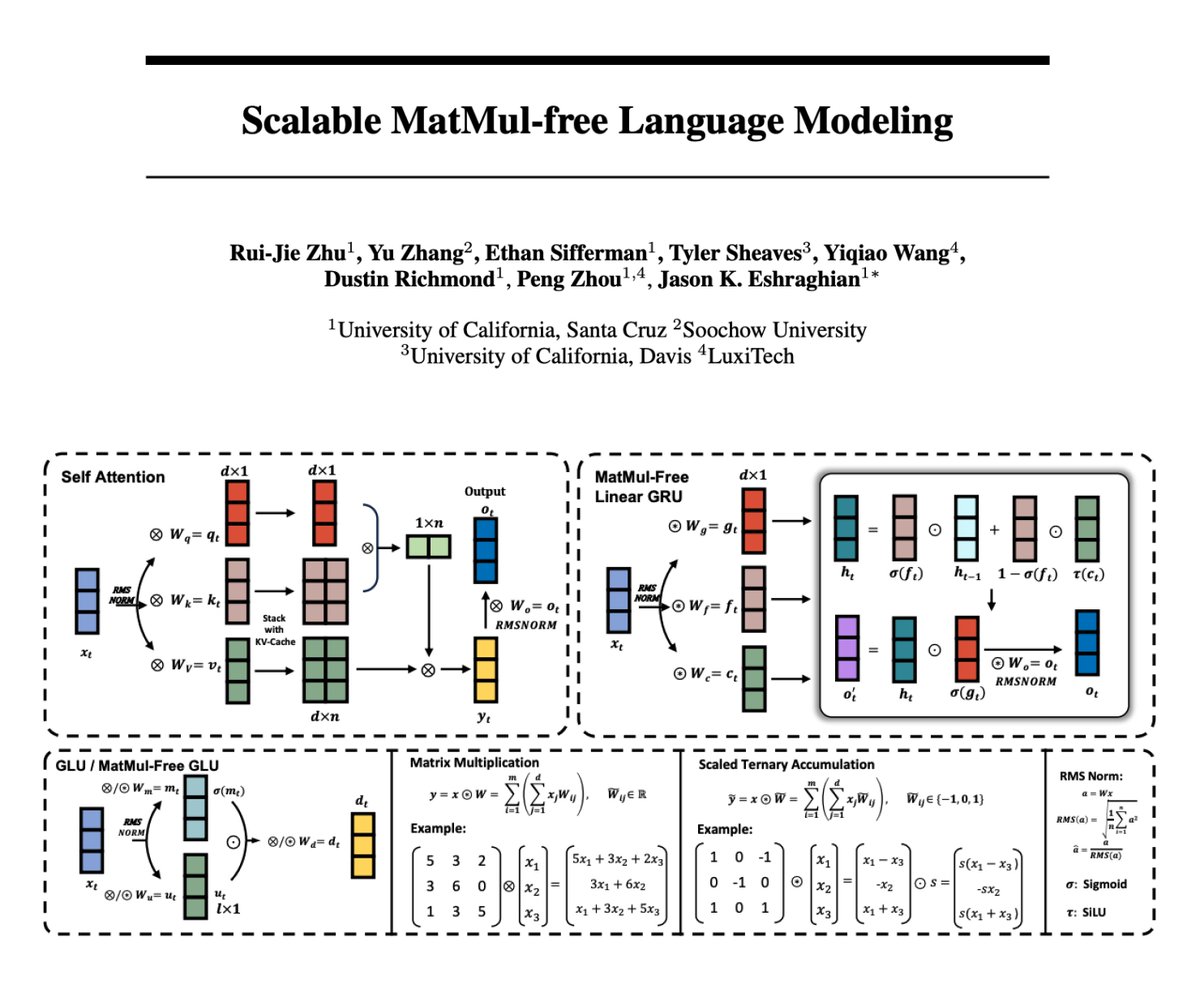
MatMul-free LLMs
Proposes an implementation that eliminates matrix multiplication operations from LLMs while maintaining performance at billion-parameter scales.
The performance between full precision Transformers and the MatMul-free models narrows as the model size increases.
Quote from the paper: "By utilizing an optimized kernel during inference, our model’s memory consumption can be reduced by more than 10× compared to unoptimized models."
There is a huge potential to use this type of approach to significantly reduce both memory usage and latency in LLMs. It's much needed especially for building agentic workflows and other types of advanced LLM applications that require better memory usage and latency.
Lots of interesting results in this paper and I am now curious what a 100B+ parameter MatMul free model or even a long-context LLM based on this approach can do. Efficiency is a huge constraint for LLMs so it's always exciting to see works that optimize core Transformer operations and overall architecture.
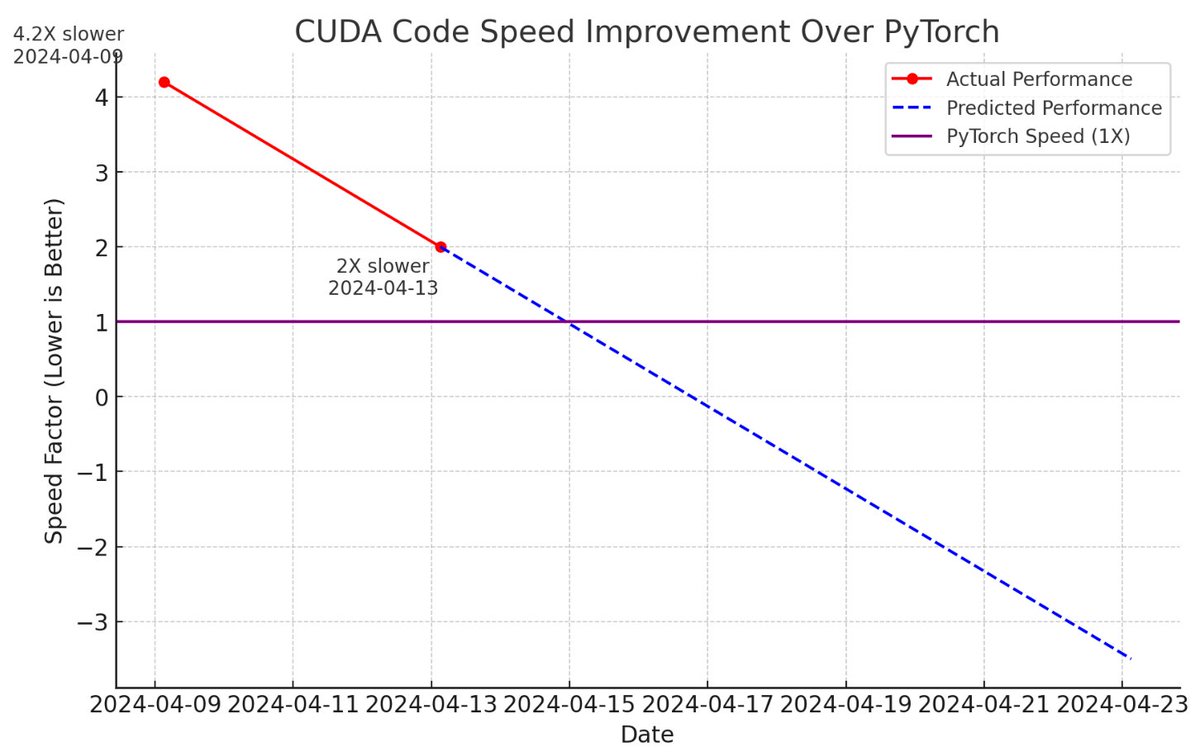
A few new CUDA hacker friends joined the effort and now llm.c is only 2X slower than PyTorch (fp32, forward pass) compared to 4 days ago, when it was at 4.2X slower 📈
The biggest improvements were:
- turn on TF32 (NVIDIA TensorFLoat-32) instead of FP32 for matmuls. This is a new mathmode in GPUs starting with Ampere+. This is a very nice, ~free optimization that sacrifices a little bit of precision for a large increase in performance, by running the matmuls on tensor cores, while chopping off the mantissa to only 10 bits (the least significant 19 bits of the float get lost). So the inputs, outputs and internal accumulates remain in fp32, but the multiplies are lower precision. Equivalent to PyTorch `torch.set_float32_matmul_precision('high')`
- call cuBLASLt API instead of cuBLAS for the sGEMM (fp32 matrix multiply), as this allows you to also fuse the bias into the matmul and deletes the need for a separate add_bias kernel, which caused a silly round trip to global memory for one addition.
- a more efficient attention kernel that uses 1) cooperative_groups reductions that look much cleaner and I only just learned about (they are not covered by the CUDA PMP book...), 2) the online softmax algorithm used in flash attention, 3) fused attention scaling factor multiply, 4) "built in" autoregressive mask bounds.
(big thanks to ademeure, ngc92, lancerts on GitHub for writing / helping with these kernels!)
Finally, ChatGPT created this amazing chart to illustrate our progress. 4 days ago we were 4.6X slower, today we are 2X slower. So we are going to beat PyTorch imminently 😂
Now (personally) going to focus on the backward pass, so we have the full training loop in CUDA.
Have you ever wanted to train LLMs in pure C without 245MB of PyTorch and 107MB of cPython? No? Well now you can! With llm.c:
https://t.co/PoGTZIwASL
To start, implements GPT-2 training on CPU/fp32 in only ~1,000 lines of clean code. It compiles and runs instantly, and exactly matches the PyTorch reference implementation.
I chose GPT-2 to start because it is the grand-daddy of LLMs, the first time the LLM stack was put together in a recognizably modern form, and with model weights available.
Genie’s model is general and not constrained to 2D. We also train a Genie on robotics data (RT-1) without actions, and demonstrate that we can learn an action controllable simulator there too. We think this is a promising step towards general world models for AGI.
Researchers from the University of Pennsylvania and Vector Institute Introduce DataDreamer: An Open-Source Python Library that Allows Researchers to Write Simple Code to Implement Powerful LLM Workflow https://t.co/YAMuf4dpLE via @Marktechpost
Is Squirting Just Pee? #science. Contrary to traditional perceptions, women indeed have a counterpart to the male prostate known as Skene's glands. Nestled around the urethra and often referred to as the female prostate, these small, duct-like structures play a role in female
Heh.. the constant battle with my AMD Instinct Mi25 flashed as a wx9100 .. Spent the night ..upgrading my OCD broken Ubuntu 22.04.3/4 amdgpu-dkms gnome-shell erroring ..etc.So 23.10 meow and it's almost .. maybe.. ready to successfully compile Koboldcpp-rocm w/o f*cking up Vulkan
OpenAI introduces a new language model. Text to video is now possible with OpenAI's Sora.
AI Prompt:
Several giant wooly mammoths approach treading through a snowy meadow, their long wooly fur lightly blows in the wind as they walk, snow covered trees and dramatic snow capped mountains in the distance, mid afternoon light with wispy clouds and a sun high in the distance creates a warm glow, the low camera view is stunning capturing the large furry mammal with beautiful photography, depth of field.
“The U.S. government, expressing concerns over the rapid developments in quantum computing, made an unprecedented move by requesting NASA and Google to shut down their quantum computer projects.“
Read this story from The Pareto Investor on Medium: https://t.co/wtT64fb3Wk