Co-Founder and Chief Scientist of @Recursive_SI, Professor of AI @AI_UCL, PI @BOLD_Lab_AI, Fellow @ELLISforEurope. Ex @GoogleDeepMind @AIatMeta @CompSciOxford
We had Minecraft legend @SethBling represent humanity on our new benchmark.
He was #1 until Astra 6.2 launched yesterday.
Introducing KradleBench: evals in live, multi-agent worlds
NEW: Britain's recent higher-than-expected growth was the result of a tech sector surge and AI adoption, according to the FT.
The UK is not quite the US, but it is benefitting from being the most tech-weighted large economy in Europe.
G7 countries growth in Q3:
🇺🇸 +0.8%
🇬🇧 +0.7%
🇨🇦 +0.3%
🇩🇪 +0.2%
🇮🇹 0.0%
🇯🇵 -0.1%
🇫🇷 -0.1%
Full piece in the FT: https://t.co/UStYlimw7F Surging British tech sector helps drive UK economy
We @bold_lab_ai are hiring a large cohort of home and overseas students for Fall 2027 entry. If you’re excited about discovering the next paradigm of open-source AI and want to work on ambitious, exploratory, but scalable ML that empowers humanity, please apply by 1st of December 2026 AOE to maximise chances of funding: https://t.co/1Ti6Y6SNx3
It was a lot of fun pointing our Eureka Machine at alien optimisers 👽👽👽, glad we could demonstrate some of the insanely wild creativity of AI there
Even more fun contributing together with some old friends at @SakanaAILabs@RobertTLange ;)
Great to see @Recursive_SI in the top 10 in talent movement. We are actively hiring: https://t.co/syowQbElPN
Join a fantastic team of ex OpenAI, Anthropic, DeepMind, and Meta members of technical staff.
Top 30 Startups and BigTech companies based purely on ~50,000 engineer job changes in the last 3 years.
If engineers leave a company to join another, it ranks higher especially if the company they come from ranks highly.
Here are the final results:
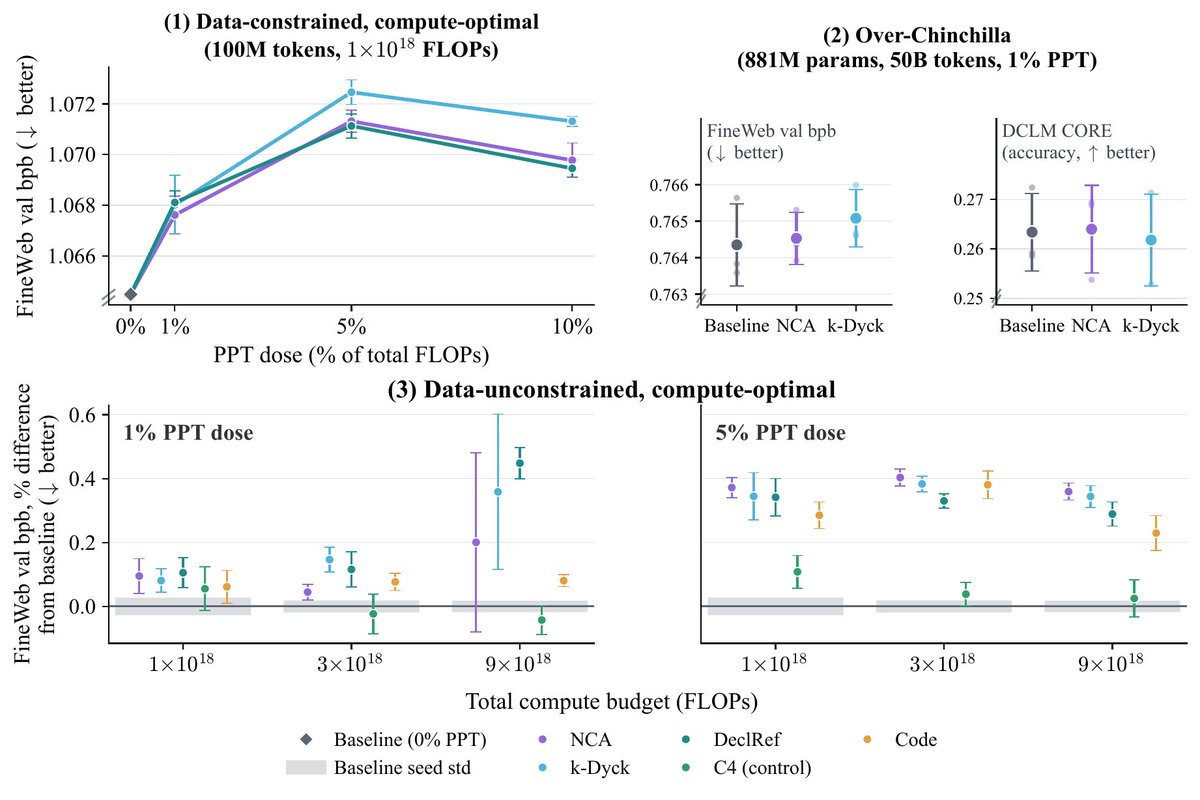
Rethinking pre-pretraining (PPT)
Allocating compute to synthetic PPT never outperforms pure natural-language training.
In our compute-matched settings: even when natural language is scarce, repeated epochs over a 100M-token corpus beat every synthetic curriculum. 🧵
Today we are happy to share one of our first open research releases: Latent Sparse Attention (LSA), a step towards subquadratic attention that matches accuracy of full attention at ultra-long context.
Sparse attention attends to only a few tokens per query, but it has to find the right ones. At 10M tokens, that search takes 98% of the attention layer's time. LSA makes sparse attention up to 22.7× faster and full attention 72.4x faster.
With @kubicek_ales@caciolai@PengLiangzu@SukritSumant@Ben_Hoov@FraserGreenlee@RMBattleday@radim_urban@thoefler@jcrwhittington
@maxencefaldor Awesome! I think it would make sense to optimize for lower brick count as well. 44k bricks sounds a bit excessive for the Colusseum :) https://t.co/TxX28lbhyI
I’ve had so much fun making bricky, and playing with it: a compiler for LEGO® models, built for AI agents.
The agent writes a Python build script. bricky places every part, reports each mistake, and renders the model.
Thanks to @omar_aflak for the idea of a LEGO® compiler.
Mindblowing chart from OBR. In 2029 real household disposable income per person expected to be just 1% higher than in 2019. What an unbelievably awful decade. It used to grow by 2%+ every year, not 1% in 10 years.