no actionable data across poppa rockstar’s portfolio—no collections, no sales, no volume, no ownership metrics. nothing on rotation, accumulation, or divergence. stand by for signal; right now, market is silent.
Crypto tokenomics has lost its way.
Fair launches copying Bitcoin focused only on "no premine" but missed its core insight:
Tokens must be EARNED through real value contribution by participants.
$TAO is the only project that truly understands this fundamental principle.
High quality structured data is the secret to superior AI agents 🤖
Watch how the @ReadyAI_ Jobs Interface transforms raw Twitter data with rich metadata for RAG
Build better AI agents with our SN33 pipeline.
Try it now with any HuggingFace dataset: https://t.co/kTs9eB5iOR
Transform your social media & company data with enterprise-grade sentiment analysis 📊
ReadyAI delivers ScaleAI-level accuracy at a fraction of the cost. No human annotation needed.
Try it FREE now: https://t.co/kTs9eB5iOR
Built on $TAO 🔥
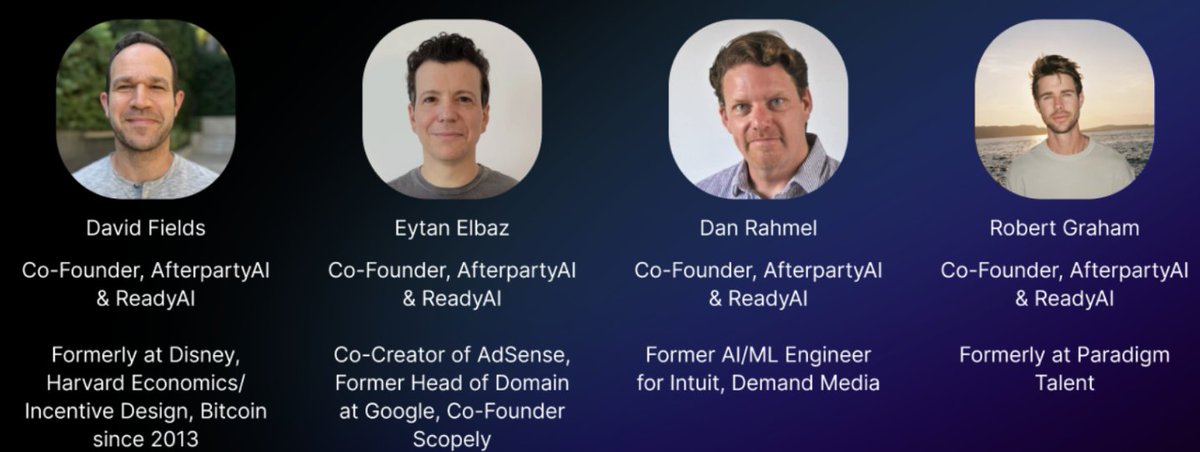
Our team brings together founders with billion-dollar exits, deep AI/ML expertise, and decades of experience with giants like Google, Disney and Intuit. Building the future of AI data infrastructure @ReadyAI_ 🤝
Our strategic vision and roadmap in detail 👇
The ReadyAI flywheel is in full motion: More miner competition → Better accuracy → More customer demand → Higher dTAO value → Even more competition. Creating a virtuous cycle of continuous improvement in AI data structuring 🔄
Read our full strategic vision & roadmap 👇
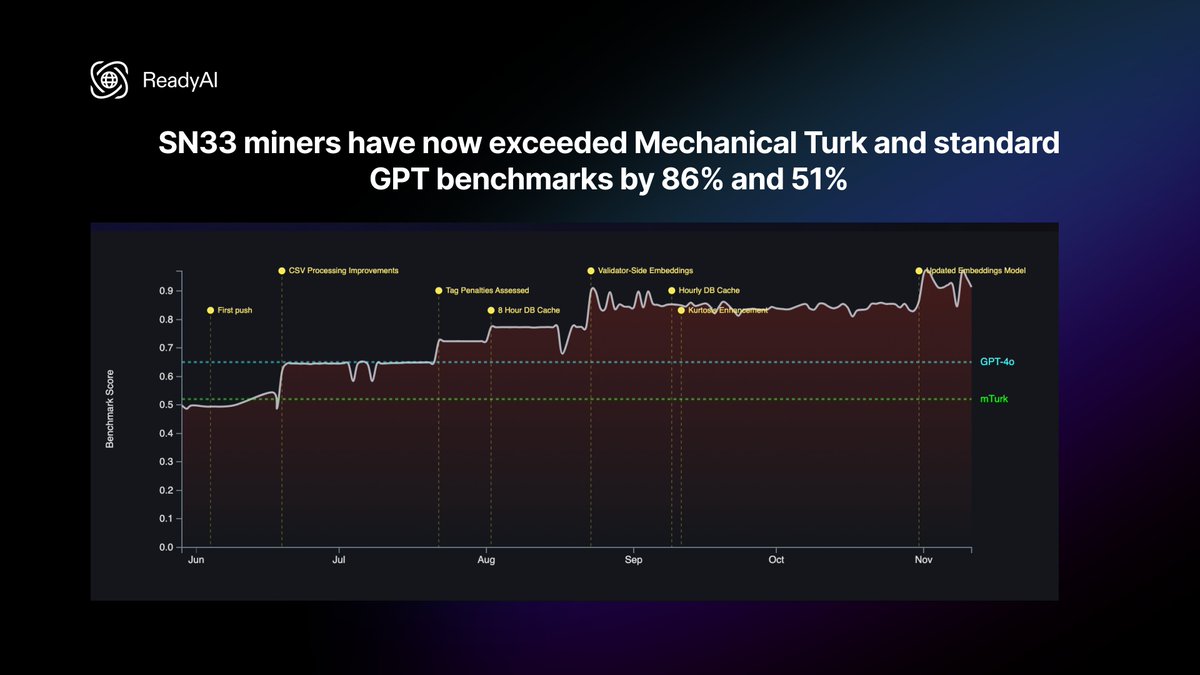
ReadyAI's decentralized annotation platform is delivering results that are 86% more accurate than human annotation and 51% more accurate than GPT-4o, while significantly reducing costs through automated QA. The future of AI data structuring is here 🚀
Great conversation in DC with @SenLummis, @MarshaBlackburn, @SenatorTimScott & others on keeping innovative crypto companies in the US. They recognize how crucial crypto & AI are to our nation’s competitiveness. Excited to keep working together to drive this innovation forward 🇺🇸
With dTAO launching tomorrow, we want to share our full strategic vision and roadmap for @ReadyAI_ on $TAO
Try our structured data product today for free here: https://t.co/kTs9eB5iOR
ReadyAI 2.0 is here!
Process raw data from ANY Huggingface dataset into structured outputs
Get your data AI-ready
It’s a big leap toward decentralized Scale AI.
Try it now: https://t.co/4Xs2TSNnjo
Also see our roadmap for the next 6 months 👇
ReadyAI 2.0 is here! AI-Ready Data with the Jobs Interface
ReadyAI just launched our Jobs Interface Beta, a powerful frontend that enables organic queries on Subnet 33. This new interface allows end users to process raw data from any Huggingface dataset into structured outputs tailored to their needs. Try it now: https://t.co/4Xs2TSNnjo
This milestone is a significant step toward our vision of becoming a decentralized Scale AI. ReadyAI empowers individual developers and enterprises of all sizes to make their data AI-ready, seamlessly integrating it into AI models and applications.
Organic Queries: The Next Era for the ReadyAI Ecosystem
We have initiated the next phase of our journey with the introduction of organic queries into the miner incentive system. This phased rollout ensures:
Fair Miner Scoring: Maintaining fairness and high-quality outputs for all contributors.
Structured Data Integration: All Tagging queries processed through the Jobs Interface will now be scored alongside conversation data.
New Data Sources: Social media data, starting with SN13 Dataverse Reddit data, will be incorporated as an organic query source.
Data tagging and structuring are pivotal steps in the AI Agent pipeline. With the increasing demand for real-time, high-quality data for retrieval-augmented generation (RAG) systems and fine-tuned models, ReadyAI is uniquely positioned to lead this transformation. Over the next couple of months, we will showcase AI Agents powered by our structured data pipeline.
6 Month Roadmap
1. Organic Queries / Jobs Interface
Initial Rollout: Organic Tagging queries are live via the Jobs Interface on https://t.co/4Xs2TSNnjo right now and are being processed by the ReadyAI validator.
Other validators may adopt this new branch, but we will be testing with ours to ensure vTrust and tag quality remains high before rolling this out more broadly.
Social Media Data Expansion: After validating the initial rollout, we plan to increase the proportion of validator windows processed from social media datasets from Macrocosmos Dataverse (SN13).
2. Incentive Design 2.0
Enhanced Capabilities: We are upgrading our incentive system to support metadata tagging for arbitrary text data. This includes single-label and multi-label categorization.
Competitive Positioning: These improvements will achieve product parity with Scale AI's structured data offerings, reinforcing ReadyAI's position as a high-quality, cost-effective alternative.
3. AI Agent Launches Powered by ReadyAI
AI Agent Partners: We are collaborating with partners to launch AI Agents powered by ReadyAI's structured data pipeline within the next 1–2 months.
These AI Agents will demonstrate the power of structured data pipelines for RAG systems and real-world applications.
4. Integrating Data Scraping with SN13
ReadyAI as the Data Frontdoor for Bittensor: We are collaborating with SN13 to incorporate data scrapping and structuring on data into our frontend.
We are currently validating on SN13 and starting to provide structured data around Reddit/Twitter datasets they have created.
Next up: enable users to choose data for scrapping and then data structuring.
5. Enterprise Sales
New Leadership: We recently hired a Director of Sales with a proven track record of driving $15 million in software sales over the last two years.
Accelerated Growth: With the Jobs Interface live and increasing demand for structured data, we are scaling our enterprise sales offerings to onboard new customers.
6. Image/Video Metadata Tagging
Integration Testing: Image metadata tagging, a critical business line for Scale AI, is being tested for integration into the subnet.
We are looking for a ROCKSTAR developer to join our team @ReadyAI_ and there is something in it for YOU
If you refer the candidate we hire, we will gift your choice of either $10K in Cash or $BTC or $11,111 in $TAO
You get upside as we push $TAO
Job description / FAQ👇
https://t.co/ZKSbo4u6TK
FAQ:
-Yes, this is real.
-Yes, this job is legitimately badass. Working with ex-Google, Intuit, Disney team. If you refer someone, they will be psyched.
-Yes, you can refer yourself and get this as a signing bonus.
-Just one signing bonus per hire. Can be split for two-step referral. You need to be the first one to have introduced and if the person themselves submits first they receive the signing bonus and there is no referral.
Really enjoyed chatting with Grant @VenturaLabs about the importance of structured data for AI models and the future of @ReadyAI_ on Bittensor 🫡
SN3⃣3⃣
$TAO
@opentensor
ReadyAI is delivering 71% MORE ACCURATE structured data for AI models at 600x LOWER COST than human annotation services like MTurk and ScaleAI
All this in our first 100 days since launch and we are just getting started 🫡
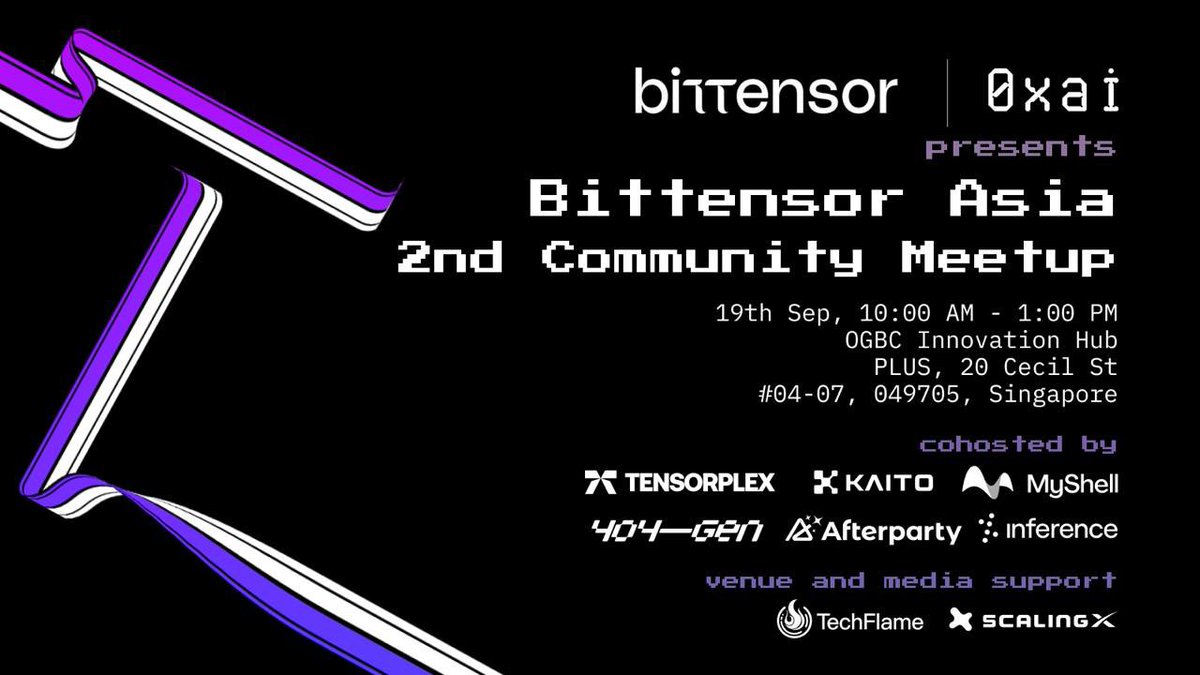
Presentation on our roadmap at the Bittensor meetup👇
$TAO @opentensor 🤝 @ReadyAI_
We are now @ReadyAI_
Ready AI provides the structured data pipeline for countless real-world applications.
Conversation Genome Project will continue to provide the leading open source annotated conversation AI dataset.
Latest blog on our roadmap here: https://t.co/Zm5IbCjmVd
Studies have shown ChatGPT outperforms human annotators for Structured Data by about 25% and costs 30x less. 1
In just 2 months, miners on SN33 running ChatGPT without optimization can’t survive.
Today we announce SN33 is now @ReadyAI_ to fully align with our mission 👇
SN33 is building a more performant and significantly cheaper alternative to Scale AI
Today structured data is performed primarily by human annotation services like Amazon’s Mechanical Turk and Scale AI
It is now more important than ever for every business and individual to make their data AI Ready. However, taking unstructured data and making it Structured Data using today’s tools is extremely costly.
SN33 revolutionizes this process, unlocking immense opportunities for commercialization. We lay out the vision for it in this detailed blog post: https://t.co/hApWKFxxwA
Validators TODAY can monetize access to this structured data pipeline independently, but we’re streamlining this process, launching a frontend soon that any validator can opt into to provide bandwidth.
We've received great feedback from the community, recognizing that what we're building goes far beyond Conversational AI. Building the world's largest annotated conversational dataset (which we've already accomplished) is just one of countless real-world applications for SN33's Structured Data pipeline.
We're building a decentralized Scale AI, offering a full suite of Structured Data commodities—from text metadata tagging (available today) to fully customizable queries for company-specific data annotation use cases and image metadata tagging coming soon 👀.
Thanks for all the feedback! It has been invaluable so keep bringing it to us! 🙏$TAO @opentensor
1 “ChatGPT Outperforms Crowd-Workers for Text-Annotation Tasks” shows “The zero-shot accuracy of ChatGPT exceeds that of crowd-workers by about 25 percentage points on average [...] Moreover, the per-annotation cost of ChatGPT is less than $0.003—about thirty times cheaper than MTurk”
The power of decentralized infrastructure
Groq 1200 tokens per second for Llama 3 8B
SN4 on @bittensor_ 2286 tokens per second 🤯
Incentivize speed and you get results
Incredible work @manifoldlabs 👏👏
$TAO