@WhosCinq@DarioAmodei It's misleading on usage. All corporates, businesses dont use open router. Open router is mostly solo devs. If not 100% chunck of corporate traffic is directly to closes models.
My friend applied to 250 tech jobs in two years. No MIT. No Stanford.
Last month Anthropic offered him $750,000.
I asked him how he broke in from zero.
He sent me the exact video that got him in. Anthropic's 2-hour course on "How to become an AI engineer in 2026".
Anthropic's team will teach you exactly how to build AI agents with skills from scratch.
I watched it last night.
Halfway through, I realized I could break into an AI lab in months, not years.
Bookmark this and read the article below.
• 00:00 - AI agent skills framework
• 25:19 - Building AI agents with MCP
• 42:05 - AI agents architecture
• 1:28:55 - How to ship with AI agents
ChatGPT has officially opened the doors to a new world.
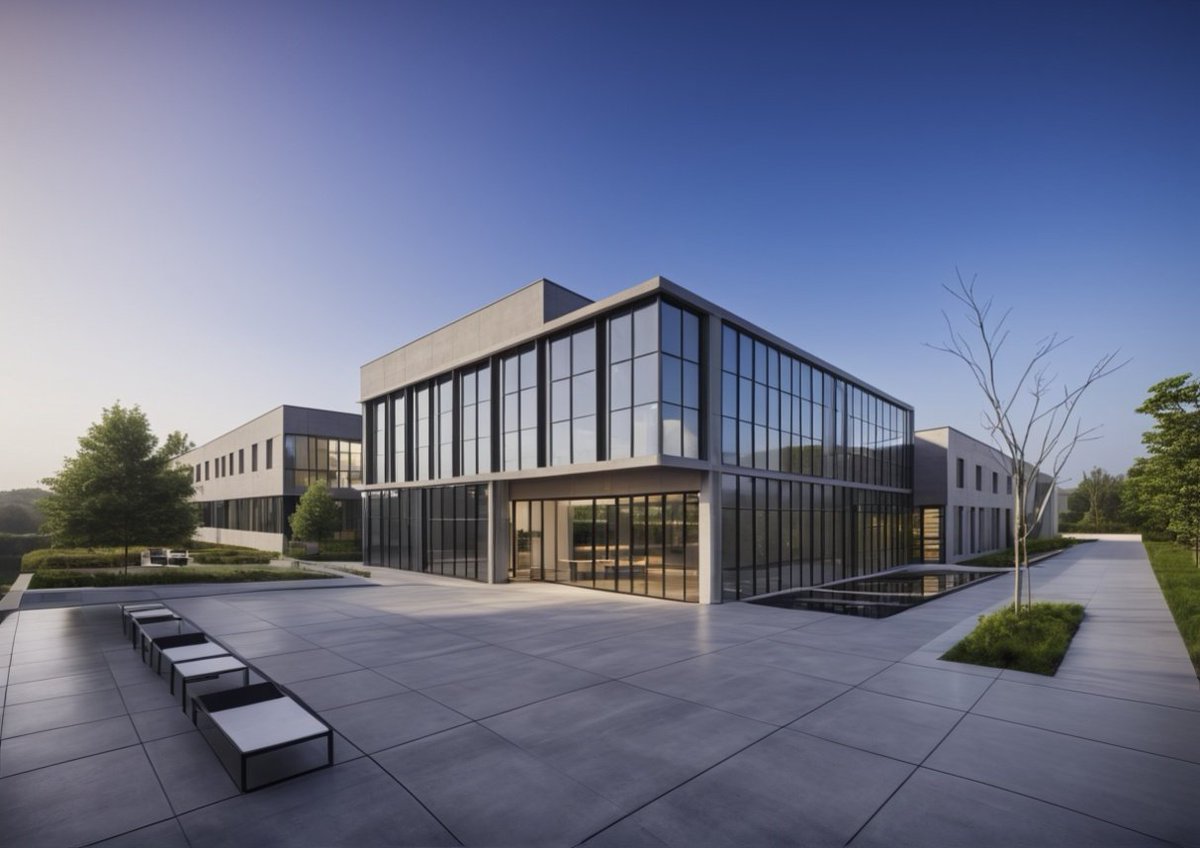
Now, even if you're not an architect, you can create incredibly realistic designs with AI.
I've shown you how:
Anthropic (Claude) has a really neat tool on their website.
It's a prompt optimizer and can turn a simple prompt into an advanced prompt template.
I've tested it and it works incredibly well.
Here's how to use it (in 3 steps):
🚨 BREAKING 🚨
NVIDIA just announced Blackwell.
The most powerful GPU in the market.
Main features:
- AI Superchip, 208B transistors
- 2nd Gen Transformer Engine: FP4/FP6 Tensor Core
- 5th Generation NVLink: Scales to 576 GPUs
- RAS Engine: 100% In-System Self-Test
- Secure AI: Full Performance Encryption
- Decompression Engine: 800GB/sec
Analysts estimate this could potentially be 10-100x faster than NVIDIA's current Hopper/A100 GPUs for very large transformer model workloads requiring multi-GPU scaling.
This represents a monumental leap in scale for accelerating the "Trillion-Parameter AI" future NVIDIA is targeting.
The tests are in!
Grok-1 is the highest quality open-source LLM released.
Grok's MMLU score of 73% and beats Llama 2 70B’s 68.9% and Mixtral 8x7B’s 70.6%.
With 314 billion parameters, xAI’s Grok-1 is significantly larger than today’s leading open-source model.
Grok-1 is a Mixture-of-Experts model that activates 25% of weights for each forward pass, giving a total of about 80 billion active parameters.
Grok-1 is a base model, not an instruct or chat model.
Grok-1 is in fine-tuning meet typical LLM use-cases.
Microsoft just integrated Copilot in OneDrive.
This integration will revolutionize the way we work.
Here's how this new feature will impact your life: ⤵️
Introducing Bland web. An AI that sounds human and can do anything. 📢
Add voice AI to your website, mobile apps, phone calls, video games, & even your apple vision pro. ⚡️
Talk to the future right now: https://t.co/V9HpsouCZb
NEWS: Elon Musk has revealed a potential Midjourney and X partnership.
Plus, major developments from Neuralink, Grok, Adobe, OpenAI, Groq, and a new AI workplace study.
Here's everything going on in AI right now:
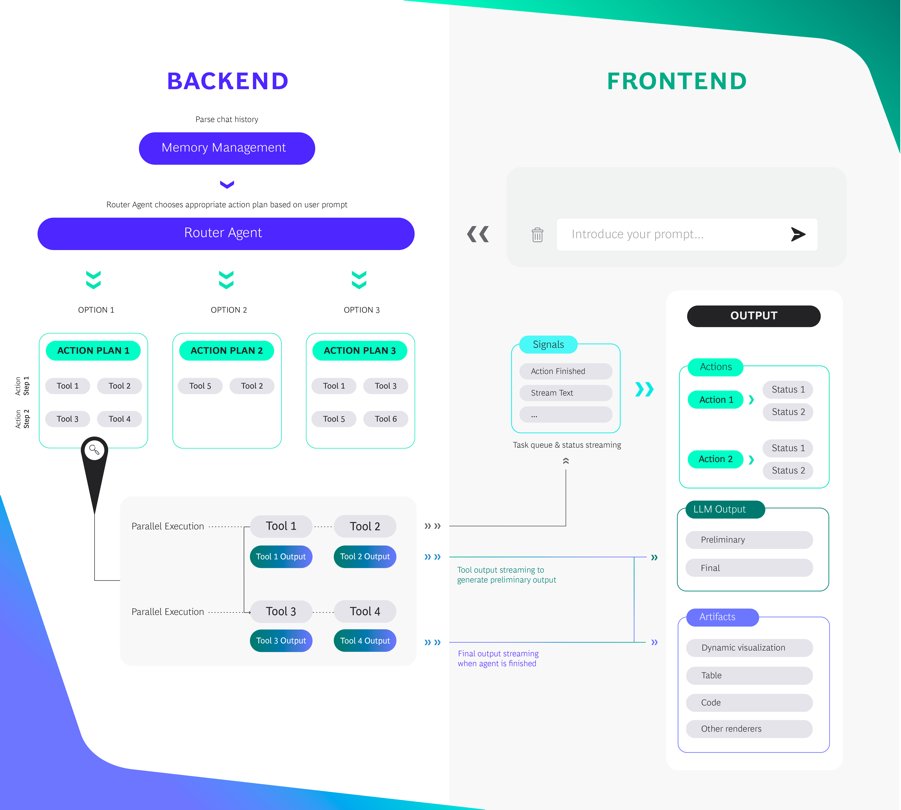
🤖BCG X Releases AgentKit, a Full-Stack Starter Kit for Building Constrained Agents
AgentKit is a LangChain-based starter kit to build constrained agents, developed by our partners at BCG X
We've often found that in order to productionalize agentic applications, you need to develop them in a fairly constrained way. This will help with that!
This is a full stack application, built on NextJS, FastAPI, and LangChain
BCG X has already used this to develop:
🧪Generating drafts of complex clinical documents, such as clinical trial protocols, for a global pharma company
🚢Controlling and orchestrating supply chain optimization systems using a helpful agent assistant
🚗Developing a chatbot that helps a major automotive player service its customers
Check out the code here: https://t.co/NsMZilpHzW
Read the full blog here: https://t.co/NwY5hdcnFe
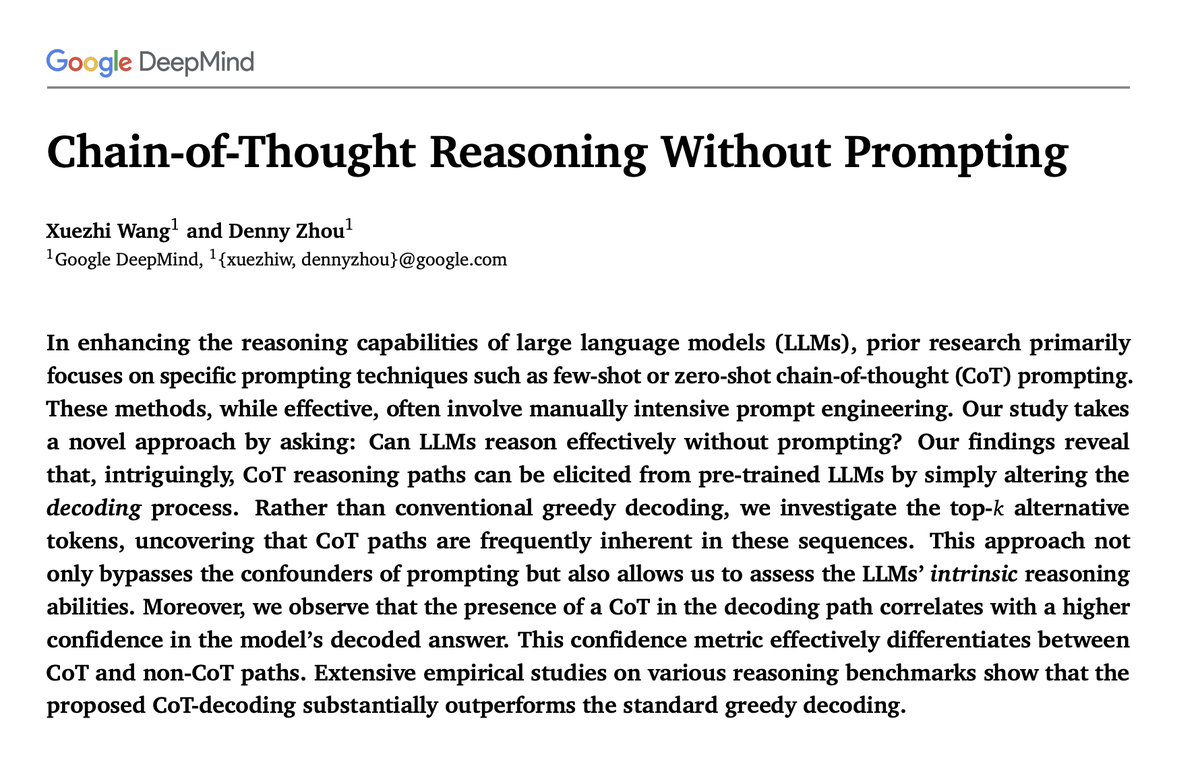
Chain-of-Thought Reasoning Without Prompting
paper page: https://t.co/o5fcJqa20L
In enhancing the reasoning capabilities of large language models (LLMs), prior research primarily focuses on specific prompting techniques such as few-shot or zero-shot chain-of-thought (CoT) prompting. These methods, while effective, often involve manually intensive prompt engineering. Our study takes a novel approach by asking: Can LLMs reason effectively without prompting? Our findings reveal that, intriguingly, CoT reasoning paths can be elicited from pre-trained LLMs by simply altering the decoding process. Rather than conventional greedy decoding, we investigate the top-k alternative tokens, uncovering that CoT paths are frequently inherent in these sequences. This approach not only bypasses the confounders of prompting but also allows us to assess the LLMs' intrinsic reasoning abilities. Moreover, we observe that the presence of a CoT in the decoding path correlates with a higher confidence in the model's decoded answer. This confidence metric effectively differentiates between CoT and non-CoT paths. Extensive empirical studies on various reasoning benchmarks show that the proposed CoT-decoding substantially outperforms the standard greedy decoding.
Bard is becoming Gemini, and we’re launching two new experiences:
1️⃣ Gemini Advanced, which gives you access to Ultra 1.0, our most capable AI model
2️⃣ A new mobile app for easier collaboration on the go
Learn more ↓
https://t.co/40maLyUXc0