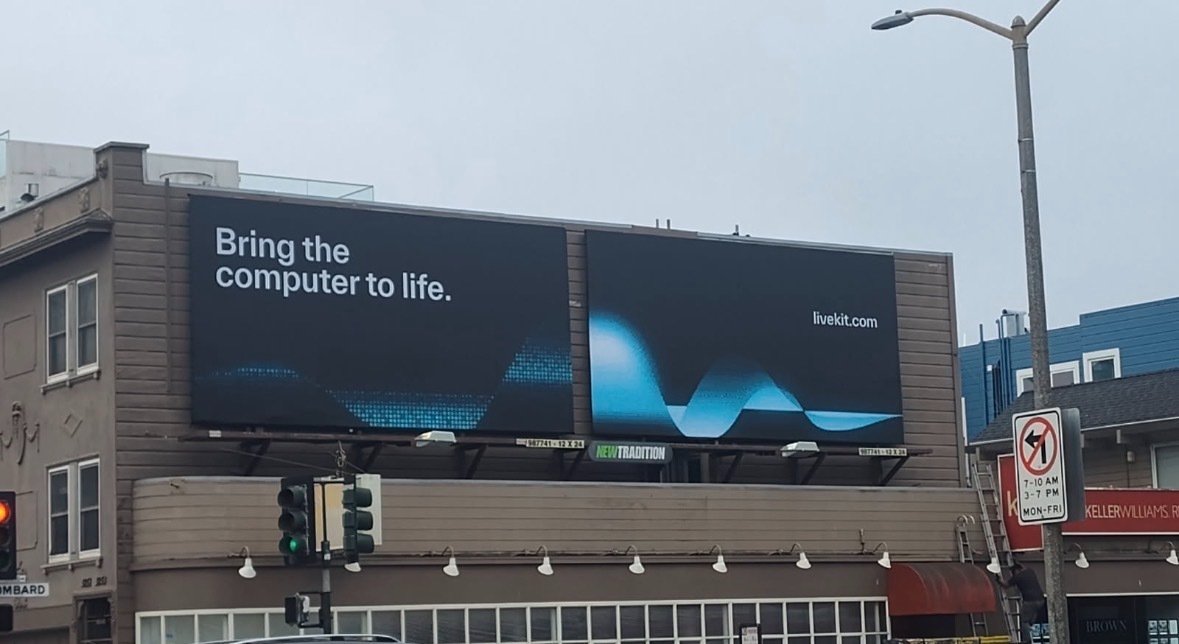
Today is a day I’ll never forget.
I grew up in Cupertino.
My dad was a tech founder in the 80s/90s.
I was in YC S07.
LiveKit is my 5th company.
The first 4 didn’t work out.
I’ve had a lot of advantages — it still took 20 years to get here.
Founders: keep taking shots.
We learn to speak before we learn to read.
Voice is the most natural interface we have.
We just raised a $100M to make building voice AI as easy as a web app.
it's crazy that dream-1 (@dreamlabs_ai) literally just works
i'm at home in vietnam, testing a robot in the @dimensionalos office in sf, for our hackathon with @makermodsai
it's quite surreal to see the thing works 13000km away
@livekit is sponsoring this hack, we provide a HITL reference repo for participants using livekit-portal, but it can also be used for distillation
i would love to see someone distill dream-1 to a smaller policy, then do RL in real life to hill climb the challenge (good way to win the hack)
another idea is policy escalation, you can detect failures and use dream-1 or another fine-tuned better policy to resolve failures
anyway, the possibilities are endless with portal's multi-participant capabilities.
Since August, Harley, the voice agent we built on @livekit, has run 10,000+ insurance onboarding calls. Average call time is down 63%, and quotes take two or three seconds on hold, not a day or two.
My first engineering post @Harper_Insure, on how we built it: https://t.co/WGD4nFozrh
$52M seed round. 15M+ users. But this is what we're most proud of yet.
Introducing Drama 3: the most emotive and controllable TTS model in the world
And yes, it's open-weight.
You can now control how even a single word should sound, change its tone, and shift your voice mid-sentence.
Uncle Roger was impressed too.
Try it here:
https://t.co/4nbz4sQ4yy
Comment “DRAMA” within the next 48 hours for 1 month free.
If you're an enterprise your first month is on us:
https://t.co/jBXXZSAg0p
Know exactly what your agent can do, catch gaps before customers do, and test any model against your own scenarios before you switch. Your agent has a QA team now.
Try LiveKit Simulations free through October: https://t.co/dx8DzqXb0s
Your whole voice stack, free for a year on LiveKit.
$10K in Cloud credits + a year of Scale + $7K in partner inference credits ($1K each: @googlegemma, @DeepgramAI, @inworld , @rimelabs , @FishAudio, @AssemblyAI, @GradiumAI.)
One workspace. No provider keys.
Apply now: https://t.co/UnWpnNyCqg
GPT-Live-1 @openaidevs is now supported in LiveKit Agents. It's full-duplex, so it listens and speaks at the same time instead of taking turns, and it hands reasoning and tool calls off to a backend model so a slow lookup doesn't leave your agent sitting in dead air.
Same `AgentSession` API. New plugin: `GPTLiveModel`.
Get started: https://t.co/igKmgICCAk
LiveKit Connectors are generally available today.
They bring calls from @twilio Programmable Voice and @WhatsApp Business Calling into a LiveKit room as a regular participant, so your agent can answer there with no SIP trunk to provision and nothing new to host.
Read the full article: https://t.co/Yvj1Crwg3r
Realtime TTS-2 is GA today, now the #1 model on Artificial Analysis and fastest TTS in the world of its class.
The research preview got far more usage than expected. That experience went back into research and today's GA model represents the biggest leap in Inworld's history.
It's now less expensive to build and run agents on LiveKit.
Agent sessions, recording, WebRTC, and SIP are billed per-second with a 10-second minimum. A 14-second outbound call costs 14 seconds, not a full minute.
No code changes. Just a smaller bill.
Read the full post: https://t.co/83rDeUnie6
Protect sensitive data without giving up voice agent observability.
LiveKit PII Redaction automatically removes personal information from transcripts and recordings before it is stored. It is included with LiveKit Agent Observability at no additional cost.
Read more: https://t.co/kqJzMsCzuO
1/ Today we're launching Expressive mode in LiveKit Agents.
Most voice agents deliver every sentence in that same, upbeat register we all know and hate (including bad news). Expressive mode makes your agent sound like it registers what the caller is actually feeling.
Here's our take on benchmarks for voice: they're hard to get right, but critical if you're building humanlike AI. Our live benchmarks page is up now: pass rate on real agent scenarios, latency including the worst-case (p99) moments, side-by-side conversation comparison between models over time. Feedback welcome! https://t.co/z32pseDRbH