DINO & friends play a big role in visual diffusion models nowadays, adding a semantic component to the generative process.
This work does the same for continuous diffusion language models, constructing coarse-grained semantic representations through clustering. It seems to help!
Bitstream language diffusion is cool, but what about bistream diffusion for everything?
Happy to share:
Multimodal Co-Generation With Continuous Bitstream Diffusion
Highly reliable and high performance training on many modalities without any modality-specific calibration!
Very proud to share the first work of my brilliant bachelor's student (!) Ella Kemperman!
2nd-order solvers offer impressive acceleration, but entropy rate alone can't find optimal discretizations.
We introduce a family of adaptive 2nd-order discretizations that do the trick!
Great new work by Georgios Batzolis @GBatz97, Carola Schönlieb @caromitreka and co-authors, on pullback geometry for data supported on mixtures of manifolds!
https://t.co/3C2EamjxdU
@Cambridge_Uni
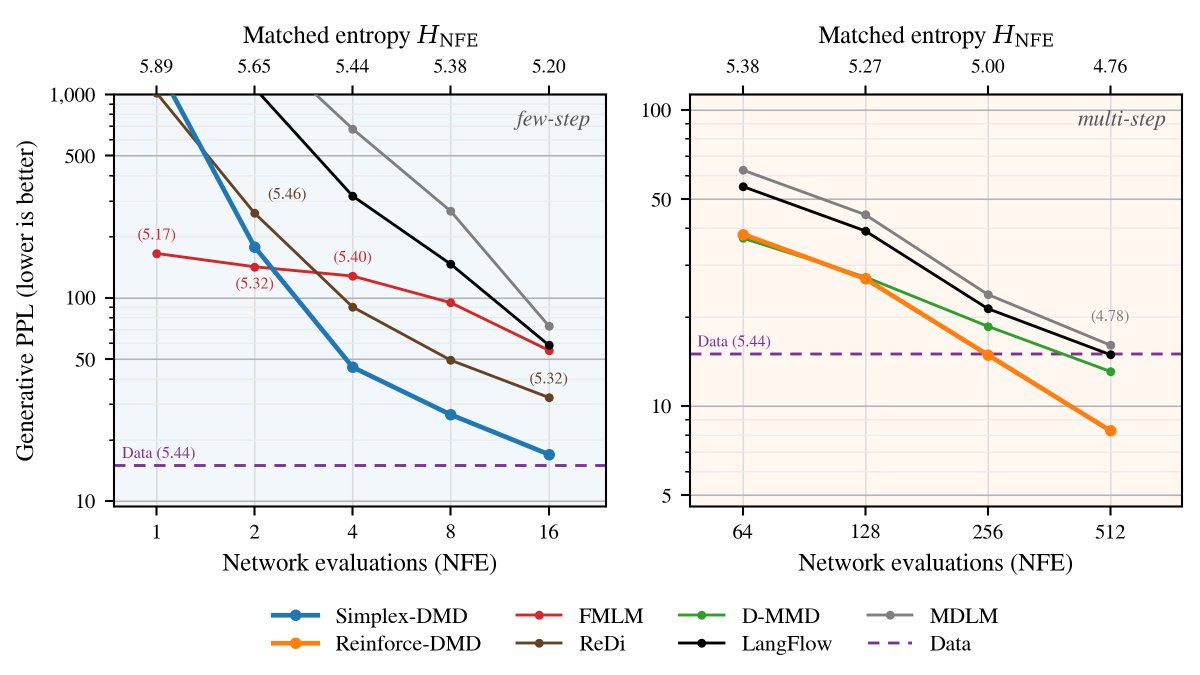
🔥 Accelerate your diffusion LMs with Distribution Matching Distillation
Introducing two methods for continuous diffusion LMs with gains at complementary sampling budgets:
🔺 Simplex-DMD at very few-step budgets
🎲 Reinforce-DMD at larger budgets
🔺 At 4 NFEs Simplex-DMD halves the strongest baseline’s generative perplexity at matched entropy
(1/n)
Very exciting work! It appears that "chunk-level" any order generation can beat the AR generation order in pass@k accuracy! That's very promising for test time scaling trends :) Also very happy to see that S-FLM also ~matches AR in pass@k 🔥
After all the AI results, something a bit more more human for you
Sharing: From Atoms to Entropy: Optimal Noise Allocation for Diffusion Training in the Convex Regime
A theory of optimal training for diffusion, with a striking result: sample noise at discrete noise levels!
Our #ICML2026 Spotlight shows that Neural Feature Geometry evolves as discrete Ricci Flow.
Poster on Wed, Jul 8, 2026, 3:30 PM – 5:15 PM HST, HALL A #1705, presented by Moritz Hehl.
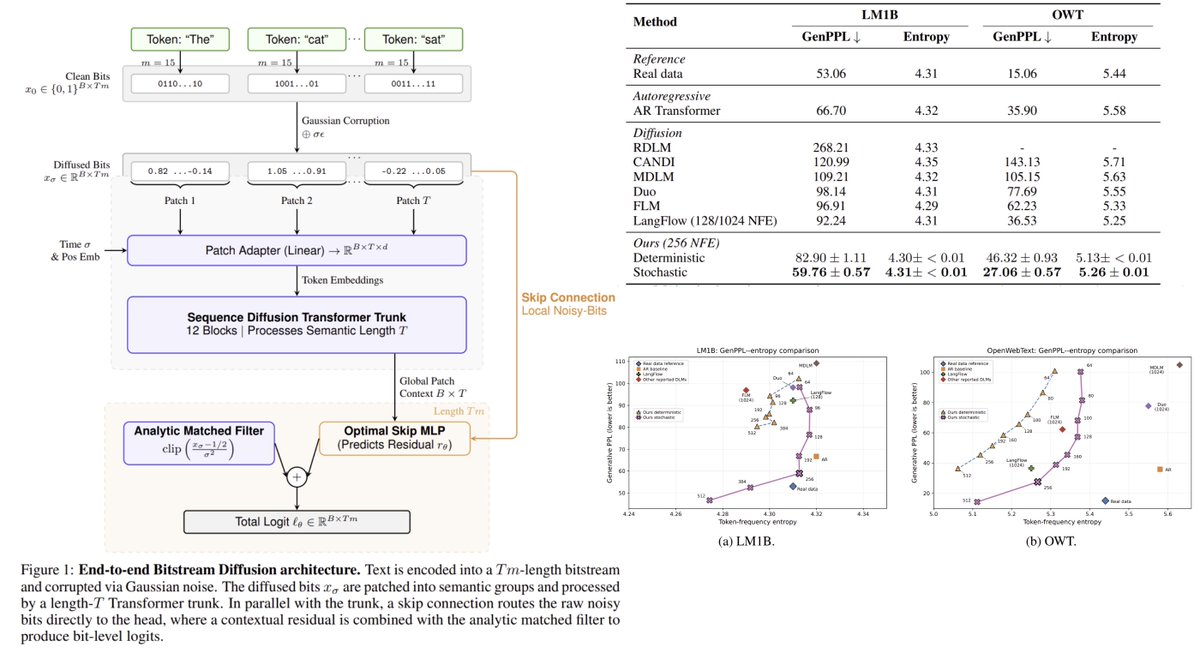
1/2) Happy to share our new results on language diffusion with BitStreams!
Continuous bitstream diffusion (CoBit, green curve) clearly outperforms discrete diffusion and continuous diffusion such as LangFlow and ELF, while nearly matching AR on Pareto fronts. Check it out!
1/?) As promised to Sander Dieleman (@sedielem), we’re finally excited to share:
Towards Closing the Autoregressive Gap in Language Modeling via Entropy-Gated Continuous Bitstream Diffusion
We show that continuous diffusion can achieve very strong language modeling performance when operating directly on bitstreams, outperforming masked and uniform diffusion baselines, and essentially matching autoregressive models under our evaluation settings.
@MingtianZhang@Singularitarian@StatMLPapers Prior estimates rely on the MLE method which is shown to underestimate the dimension, notably for higher dimensions. In Figure 4, the reconstruction error clearly shows diminishing returns beyond approx 150 dimensions, which is the greatest dimension predicted across all digits.