Deploy models in your own environment, tune inference for your workload, and see how your cluster is running—with GPUStack.
Own your inference. 👇
https://t.co/mpjRx0hVxb
#SelfHostedAI
What changes when AI goes from testing with sample data to handling real customer records and internal documents?
Where that data is processed and who can call each model become security decisions. That’s one reason to consider self-hosting. Your team can choose where inference runs and set access rules as more applications come online.
When several teams share an inference endpoint, each app may need a different set of models. With GPUStack, you can give each app its own API key and limit it to the models that app needs.
Explore GPUStack on GitHub
https://t.co/UUXf6jVKMq
#SelfHostedAI #AccessControl
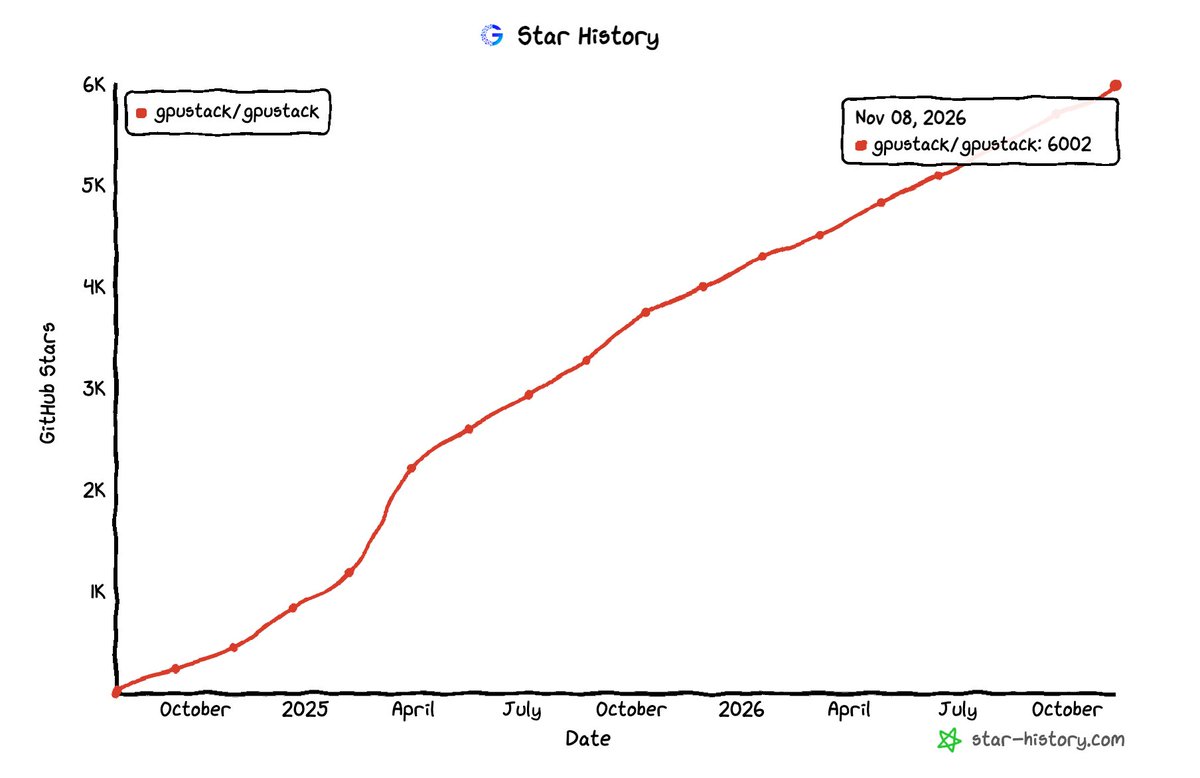
🎉 GPUStack has reached 6K GitHub Stars!
From our very first star to 6,000+, every star, contribution, issue, and piece of feedback has helped GPUStack grow.
Today, GPUStack is supported by 67 contributors, used across 120+ countries and regions, with more than 127K deployments worldwide.
A huge thank you to every developer, user, and community partner who has contributed to this journey. Together, we’re making GPU management and AI model deployment simpler and more accessible.
⭐ GitHub: https://t.co/UUXf6jVKMq
#GPUStack #OpenSource #AIInfra #GitHub #LLM #GPUManagement
Got a GPU server and a model you’ve been meaning to try? That’s a good place to start self-hosting inference.
GPUStack is an open-source platform for GPU management and model serving. Deploy it in your own environment, then connect the GPUs you need. If your setup grows, you can manage on-premises GPU servers, GPU workers in Kubernetes, and supported cloud GPU instances from the same console.
You choose where each model runs and use API keys to control which models your apps can call.
If you were setting up self-hosted inference this weekend, where would you start?
🅰️ A GPU server I already have
🅱️ The Kubernetes cluster my team already runs
🅲 A cloud GPU I can spin up on demand
Drop A, B, or C. If you already have a model in mind, tell us what you’d run first.
Explore GPUStack on GitHub:https://t.co/UUXf6jWiBY
#SelfHostedAI #LLMInference #AIInfrastructure #GPUManagement
Two ways to run LLM inference. Pick a card. 💳 Credit card → call a hosted API 🖥️ Graphics card → self-host on GPUs you own or rent
If you want to choose which models run and who can use them, GPUStack lets you deploy on GPUs you own or rent and serve models through one API.
What tipped the scales for you? Cost, convenience, or control?