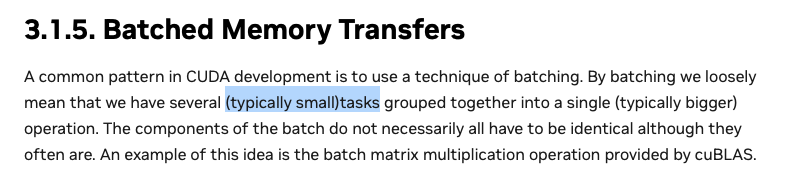
@NVIDIAAIDev anw, CUDA is super fun to learn. People should check out how they manage threads and mem, super smooth and intelligent
https://t.co/bCGPbuYstY
What does @NVIDIAAIDev use to cook this CUDA's doc? Multiple syntax and typing errors in a row? If it's AI, then seems like AI is trying to fake the error and pretend to be human (which is both scary and impressive at the same time) 😂😂😂
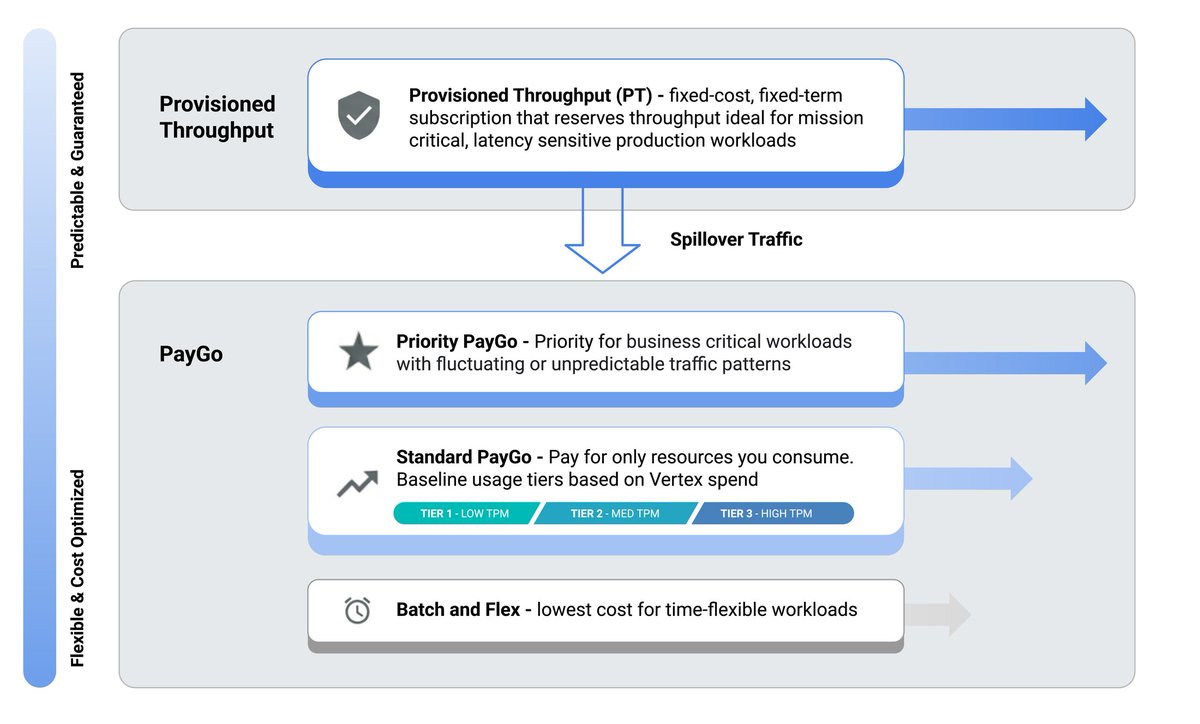
5 ways to reduce 429 errors on Vertex AI:
1. Implement smart retries
2. Leverage global model routing
3. Reduce payload via context caching
4. Optimize prompts
5. Shape traffic
More on how to build resilient LLM apps on Vertex AI and reduce 429 errors → https://t.co/DMkGIaoiiS
Mati Staniszewski and his team at @ElevenLabs have built amazing text-to-speech and speech-to-text models, and are now expanding into voice agents. In this episode of Cheeky Pint, I asked why one of the longest-promised UIs in computing ("Open the pod bay doors, HAL" was 1968!) has been so slow in arriving. Along with lots of details on how voice AI actually works at a technical level.
00:00:27 How audio models work
00:08:52 ElevenLabs business model
00:17:50 The conversational Turing Test
00:21:01 Link by Stripe
00:26:02 Cascaded vs speech-to-speech
00:31:53 Universal translation
00:51:41 Designing an AI-native org
I think storing skill.md or even knowledge text in our own database is not feasible to pull that memory back under our ownership. Since "memory" in terms of LLM is document that has been read, processed and used in the interaction with users, so that "memory" is converted into a different type (let's say different vector). The text we store in the database is like the knowledge that hasn't been used in daily interaction. Maybe fine-tunning can help, since the result of daily interaction will be baked in the output model's parameters.
Meet Gemma 4: our new family of open models you can run on your own hardware.
Built for advanced reasoning and agentic workflows, we’re releasing them under an Apache 2.0 license. Here’s what’s new 🧵
LLM Knowledge Bases
Something I'm finding very useful recently: using LLMs to build personal knowledge bases for various topics of research interest. In this way, a large fraction of my recent token throughput is going less into manipulating code, and more into manipulating knowledge (stored as markdown and images). The latest LLMs are quite good at it. So:
Data ingest:
I index source documents (articles, papers, repos, datasets, images, etc.) into a raw/ directory, then I use an LLM to incrementally "compile" a wiki, which is just a collection of .md files in a directory structure. The wiki includes summaries of all the data in raw/, backlinks, and then it categorizes data into concepts, writes articles for them, and links them all. To convert web articles into .md files I like to use the Obsidian Web Clipper extension, and then I also use a hotkey to download all the related images to local so that my LLM can easily reference them.
IDE:
I use Obsidian as the IDE "frontend" where I can view the raw data, the the compiled wiki, and the derived visualizations. Important to note that the LLM writes and maintains all of the data of the wiki, I rarely touch it directly. I've played with a few Obsidian plugins to render and view data in other ways (e.g. Marp for slides).
Q&A:
Where things get interesting is that once your wiki is big enough (e.g. mine on some recent research is ~100 articles and ~400K words), you can ask your LLM agent all kinds of complex questions against the wiki, and it will go off, research the answers, etc. I thought I had to reach for fancy RAG, but the LLM has been pretty good about auto-maintaining index files and brief summaries of all the documents and it reads all the important related data fairly easily at this ~small scale.
Output:
Instead of getting answers in text/terminal, I like to have it render markdown files for me, or slide shows (Marp format), or matplotlib images, all of which I then view again in Obsidian. You can imagine many other visual output formats depending on the query. Often, I end up "filing" the outputs back into the wiki to enhance it for further queries. So my own explorations and queries always "add up" in the knowledge base.
Linting:
I've run some LLM "health checks" over the wiki to e.g. find inconsistent data, impute missing data (with web searchers), find interesting connections for new article candidates, etc., to incrementally clean up the wiki and enhance its overall data integrity. The LLMs are quite good at suggesting further questions to ask and look into.
Extra tools:
I find myself developing additional tools to process the data, e.g. I vibe coded a small and naive search engine over the wiki, which I both use directly (in a web ui), but more often I want to hand it off to an LLM via CLI as a tool for larger queries.
Further explorations:
As the repo grows, the natural desire is to also think about synthetic data generation + finetuning to have your LLM "know" the data in its weights instead of just context windows.
TLDR: raw data from a given number of sources is collected, then compiled by an LLM into a .md wiki, then operated on by various CLIs by the LLM to do Q&A and to incrementally enhance the wiki, and all of it viewable in Obsidian. You rarely ever write or edit the wiki manually, it's the domain of the LLM. I think there is room here for an incredible new product instead of a hacky collection of scripts.
LangSmith and MCP Inspector are must-have for debugging. But speaking of connecting and kickstart, LangSmith is way easier. I remember wasting a day to solve the logger and stderr to connect to MCP Inspector 😢
Build deep agents for enterprise search with the NVIDIA AI‑Q blueprint and LangChain 🔍
Our new technical tutorial walks you through:
✅ Connecting agents to your enterprise data sources
✅ Configuring the agents with Nemotron models
✅ Monitoring and debugging performance in LangSmith
📝 https://t.co/Fo2otxpQwh