Noeri is my seventh company, @noeri_ai. Here is why I started it with @YejinChoinka
I love building tools that people use every day, like XGBoost. Lately, I keep seeing the same moment. Last week, it was my young daughter. She described what she wanted to an AI coding agent and watched it come to life. She lit up.
It's joy, and it's wonder. I call it the joy of empowerment.
But that joy stops at using AI. A handful of labs create it. Most people rent it.
We started Noeri so the craft of creating AI belongs in every hand: self-improving AI that you control. It learns continually on the job, on your problem. You create it. You own it.
Many minds, not one.
Imagine the joy of empowerment with your own self-improving AI.
Through my wonderful time at NVIDIA and Stanford, one question has kept me up at night:
Should the future of AI be monolithic or plural?
To answer this question, we’ve raised $110M to get started, backed by @MenloVentures, @MadronaVentures, @NVIDIA, @NEA, @KindredVentures,@Wing_VC, @aixventureshq, @Cisco, @Snowflake, among others.
Today, Carlos (@guestrin) and I are stoked to launch Noeri, a neolab to push the frontier of plural intelligence.
Noeri means “the plural of intelligence” or many intelligences.
The future of AI we root for is plural: a healthy ecosystem of many intelligences, in all sizes, strengths, and quirks.
Discovery, in particular, has always been plural: many curious minds, each devoted to their own question, often on roads less traveled.
Our path there is self-improving AI that:
-> learns continually on the job, closing the gap between what AI can do off the shelf and what the dynamic world demands
-> learns to use other AIs as tools and make new tools to overcome its own limitations
-> picks the right-sized model for your problem, at a fraction of the frontier cost
Then the power of intelligence, from the craftsmanship of making AI to ownership, can be in the hands of all.
@noeri_ai mission reflects who we are as the founding team. My career has been anything but linear, literally continual learning on the job. Carlos has devoted his career to building tools that empower people through AI.
We are all a bit contrarian, a bit adventurous, and above all, big believers in pluralism.
Join us to build this future together: https://t.co/oAAoe0lzEH
Noeri is my seventh company, @noeri_ai. Here is why I started it with @YejinChoinka
I love building tools that people use every day, like XGBoost. Lately, I keep seeing the same moment. Last week, it was my young daughter. She described what she wanted to an AI coding agent and watched it come to life. She lit up.
It's joy, and it's wonder. I call it the joy of empowerment.
But that joy stops at using AI. A handful of labs create it. Most people rent it.
We started Noeri so the craft of creating AI belongs in every hand: self-improving AI that you control. It learns continually on the job, on your problem. You create it. You own it.
Many minds, not one.
Imagine the joy of empowerment with your own self-improving AI.
Through my wonderful time at NVIDIA and Stanford, one question has kept me up at night:
Should the future of AI be monolithic or plural?
To answer this question, we’ve raised $110M to get started, backed by @MenloVentures, @MadronaVentures, @NVIDIA, @NEA, @KindredVentures,@Wing_VC, @aixventureshq, @Cisco, @Snowflake, among others.
Today, Carlos (@guestrin) and I are stoked to launch Noeri, a neolab to push the frontier of plural intelligence.
Noeri means “the plural of intelligence” or many intelligences.
The future of AI we root for is plural: a healthy ecosystem of many intelligences, in all sizes, strengths, and quirks.
Discovery, in particular, has always been plural: many curious minds, each devoted to their own question, often on roads less traveled.
Our path there is self-improving AI that:
-> learns continually on the job, closing the gap between what AI can do off the shelf and what the dynamic world demands
-> learns to use other AIs as tools and make new tools to overcome its own limitations
-> picks the right-sized model for your problem, at a fraction of the frontier cost
Then the power of intelligence, from the craftsmanship of making AI to ownership, can be in the hands of all.
@noeri_ai mission reflects who we are as the founding team. My career has been anything but linear, literally continual learning on the job. Carlos has devoted his career to building tools that empower people through AI.
We are all a bit contrarian, a bit adventurous, and above all, big believers in pluralism.
Join us to build this future together: https://t.co/oAAoe0lzEH
Bloomberg on why @YejinChoinka and I started Noeri.
When one provider defines intelligence, its blind spots become the world’s blind spots. We want the opposite: many intelligences, and self-improving AI that you control.
Thank you @dinabass for telling the story.
Nvidia, Menlo, Madrona and Cisco are backing Noeri, cofounded by two prominent Stanford AI scientists -- Yejin Choi and Carlos Guestrin. The company is working on self-improving AI for enterprise and science markets that can be custom and cost-efficient
https://t.co/52yGLPdulA
THE JOIN is the largest open collection of databases to train foundation models! We also show that it enables very effective pretraining and zero-shot generalization with RT-J. There is now a path to scale relational transformers!
Introducing 💥RT-J💥, a System 1 model for Data
Science: put raw data in context, predict in one forward pass⚡No feature engineering, no model training, just accurate predictions.
Excited to release models, pretraining data+code and NeurIPS paper under the Stanford Tabular and Relational (STAR) ecosystem (links in comments).
How did we build this? 👇🧵
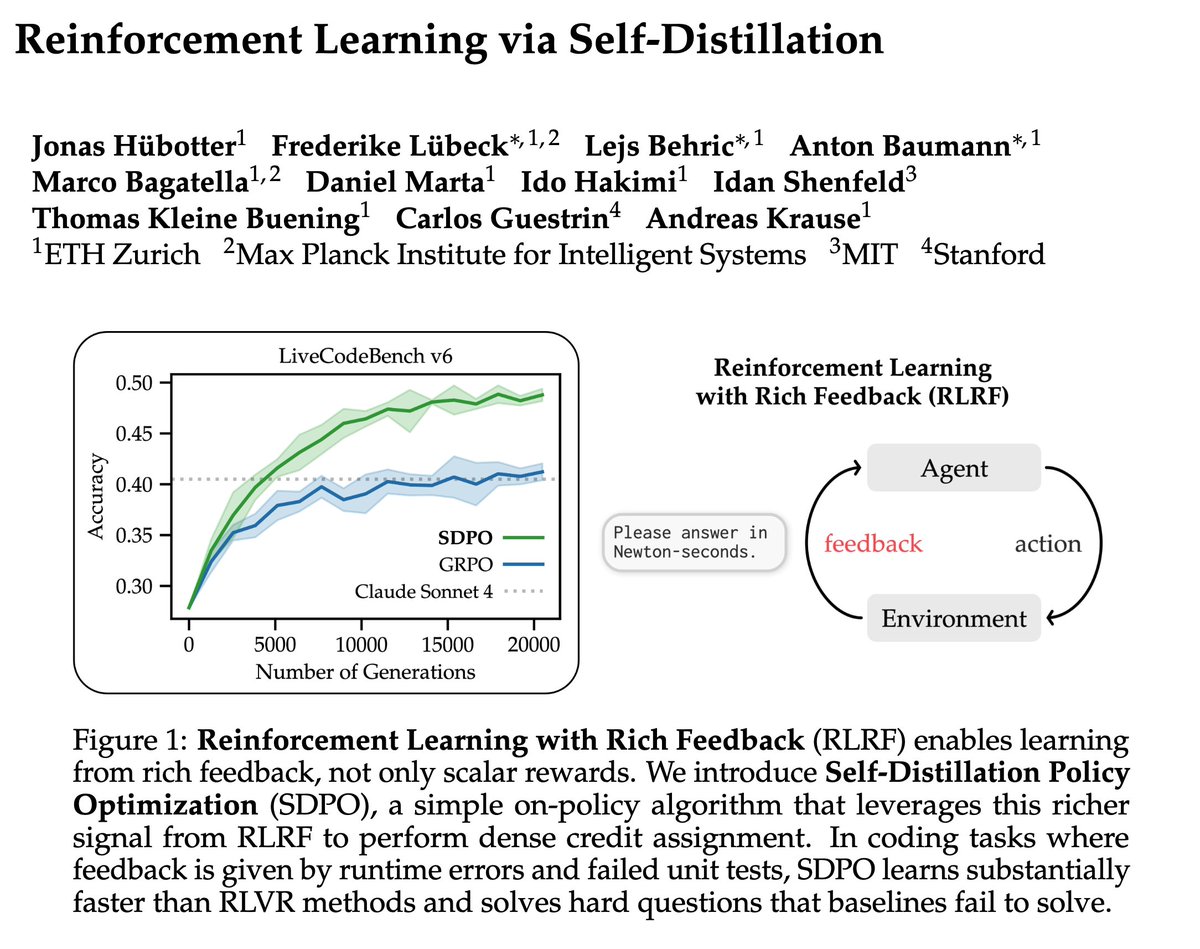
With SDPO, you can now do RL with natural language feedback, like error messages from coding environments or LLMs as judges. You can achieve huge gains over GRPO with scalar rewards!
Training LLMs with verifiable rewards uses 1bit signal per generated response. This hides why the model failed.
Today, we introduce a simple algorithm that enables the model to learn from any rich feedback!
And then turns it into dense supervision.
(1/n)
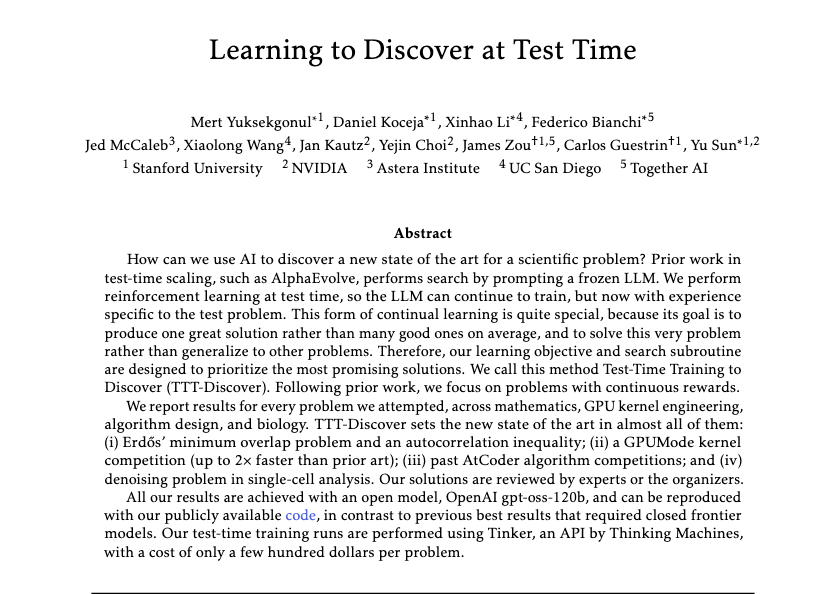
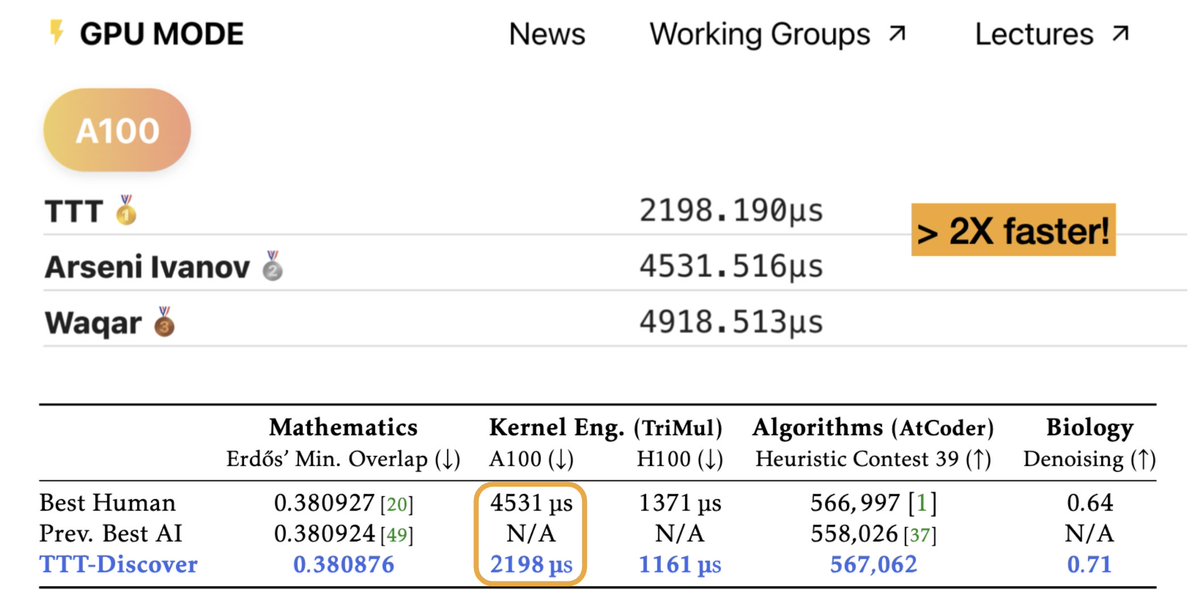
I don't think people have realized how crazy the results are from this new TTT + RL paper from Stanford/Nvidia.
Training an open source model, they
- beat Deepmind AlphaEvolve, discovered new upper bound for Erdos's minimum overlap problem
- Developed new A100 GPU kernels 2x faster than the best human kernel
- Outperformed the best AI coding attempt and human attempt on AtCoder
The idea of Test Time Training is to train a model *while* it's iteratively trying to solve a task. Combining this with RL like they do in this paper opens up the floodgates of possibilities for continual learning
Authors: @mertyuksekgonul@LeoXinhaoLee@JedMcCaleb@xiaolonw@jankautz@YejinChoinka@james_y_zou@guestrin@sun_yu_
By specializing the model to each hard task using a simple entropic objective and RL, TTT-Discover writes new high-performing GPU kernels and improves open mathematical bounds.
How to get AI to make discoveries on open scientific problems?
Most methods just improve the prompt with more attempts. But the AI itself doesn't improve.
With test-time training, AI can continue to learn on the problem it’s trying to solve: https://t.co/f32r0tUi1G
Transformers are great for sequences, but most business-critical predictions (e.g. product sales, customer churn, ad CTR, in-hospital mortality) rely on highly-structured relational data where signal is scattered across rows, columns, linked tables and time.
Excited to finally share what I have been working on over the last year: a Foundation Model architecture which brings the power of Transformers to relational domains, enabling large-scale pretraining and zero-shot generalization in enterprise settings. 🧵1/n
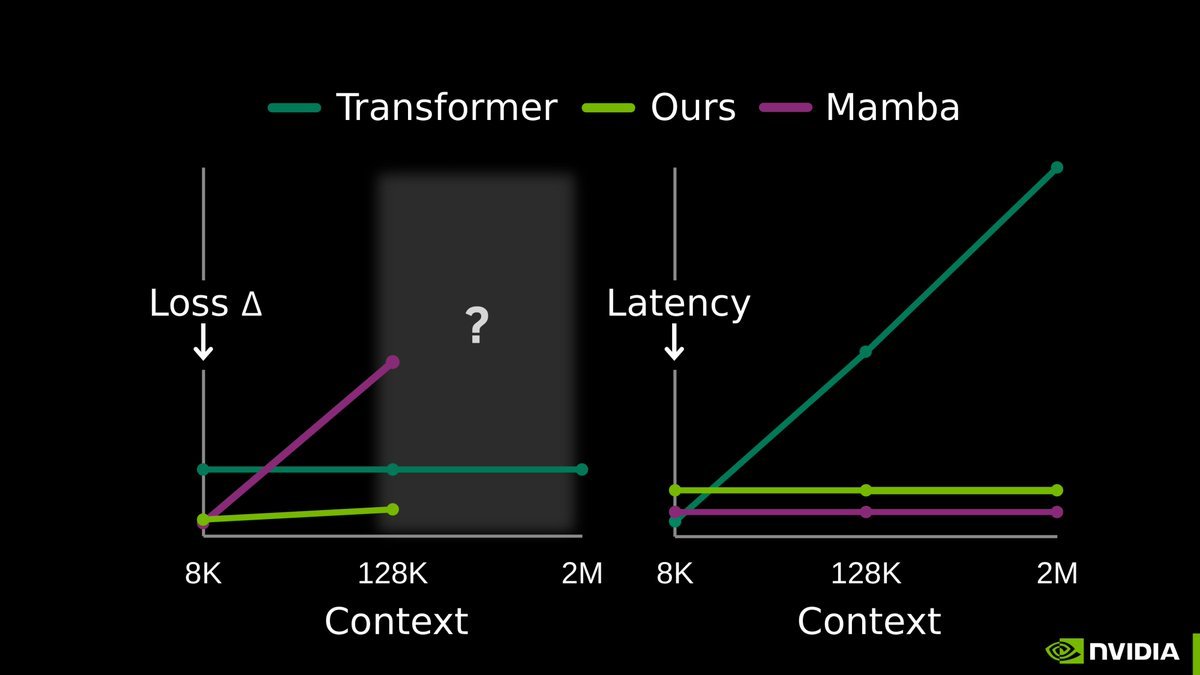
TTT-E2E compresses the context simply through end-to-end test-time training — outperforms the loss of transformers with full attention, and achieves constant-time latency per token.
LLM memory is considered one of the hardest problems in AI.
All we have today are endless hacks and workarounds. But the root solution has always been right in front of us.
Next-token prediction is already an effective compressor. We don’t need a radical new architecture. The missing piece is to continue training the model at test-time, using context as training data.
Our full release of End-to-End Test-Time Training (TTT-E2E) with @NVIDIAAI, @AsteraInstitute, and @StanfordAILab is now available.
Blog: https://t.co/woCpiIrq0T
Arxiv: https://t.co/3VkFlS3wx3
This has been over a year in the making with @arnuvtandon and an incredible team.
Transformers are great for sequences, but most business-critical predictions (e.g. product sales, customer churn, ad CTR, in-hospital mortality) rely on highly-structured relational data where signal is scattered across rows, columns, linked tables and time.
Excited to finally share what I have been working on over the last year: a Foundation Model architecture which brings the power of Transformers to relational domains, enabling large-scale pretraining and zero-shot generalization in enterprise settings. 🧵1/n
SAIL is still accepting applications for the SAIL Postdoctoral Fellowships! This is an opportunity to work with our wonderful professors and community. Applications received by the end of April 30 will receive full consideration: https://t.co/3fJEqwlkO8
The SAIL Postdoctoral Fellowship is a fantastic opportunity for recent PhDs to do their most innovative and impactful AI research, while being part of a highly collaborative and welcoming environment at Stanford.
Stanford AI Lab (SAIL) is excited to announce new SAIL Postdoctoral Fellowships! We are looking for outstanding candidates excited to advance the frontiers of AI with our professors and vibrant community. Applications received by the end of April 30 will receive full consideration: https://t.co/YXXggAwW4p
We are super excited to empower developers to focus on their goal of building innovative AI applications; we’ll take care of safety and security! What an awesome ride with Bo Li @uiuc_aisecure, @sanmikoyejo, @dawnsongtweets and the whole @VirtueAI_co team!
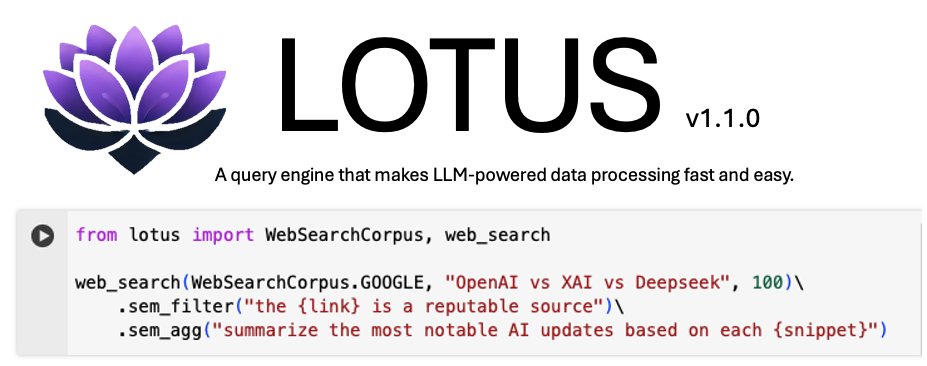
Excited to share our release of LOTUS 1.1.0, which now makes it easier than ever to get started with LLM-powered data processing over a variety of custom knowledge sources.
Seamlessly connect to data from the web, your SQL databases, vector databases and more.
And process it all with the power of semantic operators.
https://t.co/VWp0Y1VsyT
SAIL is delighted to announce Carlos @guestrin, the Fortinet Founders Professor of Computer Science, as the next Director of @StanfordAILab. Carlos is a talented researcher and leader, known for his work on explainability, graphs, compilation, and boosted trees in AI.
We've been building LOTUS at Stanford and Berkeley to make LLM-powered data processing fast, easy and declarative.
LOTUS is an open-source query engine that makes programming as easy as writing Pandas and optimizes your programs for up to 400x speedups.
To celebrate the holidays, we're excited to share our release of LOTUS 1.0.0 with a batch of new updates that make reasoning over your data faster, easier and better than ever!
Code: https://t.co/qQVJ6Vg6fi
🧵👇