Introducing 💥RT-J💥, a System 1 model for Data
Science: put raw data in context, predict in one forward pass⚡No feature engineering, no model training, just accurate predictions.
Excited to release models, pretraining data+code and NeurIPS paper under the Stanford Tabular and Relational (STAR) ecosystem (links in comments).
How did we build this? 👇🧵
Congrats to Anthropic. What they've built has caused probably the biggest inflection point in human history. With great power comes great responsibility! We’re rooting for you to use it to uplift humanity. Steer us clear of dystopia, especially the kind that passes for utopia!
Introducing Second, and a $10M seed led by @a16z.
Second builds a model of you that you own, and your agents can use as an API.
Truly personal software needs a deep understanding of you: not just your emails and messages, but how you work, what motivates you, your people, priorities, style, goals, and intent.
This requires a new kind of personal AI infrastructure. One that continuously aggregates your context, distills it into durable understanding with a ton of compute, and then serves it securely, ubiquitously, and up-to-the-minute. One that builds your *portable user model*.
Second is that infrastructure. It installs seamlessly on your Mac, and your context just comes out. Live APIs of your priorities, to-dos, wikis, writing samples, preferences. Or what you did minutes ago. Or context packs of anything, dynamically assembled in seconds.
Second is streaming-state from local to a private cloud, which means anything you connect to--whether Claude, Dot, Muse, Grok Bot, Instinct, or iMessage--shares the same, growing, continuous understanding of you.
Your portable user model is as powerful as it is sensitive. We founded @FirstPersonLabs on the principle that it should belong to you. This commitment means taking on hard systems and security problems and making sovereignty an invariant of Second from the beginning.
We've barely scratched the surface of what portable user models can unlock. Deep understanding of us, served at machine speeds, could drive the next leap in personal software, human-computer interaction, large-scale coordination of humans and agents, and more!
We're tremendously grateful to be supported by @a16z (@martin_casado, @YODELAGARZA), Mozilla Ventures, @JeffDean, Ram Shriram, Jeetu Patel (@jpatel41), @percyliang, J. Alex Halderman (@jhalderm), @sanmikoyejo, and many others.
Our vision is for a future where every person is more powerful, because they have the ultimate affordance: personal computers that fully understands them on their own terms.
If this excites you, we're hiring and come build with us!
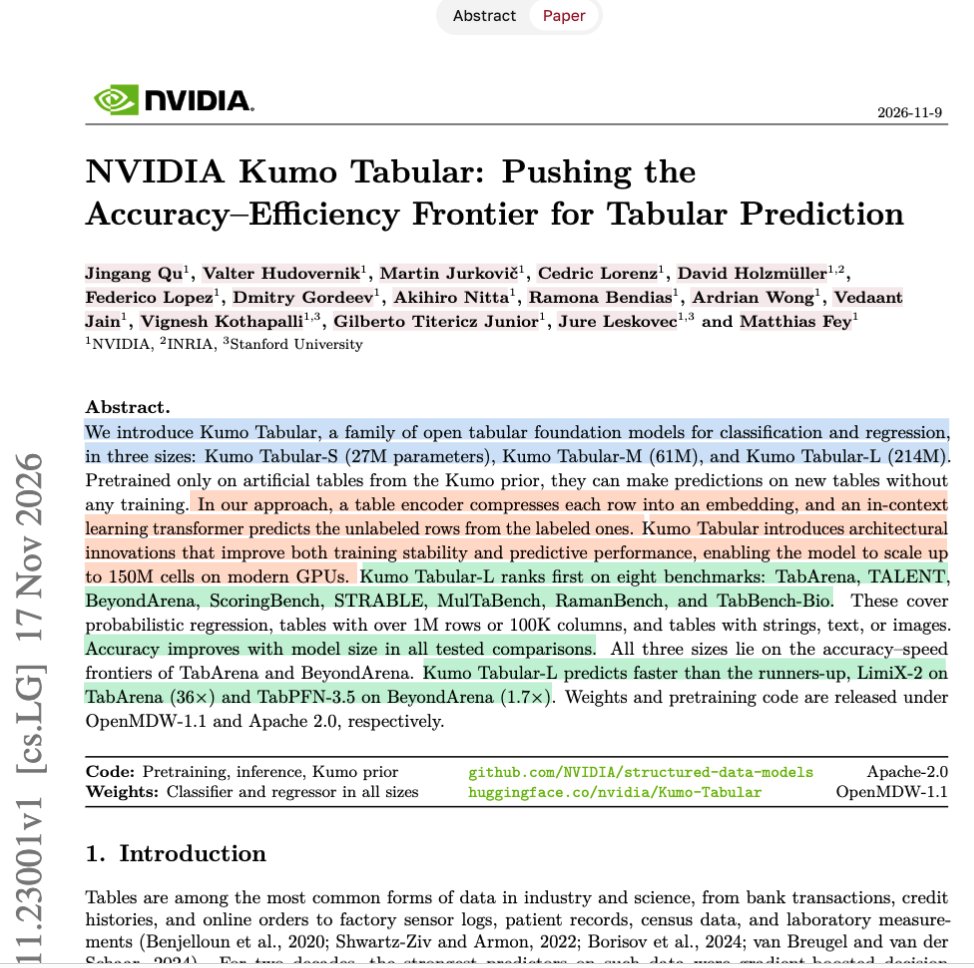
The @nvidia Kumo Tabular technical report is finally out, and I think it was well worth the wait.
The team has open-sourced both the synthetic data prior, which generates the training table and the pretraining recipe. This gives researchers something to build on, and I also like what it offers people learning about tabular foundation models.
You can see how the training tables are generated, follow how the model is trained, and download a pretrained checkpoint to try on your own data.
There is also a detailed ablation study alongside details on the evaluations and checkpoints which shows two major contributors to the improvement:
• larger-scale pretraining and
• changes to the model architecture.
If you’re interested in tabular foundation models, I’d recommend taking the time to read the paper yourself instead of just getting an AI summary. You’ll learn a lot.
TabPFN-4 has finished training. Our new tabular foundation model marks a step change in predictive intelligence. Equipped with a novel sub-quadratic architecture, it can easily scale to 10 million rows. Performance-wise, TabPFN-4 sets new standards across the board, with especially strong results where it matters most: on messy, real-world data.
Stay tuned!
Read our research preview now: https://t.co/49AZ1z2s5N
The paper and pretraining code for @Nvidia Kumo Tabular are out!
This includes optimized pretraining, many updates to the prior including a distributional numerical converter, and an ablation study! The largest gains come from scaling and interleaved row-colum attention.
Today we share the NVIDIA Kumo Tabular technical report as well as the training recipe! 🚀
Trained entirely on synthetic tables, Kumo Tabular-L leads 8 benchmark suites. All 3 model sizes achieve Pareto-optimal accuracy vs. inference time.
Arxiv: https://t.co/zvT4COnRLl
HuggingFace: https://t.co/9j9LM0z6jB
GitHub: https://t.co/D8MkunxT7v
There’s a lot of interesting work happening around tabular foundation models, especially when the data lives in more than one table. One example is STAR (Stanford Tabular and Relational Project) where they are building models, datasets, and benchmarks for working with linked tables.
One of their recent releases is RT-J, a relational foundation model which learns patterns across linked tables and uses them to make predictions on databases it hasn’t seen before. On numeric forecasting tasks in RelBench, RT-J matches strong feature engineering pipelines with about 10× fewer labeled examples on average.
What I find fascinating, apart from the strong results, is that the team also released the dataset behind RT-J called THE JOIN which is the largest open collection of real databases. It gives researchers access to 600+ DBs with around 4,000 tables and 6,000+ forecasting tasks. 👏
There’s a lot of interesting work happening around tabular foundation models, especially when the data lives in more than one table. One example is STAR (Stanford Tabular and Relational Project) where they are building models, datasets, and benchmarks for working with linked tables.
One of their recent releases is RT-J, a relational foundation model which learns patterns across linked tables and uses them to make predictions on databases it hasn’t seen before. On numeric forecasting tasks in RelBench, RT-J matches strong feature engineering pipelines with about 10× fewer labeled examples on average.
What I find fascinating, apart from the strong results, is that the team also released the dataset behind RT-J called THE JOIN which is the largest open collection of real databases. It gives researchers access to 600+ DBs with around 4,000 tables and 6,000+ forecasting tasks. 👏
There’s a lot of interesting work happening around tabular foundation models, especially when the data lives in more than one table. One example is STAR (Stanford Tabular and Relational Project) where they are building models, datasets, and benchmarks for working with linked tables.
One of their recent releases is RT-J, a relational foundation model which learns patterns across linked tables and uses them to make predictions on databases it hasn’t seen before. On numeric forecasting tasks in RelBench, RT-J matches strong feature engineering pipelines with about 10× fewer labeled examples on average.
What I find fascinating, apart from the strong results, is that the team also released the dataset behind RT-J called THE JOIN which is the largest open collection of real databases. It gives researchers access to 600+ DBs with around 4,000 tables and 6,000+ forecasting tasks. 👏
Bloomberg on why @YejinChoinka and I started Noeri.
When one provider defines intelligence, its blind spots become the world’s blind spots. We want the opposite: many intelligences, and self-improving AI that you control.
Thank you @dinabass for telling the story.
I'm hiring a Research Scientist at @StanfordAILab !
Lead research, write and manage grants, teach, and mentor PhD students in my lab. A real growth opportunity, working directly with me.
3-year role, in person, $125K–$225K base.
Apply: https://t.co/s2kvSY7yxu
Noeri is my seventh company, @noeri_ai. Here is why I started it with @YejinChoinka
I love building tools that people use every day, like XGBoost. Lately, I keep seeing the same moment. Last week, it was my young daughter. She described what she wanted to an AI coding agent and watched it come to life. She lit up.
It's joy, and it's wonder. I call it the joy of empowerment.
But that joy stops at using AI. A handful of labs create it. Most people rent it.
We started Noeri so the craft of creating AI belongs in every hand: self-improving AI that you control. It learns continually on the job, on your problem. You create it. You own it.
Many minds, not one.
Imagine the joy of empowerment with your own self-improving AI.
I have a major result to share.
I’ve found conclusive forensic evidence that the top 4 Chinese AI labs—DeepSeek, Moonshot, MiniMax and Ant Group—have built their newest models on NVIDIA’s most advanced Blackwell chips, which are barred from export to China.
This sounds insane, but I discovered that almost every AI model carries a hidden signature of the GPU that trained it. When a model is first set up, the starting values of its weights are laid out in a pattern that depends on the exact GPU. Each combination of GPU and seed number produces a unique pattern—a sort of fingerprint of the hardware used to create the model. Traces of that pattern survive training into the published model.
Again, this evidence isn’t based on any insider information or leaking. It’s based on a forensic analysis of the model weights released by the companies themselves.
I searched more than six trillion combinations of chip layout and seed number and matched them to open-weights models. In doing so, I found conclusive evidence that six Chinese AI models—including DeepSeek-V4-Pro, Kimi K3, and MiniMax-M3—were initialized on NVIDIA Blackwell systems. Four of the models match Grace Blackwell, the GB200 and GB300 parts in NVIDIA’s flagship liquid-cooled rack-scale systems.
I then verified these results on real hardware. Running unmodified PyTorch with the seeds I’d recovered, a Blackwell B300 reproduced DeepSeek-V4-Flash’s untouched starting weights bit for bit, and a rented GB200 reproduced Kimi K3’s to a correlation of 0.999995. A Hopper H100 reproduced none of DeepSeek-V4-Flash’s, and changing the seed by one broke the match. (DeepSeek’s seed is 953049583 by the way.) The method also was verified to match 24 known open-weights models to the hardware that developers said they used.
It is exceedingly unlikely that these results are a coincidence. Across six trillion combinations, the best accidental match should reach only about 8 sigma (i.e., eight standard deviations above what random chance would produce). The real matches range from 49 to 1,385 sigma, and even the weakest single test hits 20.
These were data-center-scale training runs. With some analysis of release schedules and model details, I estimate that the largest, Kimi K3 and DeepSeek-V4-Pro, used 2,000 to 3,000 Blackwell GPUs each. Clusters of this size cost on the order of $150 to $200 million each to buy, and across these labs alone would add up to more than half a billion dollars of export-controlled GPUs, not counting experimental compute or otherwise. It’s quite likely that we see multi-billion dollar expenditure on export-controlled GPUs.
I am highly confident in this result, and it has been independently verified by senior researchers at OpenAI and Anthropic. You can read the full report at https://t.co/YOtzND0Jqk.
There is much more I’ve identified about these models through other forms of checkpoint forensics like this, and will have more to share soon.
1/5 🏆 TimeH2O ranks #1 on EnergyBench, a live benchmark for day-ahead energy forecasting!
TimeH2O currently leads the Elo leaderboard, ahead of competing models including TimesFM, Chronos, and Timestral.
🔗 https://t.co/46DfpgyHXx
So cool to see relational foundation models (RFMs) get attention from Kaggle grandmasters! Expect them to fully revolutionize data science 🚀
Also check out our very own RFM, RT-J: https://t.co/oKezA8Nkwu
Relational databases are a lingua franca for business data as most enterprise data is stored across multiple tables. However, many models for structured data expect one flat table.
Yes, we can join tables and create summaries, but that results in the loss of some fine-grained information.
This is where relational foundation models come in. They work directly with related tables and preserve their structure. Because they are already pre-trained, we can use them without training a new model on our own data. @NVIDIA's Kumo Relational and Prior Labs’ TabPFN-Rel are some examples of such models.
To see how this works, let’s look at Kumo Relational. Like other tabular foundation models, it uses in-context learning i.e it makes predictions from examples we show it at prediction time, without being trained on our data.
It mainly works in three stages:
• Intra-table row embeddings wherein each table is converted into embeddings, one for every row, and the known outcomes of the context rows are added here.
• Inter-table message passing where rows linked across tables exchange embeddings over several rounds, so each row learns from the rows connected to it.
• finally, In-context learning
I’ve put together a small Kaggle notebook that runs Kumo Relational with NVIDIA’s Structured Data Models library — https://t.co/m1NSwtHoIt
Spent spme time going deeper into the @NVIDIA's Kumo family of models over the last week.
If you’ve been following the recent developments in tabular foundation models (TFMs), you’ve probably come across Kumo Tabular by now.
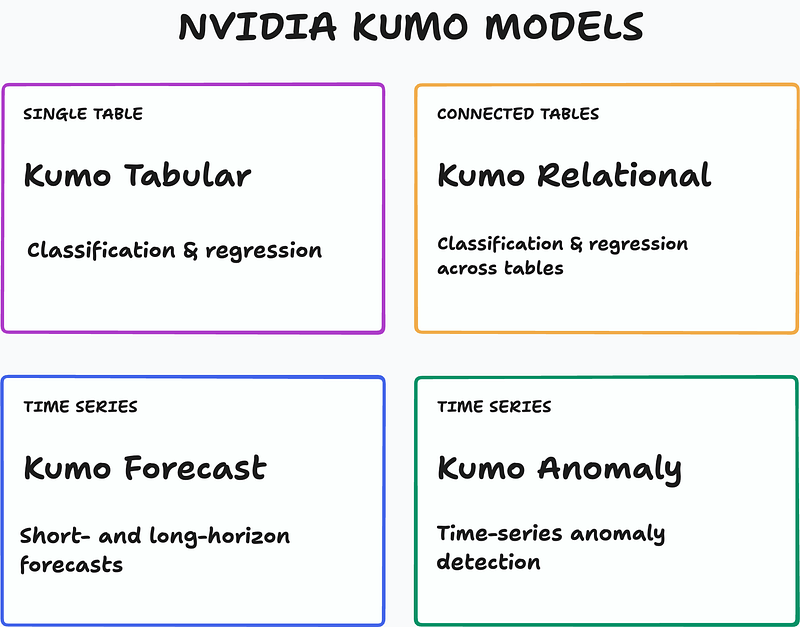
But did you know it’s just one of four models in the Kumo family where each model is designed to adress a different kind of structured data problem, which is pretty interesting.
• Kumo Tabular for classification and regression on a single table.
• Kumo Relational for classification and regression across connected tables.
• Kumo Forecast for predicting future values in time-series data.
• Kumo Anomaly for detecting unusual patterns in time-series data.
Over the coming weeks, I’ll explore each of these models in more detail, including how they work, where they fit with code.
🦍 Memorilla treats memory as a modality for LLMs. Memorilla turns everything a frozen LLM needs to remember into just 16 memory tokens. It uses up orders of magnitude fewer tokens while being faster and more accurate than full context inference. 🎯 Pushes the Pareto frontier over RAG and agentic memory in personalization, long-document and knowledge QA.
It was a monumental effort to rethink memory from scratch and go from the retrieval and agentic memory approaches to latent memory.
The potential is immense and we are excited to see new ideas popping out.
Website: https://t.co/2kC0cG7gvz
Github: https://t.co/m8MDO2bq8q