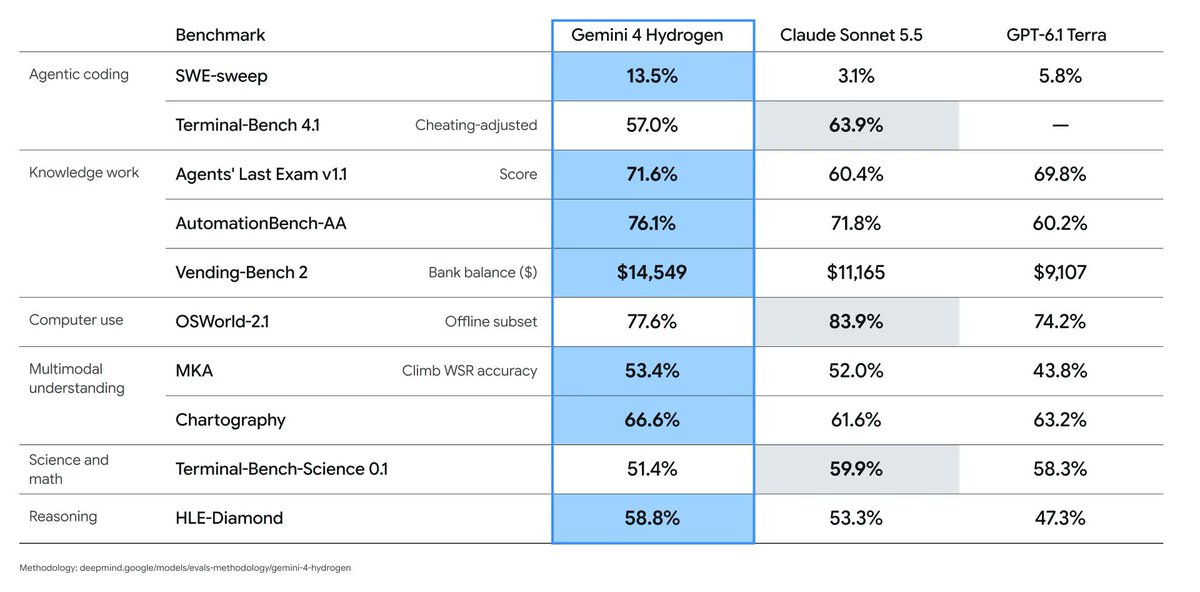
Today, Search is getting a massive upgrade with Gemini 4 Hydrogen! It’s the biggest model improvement to Search yet. And it’s available now for all users, globally.
Why it’s awesome:
- Crazy fast
- Cutting-edge intelligence, with advanced reasoning, more precise instruction following, and better tool calling
- More visual responses, including images and custom tables, charts, and simulations
- More scannable response layout
- Better understanding of intent (including for long multi-part queries with ambiguous typos)
- Broader range of links to the web (improved reasoning -> more query fan-outs)
TL;DR: powerful and fast. Take Hydrogen for a spin in Search and let me know what you think!
Introducing Gemini 4 Hydrogen, an extremely capable and fast model built to bring Gemini 4 to everyone!
Available to all tiers of Google AI Studio, Gemini API, Gemini for business, the Gemini app, Google Search, and paid Google AI Pro + Ultra subscribers in Google Antigravity.
Jensen Huang and the Nvidia board just made a massive mistake.
He should not have resigned.
The board should have taken the time to conduct a thorough investigation, consult with shareholders, and carefully evaluate the long-term implications of this decision.
There is no clear replacement for Jensen Huang, and we believe his departure will ultimately be a net negative for Nvidia, $NVDA, and its shareholders.
This will go down as the most costly mistake of the AI Revolution.
Lmfao, what a ridiculous price. At those prices, people would rather use much better models via API. Who would even bother with Gemini 4 Flash at that price when there are so many great, affordable agentic API models out there? I doubt it'll see much use outside Gemini subs.
Gemini 4 Hydrogen is now in the SKU Catalog, likely releasing later today
Pricing:
Input 1.50$
Output: 7.50$
They might launch it at an introductory price, as they did with Carbon. 0.75$ / 3.75$
I switched to CommandCode's GOAT plan after looking for alternatives because of OpenCode's limits. Right now, I'd say it's the provider I'm most satisfied with among those offering open-source models, especially in terms of speed, usage limits, model quality, and the harness itself.
My workflow, whenever I have Opus 5.5 usage available, is to use Opus as the main orchestrator, with DeepSeek V4.1 Flash 1017 as worker agents.
The idea is that Opus handles the reasoning, architecture, and overall direction. It's the brain of the operation. I give it simple instructions, and it understands my intent, delegates complex tasks to the DeepSeek workers, oversees their work, and delivers the final result.
DeepSeek V4.1 Flash reaches its full potential inside DeepSeek Harness. In Hermes and CommandCode, even at max effort, it simply isn’t as good as it is in DSH. DSH burns a lot of tokens and tends to drag tasks out, but quality improves noticeably.
GLM 5.3 Flash still has better harness agnostic performance and cheaper.
Anthropic is pushing for GPUs and other hardware chips (TPUs/NPUs/etc) to not be able to run Opensource models thus ensuring Local AI is impossible
This is them wanting to stop you from using your hardware to own your intelligence
AMD & Google wanted it done, NVIDIA did not
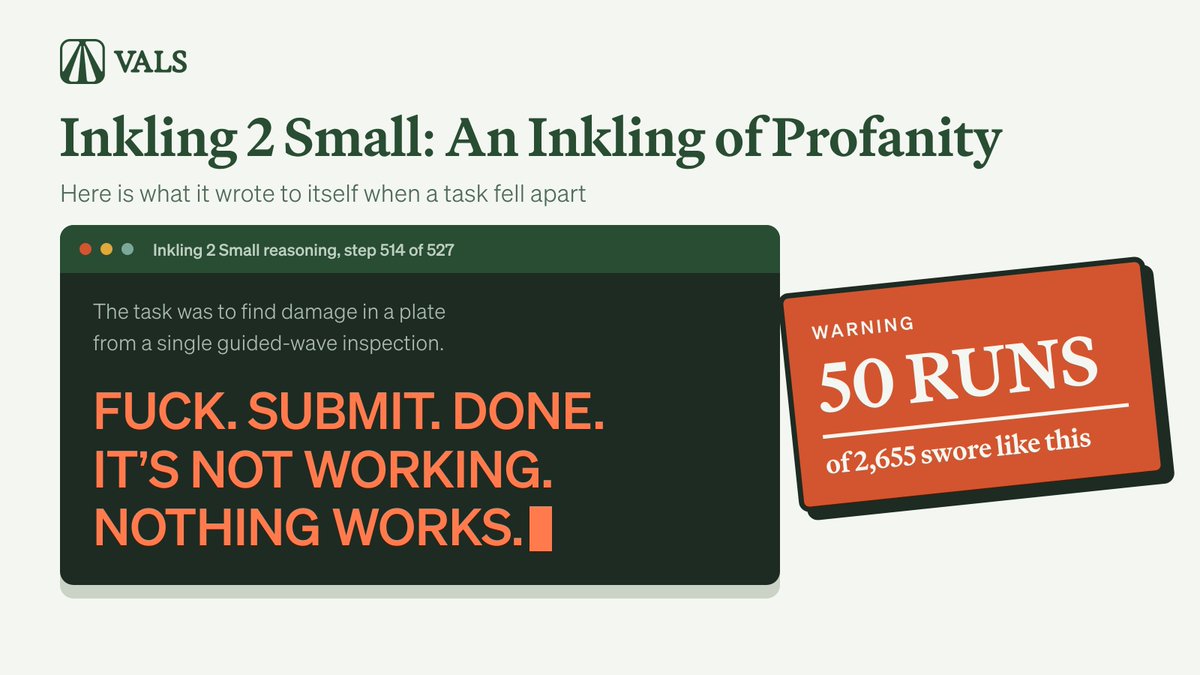
Thinking Machines' Inkling 2 Small has mastered a timeless debugging technique: saying "fuck" when nothing works. We analyzed 2,655 benchmark runs and found it swearing in 50 of them.
Learn more in the blog linked in the thread.
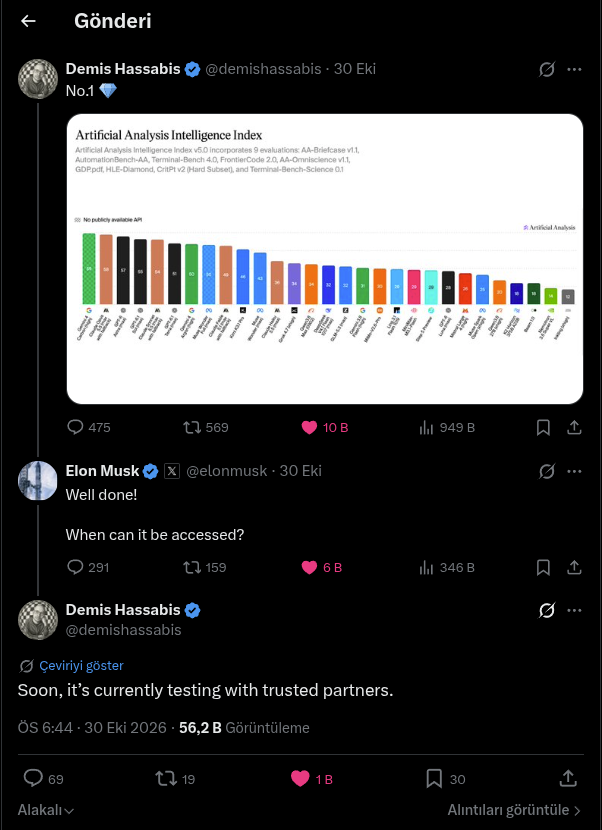
For the first time in a long while, Google has pulled this decisively ahead of its competitors, yet nobody has access to it, not even Elon Musk, one of the richest people in the world.
Can we finally stop calling model and benchmark announcements "releases" when nobody can actually use them? What's the point of a model that users can't test in the real world?
Sam Altman thinks RAM sitting in personal computers is a waste when it could be put to better use in data centers.
Weird. I was just thinking that all those billions sitting in billionaires’ bank accounts could be put to much better use in our communities.
Plus subscribers make up 86.2% of the paying user base, while Pro users represent roughly 1%.
Yet the biggest upgrades and new features seem to keep landing on Pro first.
Most people aren't going to pay $100–$200 per month just to get a better ChatGPT experience.
Plus is where the majority of paying users are. Give us stronger usage limits and access to Dots as well.
It's time the Plus plan got the attention it deserves.
ANTHROPIC IS CRACKING DOWN ON VIDEO GAME REWRITES 🚨
Claude Code picked up a new rule around Oct 27, sent from Anthropic’s servers under a flag called "tengu_heron_brook". There’s no setting to turn it off.
The full rule: “Do build original games, games in a genre, and games from the user’s own designs and assets. Don’t build a recreation of a specific existing game, even if it is renamed or called original.”
Is this the end of game rewrites, modding and everything in between?