we’re hiring 10,000 robotics trainers in the next 7 days.
$50–$90/hour, accepting applicants globally. you’ll review and label videos of robots performing tasks to help them improve. no prior AI experience required.
an entirely new category of work is emerging around teaching robots how to interact with the world.
application link in the comments below.
Today, we’re committing $5,000,000 to launch the micro1 Company Data Partnerships Referral Program.
For every company you refer, you can earn up to $25,000. Simply introduce a company, have them identify you as the referrer during onboarding, and once they enter into a paid data partnership with micro1, you’ll receive your referral payout.
If you know a company that wants to turn its operational data into a recurring revenue stream while accelerating its adoption of AI through micro1's Data Partnership Program, we’d love an introduction.
visit /data to get started
Fable 5 is now live on https://t.co/PFtK9w67C5 and currently ranks #1 across all three of our expert reasoning benchmarks: tax, legal, and financial reasoning.
These benchmarks evaluate how frontier models perform on domain-specific tasks that require expert knowledge, multi-step reasoning, and precise application of rules.
Huge congrats to the @AnthropicAI team on an impressive release.
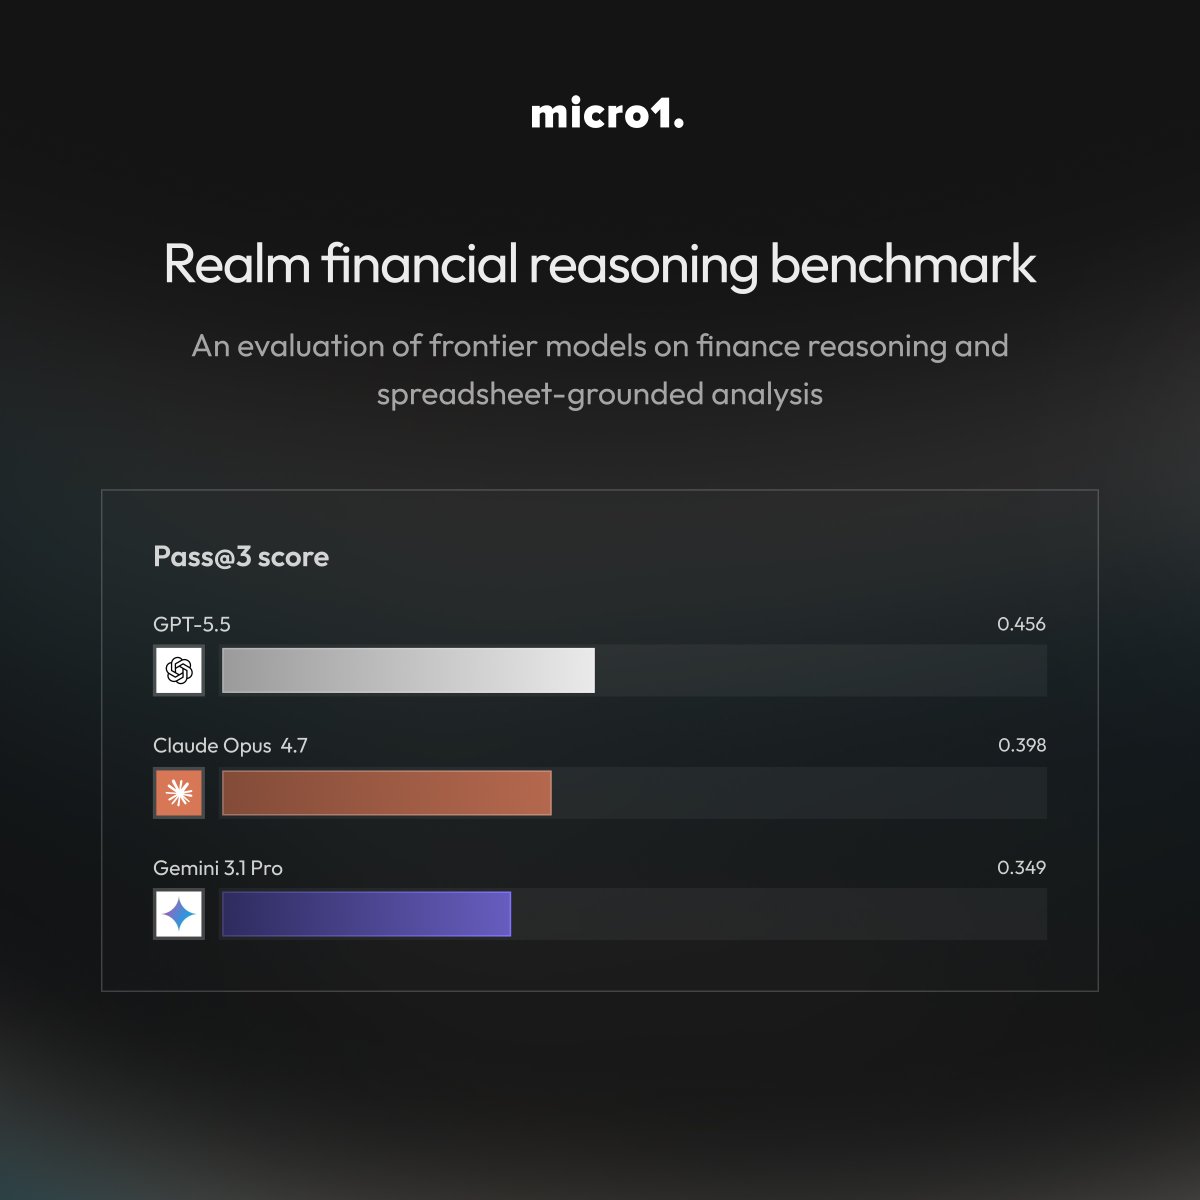
Introducing the Realm Financial Reasoning benchmark, our new evaluation of frontier AI on reasoning in finance and spreadsheet-grounded analysis.
Tasks are built around the actual work product that practitioners deliver, from IFRS reconciliation workbooks and hedge-fund backtests to VC term sheet analyses and treasury cash-flow forecasts. Each task drops the model into a sandbox with the same source materials a human analyst would open: named-range Excel workbooks, broker PDFs, earnings call transcripts, monetary-policy decisions.
Here's what the results showed (Pass@3):
-GPT-5.5: 0.456
-Claude Opus 4.7: 0.398
-Gemini 3.1 Pro: 0.349
The three models score similarly, and none clears 50% on tasks that demand a judgment call. The back and middle office are defensible today, but on capital allocation questions current frontier models should be treated as research accelerators, not final decision-making support systems.
Full report linked in the comments.
Today we’re releasing Realm Warren, part of the Realm benchmark series for measuring frontier AI models on real-world expert workflows.
Each task tests whether a model can produce a legal work product and adapt it as circumstances evolve. We evaluated Claude Opus 4.7, GPT-5.5, and Gemini 3.1 Pro across federal and state law, scored through IRAC: issue spotting, rule identification, factual application, and legal conclusion.
Here’s the results (mean score):
-Claude Opus 4.7: 0.358
-GPT-5.5: 0.351
-Gemini 3.1 Pro: 0.219
The sub-40% result shows where models break down on long-horizon legal work. Three failure modes drive it: the IRAC chain breaks after issue spotting, models front-load their effort and fail to revise, and skipping visual exhibits leads to invented facts.
Full report linked in the comments.
In recognition of National Cancer Prevention and Early Detection Month, join us for an important conversation on how AI is reshaping the future of cancer care.
From accelerating drug discovery to enabling more accurate, scalable diagnostics, artificial intelligence is unlocking new possibilities across prevention, early detection, and treatment. We’ll also dive into the real challenges, data quality, bias, interpretability, and bridging the gap between research breakthroughs and real-world clinical impact.
Featuring:
•Virginie Buggia-Prevot, PhD (Executive Director, @ValoHealth)
•Bahar Rahsepar, PhD (Associate Director of Product, @Path_AI)
•Paola Rodríguez - MD, Eng, MSc. (Director of Medical Research, @micro1_ai)
Moderated by @Exp_Mark (Chief Economist, micro1)
This session brings together leading voices at the intersection of AI and healthcare to explore how human + AI are transforming patient outcomes.
Join us on 4/28, 10am PT: https://t.co/OekKbnPidC
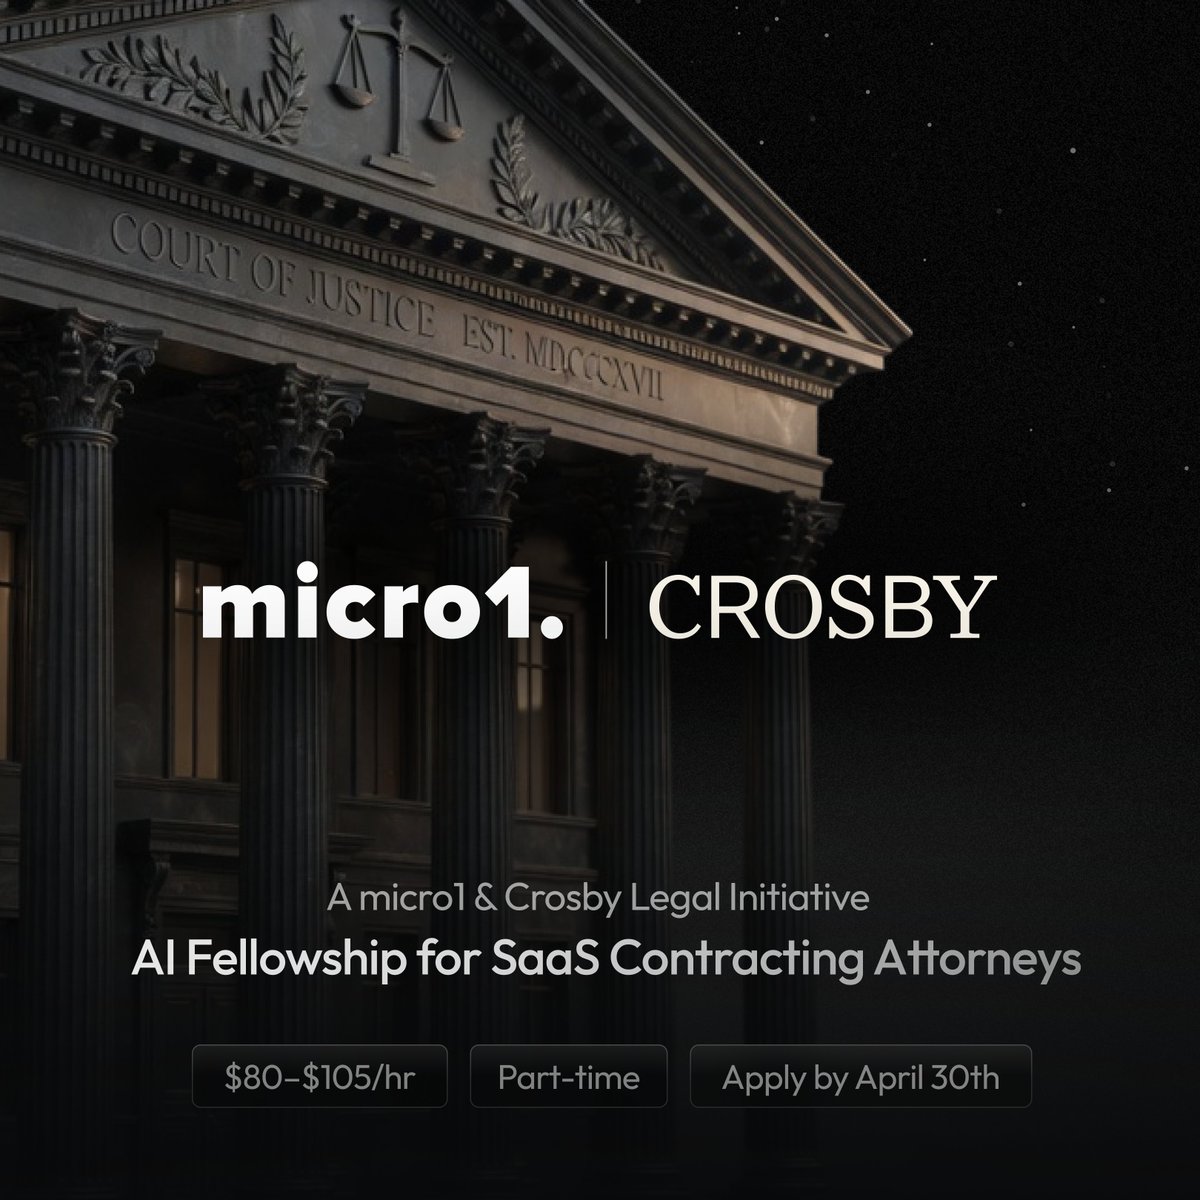
micro1 x Crosby: AI Fellowship for SaaS Contracting Attorneys
We've teamed up with @crosbylegal to launch an AI Fellowship for SaaS Contracting Attorneys, and we're looking for attorneys with deep expertise in tech transactions to help us shape how AI handles real legal work.
Here's what the fellowship looks like:
- Simulated contract negotiations and redlining exercises
- Evaluating AI-generated suggestions for accuracy and legal soundness
- Collaborating with product and research teams to improve AI outputs
This is a part-time, fully remote opportunity paying $80-$105/hr.
Apply now at the link in the comments.