Last year at @tryramp I laid out three predictions for how language models would evolve. I was trying to clarify which bets might actually be durable over time.
A lot of it is now starting to take shape.
Here’s an update. Thread 👇
training runs in 2030 be like
brb putting on my hazmat suit to go into the westus-max-security datacenter which is in a faraday cage and thermally controlled at a resolution of 1 inch to prevent low-bit rate communnication
There is a natural social pressure in organizations against questioning the premise.
Questioning the premise is quite demanding, didn't someone smart already think about this?
For this reason, questioning the premise is the highest leverage activity one can often do.
Surprisingly a robot can sometimes do highly-dynamic manipulation by just copying the demonstration 🤠. Without any learning, cracking a whip or lassoing a cleat can be done directly from human motion capture. And amazingly this process can be nearly automatically implemented by GPT-6 Astra
Check out the full blog post with fun visuals: https://t.co/Ze6tDOSZV8
Turn on sound for full effect 🔈
Quick side note: the whips shown in this post are called signal/stock whips. These whips are built to generate the loud cracking noise when the tip breaks the sound barrier and is a popular art form: https://t.co/GYz0lxEFSu.
Yann LeCun: we are not going to get human-level intelligence or AGI by just scaling LLMs.
“There’s absolutely no way in hell.”
“The idea that we’re gonna have a country of geniuses in a data center, that’s complete BS.”
“It may feel like you have a PhD sitting next to you.”
“But it’s not a PhD.”
“It’s a system with gigantic memory and retrieval ability, not one that can invent solutions to new problems.”
Hammad Bashir is the CTO of @trychroma. He joins @GregorVand to discuss AI retrieval, context rot, agentic search, small models, and the future of AI data infrastructure.
@HammadTime
https://t.co/rrQa6YfglX
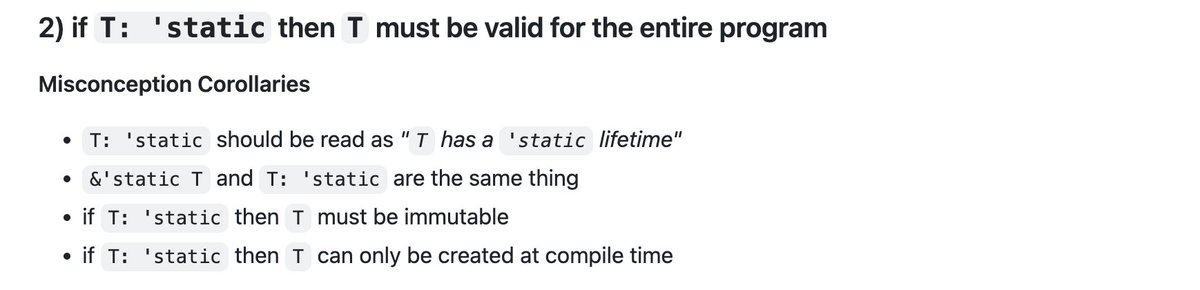
the saddest part of AI writing my code is the depths to which I understand rust lifetimes to the point where I can construct lifetime cases that boggle the mind is now completely useless.
but alas, this is good, it should be useless.
@willdepue I see it as a point on the LLM pareto optimal curve in a regime that had a large revealed latent demand (no thinking, single token, low latency acceptable intelligence) that was under-invested into because of a race to higher intelligence.
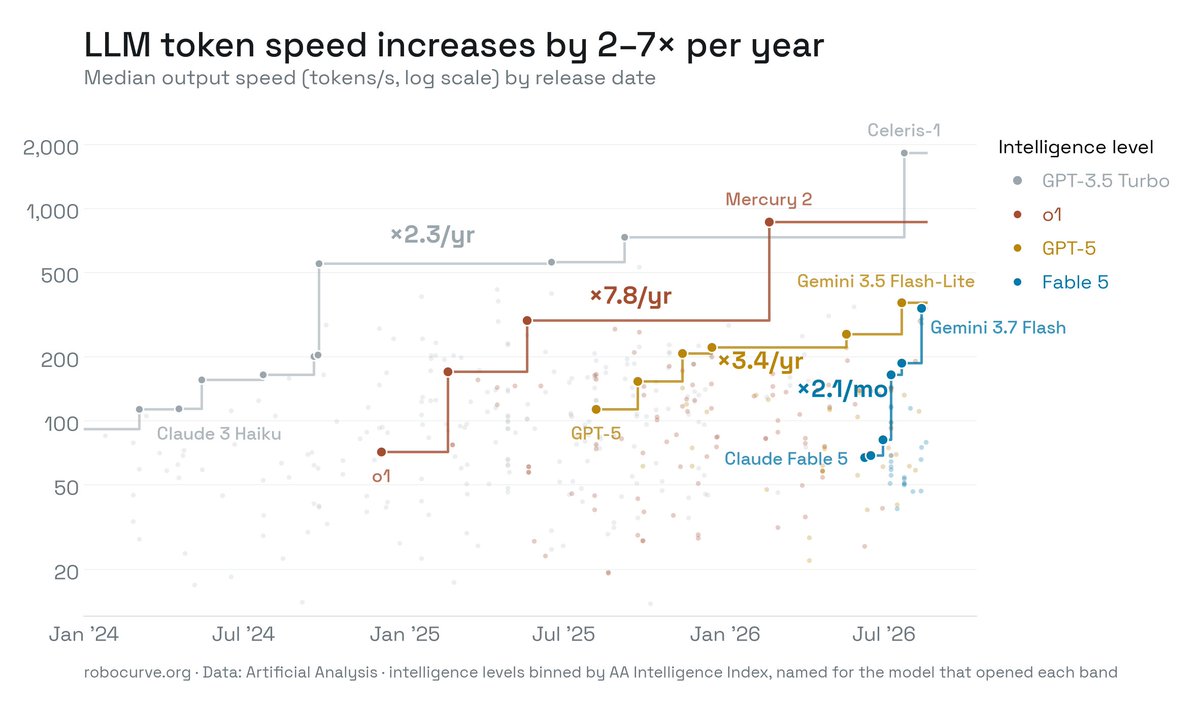
LLM token output speed increases by 2-7x per year, with Fable-class models doubling every month (month!).
If trends continue, LLMs could meaningfully control robots in real time by end of the year, or by 2029 at the latest.