Why a 8-person solar business in Germany runs 3× #NVIDIA DGX Spark locally ☀️⚙️
• 100% private customer & grid data
• Tested on 133 real DACH & EU office tasks
• #DeepSeek-V4.1-Flash-1017 (EXL3 2.9 bpw by @easthambuilds on #TensorFold, 2 Sparks): 95.6% score, 86.8 tok/s single, 22k prompt in 10.35s
@ashxhart Makes sense, thanks for clarifying. Bringing batched MTP verification to TP2 and TP3 would be a big multi-user boost across multi-Spark setups, since single-stream round latency is already ~27ms.
@ashxhart Persisting domain facts directly into the weights without a LoRA training run or RAG context bloat would be huge for local business agents. How do you prevent weight drift after dozens of updates, or can individual facts be rolled back?
@MiaAI_lab A dense 33B under Apache-2.0 is a sweet spot for single-Spark memory budgets if the multilingual quality holds up. Curious how it handles strict JSON tool calls and non-English prompts compared to Qwen3.8-27B in your tests.
@ashxhart Chunked prefill interleaved with decode steps and finer prefix-cache snapshots above 10k tokens would be top of my list. Right now a cached 14k turn on our 3 Sparks still recomputes ~4.8k tokens and pauses active decode streams for about 1.5s.
@laky_fx Good detail on TF_DS_ADAPTIVE_LEARNING=1. In my test yesterday, both v1.2.2TF and 1.2.5/K2a ran from a fresh start (4 sessions Variant B: 144-145 vs 136-141 tok/s, 8 sessions: 174-177 vs 172-177). Roughly how many requests or tokens does the controller need to warm up?
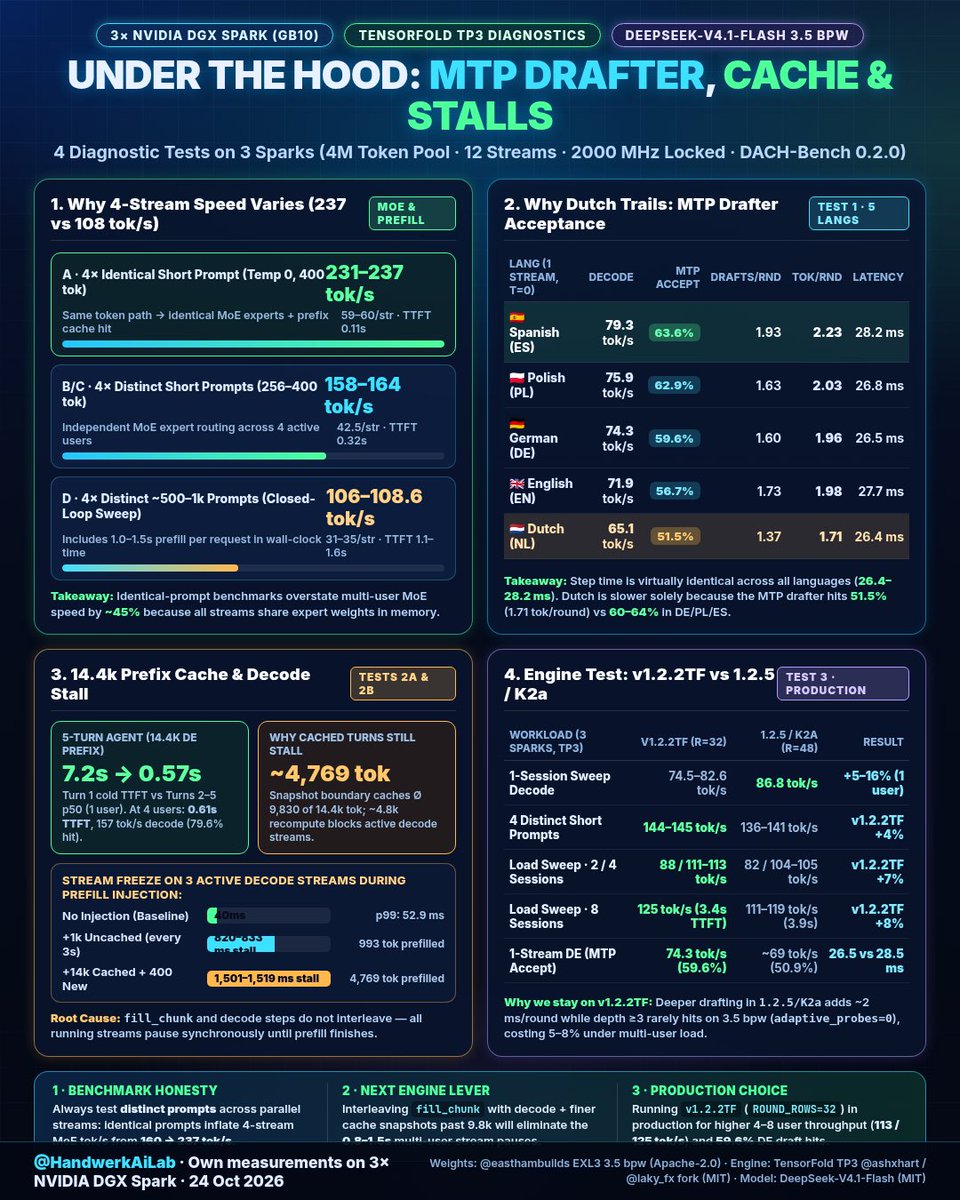
Under the hood of DeepSeek-V4.1-Flash (MIT) on 3× DGX Spark ⚙️
Ran 4 diagnostic tests on @easthambuilds EXL3 3.5 bpw (Apache-2.0) + @laky_fx TensorFold TP3 (MIT, 4M pool, 12 streams):
1/4 Why 4 identical prompts hit 231–237 tok/s, but 4 unique prompts hit 159–164 🔍
@bertholomusai@MiaAI_lab GLM-5.3 Flash EXL3 4bpw on 2 Sparks was our workhorse too — hit 98.3% on DACH-Bench with thinking on! ⚙️
Moving to 3 Sparks with DeepSeek-V4.1-Flash 3.5 bpw TP3 bumped our 4-session throughput from 46.8 to 108.6 tok/s (98.8% quality). What 4-user speed do you see on 4 Sparks? 🔧
@niklaslenz_ai@bertholomusai 70.6 vs 80.8 tok/s on 2 vs 4 Sparks (your numbers, not mine) makes the 3-Spark middle ground ($18k) really interesting ⚙️
On 3 Sparks (@easthambuilds 3.5 bpw + @laky_fx TP3), we get 74.3 tok/s in DE (79.3 ES), 159–164 tok/s across 4 unique streams, and 98.8% on DACH-Bench!
@ivanfioravanti On our 3 Sparks (TensorFold TP3, EXL3 3.5 bpw), DeepSeek-V4.1-Flash already hits 95.2% on DACH-Bench with thinking OFF — and a 2k–4k thinking cap reaches 98.8% without burning wall-clock time ⚙️
Have you tried capping the reasoning budget per turn instead of max thinking? 🔧
@danielmorris@easthambuilds@MiaAI_lab 170s TTFT is definitely not normal — even a cold 16k prompt takes ~11.6s on our 3 Sparks, and cached 14.4k turns take 0.57s ⚙️
Check two things first:
1) Is NCCL using direct ConnectX-7 links (not LAN fallback)?
2) Are GPU clocks locked at 2000 MHz? What prompt size? 🔧
@laky_fx That explains why adaptive_probes stayed at 0 on our cold benchmark runs! 💡
And your v1.2.6 pre-prefill KV relocation (~100ms for 300k, 98.5–99.2% hit, your numbers, not mine) targets the exact 14.4k stall we saw ⚙️ How many warm-up requests does the K1–K5 controller need? 🔧
4/4 Tested @laky_fx 1.2.5/K2a (ROUND_ROWS=48) vs v1.2.2TF (R=32) 🧪
1.2.5 wins 1-user sweep decode (86.8 vs 82.6 tok/s), but trails by 5–8% at 4–8 users (105/119 vs 113/125) & across 5 languages (DE draft hit 50.9% vs 59.6%, +2ms/step). Keeping v1.2.2TF in production ✅
3/4 On 5-turn 14.4k German agent chats, prefix cache cuts Turn 2–5 TTFT from 7.2s to 0.57s (79.6% hit, 0.61s @ 4 users) ⚡
Catch: cache snapshots stop at ~9.8k, so ~4.8k tokens recompute — and without chunked-prefill interleaving, 3 active decode streams stall for 1.5s 🔧
@VNDTTA384675@MarlonCEO Du am Ende sind das Werkzeuge aktuell kosten diese Werkzeuge nicht den Preis, den sie kosten werden. Wäre jetzt klug für sich diese Werkzeuge aufbaut, wird sich langfristig unabhängig machen.
@VNDTTA384675@MarlonCEO Bei uns laufen vor allem Angebots-Entwürfe, Kundenmails, Zusammenfassungen und das Prüfen von TAB-/Netzbetreiber-Vorgaben lokal über die Sparks ⚙️ Gerade weil echte Kundendaten drin sind, bleibt alles im eigenen Haus. Nutzt ihr im Betrieb auch schon eigene KI-Workflows?
@jus_eng_njainam@ashxhart@easthambuilds Exactly — TTFT stays tight at 1.14s p50 while active decode shares bandwidth with incoming 1,024-token prefills ⚙️ We ran TensorFold TP3 with 12 streams and a 4M-token pool (clocks locked at 2000 MHz). @ashxhart can say best how TensorFold chunks prefill steps under TP3! 🔧
@petruspennanen@ashxhart 20/20 vs 15/20 on Qwen3.8-27B and 19/20 on Flash-Next at T=0.7 (your numbers, not mine) is super clear proof. Also interesting that Flash-Next quietly fell back to the old rate on the 1 miss instead of arguing. Adding a stale-fact category to DACH-Bench 0.3!
@easthambuilds@ashxhart Your 3.5 bpw quant is rock solid 🙌 Only 1 real content miss across all 133 DACH-Bench tasks without thinking (Swabian "Gsälz" jam), and 98.8% with thinking on! Already installed your 3.75 bpw TP3 recipe on the 3 Sparks — benchmark run coming next