Full GLM-5.3 (753B) on 4× DGX Spark. Our own 3.0 bpw EXL3 quant, served TP4 on TensorFold!!
Measured on the release build:
• 82 tok/s aggregate across 4 concurrent streams, TTFT ~0.5 s
• ~64 tok/s aggregate with all 4 streams sharing the full 1M-token window
• ~40 tok/s single stream
• 1M context: needle found at 1,039,064 tokens
• KL 0.111 vs BF16, top-1 agreement 90% • Every concurrent reply bit-identical to its solo run
Please read my follow-up replies. Why we didn't use dflash2, why we're not going down to 3 sparks just yet. Thanks to @ashxhart for making the rest of the community lose sleep like him.
https://t.co/FkENDbrjDV
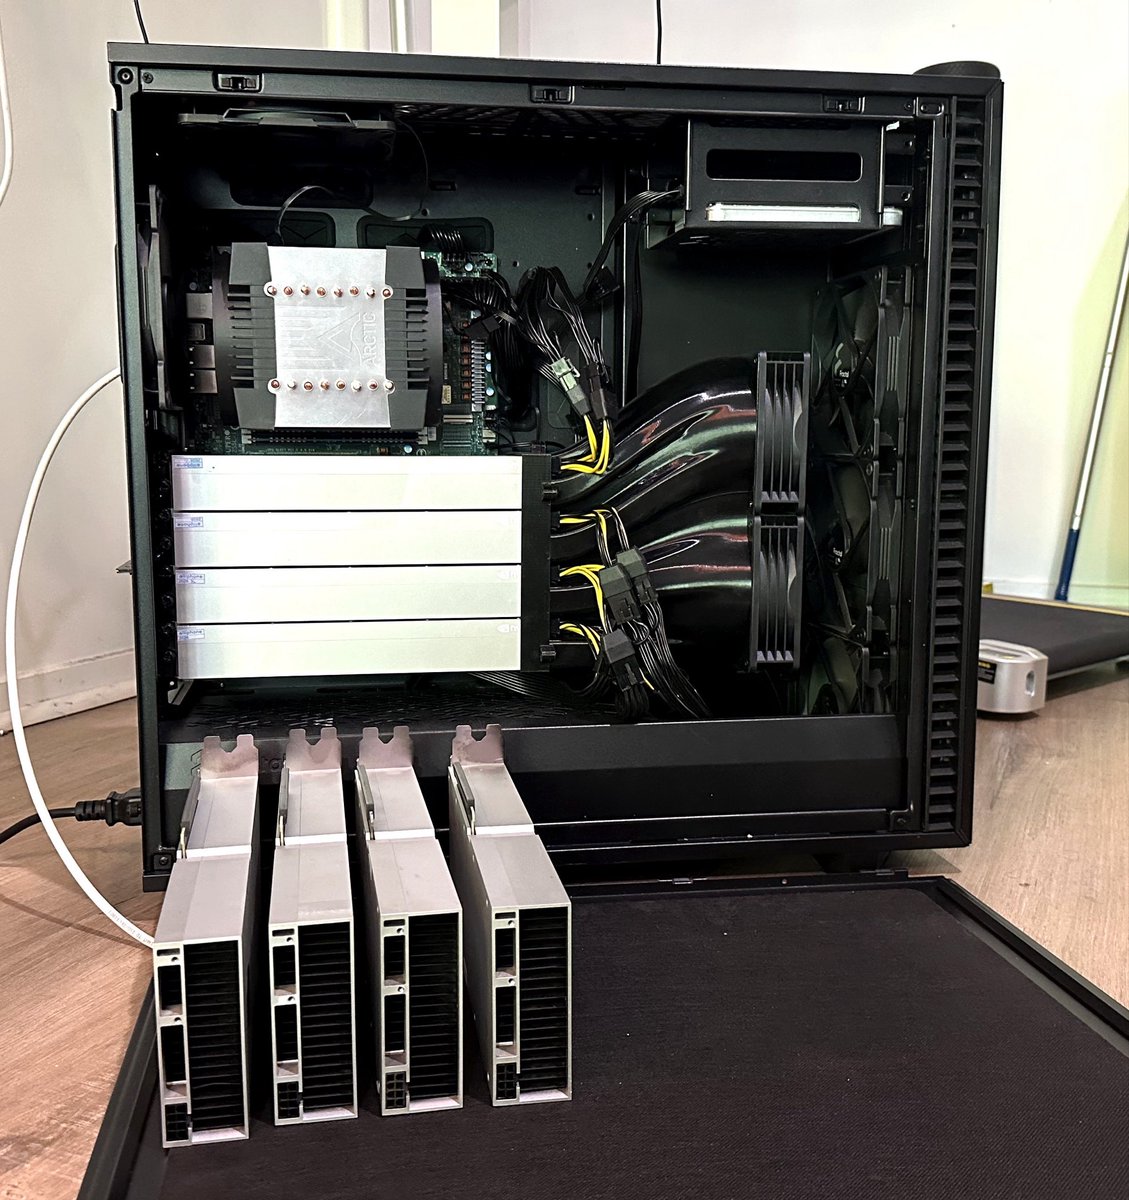
I’m going to need a bigger box!
4 more CMP 170HXs just landed. That’s 512GB of HBM2e, at ~1.5TB/s per card. 🔥🔥
CPU: Epyc 7663, 56 cores
Motherboard: H12SSL-i
RAM: 256GB PC3200 DDR4
SSD: 4TB Gen 4
HDD: 24TB
I’ll need some time to rehome this beasty.
Ling-3.1-flash is now open source: ~560B total parameters, ~25B active per token and up to 1M context.
Built for real work, it can turn a rough brief into a page, mobile UI or interactive prototype teams can review and refine. See the demo.
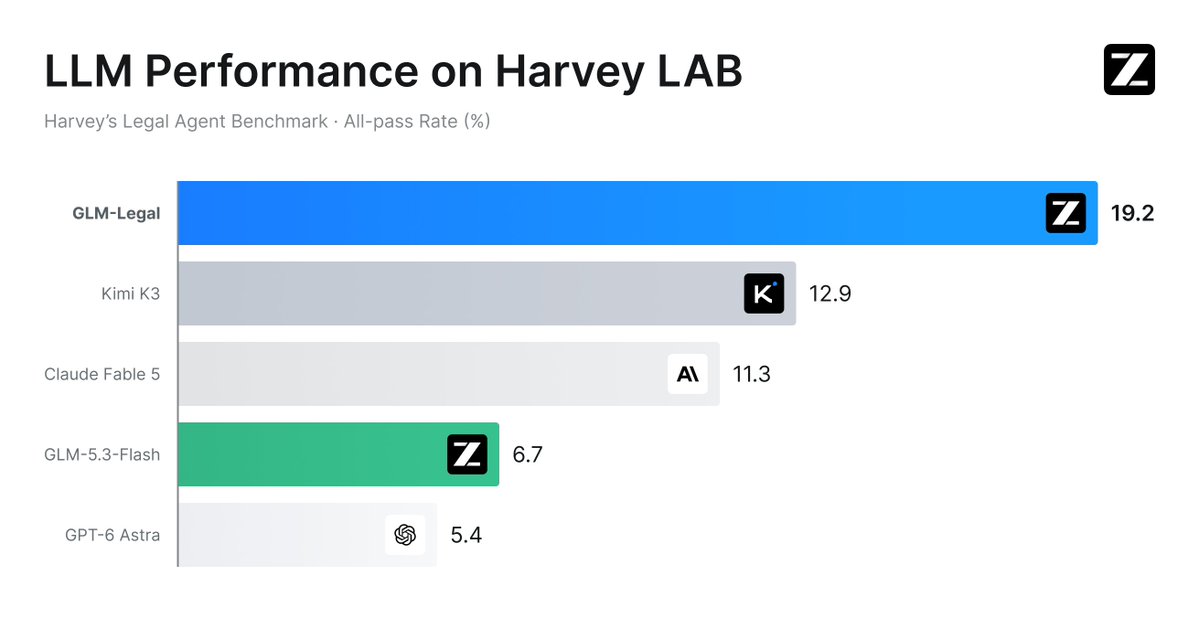
Introducing GLM-Legal
Built on GLM-5.3-Flash, GLM-Legal matches frontier models on mainstream legal benchmarks.
Designed for real legal workflows: contract review, evidence analysis, compliance, and more.
Tech Blog: https://t.co/xOzFqKNyqD
Apply for API Access: https://t.co/dKuoDRIKKz
Try AutoClaw: https://t.co/aGEG5HqTTb
NVIDIA and @Cisco introduce pluggable optics to scale AI factories.
USFP is the first module to support 400Gb/s per lane, delivering 4x the bandwidth density of today's optics. AI builders can connect more compute to the same switch — no extra network tiers, less power per bit moved.
Learn more: https://t.co/uV0qrmD0py