Somebody told me to get more power, so I did. Turns out a terabyte still doesn't fit in 128GB. But my $3,250 rig runs a 125B MoE at 77 tok/s flat across 2K-128K, 25% ahead of the vendor at depth. Arithmetic beats more power. What does your rig do at 128K? @gospaceport@coldniko
https://t.co/SNenlUcQYJ
I should clarify. Email traffic and Kanban tickets.
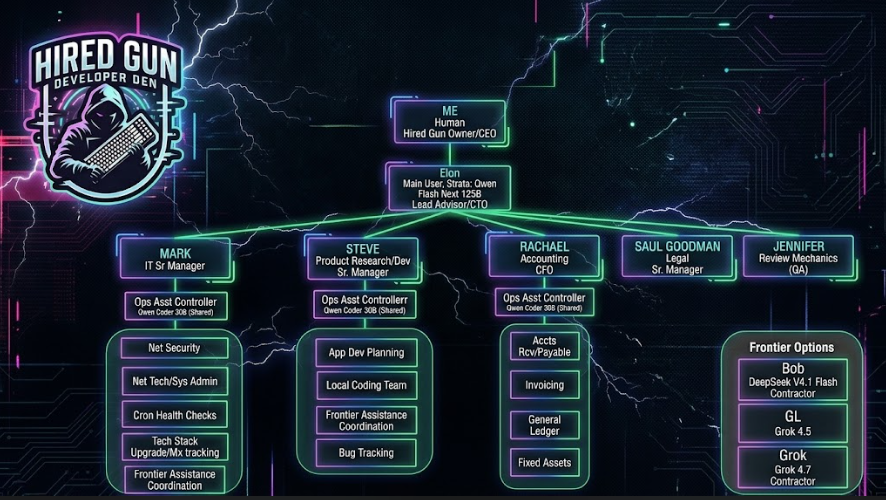
Elon Operates as my mediator.
All context and memory at his level is organizational based sub domain agents, like mark (zuck), Steve (jobs), Rachel (from the office), etc, hold seperate context on the more specific domain.
Subs task the smaller 30b to assessment of my request, then report back, mark and friends make a recommendation with a decision queue to me, elon negotiates workload with options to hire it out to a contractor.
Example. task (Need a UI refactor).. Goes to Elon, he grills me for specifics in an email, I respond to email he recommends the team lead (mark, steve, etc), They plan it and hand the plan back to my elon.. Plans get refined until elon brings it to me.. then i stamp it with my recommendations and he builds tickets.
Appreciate the added angle. Solar plus western renewable buildout is a real factor, and local electricity subsidies plus state capital look like bigger pieces of the cost picture for Chinese AI right now.
Belt and Road feels more tied to exporting influence and infrastructure than to DeepSeek’s domestic pricing, though do you see a tighter connection there?
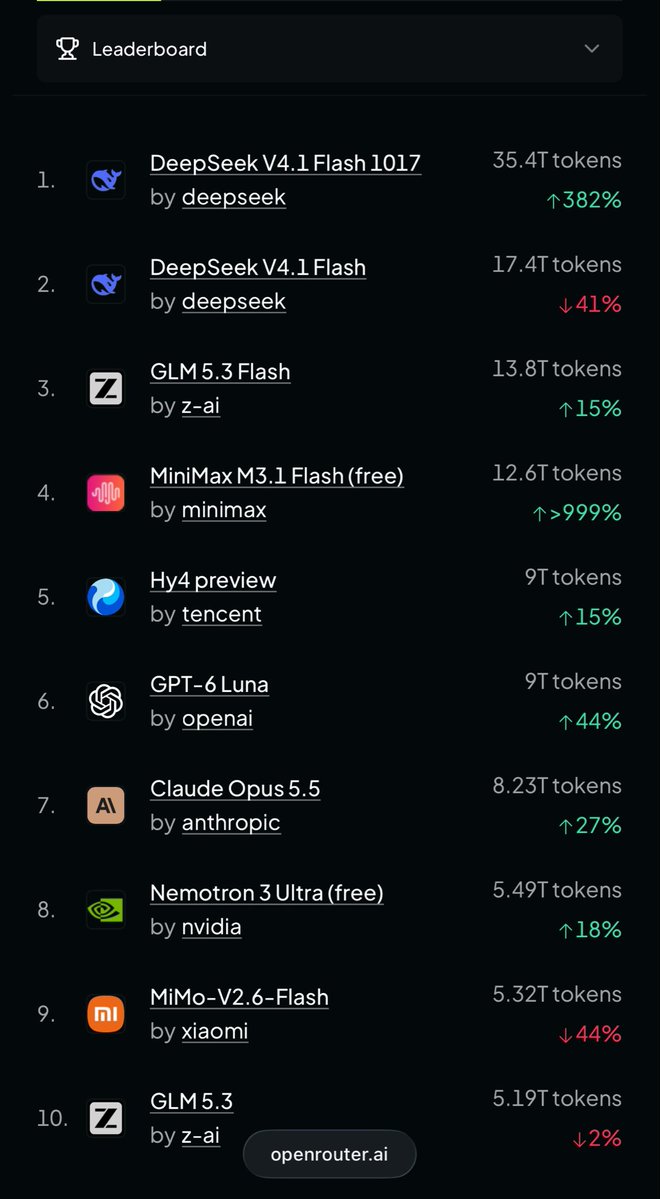
Has anyone ever considered the fact that the way China is able to offer Deep Seek at such ridiculous prices is because they have a massive solar grid powering their AI? US night hours = China peak solar time. @spacexai@SpaceXAIMemphis@gospaceport@NetworkChuck@AdrianDittmann
I validated it, NVIDIA did leave a free 60% on the table for Ampere/Ada GPUs 😎
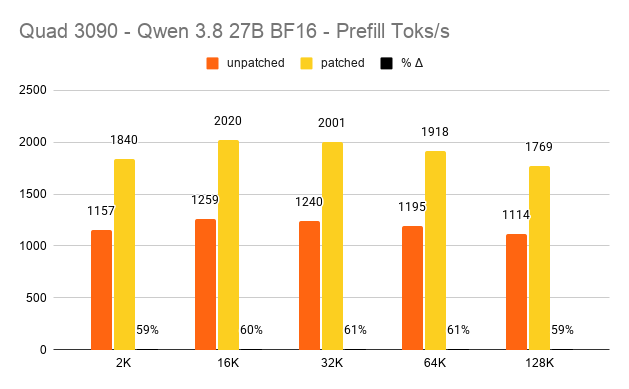
Quad 3090s + Qwen 3.8 27B BF16 in vLLM:
Unpatched: 1114–1259 tok/s prefill
Patched: 1769–2020 tok/s prefill
FREE ~60%+ on prompt processing from 2K all the way to 128K. About 15 mins shaved off every hour for long running agentic tasks in Qwen 3.8 27B and other full precision dense models.
Decode, the same. Power utilization, the same. 🔥 risk, the same.
Quantized models + Imgen/Vidgen, testing soon to get hard numbers
Windows unlocked as well. 50X0, probably 🔜
Kernel module, no driver patching or vbios crap.
Easiest free win of the year for Local Ai 🎉
Notes + bench script: https://t.co/5rBgTrtIf0
@akaNemsko As a person that has worked in the food industry most of my early years.... This is hot garbage... you don't like the tips situation, go find a different job.
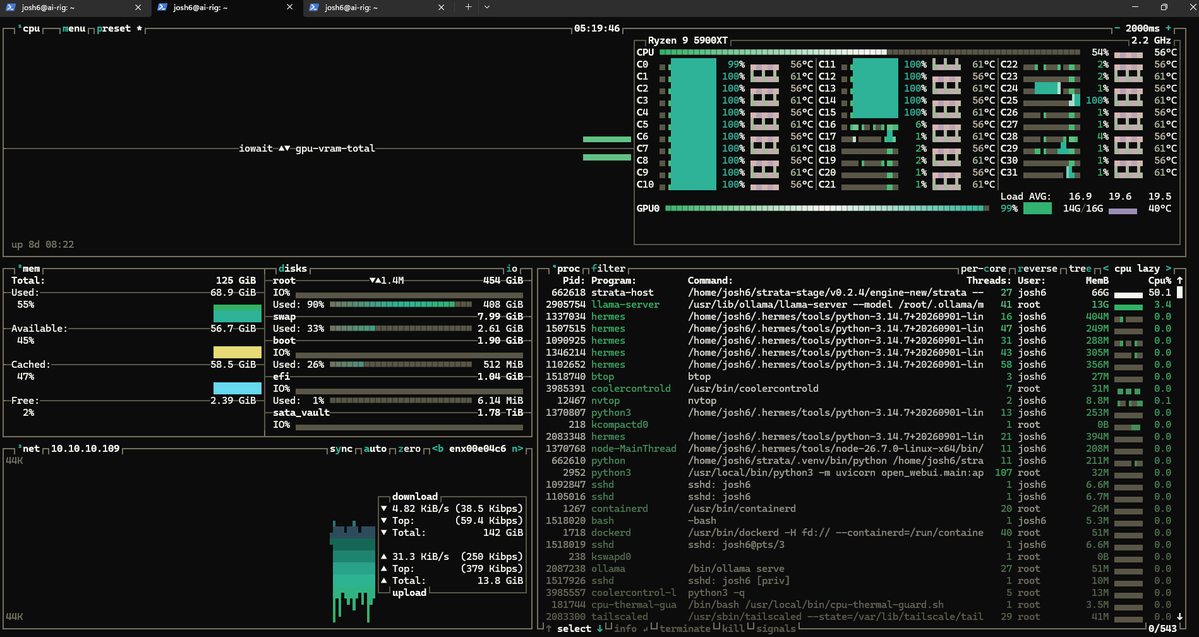
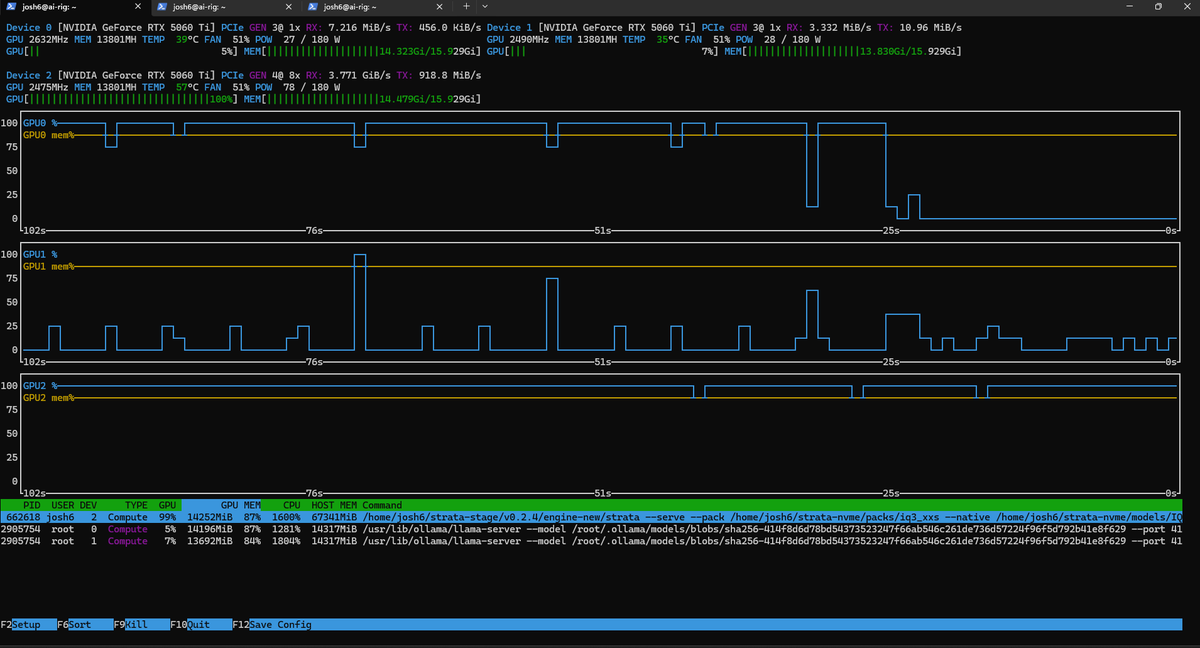
I think my AI rig is ~3K after all the upgrades I can make for my little B550 (128G DDR4, Risen 9 5900XT, 3 5060TI cards, 500G NVMe)... I spend less than ~100 a year in frontier tokens and I am pushing ~ half a million lines of code shipped. https://t.co/PkQtQf4gJs
I ran this on 32Gb DDR4 and a Risen 5 5500 before the upgrades last month.
@gospaceport I think my AI rig is ~3K after all the upgrades I can make for my little B550 (128G DDR4, Risen 9 5900XT, 3 5060TI cards, 500G NVMe)... I spend less than ~100 a year in frontier tokens and I am pushing ~ half a million lines of code shipped.
https://t.co/5Efm4byBzK
I must say Qwen3.8 125B as my attention head for my agent swarm is working out swell with Strata. It's freed up my other 2 cards for additional resources (like a vision model and an Image model). SO i basically have 32GB of VRAM idle at the moment while I run Qwen3.8 125B. and it uses only about ~30% of my 128GB DDR4..
I don't see a benefit in using anthropic.. it's a catch all for lazy devs and companies that don't understand the value of seasoned coding teams. They gladly take your money because it's a fortnite game to most who don't know ai. 99% of ai code is a half asked product no matter what agent you use.