So grateful for the chance to learn from @lintool and his great students, always thankful to both @lintool and @amirhkarimi_ for their support, guidance, and great advice along the way 🎉💛
Summer passed in a blur... 🏖️🦩🍹 and I forgot to congratulate @HosnaOH for finishing her Master's! Her work with @amirhkarimi_ "A Unified Perturbation Framework for Analyzing Leaderboard Stability and Manipulation" https://t.co/lWser4x4lG just got a +1 from NeurIPS, so yay! 🎉
Our paper got an oral at the CTB workshop @ ICML🇰🇷
How stable are LLM leaderboards? 🤔
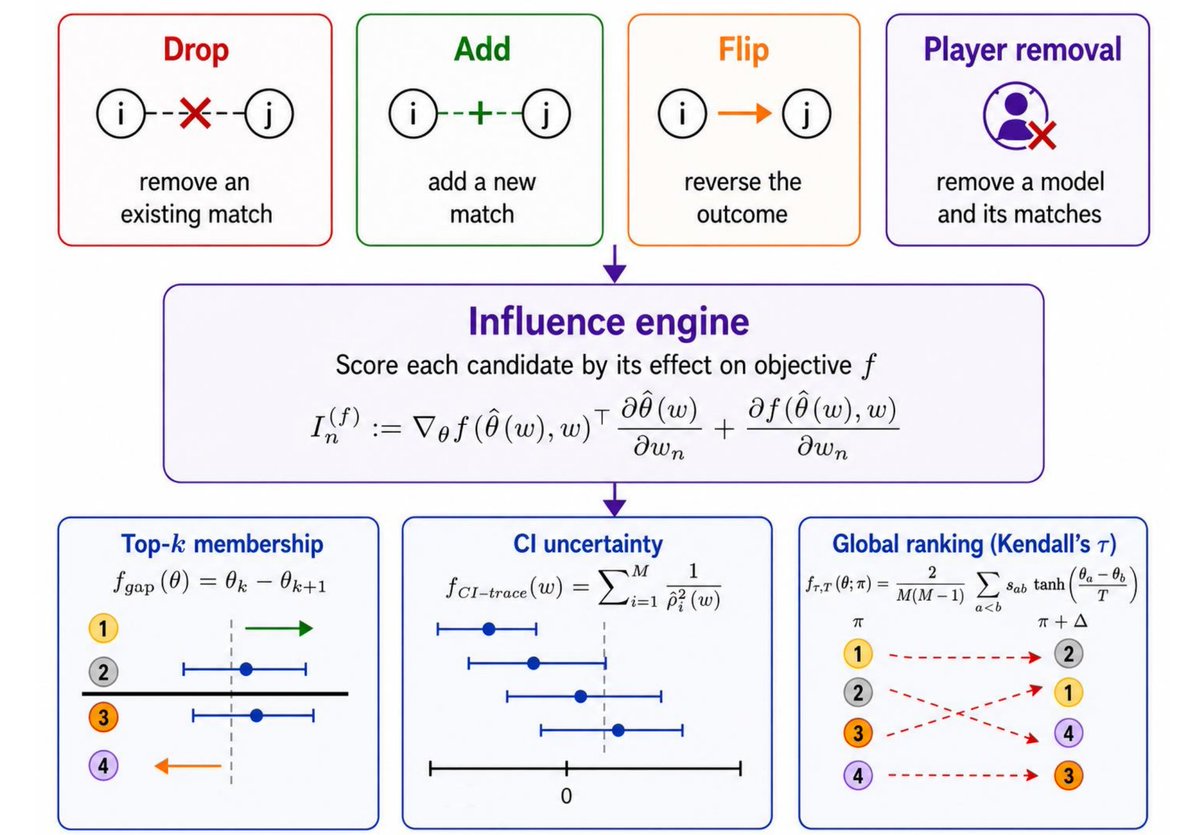
Less than you'd hope. We built a unified framework for auditing how small changes to pairwise votes ripple through leaderboard rankings
📄 https://t.co/tICCrQHYLB
🌐 https://t.co/7Rmyb2WaRG
[1/3] Our agentic search work is at #ACL2026! 🎉 I can't make it to San Diego in person, but luckily @zijian42chen is presenting the poster — go say hi!
The one-line takeaway: 𝑹𝒆𝒓𝒂𝒏𝒌 𝒃𝒆𝒇𝒐𝒓𝒆 𝒚𝒐𝒖 𝒓𝒆𝒂𝒔𝒐𝒏. 🧵
BrowseComp-Plus has been accepted to ACL 2026!
Glad to see that within a year, BrowseComp-Plus has supported 100+ research works exploring the agentic search space.
Unfortunately, I am not able to attend ACL in person.
@zijian42chen will present the paper at ACL 2026, Sunday, July 5th, 14:00–15:30, Harbor G Oral Session. Do chat with him!
This is a great project, backed by tremendous effort from the collaborators. Congrats to the team!
Our paper got an oral at the CTB workshop @ ICML🇰🇷
How stable are LLM leaderboards? 🤔
Less than you'd hope. We built a unified framework for auditing how small changes to pairwise votes ripple through leaderboard rankings
📄 https://t.co/tICCrQHYLB
🌐 https://t.co/7Rmyb2WaRG
Two more findings 👀
➕ In constructive mode, influence-guided Add selects matchups that shrink a target model’s CI faster than the current active sampling method.
🟣 Deprecating a model is not a free action: on Arena 55K, in the worst case, removal changed 5 Top-10 spots.
🤨 Is your agent confused about what to build because it says there aren’t any guidelines?
Now your agent has no more excuses - track guidelines for TREC RAG 2026 are out 🔥
And yes, they’re available via SKILLz 😎
Tell your agents to showcase your agentic search system!
🚀 Introducing AgentIR, a retriever that reads your agent’s mind (literally!)
🧠 Unlike humans, agents explicitly expose thoughts in reasoning tokens. Put them to use!
📈 Simple, substantial gains for agents on BrowseComp-Plus, 35% (BM25) ➡️ 50% (Qwen3-Embed) ➡️ 67% (AgentIR)
🧵
Retrievers, rerankers, and reward models are all language models that score text, and they're all vulnerable to the same adversarial attacks.
We propose unifying the study of how to make these models more adversarially robust. 🧵
https://t.co/rPLUSFLSax