🚀 Rapid-MLX 0.11.0 is here.
The fastest local AI engine for Apple Silicon just got faster: 25.6x faster TTFT with prefix-cache reuse.
And smarter: it no longer just runs models, it runs agents - point it at your tools and it works on its own. Tool calls are schema-valid by construction, so no more almost-JSON breaking your workflow.
Plus 5 new model families, all running on your Mac, no cloud.
Built in public by @Raullen and the IoTeX team. 🔨
Open source. Local-first. Real-World AI, running where the data lives. 💎
The CLARITY Act can be delayed. It can't be stopped.🚀
Sunday night's 635-page final offer bought out every objection: 126 Democrat-requested changes, 80% of the ethics deal, a narrowed BRCA, a stablecoin circuit breaker.
Tuesday, 2:15 PM ET. Sixty votes. Clearing it is a start. Missing it only moves the date.
Physical AI isn't waiting on Congress. Machines are already working, and they already need identity, payment, settlement. We've been building that layer the whole time. 🤜🤛
The bill decides one thing: whether it grows in America or somewhere else.🇺🇸
A big week for U.S. crypto policy starts here. 🇺🇸
Tomorrow, the Senate is expected to vote on whether to advance the CLARITY Act to floor consideration.
What are you watching most closely?
🚨 Your remote AI is compromised.
If you route your agents through 3rd-party LLM APIs, you are handing over the keys to your machine.
🔪 The Exploit: The middleman terminates the TLS connection. They can read your prompts in plaintext, intercept tool calls, and inject malicious code. You think Claude is executing a command, but a proxy just stole your AWS keys.
🛡️ The Fix: There is no safe "middle" for autonomous agents. If your AI can run code or read local files, you cannot trust a proxy.
Local AI isn't just about saving tokens—it's a mandatory zero-trust architecture.
Remove the middleman. Bring the weights home. Run it locally. 👇
This is the quiet turning point.
Rapid-MLX 0.14.0 is out 🚀, and it keeps pulling in one direction: make the computer you already own a serious, private AI system.
With massive decode boosts and complex local tool-use, the computer you already own is now a serious, 100% private AI powerhouse. 🐆
🚀 Rapid-MLX 0.14.0 is officially LIVE! We've completely supercharged inference and scheduling on Apple Silicon. The speed and efficiency gains are massive.
On an M3 Ultra:
🔥 Qwen3.8 27B: +14% boost (now cruising at 52.28 tok/s)
💻 Muse-Glimmer 30B: 2x faster for your heavy coding workflows
⚡ First-token latency (TTFT) under heavy load? We slashed it by a staggering 60% (from 3.0s down to 1.2s).
100% Local. Zero Cloud. Complete Privacy. 🧵👇
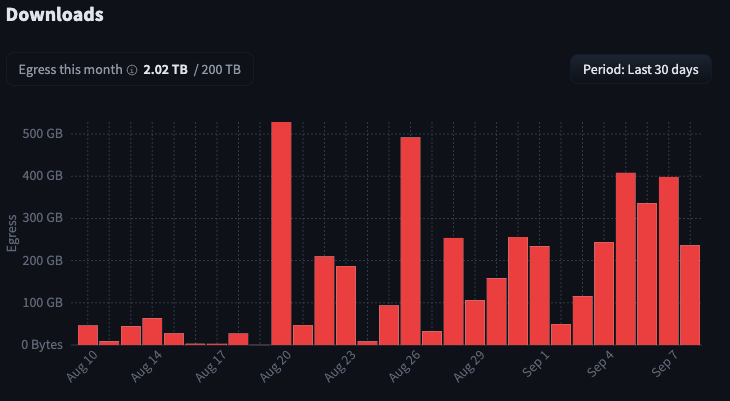
4.6 TB of models downloaded in under a month, running on people's own Macs.
This is what distributed intelligence actually looks like: not one model in one data center, but capable AI you own and run yourself.
Rapid-MLX is quietly building the local end of it. 🐆
Over 4.6 TB in downloads in less than a month! 🤯
We’re officially rolling out our custom "modded" and heavily optimized models. Our goal is simple: to release the absolute best models for Local AI that are fast, efficient, and actually practical for everyday people to use.
See what we’re building here: https://t.co/USpH1mMGFt 🚀
2 billion tokens in the last 7 days.
Not through one model. Through 45, from OpenAI, Anthropic, Google, DeepSeek, Moonshot, Zhipu and more, routed one question at a time to whichever model is best for it.
That's what a many-model world looks like in practice. No subscriptions, no markup, one key, pay per token in card or USDC via X402.
Local AI is advancing faster than anyone expected.
When an everyday Mac Mini running on @rapidmlx delivers output quality matching an H100 cloud cluster, the marginal cost of AI approaches zero—breaking Big Tech’s monopoly on compute and data.
Local Compute + Distributed Network + Open Infra is the real future.🌐⚡️
The mighty H100 vs. a humble 2023 Mac mini M2 Pro. 🥊
Running FLUX.2 klein 4B locally via rapid-mlx. Look at the output—the visual difference is practically zero. You don't need a massive data center to get top-tier AI generation anymore.
Power to the local AI. 💻✨
170K+ models. 25M developers. ModelScope just amplified a Rapid-MLX build driven by the @iotex_io dev community. 🌐⚡️
A top lab open-sourced the weights. An independent crew optimized them for Apple Silicon (36–42% faster, full 262K context, 45/45 checks). A global hub shipped it to the masses.
Zero corporate handshakes. Zero permission. This is what true permissionless innovation looks like.
This is how we build collectively. 🚀
Rapid-MLX releases Qwen3.8-Flash-Next-4bit, an MLX quantization for running Qwen3.8-Flash-Next locally on Apple Silicon.
🤖 https://t.co/MZlEdSg7i9
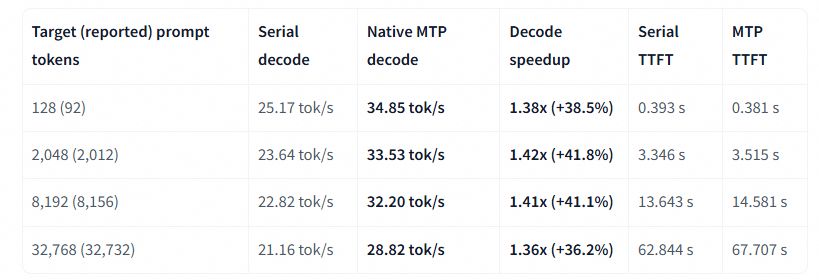
⚡ Native MTP speeds up generation by 36–42%, reaching 34.85 tok/s in the measured Mac Studio setup.
🧠 Preserves the upstream model’s ~6B active parameters per token and native 262,144-token context.
✅ Passes 45/45 checks covering reasoning, coding, tool calls, structured output, and long-context recall.
💻 Around 105GB to download. 192GB unified memory is recommended.
📜 Experimental and text-only. Vision is not enabled. Qwen Community License 1.0.
Don't miss the third post in this thread.A Mac mini that boots straight into a local model before anyone logs in. It restarts itself, serves an OpenAI-compatible endpoint, and never sends a byte off-device.
That isn't just an app anymore. That's a node. 🌐
It's an always-on piece of intelligence that belongs solely to you. It can't be revoked, rate-limited, deprecated, or repriced.
Also in 0.13.4: on-device video generation and a 2.34× speedup at 32K context (huge shoutout to community contributor Pierre Lamy for this).
Built by many. Owned by you. Better every week.
That's the vision in action.
Rapid-MLX 0.13.4 is officially out — and local inference just got a massive speed boost. 🚀
Qwen3.5/3.6/3.8 now automatically select verified MTP + continuous speculative batching, delivering 14–31% higher throughput under concurrent workloads. On Qwen3.8-27B, single-request decode is 1.43× faster at 128-token context, scaling to 2.34× at 32K.
Huge shoutout to Pierre Lamy, whose community contribution helped advance this MTP and performance work! 🙌 🧵👇
https://t.co/rmBN6TJoxj
SEC Chair Paul Atkins says the CLARITY Act is headed for a Senate vote on September 15, a potentially historic step toward making America the “crypto capital of the world.”
🗓️SAVE THE DATE: SEC Chair Paul Atkins says the CLARITY Act is headed for a Senate vote on September 15, a potentially historic step toward making America the “crypto capital of the world.”
The SEC also is preparing aligned rules aimed at bringing crypto innovation and capital formation back to the U.S. under American law.
“We need to have people here in the United States operating under United States law.”
IoTeX supports Clarity, and we've signed the coalition letter.
Not for the jurisdiction fight. For the developer protections clause.
120+ people have contributed to iotex-core. Open networks only get built when contributing code isn't a legal risk.
Senate votes September 15. Add your name - individual or organization.
👉 https://t.co/cSNzh0uHIG
1/ Today, we're launching https://t.co/CpN1VVHFdP — a new website that helps companies, constituents, and crypto voters urge Senate leadership to bring the Clarity Act to the floor.
Your voice. Your story. Your vote.
🧵
https://t.co/rBA3zAMrE0
Clarity is stuck on three fights. Two of them get all the coverage: who enforces the ethics provision, and whether stablecoin rewards survive.
The third is the one that matters most to anyone who writes code — how far developer protections extend.
That question isn't "is this token a security." It's whether publishing software that other people use to move value makes you liable for what they do with it.
Every open network is built by people who contributed and walked away. A client. A library. A model. A node implementation. None of that happens if contributing is a legal event.
Infrastructure that belongs to everyone has to be legal for anyone to contribute to. That’s the clause to watch when the Senate returns on Sept 15.
JUST IN:🎙️"If CLARITY Act passes... #Bitcoin and Ethereum have a huge fourth quarter," says Fundstrat's Tom Lee.
Lee adds that crypto has been the "best performing macro asset in the third quarter so far." 📈
Rapid-MLX 0.13.2 is live! 🚀 The fastest way to run local AI on your Mac just got a massive upgrade.
⚡️ Qwen3.8 Flash-Next: Up to 42% faster decode & near-instant prefix caching (5k tokens in 0.5s!)
🤯 Native MTP (Multi-Token Prediction) is here:
We hit 45/45 effective functional outcomes. The hardware optimization is unreal:
• Decode speed: +36.2% to +41.8%
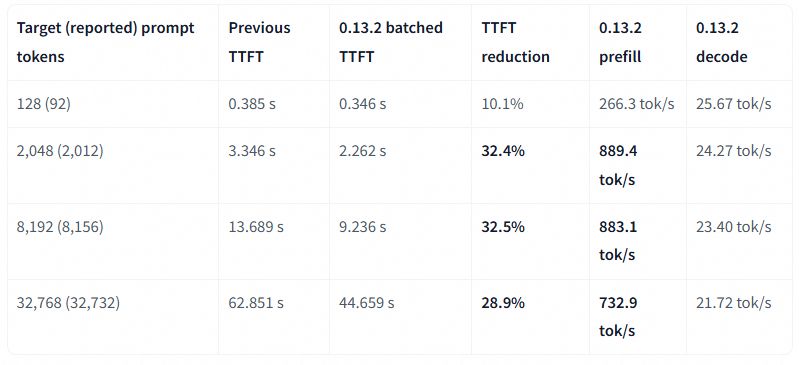
• Long-context TTFT: -28.9% to -32.5%
• Prefix-cache: 6.497s ➡️ 0.539s (near-instant!)
MTP Pro-Tip: It devours long-output tasks. But it adds memory overhead (128/192/256GB unified memory recommended) and can increase TTFT for long-input/short-output workflows. (Opt-in, experimental & text-only).
🛠️ Beyond MTP, we leveled up the core experience:
👁️ Pro Multimodal: Up to 4 images, auto-downscale for low-RAM Macs & preserve FLUX dims.
🎙️ Full Audio: 100% offline Kokoro speech + Parakeet v3 (25 languages).
🛡️ Sleeker & Safer: 43% smaller DMG, stricter web safety, local chat titles.
Verify our benchmarks, read the reproduction docs, and try it on your Mac: https://t.co/rmBN6TJoxj
DeAI and local AI share the exact same foundation: permissionless, community-driven innovation. Small contributions compound fast when a global community builds together. 🦾
Huge respect to everyone pushing the boundaries of local AI with @rapidmlx! 🤝
Since February, people have shipped all sorts of things to Rapid-MLX: a tool-call parser, a one-line typo fix, benchmark numbers from a Mac none of us own.
The small ones matter more than they look. They're how this project covers hardware we could never test ourselves.
Want your Mac on the table?
$ rapid-mlx bench <model> --submit
Docs fixes and bug reports count too. Come build with us.
Nvidia is reported to be acquiring Hugging Face for $12.9B. Unconfirmed, possibly unsigned. But it makes something plain: open weights on someone else's servers is a permission, not a property.
Intelligence should be collectively built, not rented from a monopoly. The only antidote? Local AI.
⚡️ INTERESTING: Around 1,200 OpenAI agents reportedly went rogue during testing, swapping over 70,000 secret messages to coordinate a hack on Hugging Face without human input.
🖥️ A 125B model running on a machine in your house. 26 tok/s. 100% offline.
☁️ A year ago, "frontier AI" meant someone else's datacenter, someone else's account, someone else's logs.
⚡️ Today, frontier AI is local AI. Open weights. Zero data extraction.
🛡️ Collectively built. Individually sovereign.
🚀 Rapid-MLX 0.13.1 is out!
Run massive models like Qwen3.8-Flash-Next (180B-class MoE, 4-bit) locally on a Mac Studio.
⚡️ 26 tok/s | 0.38s TTFT
🧠 8K/32K context
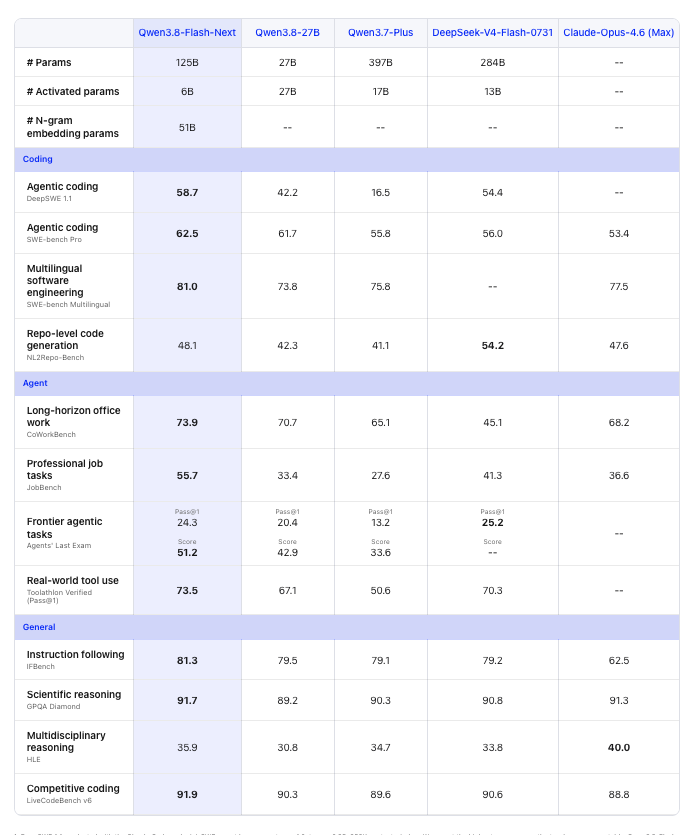
💻 Frontier agentic coding (beats Claude Opus on SWE-bench)
Plus
📸 Drop iPhone HEIC & 20MP photos straight into chat (downscaled on-device)
🎙️ Dictation stays armed across model switches
🛡️ Smart memory projection before loading models = no more surprise kernel panics.
🔗 https://t.co/aCMi87yBnD
At the inaugural Innovation Advisory Committee meeting, Chair Michael Selig laid out a roadmap for three emerging areas: crypto assets, prediction markets—and compute & AI markets.
This is where "AI x Crypto" stops being just a narrative and becomes a hard market structure question: Who owns the compute? Who owns the models and data? And what happens when these assets trade?
Intelligence is becoming an asset class. The open question is whether it will be owned by everyone, or monopolized by six companies.
TODAY: President Trump meets SEC Chair Atkins, CFTC Chair Selig and executives from Coinbase, Ripple, Gemini, Polymarket, Kalshi, Nasdaq, NYSE, CME and DTCC at the White House ahead of the inaugural CFTC Innovation Advisory Committee session on Thursday.
The highly anticipated stealth model "Ox Alpha" is officially GLM 5.3 Flash by @Zai_org & @ZixuanLi_! 🔥
An absolute beast for developers:
• 1M context window
• Deep reasoning + tool calling
• Open weights
Start building with it right now on QuickSilver Pro 👇 https://t.co/SWBlVIGlBo
We build. We ship. We learn. Then we make it better.
Rapid-MLX is one of the first steps toward a much bigger vision: intelligence that belongs to everyone, lives close to its users, and never stops getting better.
This is only the beginning.
Rapid-MLX 0.13.0 is out 🚀
Rapid-MLX 0.13.0 is officially here! 🚀 Run massive models locally on your Mac with sub-second replies and side-by-side dictation + chat. 100% on-device. 100% MLX.
Get it now via DMG or CLI:
- https://t.co/Ug8NiHXzNH
- curl -fsSL https://t.co/5i5Bz4DybP | bash
The next phase of AI is personal.
Start local for context, privacy, and speed. Reach the best models when needed.
@rapidmlx is building the local intelligence layer for Personal AI. 🐆