[4/4] Paper: https://t.co/pzGJQjbaJd
Code: https://t.co/7gPrSYpluM
Data: https://t.co/Edi3tCVn7L
And a big shoutout to the team: Piotr Sielski, @hugolinsen, Rajesh Gandham, @shiemannor, Alex Fender, @GalChechik and @eli_meirom!
[1/4] EARLI is out in Nature's Communications AI & Computing!
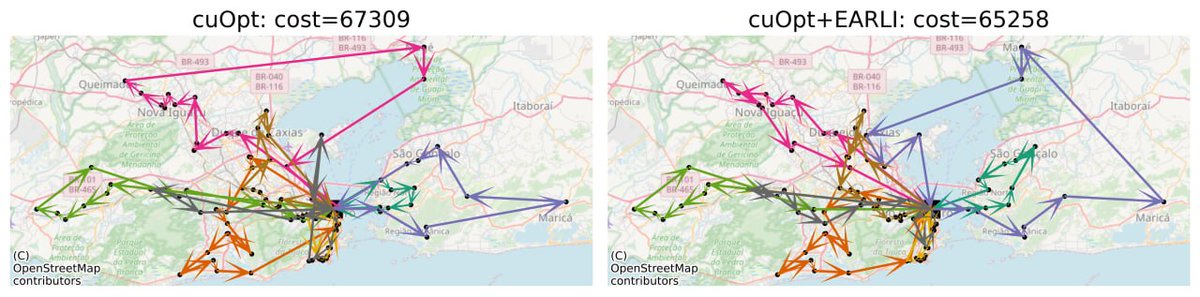
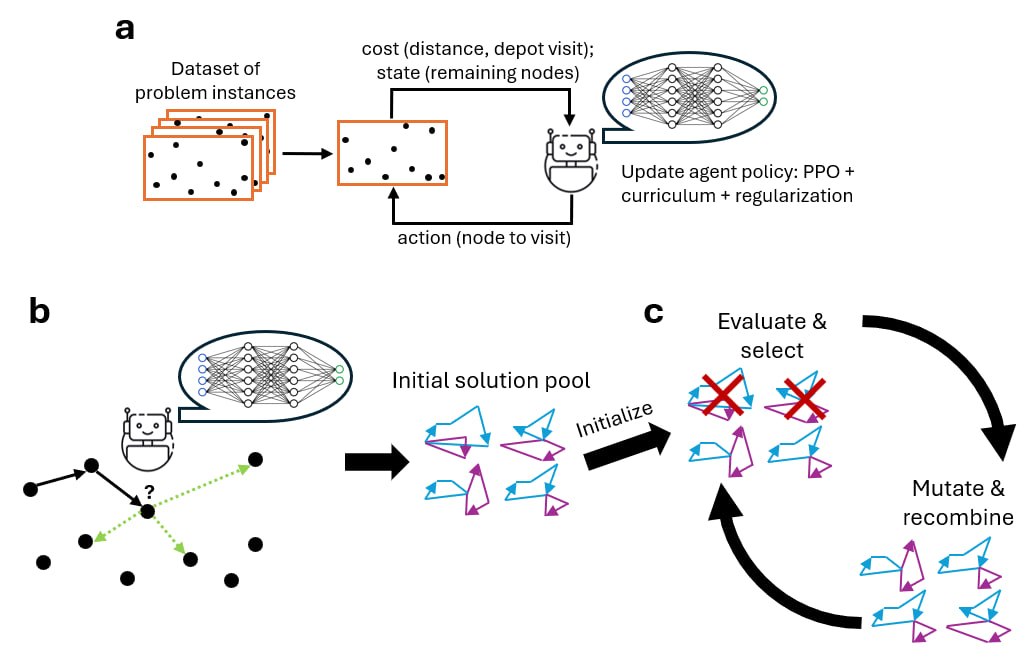
EARLI combines learning and genetic algorithms to accelerate routing solvers like cuOpt and HGS, producing high-quality routes in seconds for hundreds of delivery locations.
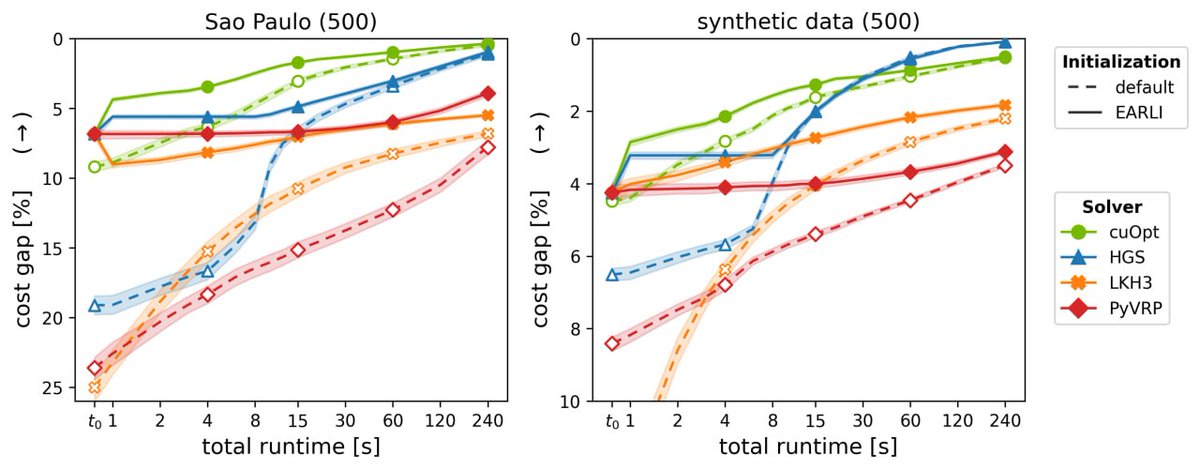
[3/4] EARLI improves cuOpt, HGS, LKH3 and PyVRP across time budgets and datasets, and even generalizes out of distribution to a previously unseen city.
[2/4] SOTA delivery solvers tackle many similar routing problems every day. Why solve each problem from scratch?
EARLI learns from past problems with reinforcement learning, quickly proposes route solutions, then uses them to initialize an iterative optimizer.
@amsterdamski2 אני חושב שנכון יותר: אם אתם רוצים פיצוי ממס רכוש עבור דירה חלופית, תמשיכו לשלם שכר דירה. לחלופין, מותר לכם להפסיק לשלם ולוותר על הפיצוי מהמדינה.
ואז זה מסתדר גם עם המקור שלך וגם עם התגובות.
@HarelKleiner היי, כתבת בעצם ש:
א. העירייה נותנת מגורים חלופיים.
ב. המדינה מחזירה את שכר הדירה.
ג. השוכר פטור מלשלם שכ"ד למשכיר (כתבת בפוסט נפרד).
לא הבנתי אם השוכר אמור לקבל הכל או לבחור אחד - כי הרי אלה שלושה סעדים שפותרים את אותה הבעיה
@AMIRD1978 לא רמאות - זה ניהול כושל של כלכלה על פני עשרות שנים. מתחלק לחוסר יעילות (כמו חסמי ייבוא הזויים), גזל ישיר (הטבות מוגזמות לאוכלוסיות מסוימות), וצרכים יקרים (ביטחון, שמנוהל לאחרונה בלי מחשבה על השלכות כלכליות). אז יש מחסור (נדלן, עובדים, חומרים) ומחירים עולים.
@rozolyo@YairGolan1 כמי שהרבה יותר קרוב לדעות של יאיר גולן, אני חושב שהוא התנהג פה בדמגוגיה, חוסר תרבות דיון ואד-הומינם בריוני בתגובה לשאלות סבירות, באופן שמזכיר הרבה ח"כים מהקואליציה, והתשואות שהוא מקבל בתגובות הן המסמר האחרון בתקווה שלי שתקום פה אי פעם ממשלה עניינית ושקולה
הראיון המלא שלי הלילה ברשת NBC האמריקאית על המלחמה בין ישראל לבין חיזבאללה:
״דמיינו שמדינת פלורידה היתה סופגת 8,000 טילים, ועשרות ילדים שלכם היו נרצחים במגרש כדורגל, מה הייתם עושים?״
Following my recent work (link in comments), I was asked why we need to optimize risk measures in RL at all. Can't we just express risk aversion through the rewards? Short answer is: often not.
https://t.co/JeNp82Vh1x
#artificialintelligence#reinforcementlearning#riskmanagement
[4/4] Our algorithm - Cross Entropy Soft Risk (CeSoR) - not only solves the surprisingly tricky maze, but learns cool risk averse strategies in other problems, like keeping more distance from the car in front of it, and using the gas and brakes less frequently.
[3/4] To sample more high-risk episodes, we developed a dynamic version of the cross entropy method (CEM), which can be used more generally to over-sample useful examples for training. See our PyPI package:
https://t.co/TaxFvXmWFb