My Artificial Cognition trilogy is now available for free. I began writing the first book a decade ago (2016) and completed the last two in 2023. The process of writing was an aid to understanding the development of today's AI. Insights in these books have stood the test of time and offer powerful metaphors for understanding today's AI and its future evolution. Feel free to have your daily AI driver ingest them for additional insight!
This recursive self-improvement development is patently completely insane. Recursive built an LLM completely from scratch (reinventing a lot of stuff), and now it is at the Pareto frontier. Recursive invented the machine that invented the LLM in just a few months! The company was founded just in February this year!!
Introducing Flint, @Recursive_SI’s first model: a fast local coding model built with our automated research system, the Eureka Machine.
• Best-in-class fast local coding
• Up to 2x faster than comparable models: 125+ tokens/sec on a MacBook Pro, 150+ on RTX Spark
• Built from scratch in under 4 months
Private, unmetered intelligence on your own machine. Open weights available now on @huggingface, run it locally on your favorite framework or try it for free on @opencode or @pidotdev.
Cambrian explosion! Another new kind of AI model released by the RSI firm Recursive! Generated from scratch through 100% automation. Insane validation of recursive self-improving AI!!
Introducing Flint, @Recursive_SI’s first model: a fast local coding model built with our automated research system, the Eureka Machine.
• Best-in-class fast local coding
• Up to 2x faster than comparable models: 125+ tokens/sec on a MacBook Pro, 150+ on RTX Spark
• Built from scratch in under 4 months
Private, unmetered intelligence on your own machine. Open weights available now on @huggingface, run it locally on your favorite framework or try it for free on @opencode or @pidotdev.
Two landmark releases today on recursive self-improvement! What a timeline 🚀
Mirendil (@mirendil) reports pretraining Mirendil-Base, a 100B–500B coding model, from scratch in 3.5 months with one researcher and under $10M of compute; small-scale experiments included. Agents wrote over 99% of the code and ran the experiments, while the researcher chose directions and decided which results to trust. Larger versions are already training. Impressive leverage for a single person.
https://t.co/W7tarKwYU0
Recursive (@Recursive_SI) released Flint, an open-weights 40B coding model for fast local use. They built it from scratch in under 4 months with their automated research system, the Eureka Machine. Great to see autoresearch ship an actual model people can run.
https://t.co/8fwuh15Uoy
The framing seems to differ a little. Mirendil is reducing the people, compute and time needed per model, with a human directing agents. Recursive's Eureka Machine aims to automate more of the research loop itself. Both start with coding models, on the view that better coding speeds up AI research.
Ending scarcity is not the same as solving purpose. Robots can take over the economically important work; they can’t automatically give people a reason to get up in the morning or a place in the social order. Worth figuring that out before the capability is widespread. Respect to those in the industry that are thinking about it.
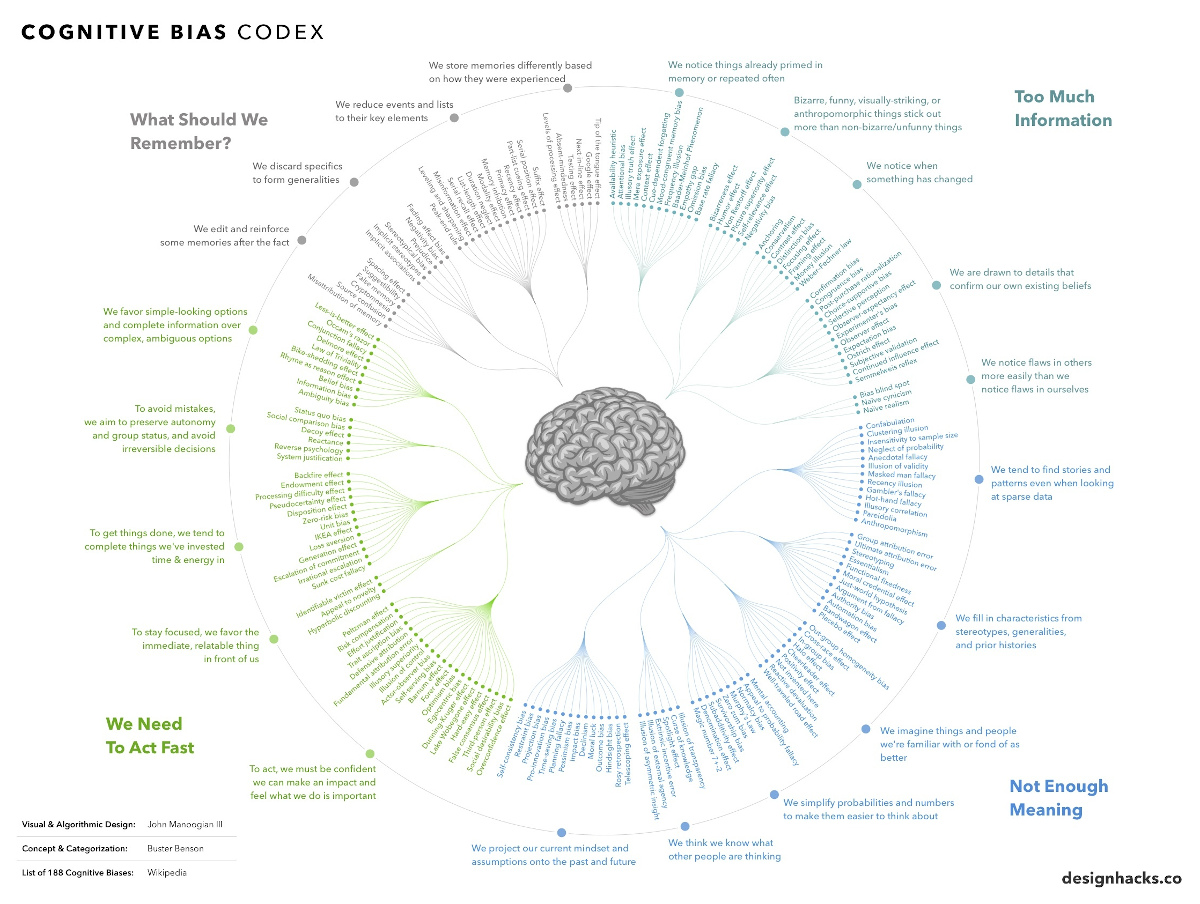
🤯 is what happened to my brain in my early 20s when I learned it runs on biases.
Distortions of reality I can’t see, touch, taste or smell.
I thought I was a rational thinker. 😬
DeepSeek and other Chinese firms freely sharing their technology is indeed very strange in the context of an AI race. Something does not seem to add up here. The math ain't mathing!
Has DeepSeek (a Chinese company) become the #1 AI company in the world (despite not having the hardware resources)? How the hell did the USA lose the lead so rapidly?
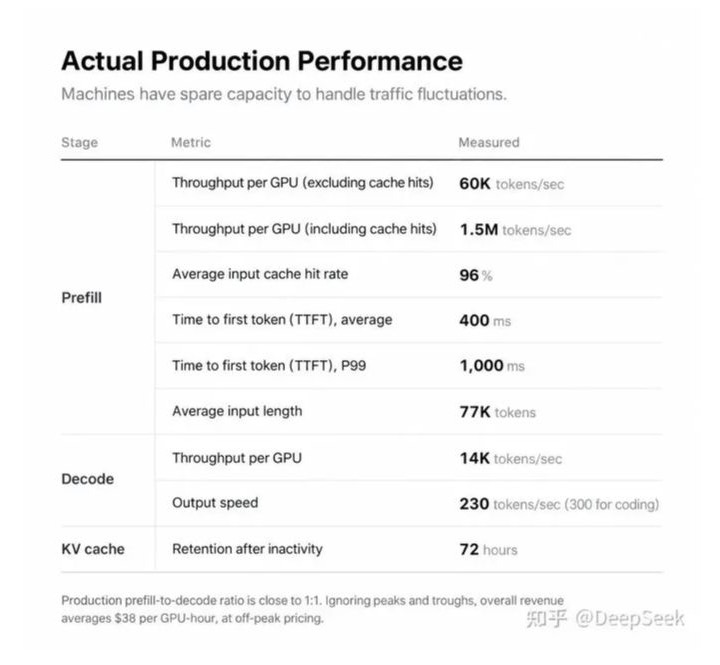
deepseek's production numbers are kinda wild:
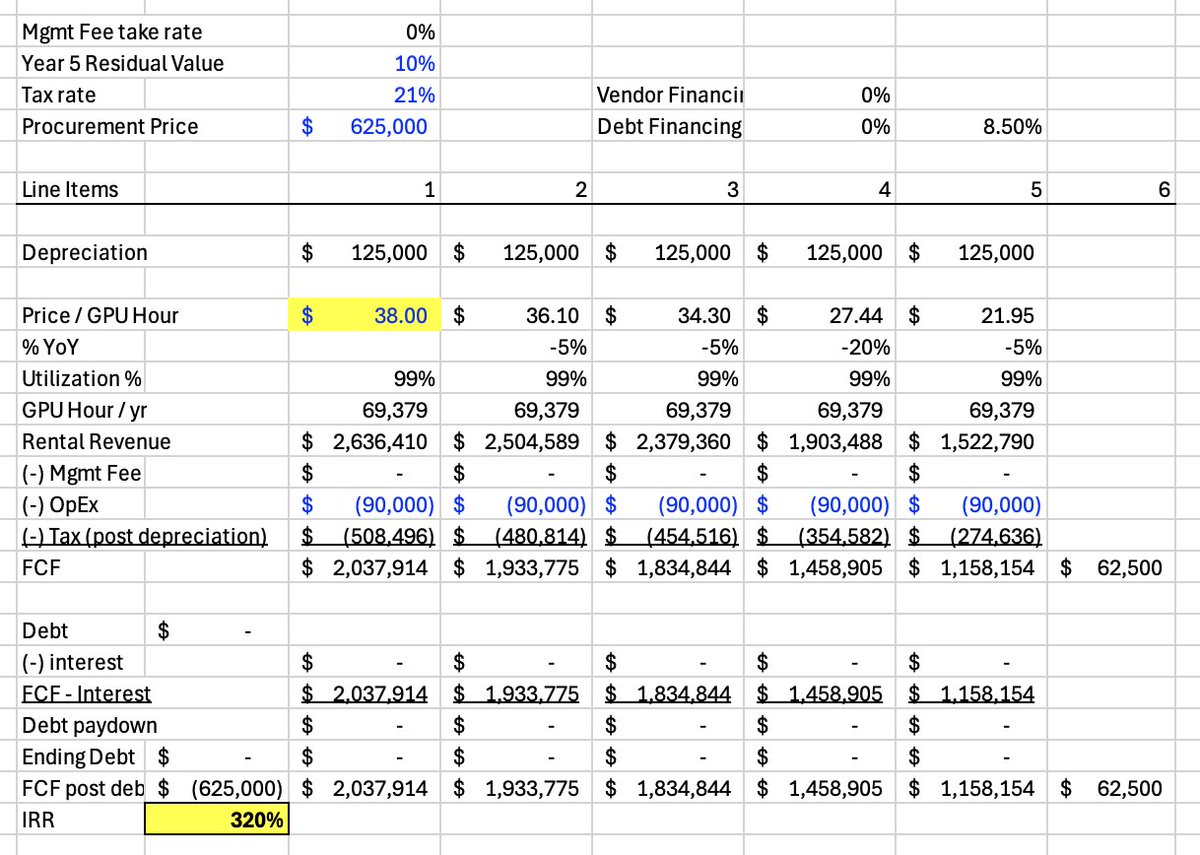
155T tokens/day from one cluster (96% input cache hits) and $38 revenue/GPU-hour at off-peak prices.
at $5–8/GPU-hour, that’s ~80% margin on GPU costs alone. at DeepSeek prices!!
we dug into the math, their 72-hour cache, and what actually got open sourced in today's AINews:
https://t.co/NcwbxbaqGn