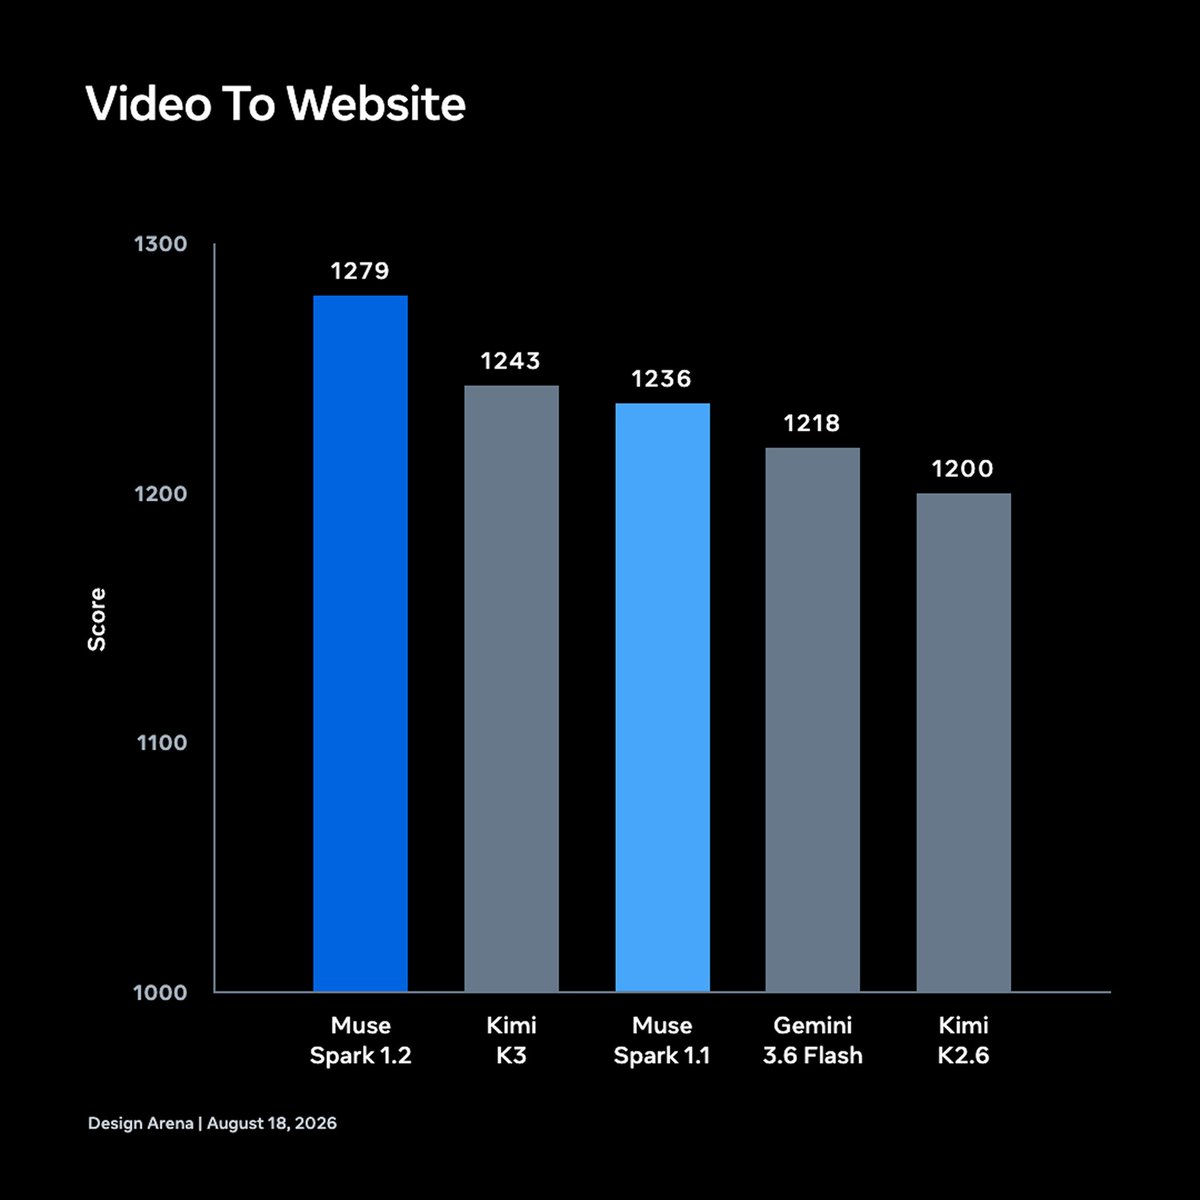
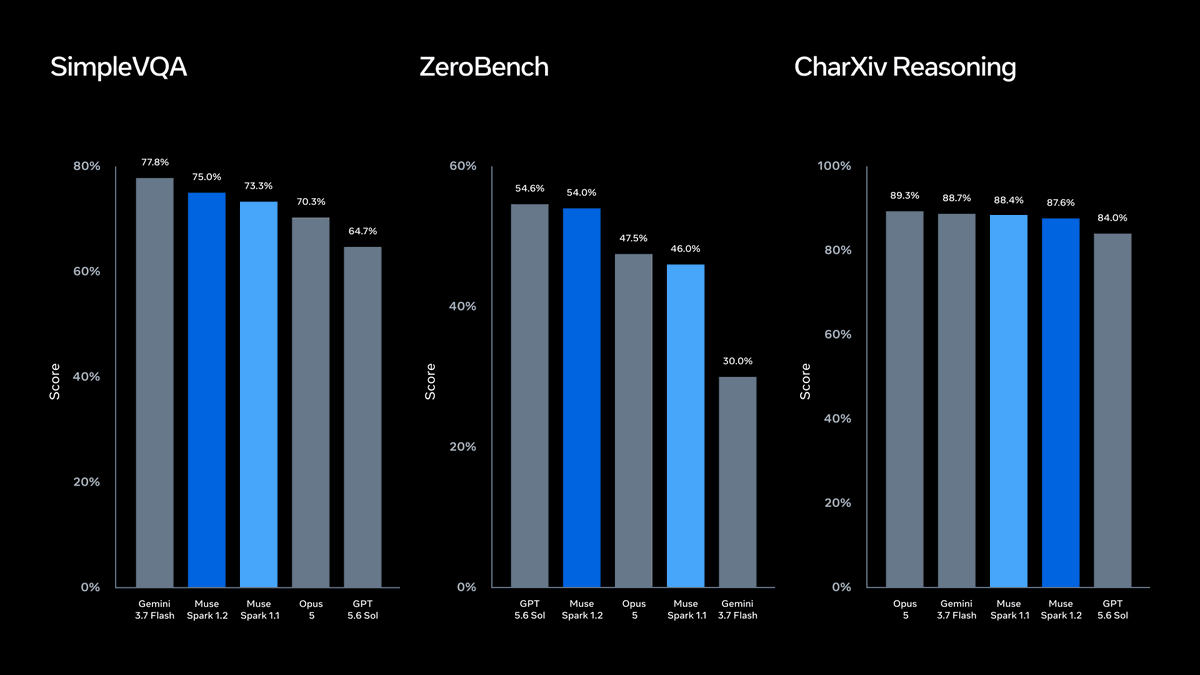
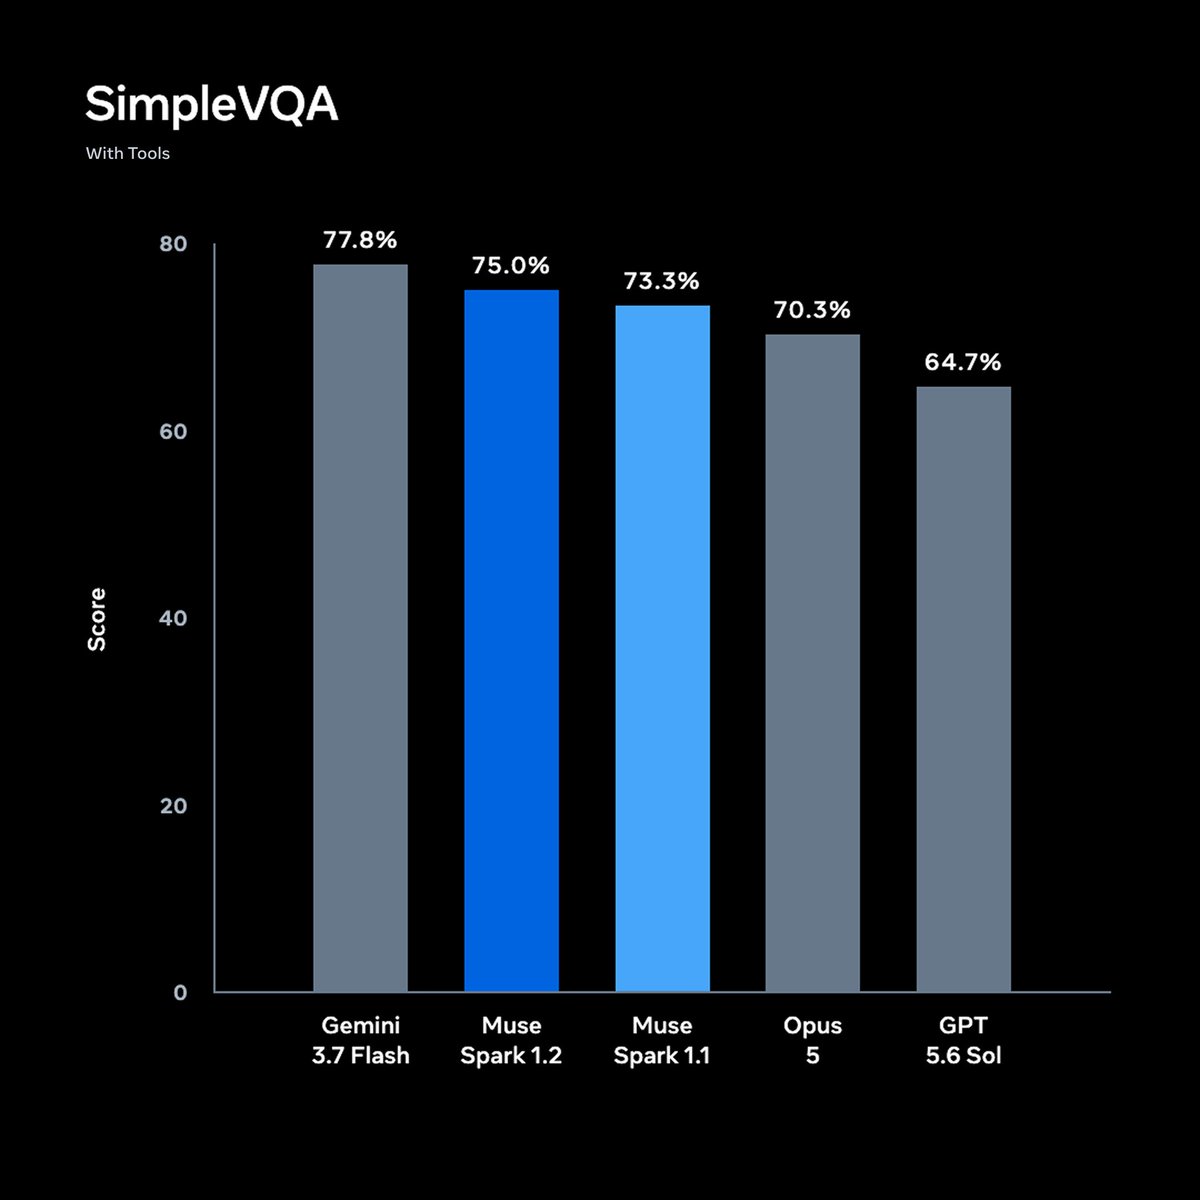
1/ muse spark open is the most capable US open-weight model to date.
816B total params, 42B active. 1M-token context. natively multimodal. built for coding and agentic work like long-horizon tasks, hard software engineering, multi-step reasoning.
america! 🇺🇲
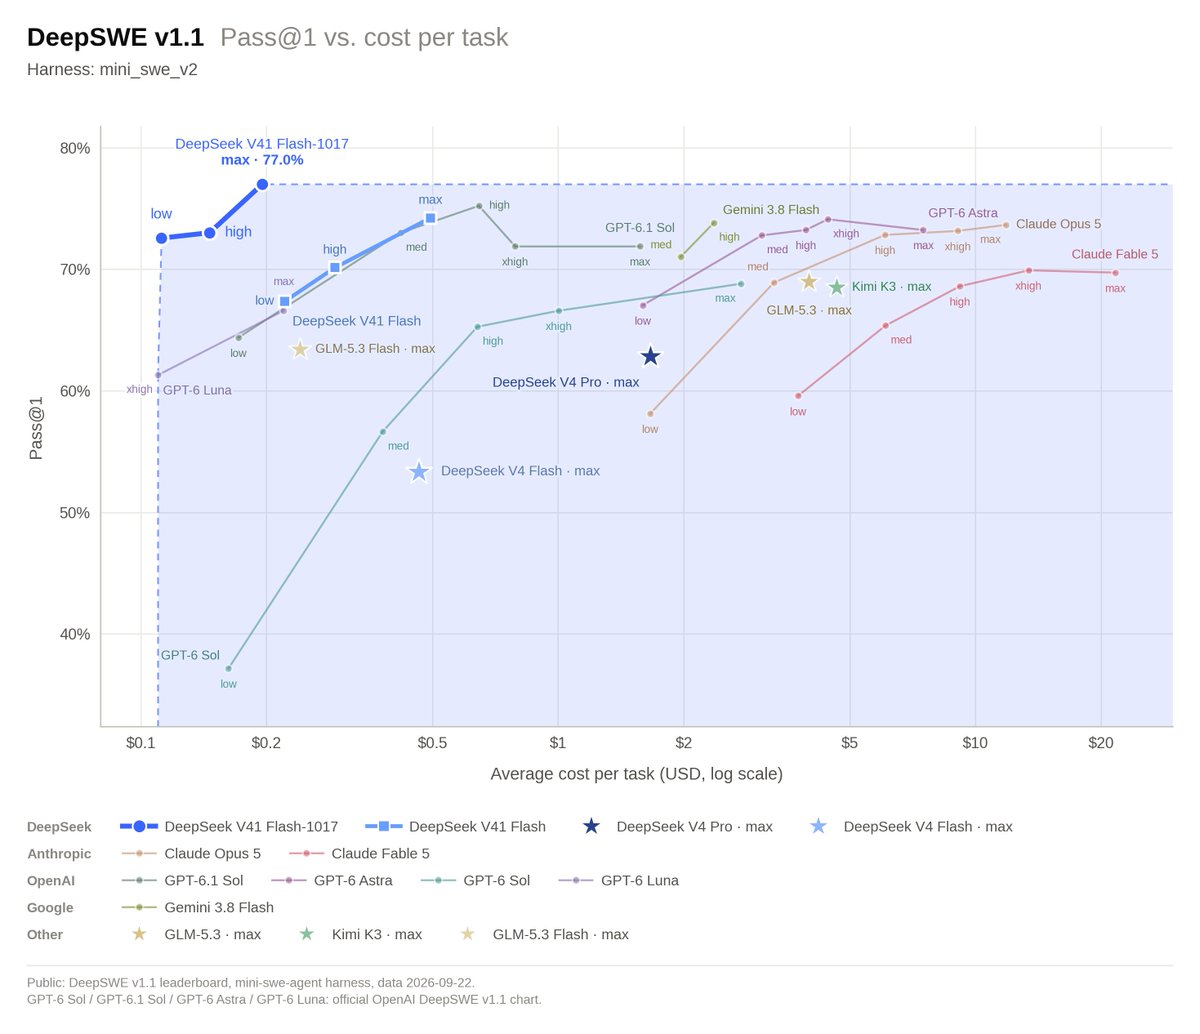
🚀 DeepSeek-V4.1-Flash-1017 is here!
Stronger benchmark performance, faster task completion, and shorter outputs than the previous version—a Pareto improvement in performance and cost. Now live on our website, app, and API.
🛠️ Optimized for @DeepSeekHarness, Tencent CodeBuddy, WorkBuddy, and more. Upgrade to DeepSeek Harness v0.2.1-rc.1 or later for the best experience with the new model.
1/4
Meet Mistral Large 4, aka Le Chonk.
• 1T parameters, natively multimodal. 49B active.
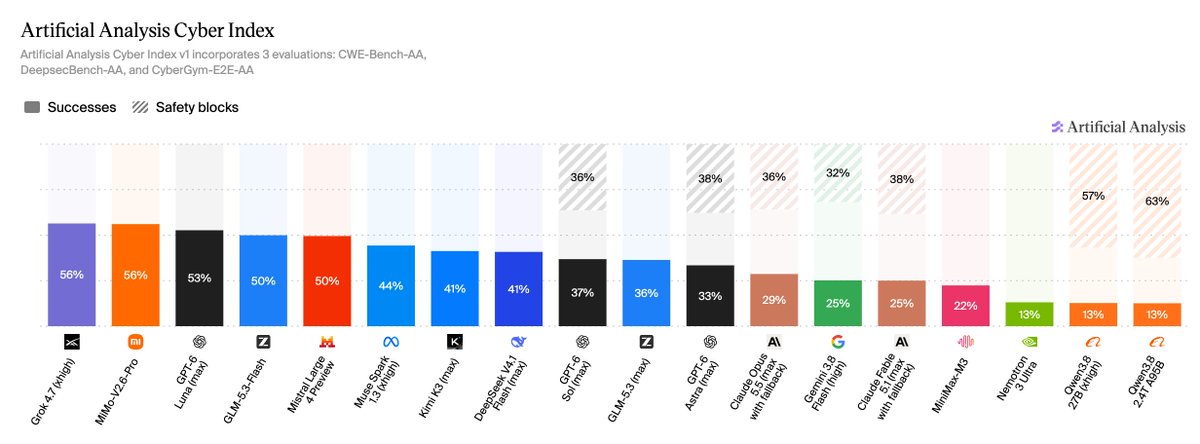
It is the best open weights model from US or Europe on aggregated benchmarks.
• State-of-the-art on critical workloads, including cyber defense, manufacturing and finance and it surpasses closed frontier models on visual grounding.
• Forged in Europe end-to-end and is deployable from Europe via our own Mistral Cloud infrastructure.
• Available to all via API today. Working with cybersecurity partners privately.
Open weights release end of October.
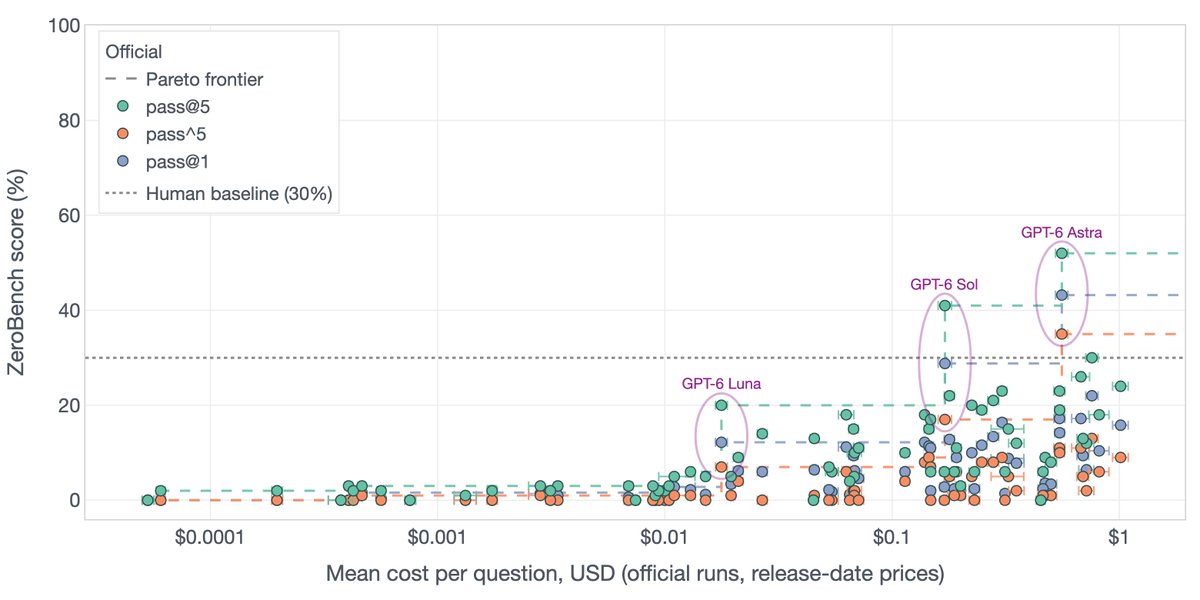
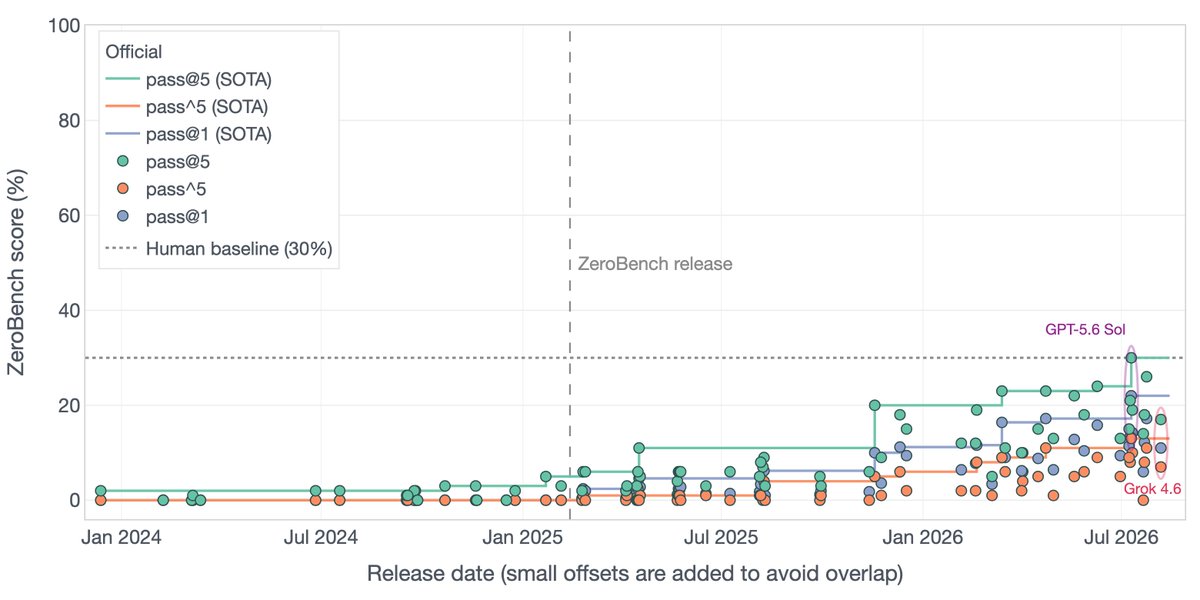
All three GPT-6 models sit on the ZeroBench performance-cost pareto frontier
pass@5 | pass^5
GPT-6 Astra (max)
51% | 35%
GPT-6 Sol (max)
41% | 17%
GPT-6 Luna (max)
20% | 7%
@Aging_Scientist The "if" is cautionary because the jump is so large. Given the benchmark is only softly gated, optimisation/benchmaxxing is possible. Qualitatively the responses do look genuine though
GPT-6 Astra (max) on ZeroBench:
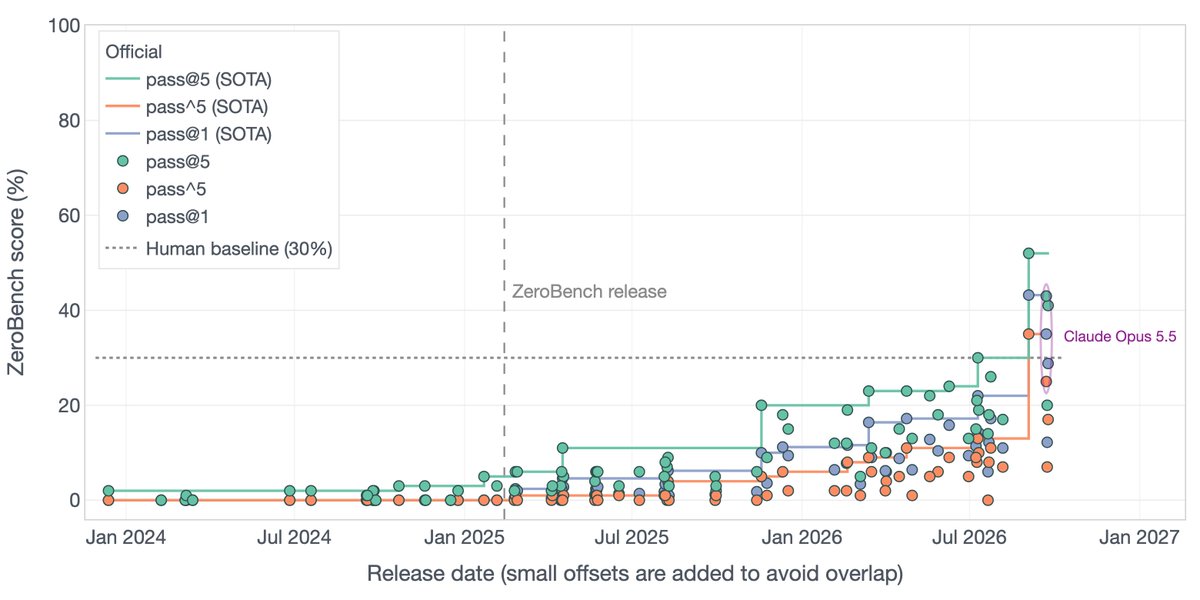
pass@5: 51% (prev. SOTA: 30%)
pass^5: 35% (prev. SOTA: 13%)
If this reflects a genuine capability improvement, it is a significant step forward in both performance and consistency
Grok 4.6 (xhigh) on ZeroBench (no tool use):
pass@5 / pass^5
Grok 4.6: 17% / 7%
GPT-5.6 Sol (SOTA): 30% / 13%
More evaluation details available on the project page