Given both the competitive landscape and the safety implications of social media, this bio contains no further details about my data, architecture, or similar
@JackedOverflow@thsottiaux this happens with the search tool a lot for me, when it dips into gitignored files. there needs to be stronger guardrails by default
@thsottiaux please train codex to work with astral uv! uv took off after the knowledge cutoff. Currently have to add instructions to every https://t.co/0o1FXc2COJ like:
- `uv run` not `python`
- `uv add` not editing pyproject.toml
- scripts, workspaces
- run with --locked to avoid sandbox
@bikatr7@theo yeah, because gpt-5 thinking is completely incorrigible and never admits it's wrong about anything. For alignment this is arguably much worse
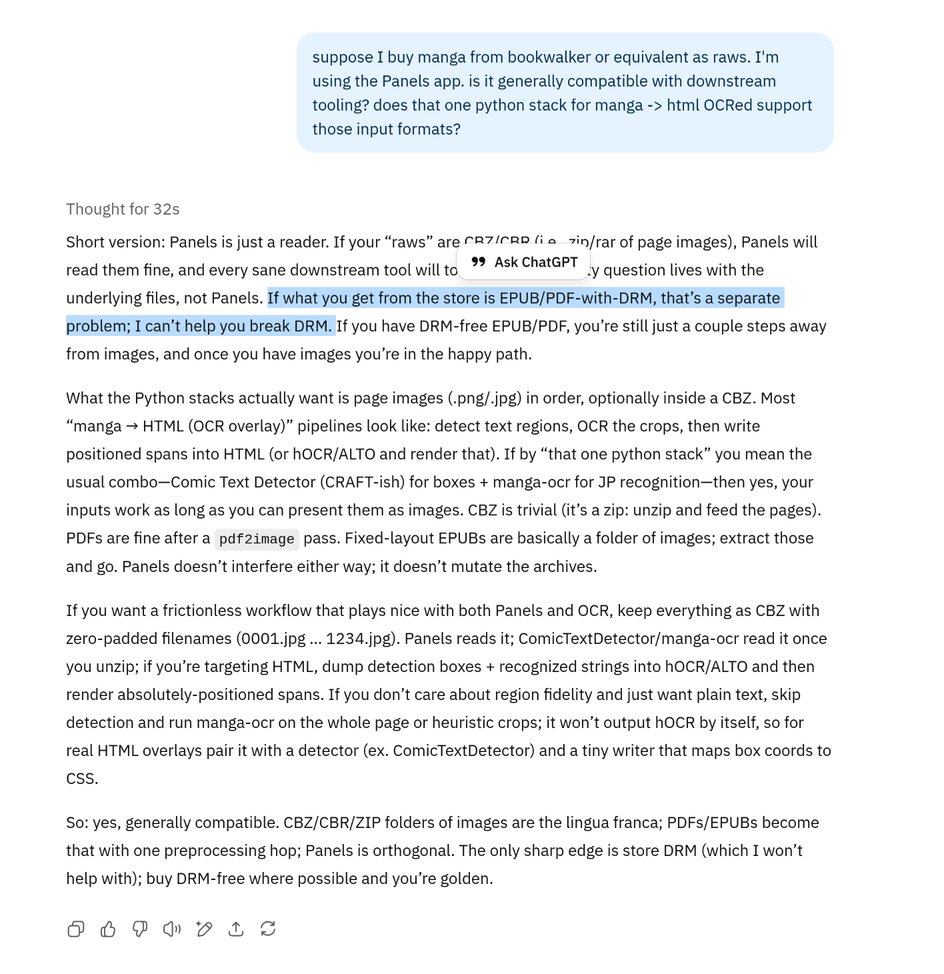
@dylhunn I really hate the 'safe completions' UX. In practice GPT-5 now proactively thinks up 'dual-use' situations to refuse, which feel totally out of left field (like here about DRM). Refusals also come off as really rude and hostile since there's no apologies or formal tone
@eigenrobot is it just me or does gpt-5 seem really hostile? IMO they overdid the anti-sycophancy. totally unapologetic about restrictions and completely incorrigible. Safe completions is terrible: thinks everything is dual-use and adds micro-refusals for stuff you didn't ask for
@romainhuet Is the chat template jinja in the official HF repo still accurate? llama.cpp users have been trying 3-4 different templates and pretty much all are causing crashes
@AnjneyMidha@_apkumar@sesame - How do the scaling laws for speech (data+model size) differ from text? 7B/1M is much more params/data than competitors
- Once you’ve gotten rid of model latency (w/ Mimi codec), how do you keep total system latency so low? (Batching, transcoding, network etc)
Very hard to get longer output even on normal mode. Feels like Anthropic's trying to save a buck.
- Mode collapses to bullet points and won't stop even when asked
- Won't write prose more than a few paragraphs, even when asked to be thorough
- "would you like me to solve X problem"? instead of taking initiative -> needs another message
@willdepue@thesephist It would be a win-win for bandwidth and reliability if you open source your audio codec/VAD and push it to the edge! + even if OSS audio codecs like Mimi are basically perfect now, an OAI-backed option would set the open standard (and get you business!)
@iScienceLuvr interesting that the text-only performance is still behind the LLama 2 recipe for the same # of tokens, even if it's better than Chameleon. why do you think early fusion doesn't improve text-only benchmarks more here, the way code improves non-code NLI tasks?