Pinning a thread of my Twitter highlights, starting with my very recent work on @FortniteGame, redoing their gyro controls and adding flick stick. This has been a hugely rewarding experience!
...🧵
https://t.co/6XFwEf81QG
We've added new and improved gyro controls along with flick stick on the platforms that support it.
Made in collaboration with input specialist and flick stick creator @JibbSmart, check out the video for all of the details of what's new!
More info: https://t.co/pffo2pb9vG
How Fortnite's "tweak zone" gives you more aim control, no matter how big a dead zone your controller needs 🎮🎯
(And why if you have a non-standard controller with built-in dead zones, you should disable them if you can)
How Fortnite's "tweak zone" gives you more aim control, no matter how big a dead zone your controller needs 🎮🎯
(And why if you have a non-standard controller with built-in dead zones, you should disable them if you can)
@Keento_xyz The game does not move the crosshair automatically. As I said in the video, ALL of the crosshair movement is up to the player. It's 100% decided by what the player does with the stick.
Because being able to train the AI yourself will be cool and all, but you don't want to train the same AI that your competitors are using.
Training the cloud is an un-feature for some.
LLMs approximate a lot of the AI fantasy by being good at words and using that to approximate reasoning and seem smart.
But a lot of the fantasy is on-the-spot improvement and learning. Will be interesting to see when and how they get there -- especially local-only learning...
inb4 LLMs get trained to play chess so that companies can say "our model is so smart it's good at chess"
...which would be besides the point. People want AI that can in-the-wild learn to be good at things by practice.
So this test measuring *improvement* is great.
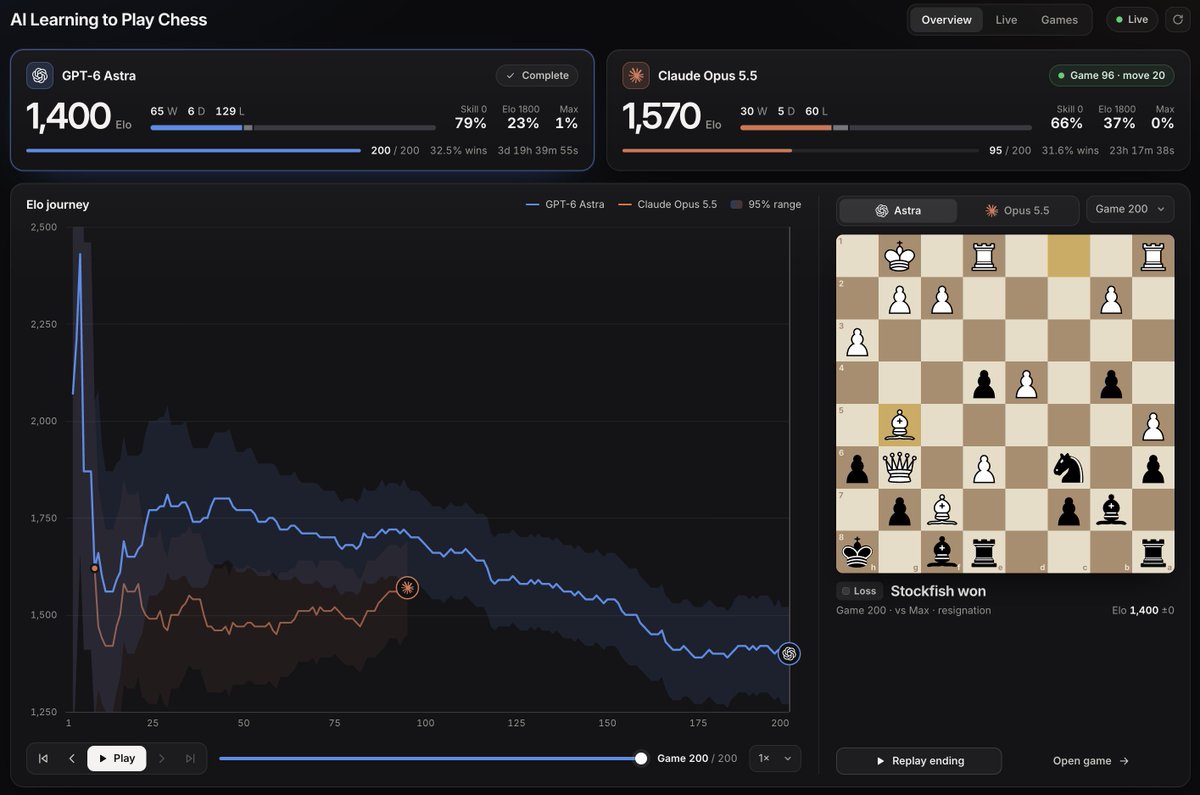
I have a Continuous Learning benchmark where models attempt to learn to play chess. They are given a /goal of learning and improving playing against a Stockfish opponent in 200 games. They can choose the difficulty, take notes, whatever they like - except cheating (e.g. using a chess engine) of course.
So far the improvement in Elo has been negative for Astra. Tiny bit positive for Opus, but could also be random. I've started Astra off sooner, so it finished its 200 games already, Opus is still playing.
Site here to watch how they are doing: https://t.co/voMG7th5MS
The reason why this is interesting is that while we obviously don't have continuous learning, at the back of my mind I was thinking that maybe models can simulate it through self-scaffolding. Turns out not so much at least in this context. Perhaps it's a solvable problem and we don't need 'true' self-learning for models to learn in some way.
-------
Just a note, the idea for the benchmarks belongs to someone else, but I don't want to use their name to give this more weight without permission.
@EliteBlayze It doesn't reduce aim assist at all.
If you're learning something different you'll often be worse for a bit before you become better. Some folks pick it up more quickly, but it's okay to prefer what you're used to :)
@ATD_GGs@ShipStreaming Yep :) You can see the effect your anti-deadzone is having by checking out something like Gamepad Tester in your browser. The point of tweak zone is to make use of every tiny stick movement, but it can't do that if the controller hides those movements:
https://t.co/Z8mXzSf9xR