🎙️ Excited to introduce one of my favorite projects from the past year: TeleDexter, from the BIGAI dexterity team.
It’s a stable, human-level dexterous teleoperation system and a suite of autonomous policies trained with it. Pen spinning, complex in-hand reorientation, and long-horizon tool use—once seen as the holy grail of manipulation—are now unlocked. 🧵👇
The hardware is already here; we have some incredible high-DoF robotic hands. The bottleneck? The controller. Most current systems are stuck in "quasi-static" grasping mode. Meanwhile, dynamic in-hand dexterity has remained severely limited.
🧠 To unlock the massive capabilities of human-like hands, we need to build an excellent "cerebellum" for dexterous hands. TeleDexter solves this with a novel co-tracking approach: it simultaneously tracks both human hand kinematics and object states, beautifully bridging the gap between human intent and robotic control.
In order to train a better co-tracking policy that works robustly in the real world, we designed : (1) a hybrid reward design that combines consecutive goal reaching and dense tracking, (2) an action masking strategy during training that enhances sim2real performance, (3) a dexterous curriculum for learning the long-horizon interactions. Each design is inspired by numerous trials and countless real-world experiments.
We’ve synthesized all the system details, engineering challenges, and core insights into our latest post.
If you're interested in the future of dexterous manipulation, grab a coffee and check it out (9-min read): https://t.co/NWzBZ7hnE2
If you have more time, check out the paper: https://t.co/vEcbwNPdLb
Presenting PTLD: an approach to learning tactile dexterous policies without ever simulating the tactile sensor.
Tactile is essential for performing highly dexterous manipulation. However, collecting tactile observations reliably has been a fundamental bottleneck: (1) teleoperating a multi fingered hand for dynamic tasks is challenging, making sim-to-real imperative, (2) one can’t realistically simulate tactile today
TopoRetarget enables a dexterous manipulation RL mimic pipeline from human demonstrations to real-world robot execution.
With TopoRetarget + RL tracking, we achieve zero-shot sim-to-real pen spinning on the Wuji Hand.🎉🎉🎉
We collect human hand-object motion with Wuji Glove, retarget the human demonstration to wuji hand while preserving hand-object interaction information, and train a RL policy to track the resulting hand-object reference.
Paper: https://t.co/e9TrpkFMpd
Project page: https://t.co/U0KncaOIaR
Autoresearch just left the sandbox and entered the embodied world.
We are excited to introduce 𝐄𝐍𝐏𝐈𝐑𝐄: a system that drops frontier coding agents onto a fleet of real robots and hands them the entire loop:
reset the environment → search the literature → implement ideas and build the infra → train and deploy → self-verify → analyze the logs and rewrite the code → repeat, until the policy is reliable in the real world. No human in the loop.
Guided only by the robot's self-proposed, heuristic-based success signal, the agents hill-climb to 99% on dexterous real-world tasks: organizing pins into a box, seating GPUs, tying zip-ties.
We envision the bottleneck in robotics shifting — from building smarter algorithms to building the closed physical feedback loops an agent can finally turn on its own.
🔗 https://t.co/3tL2ArGo3v
From @NVIDIA@CMU_Robotics@Berkeley_AI
🧵
Humanoid robots don't need to look human.
Meet Eno, our first general-purpose robot.
Not a machine pretending to be human, but intelligence given a body.
At Genesis, we’re building a future where robots don’t feel cold or distant, but capable, calm, and ready to help.
Available Q4 this year.
🪜 What if humanoids could climb ladders and work on them straight out of simulation?
Meet LadderMan: a perceptive system for zero-shot sim-to-real ladder climbing and on-ladder manipulation.
Watch the humanoid climb, stabilize, and manipulate—all in one system. 🤖👇
Arxiv: https://t.co/ogFiI055hE
Website: https://t.co/5b2hvutdhL
Try out our toy demo on the website!
Shout out to our amazing team: @Haoran727, Aditya Nisal, Rahul Kumar, Guofei Chen, @taochenshh, @QinYuzhe , @GuanyaShi.
From a single demonstration, can a robot learn robust, dynamic bimanual manipulation?
We introduce 🧬𝗣𝗚𝗗𝗚, a curation-guided data generation framework that expands one demo into a compact dataset that enables robust BC policy learning.
website: https://t.co/Qa1mCp1ImI
🧵1/6
We also highlight some moments we are excited to see: 1) Recovery behavior: policy naturally learns how to recover from a failure state.
2) Continuous flipping (16x speed up), no cut.
All from a single demonstration.
🧵6/6
SONIC is now open-source!
Generalist whole-body teleoperation for EVERYONE!
Our team has long been building comprehensive pipelines for whole-body control, kinematic planner, and teleoperation, and they will all be shared.
This will be a continuous update; inference code + model already there, training code and gr00t integration coming soon!
Code: https://t.co/7u3SBxzXU9
Docs: https://t.co/HpDLkTCSMF
Site: https://t.co/D3i4KlnLLr
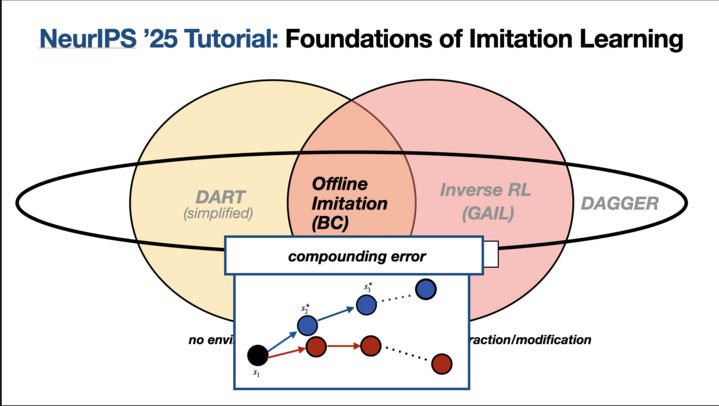
🧐🧐 Why do we pretrain LLMs with log likelihood? Why does action chunking work so well in robotics? Why is EMA so ubiquitous? And could their be a mathematical basis for Moravec’s paradox? 🤖🤖
Come check out our NeurIPS 2025 Tutorial “Foundations of Imitation Learning” with @canondetortugas and Adam Block, Tuesday 130-4pm, to find out! (🧵for details)
We just released results for our newest VLA from Physical Intelligence: π*0.6. This one is trained with RL, and it makes it quite a bit better: often doubles throughput, enables real-world tasks like folding real laundry and making espresso drinks at the office.
🕸️ Introducing SPIDER — Scalable Physics-Informed Dexterous Retargeting!
A dynamically feasible, cross-embodiment retargeting framework for BOTH humanoids 🤖 and dexterous hands ✋.
From human motion → sim → real robots, at scale.
🔗 Website: https://t.co/ieZfG2Q4L0
🧵 1/n
It’s been an exciting journey to see this come to life: BFM-Zero🤖 A behavioral foundation model capable of zero-shot goal reaching, tracking, and reward optimization — all from a single latent space. Check out Yitang's post for more details!
Meet BFM-Zero: A Promptable Humanoid Behavioral Foundation Model w/ Unsupervised RL👉 https://t.co/3VdyRWgOqb
🧩ONE latent space for ALL tasks
⚡Zero-shot goal reaching, tracking, and reward optimization (any reward at test time), from ONE policy
🤖Natural recovery & transition
Meet BFM-Zero: A Promptable Humanoid Behavioral Foundation Model w/ Unsupervised RL👉 https://t.co/3VdyRWgOqb
🧩ONE latent space for ALL tasks
⚡Zero-shot goal reaching, tracking, and reward optimization (any reward at test time), from ONE policy
🤖Natural recovery & transition