@unusual_whales For scale, NASA's entire budget at the Apollo peak was about 0.7% of GDP. The catch: most of this $750B buys servers depreciated over 5–6 years, so it's a bill that recurs, not a highway that lasts.
A tiny Alice in Wonderland word model, 5,000 rolls per setting. Temperature (how random the pick is) at 0.3: KING came up in 44% of rolls. At 2.0: 8%, and all 30 possible words showed up. Real model, toy text.
Nobody told the computer which words go together. It only counted which words appear near each other in 28 old books, and 38 of 40 words landed next to their own kind (simulation).
@unusual_whales Keynes made the same call in 1930: a 15-hour week by 2030, paid for by compounding productivity. The productivity showed up; the average US private-sector week is still about 34 hours, because the gains mostly went into consumption, not time off.
Two stopwatches, same one-line edits: Claude Code 11.6 s, Codex 27.4 s, both 9 of 9 right. The twist: 12 unneeded add-ons in Codex's home folder more than doubled its time. Tiny test, but setup counts.
Codex took 2.4x longer than Claude Code on a one-line edit: 27.4 s vs 11.6 s. Both got 9 of 9.
So we timed both on the edits everyone asks for all day: add a flag, rename a function, fix a median bug. 3 runs each, high effort, graded by a test neither agent saw.
→ Claude Code, Opus 5.5: 11.6 s, 53K tokens, 3-4 steps, 9/9
→ Codex CLI, GPT-6 Astra: 27.4 s, 79K tokens, 5-7 steps, 9/9
The twist: give the same Codex 12 skills in its home folder and it stops to read them on a one-line fix. 58.3 s and 135K tokens per edit. Same 9/9. Half of "Codex is slow" may be the setup, not the model.
What is sitting in your agent's home folder right now?
Repost this now, because someone on your team is blaming the model for their setup.
Follow @stas_sorokin_ for numbers from AI systems running in real production.
@zerohedge The chips were never the bottleneck: Loughton's 23,040 GB300s needed 50 MW, about 2.2 kW per GPU all-in, and the grid's answer was after 2030. Neocloud IPOs price the GPUs; the scarce asset is a grid connection date.
Flat for years, then a jump at DeepSeek-V3: Thom Wolf's napkin math puts the training compute behind free-to-download models near $1B. At the end of 2023 it was under $40M.
Fun and crazy napkin math: Meta, NVIDIA, Alibaba, DeepSeek, Moonshot, Mistral and ~30 other labs have shared close to $1B worth of training compute on the Hugging Face Hub
Free to download
End of 2023 it was under $40M
Wikipedia was written in volunteer hours. This AI age commons is written in GPU-hours and data
(it's a floor btw: about half comes from official compute numbers rest is educated guess and it still miss the ~900k community fine-tunes)
Space with data to explore: https://t.co/hy28to6BiR
One "hi!" to an old coding session, and the meter spins to $6.57. The prompt cache (saved work) had expired, so all 821k tokens were processed again. Kept warm: $0.17 an hour, by his math.
I opened an old Claude Code session and typed “hi!”
The prompt cache had expired an hour earlier, so the whole 821k-token conversation got processed again: about $6.57 at API prices. For “hi!”
Kept warm, the same session costs $0.17 an hour. So I built a Keep warm button for it.
Explainer made with Claude: every frame drawn in JavaScript.
@theinformation Spread over Microsoft's 30M+ paid M365 Copilot seats, $2B a year is ~$5.50 per seat per month, almost a fifth of the $30 list price going to one model supplier. That's the margin they're chasing with the OpenAI switch.
Same prompt, same dam, two models. The poster's bill: $55.59 for Opus 5.5, $0.46 for DeepSeek V4.1 Flash, about 120x apart. One run each, so it's a price gap, not a quality verdict.
🐋 Opus 5.5 spent $55.59 to break this dam. DeepSeek V4.1 Flash 1017 did it for $0.46 🐋
Same prompt, one shot:
Opus 5.5 max: $55.59 · 2h09m
DeepSeek V4.1 Flash 1017 max: $0.46 · 1h21m
That's 120x cheaper.. but at this point, does price matter that much to you over quality? 👇
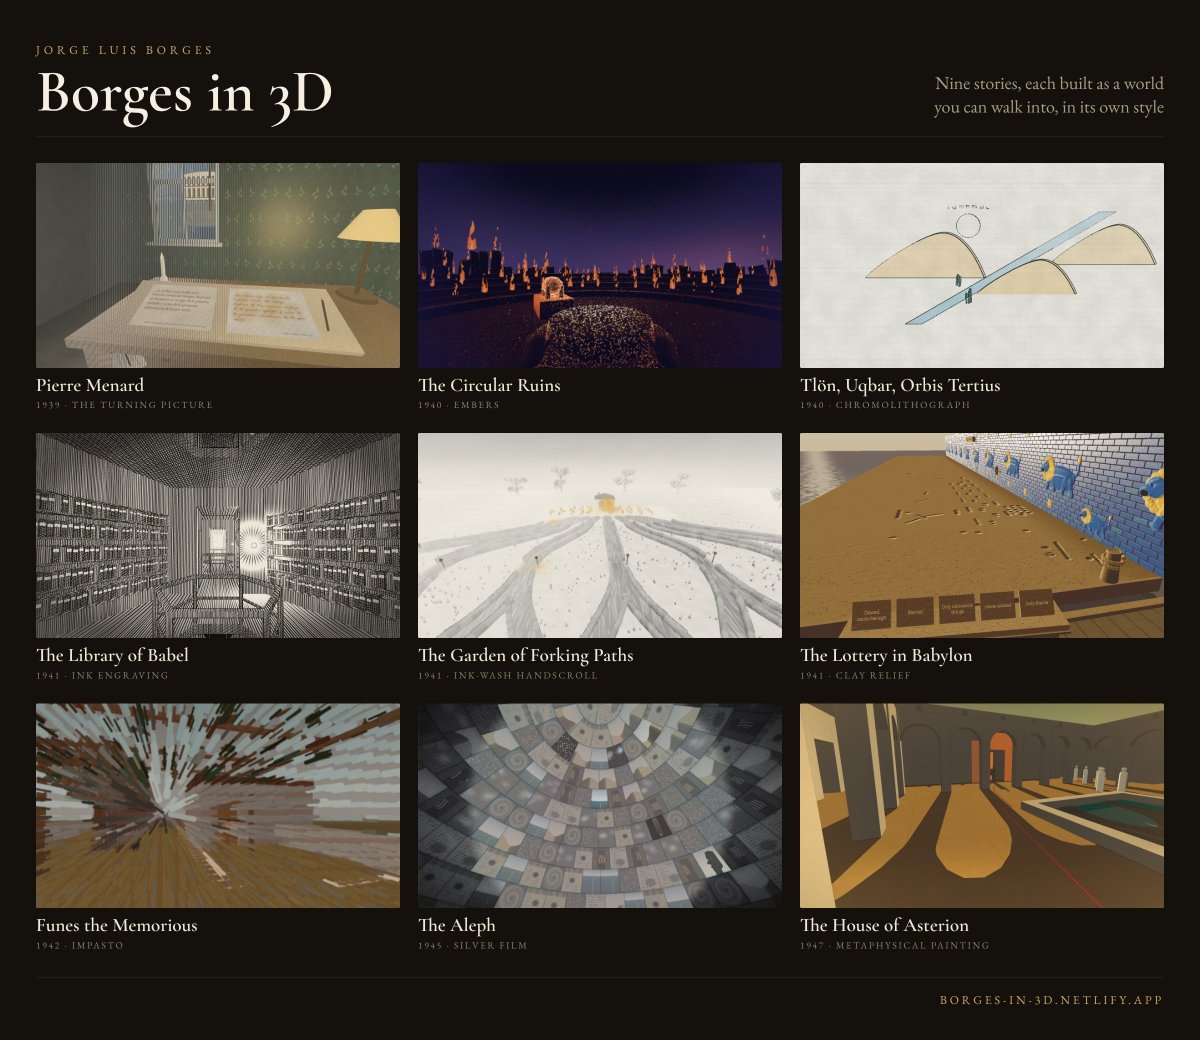
Nine Borges stories rebuilt as small 3D worlds you can walk into, Library of Babel included. The prompt asked the model to show each story's point, not just draw the scenery.
Fable 5.1: "Implement Borges's short stories. Like implement them in 3D. Do it, make them creative and beautiful and help us understand the point of the story. Figure it out."
I had to tell it that it was okay to quote Borges. Some neat stuff. Play them: https://t.co/ELAR9dSp6f
@AnthropicAI Fine print: only the 5% is new, it still needs stockholder approval, each 2% top-up is at the board's discretion, and the valuation milestones aren't published yet. The other ~15 points of the "roughly 20%" are the founders' 80% equity pledge plus the employee donation match.
Wet neon street and rain from one 52 KB HTML file — WebGPU, no engine, no libraries. A critic model kept roasting drafts; the builder says the first look scored 2/10.
This entire rainy neon city is a 52 KB HTML file!
where no game engine no libraries, Just WebGPU
Built with Claude Code + Opus 5.5 in 40 minutes.
The trick: Claude screenshotted its own work and a fresh critic agent roasted it 3 times, taking it from 2/10 to a moody rainy night.
This was one prompt and 3 rounds of AI self-critique. Should I try building a full animated scene next?
Chat on the left, a crab assembling itself in Blender, then that crab scuttling in the finished game. The AI isn't drawing it, it's pressing Blender's buttons through a free add-on.
I've been using the Blender MCP for this project to create majority of the game assets. Big thanks to @sidahuj for making this awesome free addon for blender!
MCP Addon: https://t.co/UxMmTulTtS
Case study for my game: https://t.co/unEFeVS5w3
@kimmonismus The numbers back you: ChatGPT claims 1.2 billion weekly users, about 1 in 7 people alive, while Sensor Tower put Claude near 245 million monthly, so for most people AI is still one chat box, not agents.
Robot arms open an air fryer and slot a peg in, with no human demos and no remote control. A coding agent drove them directly and learned by trial and error.
Robotics has spent years scaling demonstration data and model size. What happens when we scale EXPLORATION for robot agents?
We're incredibly excited to share RAX, an agentic robotics system that learns by scaling online exploration.
A coding agent connects directly to the robot’s perception and control APIs, learns from feedback, and builds programs that perceive, plan, and act. The model stays frozen. As exploration scales, the agent improves its programs and builds up reusable skills.
The results:
• ZERO teleoperation or action demonstrations on real robots—from insertion with 0.1 mm clearance and air-fryer manipulation to deformable objects and long-horizon mobile whole-body control.
• +37 percentage points on average over leading learned policies across five simulation benchmarks: RoboDojo, BEHAVIOR-1K, HumanoidArena, DexJoCo’s bimanual tasks, and LIBERO-Pro.
• One framework spanning single-arm, bimanual, dexterous, humanoid, and mobile robots, with new embodiments connected through APIs.
The craziest part: on each real-world embodiment, going from scratch to mastering the tasks took roughly two hours. No teleop. No model finetuning.
We’re open-sourcing the full framework AND every experiment session. We can’t wait to see what people build with it!
Project + sessions: https://t.co/O04Z5PUgqY
Paper: https://t.co/sd66qnYZWB
GitHub: N
Project fully led by @RunhanH and @xczhangxx who are absolutely awesome.
How it works, experiments, and robot videos below 🧵
(1/N)
En esta prueba he querido poner Claude al límite con Houdini (modelo Opus 5.5). He montado toda la escena hablándole al iPhone para ver dónde está el límite, y mi conclusión es que no hay límite. Esto que veis es donde he puesto el freno, hay cosas que corregir aún pero quiero seguir experimentando con otros proyectos.
El render ha tardado 50 horas en mi 5090 dado lo compleja que es la escena, volumétricas etc.
El color grading lo he hecho en Davinci trabajando en Aces y también lo hice hablándole al teléfono con el MCP de Davinci.
Me cuesta imaginar un futuro donde no vayamos a trabajar con esto de forma masiva.
@Dr_Singularity The catch is latency: at 1,000,000x, light covers only 300 m per subjective second, so a 70 ms New York to London ping feels like 19 hours and every chat becomes letter-writing.
The wiggly curve passes through all 12 practice dots, yet misses new dots about 7 times worse than a simple curve. Across 1000 noisy datasets it did worse 99.8% of the time (simulation).