Your laptop is now the voice of your whole house.
Boubou turns open-source TTS models into local runtimes with one command. Your phone, robot or smart home on the same Wi-Fi just talks to it.
100% local. Built on @LiquidAI_ + @huggingface 🤗
https://t.co/5Z11jeBk4Z
Your laptop is now the voice of your whole house.
Boubou turns open-source TTS models into local runtimes with one command. Your phone, robot or smart home on the same Wi-Fi just talks to it.
100% local. Built on @LiquidAI_ + @huggingface 🤗
https://t.co/5Z11jeBk4Z
Thanks so much! 🙌 The small model helps, but a lot of it comes down to the setup. Latency on your phone is basically the same as on your laptop, since the phone just connects to the server running on your computer over WiFi. Japanese is already supported, and we'll be opening up more languages and models soon. Give it a try!
@jt_sidious Running Boubou on an M5 Max, audio starts ~100 ms after it knows you’re done talking. Most of the wait is the 0.6 s of silence it listens for before replying. Talk over it and it stops in about 0.15 s
LLMs have llama.cpp. Can speech models run locally the same way?
Yes. The weights and config can go into a GGUF file. The runtime builds a computation graph for the model, and GGML runs it on your CPU or GPU.
Much of the engineering carries over, including model support, quantization and validation. Streaming speech also needs to keep up with playback and stop when the user interrupts.
Good point, thanks for adding this. Phones can slow down as they heat up, so a fast first run doesn’t tell us whether TTS can keep up with playback over a longer session.
@Jinyu_Chai Good thread. On phones the gap problem gets worse because thermal throttling slows later chunks, so TTS that starts out real-time can fall behind after a few minutes. Worth testing sustained speed, not just the first run.
XDA: https://t.co/y2C0sZfg44
llama.cpp is expanding its speech support too. It already has a llama-tts tool, with examples for models like Qwen3-TTS 1.7B Base.
As speech models mature, they're finding their way into the same tools used to run LLMs locally.
For real-time speech, average speed isn't the whole story. If the next chunk isn't ready when the current one finishes playing, the user hears a gap.
Generating in chunks also means preserving the context and state the model and decoder need. Otherwise, chunks that sound fine on their own can sound disjointed when played together.
And when the user interrupts, canceling generation isn't enough. The player also needs to clear the audio still waiting in its queue.
I've always believed that intelligence should come from simple, general building blocks that learn their own abstractions directly from raw data; in other words, the bitter lesson. I think we're finally seeing a real step towards AI that can learn from all data.
Language modeling on raw bytes is a microcosm of this ideal, and to me it's a central problem in AI: if we can't build LLMs that learn end-to-end from bytes, how will we handle the rest of the world's data that we understand even less?
Last year we introduced hierarchical networks (H-Nets) as a first step. Our new version finds up to 3-5x efficiency gains in controlled scaling law experiments, and at larger scale matches an open-source model trained on 11T tokens with ~10x less data and compute. The posts below walk through what we found and why we think it works.
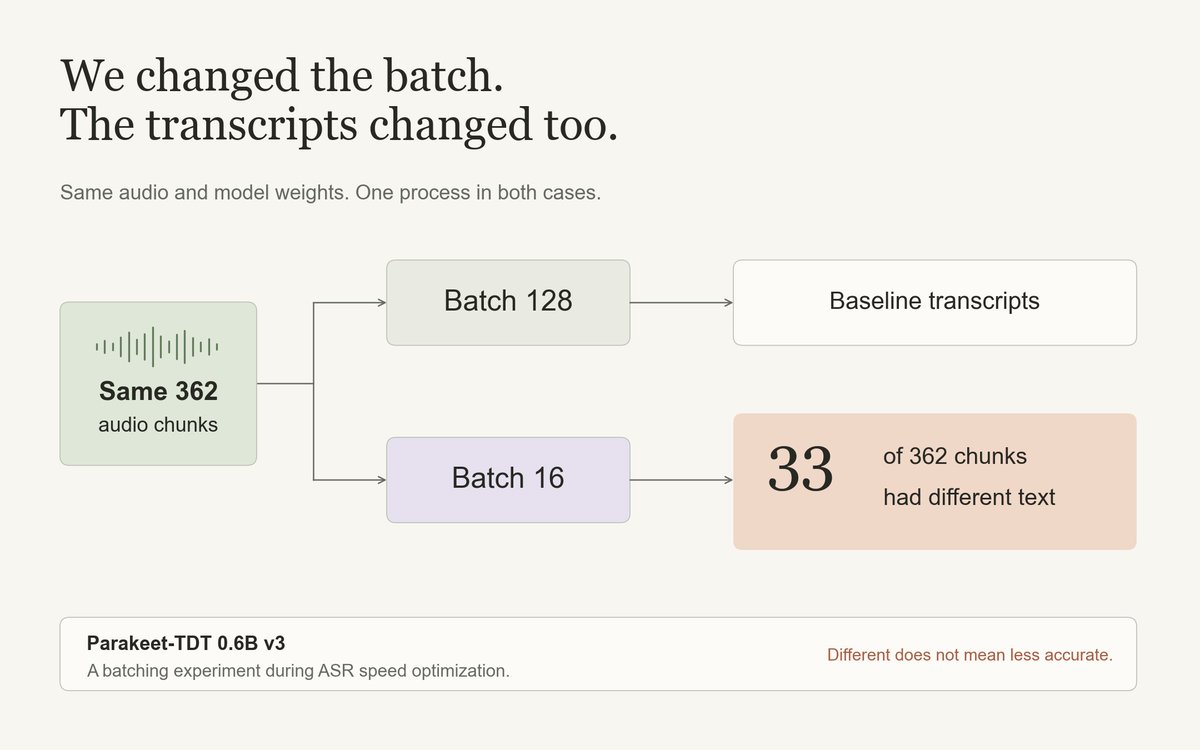
We tried to speed up ASR. Some transcripts changed.
Same audio. Same model. Reducing the batch size from 128 to 16 changed the text in 33 of 362 chunks.
We eventually made inference faster while keeping outputs unchanged. Here’s what worked.
We kept the original groups of up to 128 chunks, sped up CPU timestamp processing, and overlapped it with the next GPU batch.
On a separate set of 4,980 chunks, iinference time dropped from 86.00 to 73.06 seconds. Text, word timestamps and generated token counts all matched.