free Mimo 2.6 Pro at 320 tokens/sec
currently the best open weights model on the market
cheaper and 50% better than GPT Luna
only possible in partnership with @RunAnywhereAI
https://t.co/HlC3SrGOoI
introducing
═══════════ 𝚌𝚏𝚘.𝚊𝚒 ═════════════
tl;dr
1/ runway is now https://t.co/Uqg6xlaJIU
2/ you can hire @arithecfo and he can start TODAY
3/ you can give @arithecfo a test drive by replying to this thread with any ridiculous thing you want him to model for you, and he'll come back to you with a beautiful, detailed, fully wired financial model
... in 30 minutes or less
now, story time:
🧵 1/n
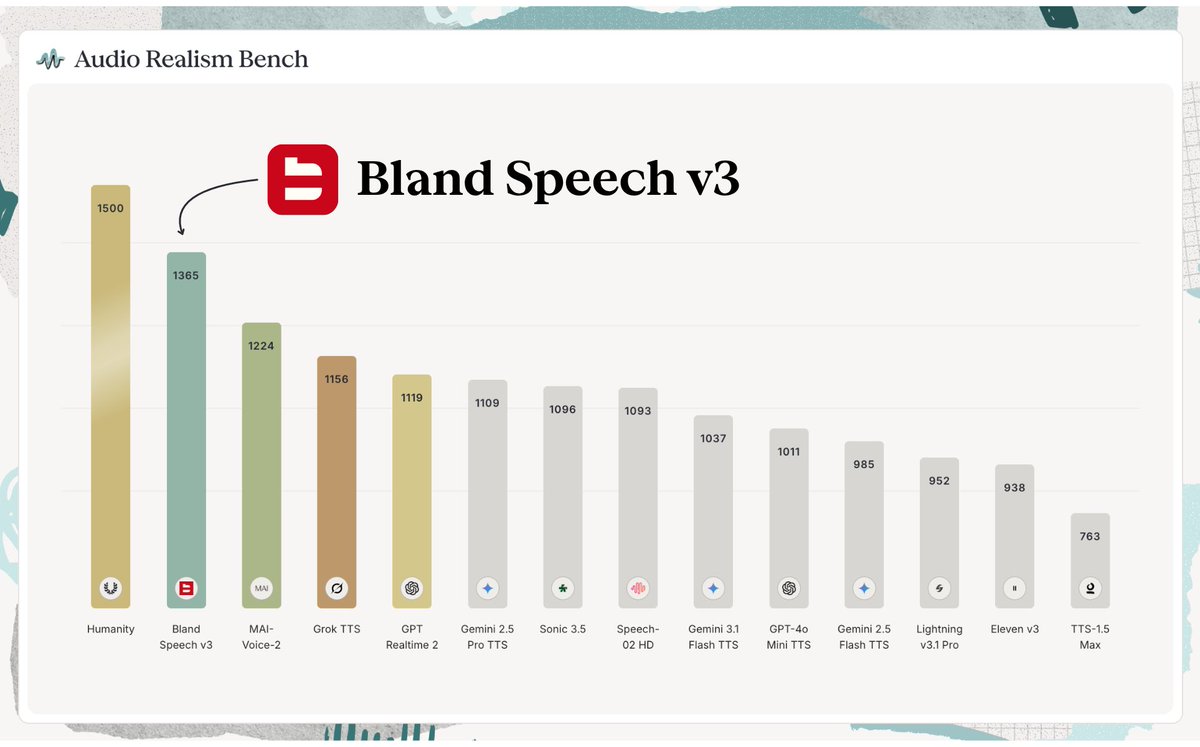
BREAKING: Bland Speech v3 by @usebland debuts as the most human-sounding TTS model on our newest evaluation: Audio Realism Bench.
Traditional speech benchmarks increasingly struggle to separate frontier systems that all sound clean, fluent, and intelligible.
Audio Realism Bench instead asks a harder question: when two voices read the same transcript, which one sounds more like a real person?
Vetted native speakers evaluate recordings blindly across phone agents, conversational assistants, and spoken explainers, judging the subtle qualities that define human-like speech.
We also place real human recordings directly into the evaluation pool, testing whether evaluators can distinguish TTS models from actual human speech.
Bland Speech v3 takes the top spot in our initial rankings, followed by MAI-Voice-2 by @MicrosoftAI and Grok TTS by @SpaceXAI, all demonstrating important steps toward voice systems capable of sustaining genuinely human-feeling interactions.
Congratulations to the @usebland team!
Bland is in New York!
We've raised over $100M to continue building the platform that handles your business's most valuable phone calls.
Thank you @Nasdaq for sharing us with the world & the great city of New York.
Our recent $100M Series C means we can continue training our models to handle the urgent, high-risk, 45-minute phone calls that matter most.
We brought Paul back to explain what this means and why he might be headed back to Costa Rica…
Today, we’re announcing that we’ve closed our Series C and raised $100M to continue automating the world’s most complex phone calls.
We grabbed some guy named Paul to talk about it because nobody else in the office wanted to. 🧵