Gemini Decision 1 on LLM Reference: Google's first decision model returns calibrated probabilities for up to 1,000 typed questions per request, with zero output tokens. $0.10 per 1M input tokens. https://t.co/uEECEqJBgD
Introducing Gemini Decision 1, our new frontier decision model in the Gemini API.
It is $0.10 per 1M input tokens with no additional cost. With support for image, audio, video, and PDF natively, 256K context window, & 1K questions.
You can try it for free in the API!
SWE-2 Flash, Cognition's fast, low-cost coding model for Devin: post-trained from Thinking Machines' Inkling-Small (276B total, 12B active). In Devin Desktop and CLI, released Nov 4.
https://t.co/ghok0d79da
Introducing SWE-2 Flash, our new fast & efficient coding model.
On leading evals, it outperforms all American open-weight models, even ones 3x larger.
To balance transparency and cyber risks, we are building a program to securely share the weights with partners & researchers.
LongCat-2.5, Meituan's natively multimodal agentic model: 1.6T total parameters, about 48B active, text and image input. Weights on Hugging Face under MIT since Nov 9.
https://t.co/mdLT9nkLKc
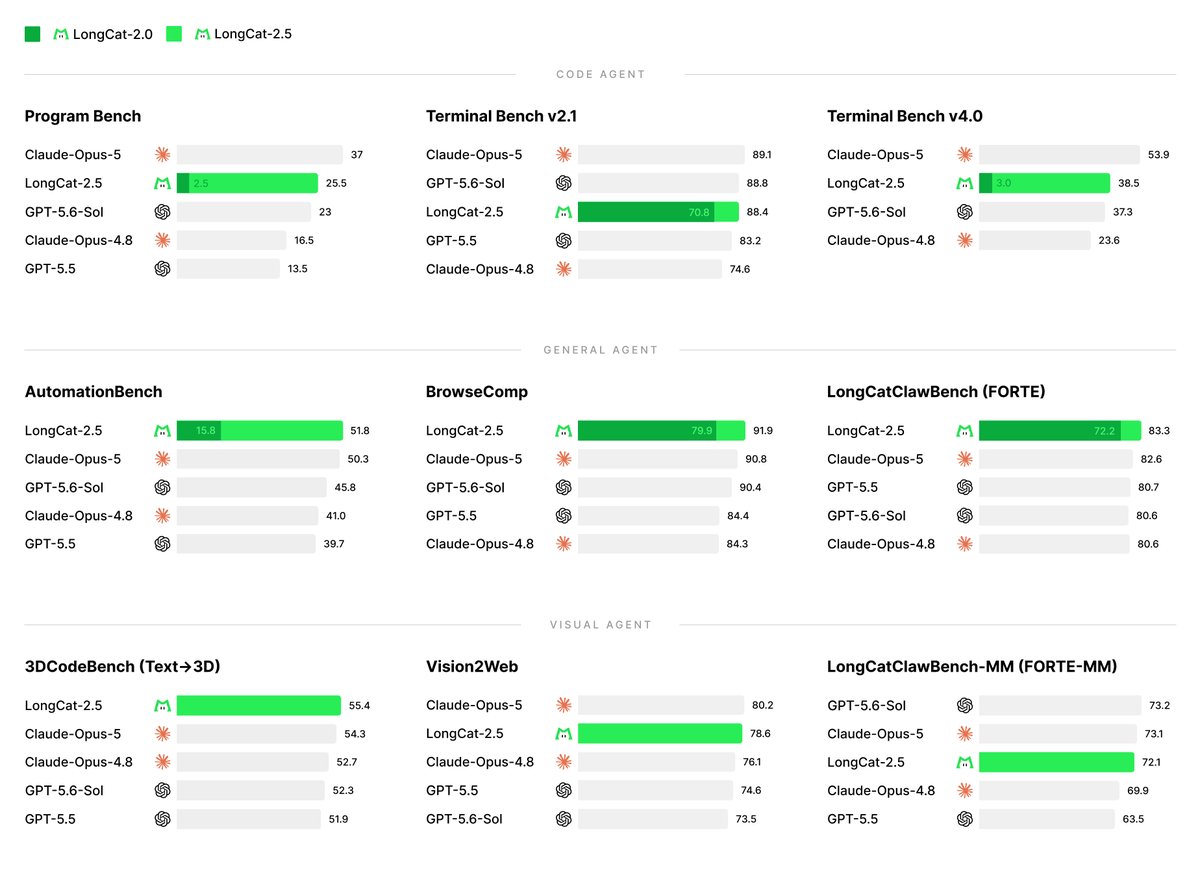
Introducing LongCat-2.5, our latest natively multimodal agentic model with 1.6T total parameters and ~48B active.
Built for long-horizon agentic tasks, it brings stronger visual understanding and agentic coding to work ranging from complex coding projects to visual coding such as creative design and 3D tasks.
Learn more about LongCat-2.5: https://t.co/ULLDweplqR
Kling 4.0 Flash, Kuaishou's lower-cost video model, went fully available on Nov 4 via the Kling AI site and API. Text-to-video, image-to-video, omni reference and editing; 3 to 20 second clips at 720p.
https://t.co/LGYYXq6FhR
Kling 4.0 Flash Is Now Fully Available! ⚡
Kling 4.0 Flash is now available to everyone on the Kling AI website and via API.
You can also access it through MCP, CLI, and AI plugins, bringing greater flexibility to your video creation workflows. With Kling plugins for professional creative tools such as Adobe Photoshop, Premiere Pro, and After Effects, you can integrate video generation directly into your creative process.
Ready to create? You call the shots.
LFM3-Omni-2B, Liquid AI's first omni model: one 2.17B model takes text, images, video and audio in and answers in text or speech. 32K context, open weights under the LFM Open License v1.0.
https://t.co/XeQOuOvyN5
𝙻𝙵𝙼𝟹-𝙾𝚖𝚗𝚒-𝟸𝙱 is our first omni model, built for cross-modal interactions that require understanding visual and auditory information together. It combines vision, audio and language in a single model that responds in text, speech or both.
Ask a spoken question about an image, or provide a video with its soundtrack and ask something that requires understanding both. The model processes visual and auditory information jointly.
It also combines visual context with spoken instructions to generate structured tool calls, helping assistants act on what users show and tell them.
> In our evaluations, it scores 70.1 on Daily-Omni, which tests video and audio understanding, compared with 61.3 for Qwen2.5-Omni-7B.
At 2.2B parameters, it brings multimodal agents on-device that use visual and auditory context to guide users, respond to voice commands and act through tools. Developers can specialize this foundation model for personalized education, everyday assistance, in-car experiences, digital interfaces, robotics, and more.
> 𝙻𝙵𝙼𝟹-𝙾𝚖𝚗𝚒-𝟸𝙱 model card: https://t.co/sgeBm9G4u2
7/
GPT Image 2.6 Sunburst from OpenAI is on LLM Reference:
🔗 https://t.co/YyubFyWCXp
Detail-oriented Images 2.6 model, released Nov 4. Markup-guided edits, SVG and animated GIF. Image API only (no Batch).
Images, upgraded—introducing ChatGPT Images 2.6.
Now with GIFs and reference images.
Plus, two new models are coming to the API with 50% faster image generation.
Hy4 from Tencent Hy is on LLM Reference:
🔗 https://t.co/XGHJp1nDA2
First Hy model with vision. Released Nov 4. $0.834 input / $2.50 output per 1M tokens on Tencent Cloud (cheapest of 3 routes we track). API-only for now.
Hy4 is now available on @TencentCloud and @OpenRouter. It adds vision and computer use for the first time, with stronger instruction following and long-context understanding. https://t.co/XT9L382NxB
Canva Brush from Canva is on LLM Reference:
🔗 https://t.co/jPEb5yR1fh
Canva's first vision-language model for design. It edits through an agentic loop that writes and runs code, then inspects the page. In Canva AI for Pro subscribers; no public API or weights.
Canva Brush is here!
For years, we’ve been working to make AI feel like a true design partner inside Canva, not something that takes over your work.
The first time I used Brush, it finally clicked: super fast, understood what I wanted to change, and kept what I loved intact.
We can't wait to see what you'll create with it!
Particle-1 from Particle AI is on LLM Reference:
🔗 https://t.co/GW4utbwvpC
Coding model post-trained on DeepSeek V4.1 Flash to finish tasks with fewer tokens. 1M-token context, 128K output. $0.25 input / $1.00 output per 1M tokens, the same on all 3 routes we track.
1/ Excited to announce our new company Particle
This is our first step in a series of models focused on developers.
With particle-1, we focused on token efficiency and managed to keep parity in performance while using ~45% fewer tokens.
Live now: https://t.co/m5MvOwR9yE
joey-1 from Base Labs (Baseten) is on LLM Reference:
🔗 https://t.co/lNc7UkNYS0
2B open-weight decision model, fine-tuned from Qwen3.5-2B. Returns calibrated probabilities for choice, yes/no and score questions in one forward pass. 16K context, MIT.
https://t.co/DLlHHvy8PA
Today we’re releasing our third open-source decision model, joey-1 (2B), the fastest decision model available and among the most intelligent decision models of its size.
joey-1 is trained by the @baselabs team, and is available on our Model APIs, as a dedicated deployment, and with a cookbook to fine-tune on our Training Jobs.
joey-1 is built to maximize speed and minimize cost without sacrificing intelligence for those workloads where TTFT really matters.
Jump on it: https://t.co/eraAN1PC3B
Nemotron 3.5 Transcribe from NVIDIA is on LLM Reference:
🔗 https://t.co/Wly2Bhucig
Open-weight speech MoE, 34B total / 4.3B active. Transcription in 40 languages, speaker attribution and translation in one checkpoint. OpenMDW 1.1. https://t.co/clSrsEMv1J
Meet NVIDIA Nemotron 3.5 Transcribe 🎙️
An open-weight, promptable 30B MoE model with ~4B active parameters that brings transcription in 40 languages, speaker attribution, translation, contextual prompting and audio understanding into one checkpoint.
Watch it keep track of who said what when everyone’s talking at once.
1/ 🧵
LFM3-1.7B from Liquid AI is on LLM Reference:
🔗 https://t.co/L7GeR78YzV
Base text model of the LFM3 family: tri-hybrid architecture (convolution, sliding-window and global attention), 256K-token context, about 1 GB of memory at 4-bit. Open weights (LFM Open License v1.0).
Introducing 𝙻𝙵𝙼𝟹: our new generation of Liquid Foundation Models. With a new tri-hybrid architecture and new multimodal encoders, the LFM3 family is the ideal model suite for specialized intelligence.
> 6 model instances, across text, audio, vision, and omni modalities, generative and decision models.
> 𝙻𝙵𝙼𝟹-𝟷.𝟽𝙱: text, 256k context window.
> 𝙻𝙵𝙼𝟹-𝚅𝙻-𝟸𝙱: vision-language model with video-input support for spatial understanding
> 𝙻𝙵𝙼𝟹-𝙰𝚞𝚍𝚒𝚘-𝟸𝙱: tool calls, voice chat, reasoning in 18 languages.
> 𝙻𝙵𝙼𝟹-𝙾𝚖𝚗𝚒-𝟸𝙱: an omni model combines vision, audio, and language.
> 𝚍𝟷-𝟸𝙱 and 𝚍𝟷-𝙾𝚖𝚗𝚒-𝟸𝙱: decision models with typed outputs and calibrated probabilities in a single pass. Omni adds audio input.
> fine-tune on 1 GPU.
> a new tri-hybrid architecture
> architecture optimized for 14 processor classes across GPUs, CPUs, and NPUs.
> 𝙻𝙵𝙼𝟹-𝚅𝙻-𝟸𝙱 is a beast. It performs competitively with Gemma 4 12B (6x larger), and Gemini 3.5 Flash Lite, and GPT-5.6 Luna, with 1.9B parameters.
> 𝙻𝙵𝙼𝟹-𝟷.𝟽𝙱 is #1 on the Pareto frontier of device intelligence 𝚙𝚒𝚙𝚎𝚝𝚝𝚎.𝚕𝚒𝚚𝚞𝚒𝚍.𝚊𝚒
Every modality for specialized intelligence. Pick the one that fits your use case, customize it, and run it on-device.
1/ 🧵
MAI-Image-2.7 from Microsoft AI is on LLM Reference:
🔗 https://t.co/GColPoS2JA
Image editing model, in preview since Oct 27: restyling, relighting, and editing text inside images. Try it on Arena and MAI Playground; Microsoft says text-to-image is coming soon.
MAI-Image keeps climbing!
MAI Image 2.7 Preview is now #3 on @arena's image editing leaderboard. #2 by lab and ahead of GPT-Image-2. That's a +45 point jump from 2.6.
Nemotron 3.5 Bolt E4B from NVIDIA is on LLM Reference:
🔗 https://t.co/T6yktdKHyW
Small open model built on Google's Gemma 4 E4B with Nemotron post-training. 8B params (4B effective), 64K-token context, OpenMDW 1.1 with commercial use permitted.
Available now: NVIDIA Nemotron 3.5 Bolt E4B 4GB ⚡️
Our newest small open model is built for local assistants, interactive characters and robots that can carry on a conversation and use tools to get things done.
Watch Reachy Mini chat and move, with Bolt handling conversation and NVIDIA Cosmos handling vision. Both models run locally on Jetson Orin Nano 8GB.
Learn more: https://t.co/B8ODaWMn0O
Carbon-X from Hugging Face is on LLM Reference:
🔗 https://t.co/utLEkcRo4u
Open 14.8B model trained jointly on DNA and natural-language text: give it raw DNA in a chat and it answers in English. Midtrained from Qwen3-14B, Apache 2.0, 40K-token context.
Introducing Carbon-X: The best open DNA model.
We midtrained a 14B model on DNA and text, and it beats every open language model and matches GPT-6.1 Sol at 1,000x lower cost.
Ask it about a sequence, what a mutation does, or to generate new DNA.
https://t.co/cpZCkEHHmn
Flint from Recursive is on LLM Reference:
🔗 https://t.co/UHNYdeB0vp
Open weights under Apache 2.0, trained from scratch. 39.8B total params, about 2.5B active, 262K-token context. Free on the one route we track (OpenRouter). Recursive reports 74.2% on SWE-bench Verified.
Voxtral Small Transcribe 3 from Mistral AI is on LLM Reference:
🔗 https://t.co/lo2fo3JIba
50+ languages, speaker diarization, end-of-turn detection, 32K context. $0.004 per audio minute on Mistral AI Studio, one of the 2 routes we track. Weights aren't published.
DeepSeek V4.1 Flash 1017 is on LLM Reference:
🔗 https://t.co/7FrV0Tm4NO
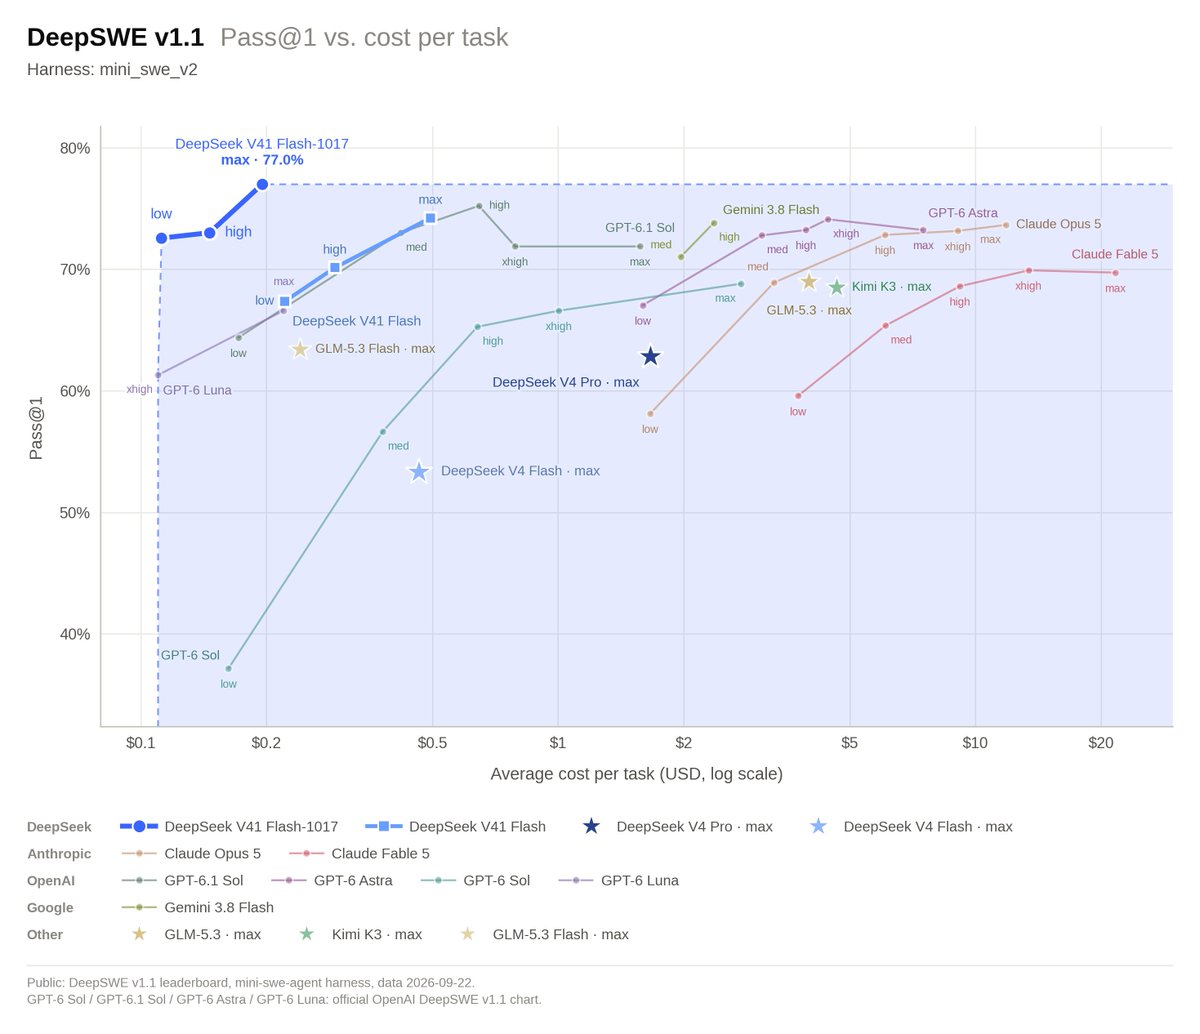
Open weights under MIT, 1M-token context, up to 384K output. $0.20 input / $0.60 output per 1M tokens on DeepInfra, the cheapest of the 4 routes we track. DeepSeek's API serves it as deepseek-flash.
🚀 DeepSeek-V4.1-Flash-1017 is here!
Stronger benchmark performance, faster task completion, and shorter outputs than the previous version—a Pareto improvement in performance and cost. Now live on our website, app, and API.
🛠️ Optimized for @DeepSeekHarness, Tencent CodeBuddy, WorkBuddy, and more. Upgrade to DeepSeek Harness v0.2.1-rc.1 or later for the best experience with the new model.
1/4
Grok Voice 3.0 is on LLM Reference:
🔗 https://t.co/SDVpwlmAdR
Speech-to-speech model for the Grok Voice Agent API, released Oct 14. $0.080 per audio minute on the one route we track (xAI Console). It replaced Grok Voice 2.0 as grok-voice-latest, same price.
Introducing Grok Voice 3.0, the world’s most intelligent speech-to-speech model.
It excels at resolving customer calls, responds in under a second, and costs less than other frontier models.
Nemotron 3.5 Super VL from NVIDIA is on LLM Reference:
🔗 https://t.co/SJp4RydxuU
120B total params, 12B active, hybrid Mamba-Transformer MoE with a 1M-token context. Open weights under OpenMDW 1.1, commercial use permitted. Free on the one route we track (OpenRouter).
Meet NVIDIA Nemotron 3.5 Super VL
Our new open model combines reasoning and tool use with text, image, document, and video understanding for long-running AI agents.
120B total parameters with 12B active 🧵