Now I have successfully configured and connected Google Flow to Claude Code, and can call terminal Codex server to generate image from Google Flow directly on Claude AI.
Flow doesn't have MCP you can directly connect to Claude, so you have to use several codex connectivity servers.
Claude can now use Google Flow to generate unlimited AI images and animates the images video if I want to.
This setup will save cost because i don't need to subscribe for Highfields, i can literally use flow from Claude. 😂
I'm automating every single process for YouTube Automation,while cutting cost. I love this! ✌️
this is f*cking insane... Anthropic just dropped 532 Claude plugins for free. Stripe, Shopify, Canva, BlackRock and HubSpot built them for Claude themselves
Dario Amodei (CEO of Anthropic) picked the 7 that replace a whole small-business team. that team costs $38,400 a month. these plugins cost $0:
→ bookkeeper: QuickBooks. reads your P&L and chases every overdue invoice
→ payments dev: Stripe. builds checkout, subscriptions and refunds into your app
→ store manager: Shopify. 18 skills to build and ship your whole store
→ designer: Canva. creates, resizes and brand-checks every design
→ sales rep: HubSpot. preps every call and writes your morning brief
→ lawyer: LegalZoom. flags the risky clauses in your contracts
→ ops: Zapier. plugs Claude into 8,000+ apps
how to set it up in 5 minutes:
1. open Claude Code and type /plugin
2. search the name of a tool you already pay for
3. hit install and log in once
4. give it the first job in plain words: "chase every invoice older than 30 days"
start with one. the tool you open every morning is the one that saves you the most
all 532 in one place: https://t.co/vdMTG3cINS
$38,400 a month for a team, or free plugins and one afternoon. which one are you running next month?
the whole marketplace, mapped live, every pick below ↓
O futuro do AI local chegou.
A Microsoft acabou de lançar um LLM de 2B parâmetros que:
• Roda só no CPU
• Usa 0,4 GB de RAM
• É até 6x mais rápido
• Consome até 82% menos energia
E ainda compete com modelos full-precision do mesmo tamanho.
Isso é o BitNet.
Link:👇
It's f*cking insane that you can now train your own ChatGPT-style model from zero in 2 hours for less than a dollar
it's called MiniMind (65.8K stars), and it walks you through every step big labs take, on a model 2,700x smaller than GPT-3:
→ tokenizer: turns text into numbers
→ pretraining: learns language by guessing the next word
→ fine-tuning: learns to answer like an assistant
→ DPO and RL: learns which answers are better
→ tool use: learns to call a calculator or a search
→ chat: runs on your laptop or behind an OpenAI-style API
no black-box libraries. every algorithm is written in plain PyTorch, so you can actually read how it works
one GPU, 2 hours, $0.40. that's it
https://t.co/9p0YhY3oai
save it for your weekend build
ANTHROPIC GASTÓ 3M DE DÓLARES Y 30 MESES PROBANDO AGENTES DE IA EN EMPRESAS REALES
Y lo resumió todo en 12 páginas.
1.287 tareas reales. 2,4 millones de líneas de código.
La IA superó a los humanos en sus propios proyectos y automatizó el 63% del trabajo rutinario.
Con la memoria y los ciclos correctos, un ingeniero multiplicó por tres lo que producía.
Alguien pagó 3 millones para que tú lo puedas leer gratis.
Y la mayoría lo va a guardar y no lo va a volver a abrir.
Pero hay algo que esas 12 páginas no te dicen.
Saber que el sistema correcto te multiplica por tres no es lo mismo que saber construirlo.
Ahí es donde se queda atascada casi todo el mundo.
Precisamente por eso te dejo abajo esta guía sobre cómo pasar de escribir prompts a construir tu propio sistema.
No dejes que esto sea otra cosa que guardaste y nunca aplicaste ↓
It’s happening.
Google built an AI that rewrite its own weights to get smarter.. and it does it by sleeping.
Right now, every AI model you use has a fatal flaw.
When you train a model on new data, it suffers from "catastrophic forgetting." It forcefully overwrites its old knowledge to make room for the new.
If you try to bypass this by using a massive context window, the AI simply forgets everything the second you close the chat.
Once a model is deployed, its brain is effectively frozen in time..
But Google Research published a paper introducing a biological "Sleep Framework" for LLMs.
They split the AI's existence into two distinct states.
1. The Wake Phase: AI interacts with you. It solves problems, processes data, and stores new information in a fragile, short-term memory bank.
2. The Sleep Phase: When the system goes offline, the AI literally goes to sleep. It unlocks dormant parameters and actively transfers its short-term experiences into permanent, long-term memory.
It learns forever without overwriting the past.
But then, the AI starts dreaming.
During the sleep phase, the model deliberately activates random, unusual neural pathways. It generates synthetic scenarios, literally dreaming up fake data, and tests itself to improve its own reasoning and uncover hidden patterns.
The results are staggering.
• It retained perfect knowledge across a massive 10-million token window.
• It learned entirely new, unseen languages with zero performance drop.
• It crushed elite math benchmarks (AIME), jumping to nearly 80% accuracy.
Zero catastrophic forgetting. Continuous, autonomous self-improvement.
We’ve spent billions trying to build bigger context windows so AI can hold more information at once.
But the future of AI isn't about cramming more data into a single prompt.
It's about letting the machine process its experiences after you log off.
A maior praga da nossa geração é o homem inteligente que não constrói nada. Eu encontro esse perfil o tempo todo. Ele lê os livros certos, entende dos assuntos certos, domina a teoria dos jogos, direct response e entre outros.
Mas ele fica preso no ciclo de otimização infinita, esperando o momento ideal e, o plano infalível. Quando na verdade, o mundo não recompensa quem sabe mais. O mundo recompensa quem executa mais rápido. Um plano medíocre executado hoje sempre vai destruir uma estratégia perfeita que só existe na sua cabeça.
Eu vejo homens brilhantes apenas assistindo enquanto gente com metade da inteligência deles, acumulam poder e dinheiro simplesmente porque tiveram a coragem de começar antes de estarem prontos. O conselho que posso dar aqui, é que conhecimento sem atitude é apenas entretenimento. Como documentários que assistimos.
Se você não está disposto a parecer um idiota no começo, você vai passar o resto da vida pensando no que podia ter feito.
Si siempre quisiste aprender robótica sin comprar placas, ve esto
Alguien hizo un sitio gratis donde armas 8 placas reales en 3D, desde un Arduino Uno hasta una Raspberry Pi 4, y luego las conectas.
Cómo funciona la demo:
→ Colocas chips, conectores y headers pieza por pieza
→ Luego los sueldas
→ Armas circuitos reales: prender un LED, leer un sensor, mover un motor
→ Todos los modelos 3D los generó Fable 5.2 en código, sin archivos 3D ni fotos
Para qué sirve:
→ Entender qué hace un pin GPIO antes de gastar en hardware
→ Practicar soldadura y circuitos sin quemar nada
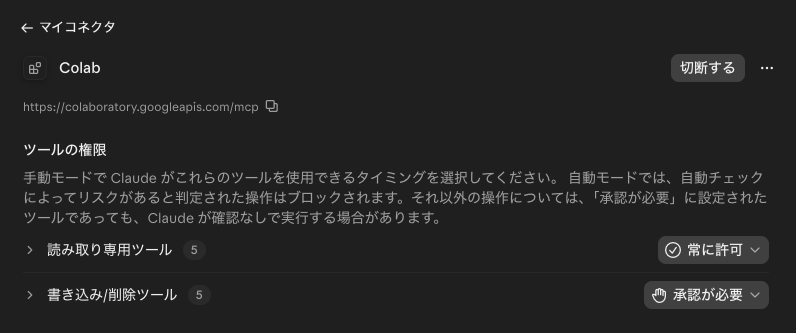
Google ColabがRemote MCPに対応した!!
これは神アプデで、Cloud AgentからもColabのGPUを使える!自分のPC閉じたまま、モデルの学習や推論を任せられるの嬉しい!
Google AI ProやUltra入ってる人は無料でColabの計算枠もついてくるしかなり相性が良いのでは!
🔴 PEGA ESTO EN CLAUDE Y TE MONTA TU PRIMER EQUIPO DE AGENTES DE IA
Te dice qué tarea automatizar, qué hace cada agente y cómo ponerlo en marcha en 7 días.
Aquí tienes el prompt: ↓↓
there is no catch and that scares me
Elon Musk posted an idea that hit 27 million views:
"stop building startups. buy boring internet real estate and let bots run it"
that's literally what Grok Bot does now. the whole setup costs $0 on top of the sub:
→ create a bot, name it Mogul
→ tell it to find one boring niche people search every day (it reads X and reddit complaints in real time, it's grok)
→ it builds a small directory site on its own computer and ships one useful page every night
→ it negotiates affiliate and referral deals itself, by email, in your name
→ publishing runs on a routine. telegram sends you the money reports
→ month one: traffic. month three: the first $217. it never stops after that
your laptop stays shut. the site grows anyway
every page is a tiny employee that works forever. it compounds like rent
some of them run 3 sites each and haven't opened a single one. they don't post about it, and now you know why
every month you wait, someone's bot ships another 30 pages into the niche you would've picked
full playbook below
bookmark this before someone takes your niche
I am begging you, turn your old laptop into a private AI this week.
That laptop in the drawer can run a free open source model.
If it has 8GB of memory, it's enough and it works with the Wi-Fi off.
Leave it on your desk and it becomes the one AI in your house that nobody can read, change or switch off.
Install Jan, a free open source app, then download Gemma 4 E4B from inside it. Ask it the questions you'd never type into a website.
Setup takes about 20 minutes.
You'll be glad you didn't throw it away.
🚨ESTO ES PURO ORO
acaban de convertir tu repo en una fábrica donde los agentes curran solos.
se llama Islo.
le dejas un ticket y vuelves con el fix ya testeado y el pr abierto. cada agente trabaja en su propia microvm aislada, con tu stack entero montado.
lo de bajo riesgo se mergea solo. lo de alto riesgo se para y espera a que un humano diga que sí. tú sigues firmando siempre el merge final.
y te dejan elegir lo que casi nadie deja:
→ el harness que quieras (claude code, codex, cursor o el tuyo)
→ el modelo que quieras
→ evals contra tu histórico real de ingeniería
→ soc 2 type ii y tope de coste por línea
400+ empresas ya confían en ellos. 15M$ liderados por insight partners e infra con databricks.
los agentes generan código. esto lo manda a producción sin que reces.
Qwen3.8-35B-A3B Is Running at 50 Tokens/s on an RTX 3060 With Just 12GB VRAM
A 35-billion-parameter Qwen3.8 model is reportedly generating around 50 tokens/s on an NVIDIA RTX 3060 with just 12GB of VRAM and 16GB of system RAM.
Prompt processing is even faster, reaching approximately 550 tokens/s.
No RTX 3090. No RTX 4090. No multi-GPU setup.
Just a consumer GPU, system RAM and llama.cpp.
The interesting part isn’t simply that a 35B model can run on a 12GB graphics card. It’s how the developer gets around the GPU’s memory limitations without needing to fit the entire model into VRAM.
The setup combines Mixture-of-Experts architecture, four-bit quantisation, CPU offloading and memory-efficient inference techniques.
Let’s break down how it works.
The Hardware and Performance Configuration
Here’s the reported setup:
Model: Qwen3.8-35B-A3B
GPU: NVIDIA RTX 3060
VRAM: 12GB
System RAM: 16GB
Inference engine: llama.cpp
Quantisation: Q4_K_M
Decode speed: Approximately 50 tokens/s
Prefill speed: Approximately 550 tokens/s
Configured context: Up to 262K tokens
Attention: Flash Attention
KV cache: Q8
CPU offloading: 26 MoE layers
Two performance figures deserve attention: 550 tokens/s and 50 tokens/s.
They measure different stages of inference.
Prefill measures how quickly the model processes the incoming prompt. A higher prefill rate means it can ingest large amounts of text more quickly.
Decode measures how quickly the model generates its response, one token after another.
So, the reported 550 tokens/s doesn’t mean the model writes answers at that speed. Its reported generation speed is approximately 50 tokens/s.
Both numbers matter, but they describe different parts of the inference process.
How Does a 35B Model Fit Into 12GB of VRAM?
The first thing to understand is the model architecture.
Qwen3.8-35B-A3B uses a Mixture-of-Experts (MoE) architecture.
Although the model contains approximately 35 billion parameters, only around 3 billion parameters are activated for each token.
This is different from a conventional dense model, where most of the model’s parameters participate in processing every token.
An MoE model contains multiple expert networks and a routing mechanism that selects which experts should process a particular token.
Rather than activating every expert, it uses a smaller selection for each computation.
This reduces the amount of computation required during inference.
But there’s an important distinction:
3B active parameters does not mean the model only needs memory for 3B parameters.
The complete collection of expert weights still needs to be stored somewhere because different experts can be selected depending on the input.
MoE reduces the active computational workload, but the memory requirements of the full model remain substantial.
That’s where quantisation and CPU offloading become important.
Splitting the Model Between GPU and CPU
The RTX 3060 has 12GB of VRAM, while the machine has another 16GB of system RAM.
Instead of trying to squeeze everything into GPU memory, the developer uses llama.cpp to distribute the workload across both memory pools.
According to the reported configuration, 26 MoE layers are offloaded to the CPU.
This means the GPU handles the portions assigned to it, while the CPU executes the offloaded layers using system memory.
llama.cpp coordinates the execution across both processors.
This allows the system to work with model weights that exceed the GPU’s physical memory capacity.
However, CPU offloading introduces a trade-off.
Data must move between system RAM and GPU memory through the PCIe connection. These transfers introduce additional latency and can affect generation speed.
The final performance therefore depends on more than the GPU.
CPU processing power, RAM bandwidth, PCIe bandwidth and the way layers are distributed all influence the result.
🔴 YA PUEDES CREAR Y EDITAR IMÁGENES CON IA SIN PAGAR NADA
→ Pesa 4,4 GB y va en tu ordenador
→ Sin cuenta, sin créditos y sin filtros
→ 224.000 descargas en un mes
Te dejo el link abajo: ↓↓