We’re a 2-person lab researching more efficient architectures for generative image and video.
https://t.co/96Vwy4laKo
Last month, we published Pyramid-JiT, a pixel-space architecture that converged 11x faster than its latent-diffusion counterpart.
Today, we're releasing a 2B Pyramid-JiT text-to-image model as a milestone towards more affordable video models.
Trained from scratch for only ~$20K.
See blog for details & weights (Apache 2.0).
New research, hot off the presses 🔥
We introduce a pixel-space image model (P-JiT) that matches our latent diffusion model in 11.3x fewer training samples.
https://t.co/4nF3Zr0dmk
See blog for details. Code and model checkpoints (Apache 2.0, as always).
Excited to release early research, on our road to Linum v3 text-to-video.
We introduce a novel pixel-space text-to-image architecture (JiT-DDT), that trains 3.6x faster than our old Linum v2 model.
https://t.co/Gx245U6oPJ
See the blog for the details, as well as code and model checkpoints (Apache 2.0).
Been heads down working on our next text-to-video model, but we're going to be publishing some exciting research updates over the next few weeks!
Here's an appetizer - How do you build pre-training datasets that accelerate model convergence?
https://t.co/G2Hgiaih7k
From the performing arts to frontier AI.
@LinumInc's two-person team trained a 2B parameter text-to-video model from scratch. The key constraint wasn't compute, it was networking.
Video data is orders of magnitude larger than text. They streamed petabyte-scale data live during training. That only works if the uplink is fast enough at scale.
With Crusoe, it was. Training bottlenecks that would've made it 25% more expensive elsewhere — gone. A small team with a big model, actually executable. 🤯
Full story: https://t.co/j1RUqsgnqO
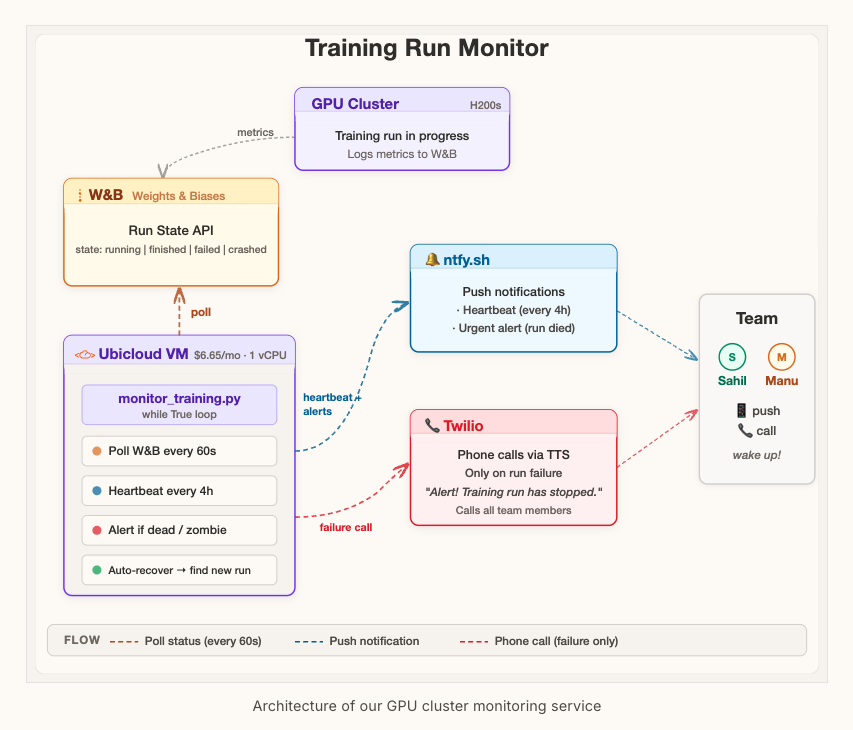
We trained Linum-v2 on a big cluster over the holidays and didn't want to spend the whole time refreshing our Weights & Biases from our phones.
So we built a simple $8/month tool to just call us when something crashed.
Open-sourcing it, in case it can help other foundation model teams. https://t.co/IHSyQ36nMa
Turns out better VAE reconstruction quality can make your diffusion model worse.
We learned this the hard way over 4 months.
Writeup + open-source Image-Video VAE model.
https://t.co/JgX8qpsfKR
We’re a 2-person AI Lab.
Today, we’re releasing our first open-weight text-to-video models trained from scratch (2B params, Apache 2.0, 360p & 720p).
Weights on Hugging Face.
https://t.co/0j7t2oqL4Z
@eigenron all code is open source, so you can dig into the details; but like i said we'll be writing a lot more about the technical specs and how we got here
💪After months of hard work, we're excited to announce our first text-to-video model!
💰Model is free to use.
🤫Discord remains private, as we scale up GPUs.
👉 Waitlist link again in case you missed it -- https://t.co/nK8Sqo77W8