ok, so sora can generate up to 60s video. With 8 fps, that is 480 frames. My guess is it is likely 1280*720 or 1024*1024 resolution when it comes to 60s video. So 1024*1024/(8*8) for video encoding, and 8*8 pixels per patch, we are looking at 256 tokens per image. 1/2
AI has 2 loud groups: “AI Safety” builds hype by evoking existential risks from AI to distract from the real harms, while developing AI at full speed; “AI Ethics” sees AI faults & dangers everywhere—building their brand of “criti-hype”, claiming the wise path is to not use AI.
RLHF is the 🪄 getting us from GPT-3 to ChatGPT.
But RLHF is hard! Need to train a reward model, then do RL on a big LM (w/ expensive sampling & tuning)
𝙊𝙧 𝙙𝙤 𝙮𝙤𝙪?
Introducing Direct Preference Optimization (DPO), a simple classification loss provably equivalent to RLHF
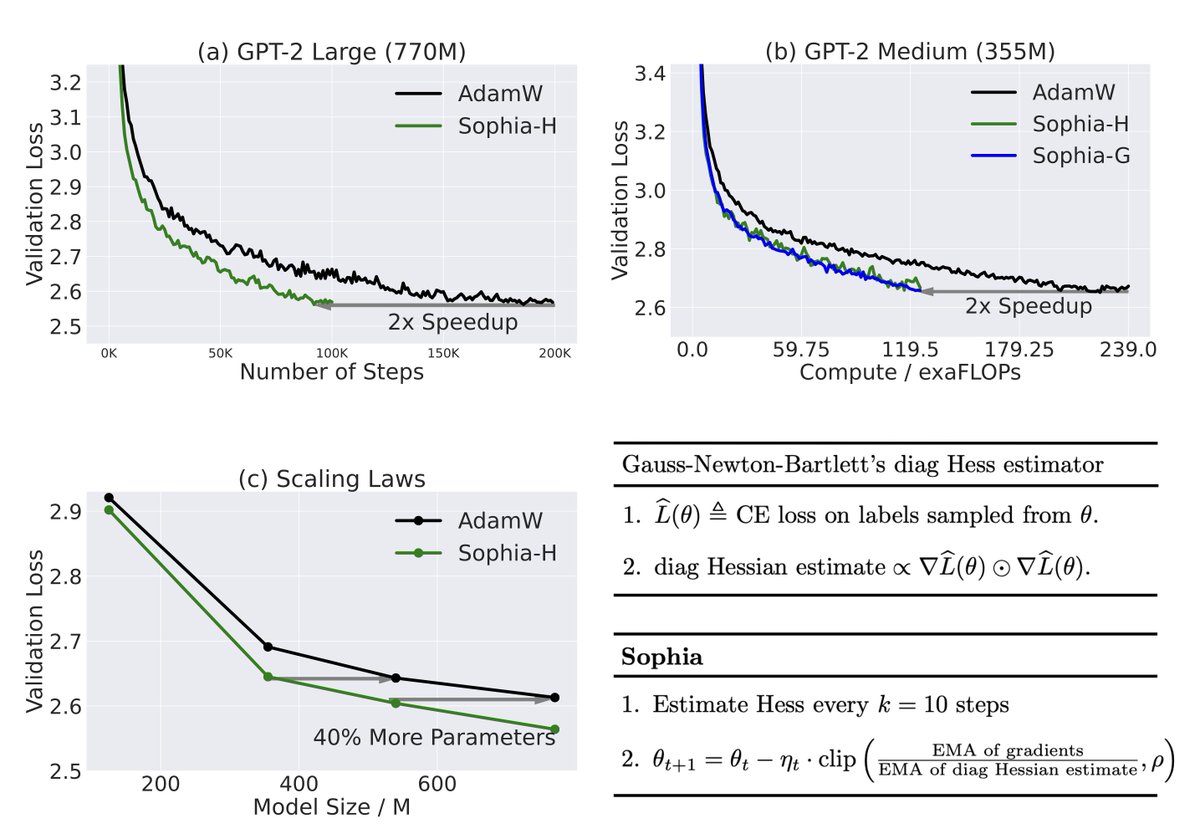
Adam, a 9-yr old optimizer, is the go-to for training LLMs (eg, GPT-3, OPT, LLAMA).
Introducing Sophia, a new optimizer that is 2x faster than Adam on LLMs. Just a few more lines of code could cut your costs from $2M to $1M (if scaling laws hold).
https://t.co/GrMY600lLO 🧵⬇️
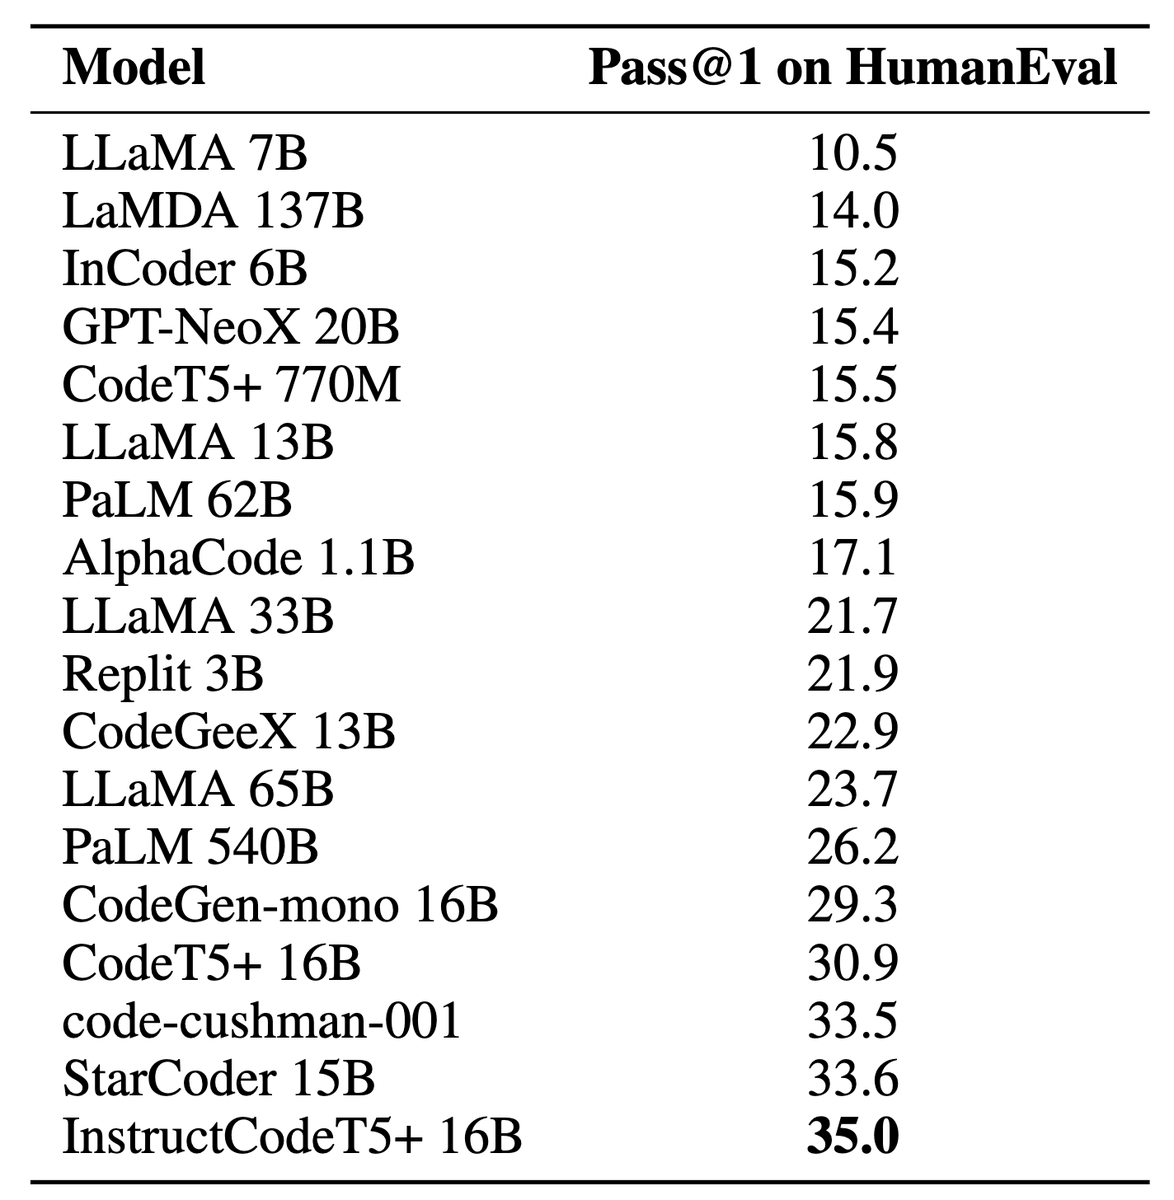
Introducing 🔥CodeT5+🔥, a new family of open-source code LLMs for both code understanding and generation, achieved new SoTA code generation performance on HumanEval, surpassing all the open-source code LLMs.
Paper: https://t.co/apxl03WvNc
Code: https://t.co/nHTaIGIEmm
(1/n)
Three things you need to know about AI and teaching: AI writing is actually undetectable. AI use will become even more ubiquitous. And the need for classroom learning remains, but it will need to evolve quickly.
Education can adjust, and will need to. https://t.co/prg1eJiFyQ
Introducing 100K Context Windows! We’ve expanded Claude’s context window to 100,000 tokens of text, corresponding to around 75K words. Submit hundreds of pages of materials for Claude to digest and analyze. Conversations with Claude can go on for hours or days.
IMAGEBIND: One Embedding Space To Bind Them All.
Learns a joint embedding across six different modalities - images, text, audio, depth, thermal, and IMU data.
An open source project by Meta-FAIR.
Paper: https://t.co/g07iDT5rVO
Demo: https://t.co/80OKqOyGEb
Code: https://t.co/J4jrRm3Kik
Blog post: https://t.co/Meh7QSQsRS
Introducing: 💫StarCoder
StarCoder is a 15B LLM for code with 8k context and trained only on permissive data in 80+ programming languages. It can be prompted to reach 40% pass@1 on HumanEval and act as a Tech Assistant.
Try it here: https://t.co/4XJ0tn4K1m
Release thread🧵
📢 Introducing MPT: a new family of open-source commercially usable LLMs from @MosaicML. Trained on 1T tokens of text+code, MPT models match and - in many ways - surpass LLaMa-7B. This release includes 4 models: MPT-Base, Instruct, Chat, & StoryWriter (🧵)
https://t.co/Zg7PcrQvOi
Some good remarks about the mood of many AI researchers and engineers at the moment.
It's easy to make two mistakes and get depressed or feel burned out:
1. Thinking that AI is "solved" or will soon be.
2. Thinking that one can not contribute.
Both are false.
Today we're releasing the Segment Anything Model (SAM) — a step toward the first foundation model for image segmentation.
SAM is capable of one-click segmentation of any object from any photo or video + zero-shot transfer to other segmentation tasks ➡️ https://t.co/qYUoePrWVi
Our new course, "From Deep Learning Foundations to Stable Diffusion", is finally done after 8 months of work!!!
With >30 hours of video content (all free, no ads!), you'll learn how to create and train a Stable Diffusion model starting from pure Python 🧵
https://t.co/bK0PSIzFww