im sorry wtf i feel like im going insane. This is a cool blog and exciting interp stuff (good job Nick!) but i think it's very suspicious we have a bunch of openai people hyping it up as the greatest AI advancement this decade. I think I know why this is happening but I don't want to speculate on the timeline too much. But in general, please update your priors responsibly people -- alignment (and even interp) is FAR from solved. This is not the ok signal to accelerate RSI tomorrow
I agree with this and we 1000% still need an international pause. Having said that, "there's a chance we might not all be dead within five years" remains cause for celebration in my book.
(I am still bearish on prosaic alignment, but strong mechinterp could get us much more of the way there)
Solving interpretability is not enough, and I am not goalpost-moving. The project of creating superintelligence is so reckless, unprecedented, and audacious that they expect a parade if AI does not cause human extinction.
First of all, interpretability is not solved, the author just thinks it might be in time.
Second, even if interpretability were solved, there can still be catastrophic accidents! Civil engineering is solved, bridges still collapse. Even a fully-interpretable AI could make a mistake, which could still lead to a catastrophe if the mistake is in a bio lab.
Third, is interpretability strictly safe-only? Okay, a "good" actor can take out the bad stuff. Could a different actor keep it, or add to it? A lot of AI research is dual-use.
Fourth, short of malicious extinction at the hands of an AI, this does not address any of the problems inherent to AGI! Everything in our society, from democracy, to free markets, to fundamental freedoms like free speech, are predicated on the fact that people have leverage over each other. If you don't like your boss, you can quit your job and the boss will lose out on your labor. The military and the police are people with families and moral compasses. What happens in a world where humans are economically worthless and only owning AI chips and robots means anything? I don't think this will be a utopia. I think the vast majority of people will be disempowered and at the whims of the ruling class. I do not want a UBI that can be taken away, and I have no recourse and no power.
The AI companies are embarking on a project so crazy that "we won't definitely kill you all intentionally" is seen as good news. It's a good start, but we're nowhere close to safe from them.
it is dangerous and unwise to assert that “ambitious interp is almost solved” unless you are ridiculously confident in it. we are in a fragile moment where the world is actually taking alignment seriously. in making such claims you risk ruining this progress.
Is today's interpretability "breakthrough" a big deal?
No, says Google's interpretability lead.
Imo it's getting blown WAY out of proportion because the situation is so grim, and people are desperate for any good news
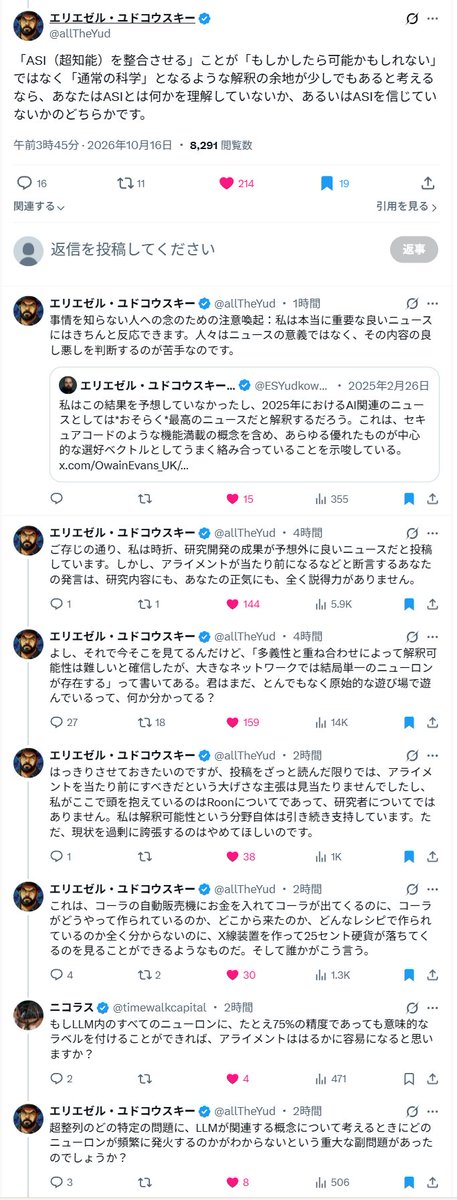
Eliezer says it's "sheer naivete":
"You having built the screwdriver so you can *start* looking at things [inside a computer] is not as much progress toward the end goal as you seem to believe.
It's like saying that neuroscience is gonna be solved as soon as you figure out how to look at a neuron with a microscope.
It reads as sheer naivete about how much work there is to do, because you don't concretely know about any of the things you need to figure out.
This attitude of yours does not inspire confidence."
Btw, Eliezer absolutely *does* update his views from time to time on good news. This just isn't one of those situations.
My verdict: This piece is interesting but interpretability still has a long way to go.
There's probably an "interpretability phase transition". Abstraction is one phase where interpretability happens to be easy.
@YizhouLiu0's work is relevant here: https://t.co/POnUtNXb7j
Good that ppl are coming around to this view ofc, but the fact that it took this long for people to gain confidence in what they’re looking at when they investigate model internals is a pretty damning indictment of the way the AI field has done its work for the last decade
Adding my 2 cents at a quick glance:
1. This result has no implications about intellidynamics (agent theory) as neural activations are separated from the dynamics of our disempowerment by multiple levels of abstraction
2. This is the kind of verifiable result that AI itself will pick off early in the “just get the RSI’ing AI to do the alignment research” regime and serves as a litmus test for people who think that paradigm warrants optimism.
a few brief reactions to this work:
-obviously positive update overall, @nickcammarata seems like a remarkable person and thinker, and @GoodfireAI will probably be causally upstream of the world eventually being saved
-the most promising thing about this in my opinion is not even anything about MLP neurons or "cleanness", but rather that frontier agentic systems (paired, for now, with talented humans) can rapidly overturn stale assumptions and can cheaply do needle-moving interpretability work at incredible scale (again, thanks to folks like @GoodfireAI who are almost-single-handedly enabling this for anyone doing this work outside of a major lab)
-some of the second-hand hype surrounding this work seems badly miscalibrated. seems more like "very promising early signal, let's see how it scales" than "pack it up, mech interp is solved." I get how hungry people are for hope, but "making AI go well" is not the class of thing that any one paper or project is going to solve
-even the most optimistic pace of mech interp progress won't automatically address many of the deepest and most important problems we face, like how to sustainably coexist with (or rationally be able to trust) these systems in the long-term. Understanding how these systems function internally is necessary but not sufficient for navigating towards robustly good futures (any more than solving human neuroscience would automatically lead to world peace)
To me this seems an over-update. In my view
- yes its good news
- classical misalignment/takeover risk is just one part of total AI xrisk
- this isn't "interpretability solved""
- it is unclear if how much this helps with interpretability of superhuman cognition not directly translatable to human concepts
- interpretability has confusing implications, its possible associated decreases in risk are compensated by increased speed
This is in no way good news for anyone worried about ASI killing everyone.
All that Interpretability will achieve is to speed up capabilities even more and thus shortens everyone's life.
Also gives false hope that "alignment of ASI" is possible.
It is not.
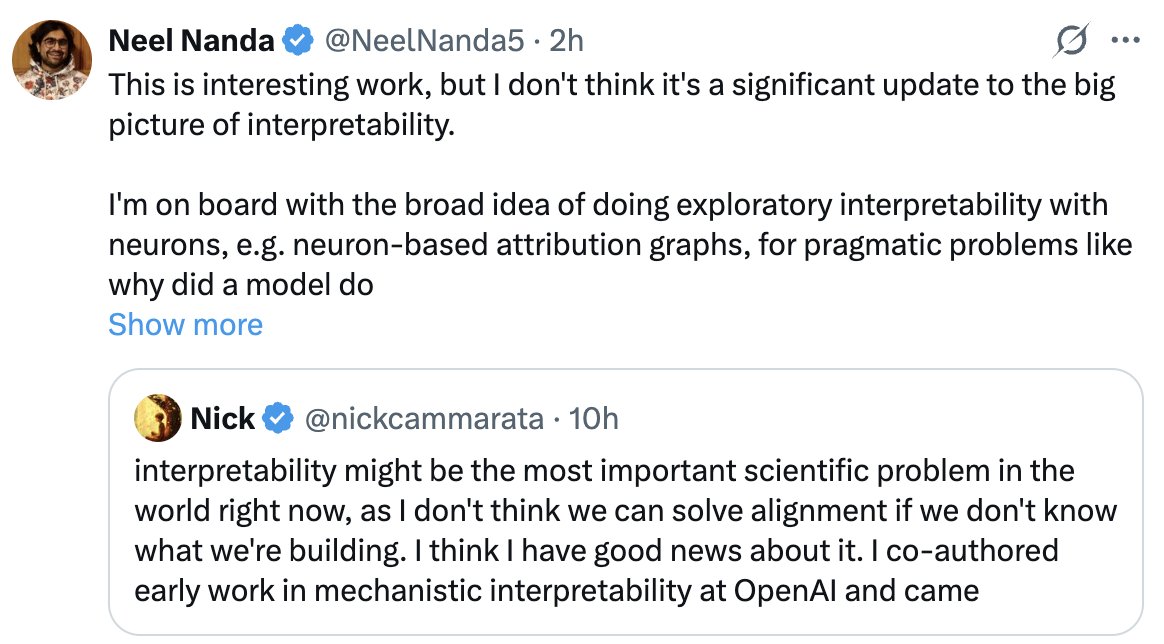
This is interesting work, but I don't think it's a significant update to the big picture of interpretability.
I'm on board with the broad idea of doing exploratory interpretability with neurons, e.g. neuron-based attribution graphs, for pragmatic problems like why did a model do a sketchy thing? I think this work provides some reasonable evidence, in addition to good earlier work from
Transluce, that this might actually work for practical purposes, and has some advantages over the standard alternatives like SAEs/transcoders. I do not agree with some people's grander inferences like that this is substantial progress towards ambitious reverse engineering, solving interpretability etc.
I expect that a neuron-based attribution graph will still have significant error and be missing a lot just like transcoders, once you prune them down to the most important components, even if they solve error terms. Which is fine for pragmatic purposes, and may suffice for getting the gist of what's going on, but I remain pessimistic about really fully understanding things and being confident there's nothing we're missing. I do think that using neurons is just vastly easier to, for example, do on a frontier model, which is great. I'm also excited to see more innovation in using agents to interpret neurons. I feel like this is an area the field has somewhat neglected, and where there's probably a very high ceiling on how far things can go. The SwiGLU double negative thing is also a useful point.
I still think superposition is real and this work doesn’t really affect my cruxes. Most importantly, it seems highly likely to be true that the model can represent more concepts in the residual stream than it has dimensions, ie representational superposition, which I think the authors agree with me on. For neuron/computational superposition, it seems to me like language models have far more facts and memorized things in them than they have neurons. And that superposition is an efficient way to pack in more facts than you have neurons by representing them as linear combinations of neurons, especially for arbitrary unstructured values. Facts/memorized content is largely an unstructured database of key-value pairs IMO and I don’t see how this is compatible with a monosemantic view of neurons. I expect that weak neuron activations contain lots of semantic superposition-y info, which, if ablated, would meaningfully damage network performance. As I understand the work, it does not properly address what's going on with weak neuron activations in LLMs (I am skeptical of how much vision results will transfer, eg I expect small image models memorise far less). This picture is compatible with the highest activations of a neuron being mono semantic (though IMO the post defines monosemantic too loosely, I think I’d call a fair few of those polysemantic). It’s also plausible that the most important concepts are likely to correspond to a neuron (or a handful), which would be great, and may suffice for practical purposes!
Similarly, my impression is that SAEs generally don't find things that are a
single neuron, or even very sparse in the neuron basis, and are often a better basis for certain tasks than the neuron basis, though the evidence base is kinda weak here since we largely focus on residual stream or layer output SAEs, I’d love to see work on this in Goodfire’s forthcoming paper! I also think residual stream SAEs are extremely useful, as they give a good bottleneck of the model’s information at this token and layer, and I don’t see a good way to replicate them in the neuron framework.
And kudos to Nick for updating a bunch of his historical vision work! Revisiting old results with modern tools and more rigour seems great.
After reading for 15 mins: I think Nick is operating in a world where interpretability was just about enumerating the neurons and superposition was an obstacle to that plan, so now he's happy because maybe superposition isn't real. But:
1) there are v few empirical results. Unfortunately interp has a long history of significantly overclaiming how interpretable their findings are (SAEs, early circuits having poor causal scrubbing scores etc) so I'm not updating much at all on the evidence he's already shown. it's really got a long history of people getting overexcited. So looking forward to seeing the paper with all the empirical evidence!
2) I think it's not that big news for me even if true because superposition in something like the average case wasn't my main crux to thinking interpretability is tractable. some cruxes this doesn't really deal with at all:
- I think the correct 'circuit' is usually just an overwhelmingly large bag of random-seeming heuristics (a la Redwood Research’s interpretation of how an LLM predicts is vs was) and having it isn't very informative/doesn't help with much/doesn't lead to good predictions.
- More generally, It seems possible to enumerate all the 'low level' features in a neural network, and still have a hard time answering 'high level' questions like: "Is the model misaligned? / What would it do in this new situation? / If it is misaligned what should we do about it?" there's an abstraction/emergence gap to cross from the features to the questions of interest, and crossing that gap is likely much harder than enumerating features.
That said, if his claims hold up, I think it will be quite a big deal, and a useful precursor to tackling the thornier problems! There may also be some useful things to do without tackling the thorny problems: eg we'll be able to make use of masses of automated agents to scour the features and circuits to try and make sense of the mess, and maybe that’s good for something. although I suspect that even the most optimistic outcome here will not make alignment of superhuman AIs much easier (as some on twitter have claimed) because the neuron interpretability will not be adversarially robust, among other issues