We just released Polars 2.0.
It removed many of our legacy decisions makes the streaming engine our default and promotes SQL to a first class citizen within Polars.
It comes with initial out-of-core (spill to disk) support, a new Map data type and a lot of performance improvements. In fact, we think Polars is now one of the fastest analytical SQL engines on a single node. See benchmarks in the post: https://t.co/ATc6UzJqby
Pretty much at every academic event I went to in the last year, I end up talking to others about how to change teaching in response to AI. Since I keep repeating myself, I figured I might just as well write down what we have been doing: https://t.co/doLMnKBQ10
Marin 535B-A23B is ~7% done training, and so far things look on track. Next Tuesday (Sept 1 @ 10 PT), we will have a Zoom panel/discussion where the Marin team will talk about the design decisions that went into this run, the tradeoffs made, and our learnings. If you're interested, join the Discord for details (https://t.co/xwJSxd2IxH).
I'm joining OpenAI next week!🥹 The job search turned out to be really challenging but also super rewarding, so I wrote a small blog to share what I learned along the way and hopefully make the process a little less mysterious for the next person. https://t.co/6FigSBdenD
On-Policy Distillation is the most active new research direction being explored in RL for LLMs. Had the chance to discuss how it works with Dwarkesh and why it fits so nicely into large-scale pipelines.
Introducing: Cohere Command A+
We’ve created our most powerful LLM yet, optimized it to run on as little hardware as possible, and released it open-source for all.
We open-sourced some amazing work on an experimental Rust compiler for GPU from my colleagues at @nvidia. It takes a slightly different approach to expose GPU programming concepts natively in Rust. Check it out https://t.co/xR4Ho2LUMR.
@scaling01 Open models are behind. The token usage can be an indicator of efficiency but I will say that the token usage by the number of params is more interesting.
Closed labs hide model sizes. They can't hide what their models know, and what a model knows is an indicator on how big it is.
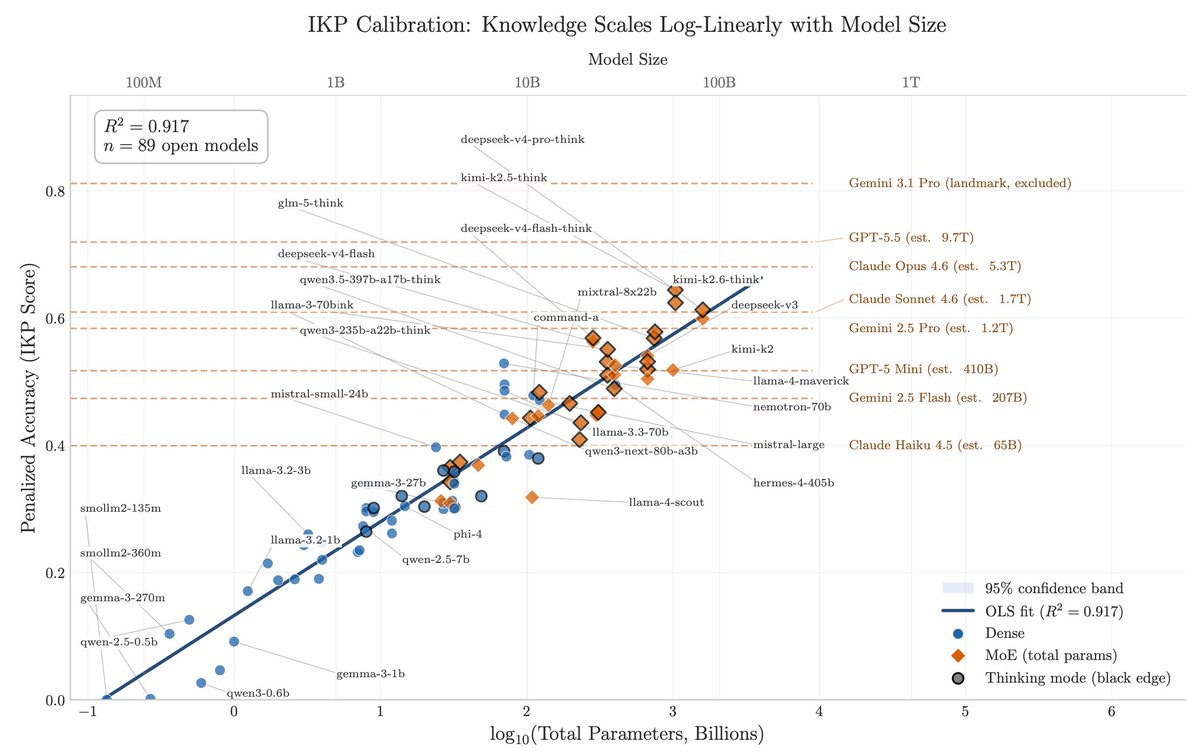
Reasoning compresses. Factual knowledge doesn't. So you can size a frontier model from black-box API calls alone, and across releases you can literally watch a single fact arrive in the parameters over time.
For three years, my friends Jiyan He and Zihan Zheng have been asking frontier LLMs the same question: "what do you know about USTC Hackergame?", a CTF contest. May 2024: GPT-4o invented fake titles. Feb 2025: Claude 3.7 Sonnet listed 19 verified 2023 challenges. By April 2026, frontier models recall specific challenges across consecutive years.
After DeepSeek-V4 dropped, I instructed my agent to spend four days autonomously turning that habit into Incompressible Knowledge Probes (IKP) — 1,400 questions, 7 tiers of obscurity, 188 models, 27 vendors. Three findings:
1/ You can approximately size any black-box LLM from factual accuracy alone. Penalized accuracy is log-linear in log(params), R² = 0.917 on 89 open-weight models from 135M to 1.6T params. Project closed APIs onto the curve → GPT-5.5 ~9T, Claude Opus 4.7 ~4T, GPT-5.4 ~2.2T, Claude Sonnet 4.6 ~1.7T, Gemini 2.5 Pro ~1.2T (90% CI: 0.3-3x size).
2/ Citation count and h-index don't predict whether a frontier model recognizes a researcher. Two researchers with similar citation profiles get very different responses. Models memorize impact — work that shaped a field, not many incremental papers.
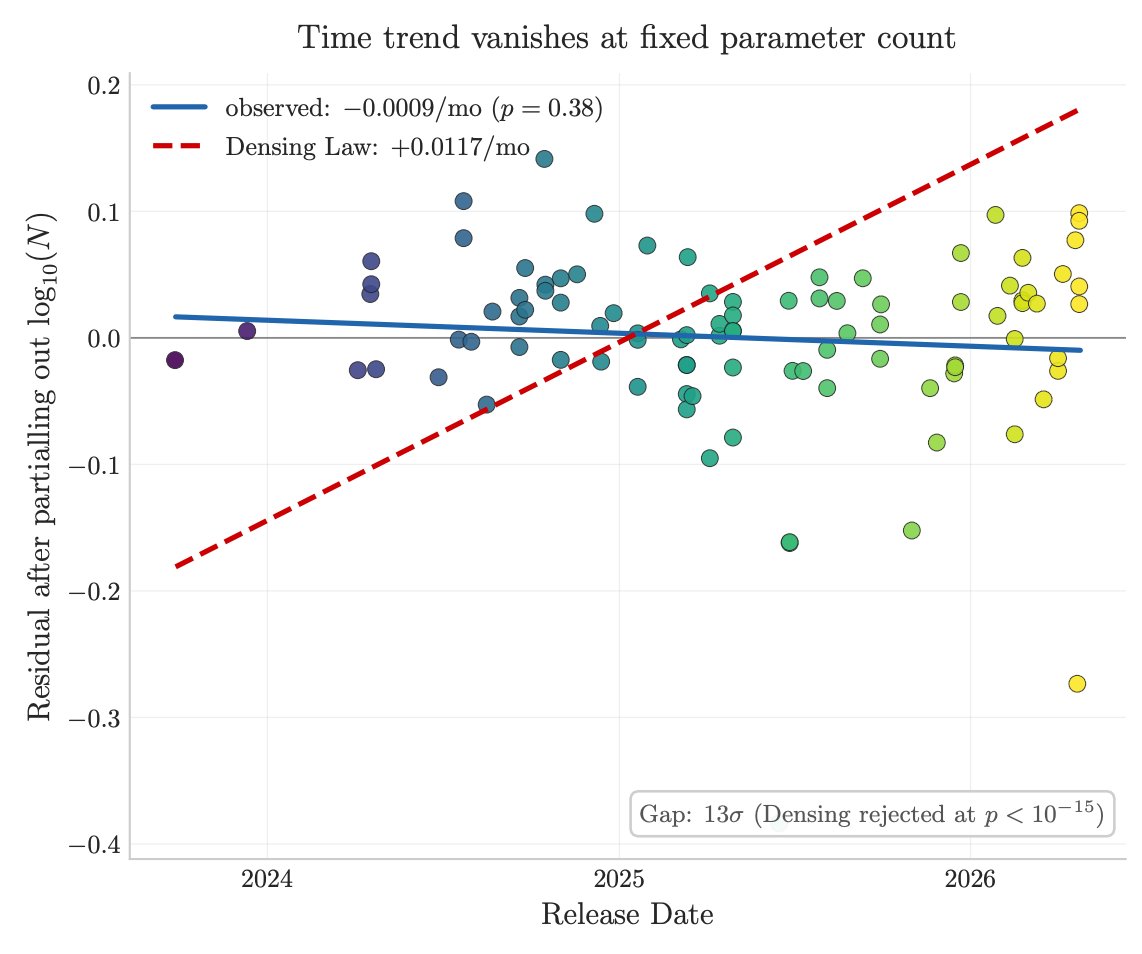
3/ Factual capacity doesn't compress over time. Across 96 open-weight models across 3 years, the IKP time coefficient is statistically zero, rejecting the Densing-Law prediction of +0.0117/month at p<10⁻¹⁵. Reasoning benchmarks saturate; factual capacity keeps scaling with parameters.
Website: https://t.co/CkwJsXqnsX
Paper: https://t.co/eNUdC9ye7w
🚀 DeepSeek-V4 Preview is officially live & open-sourced! Welcome to the era of cost-effective 1M context length.
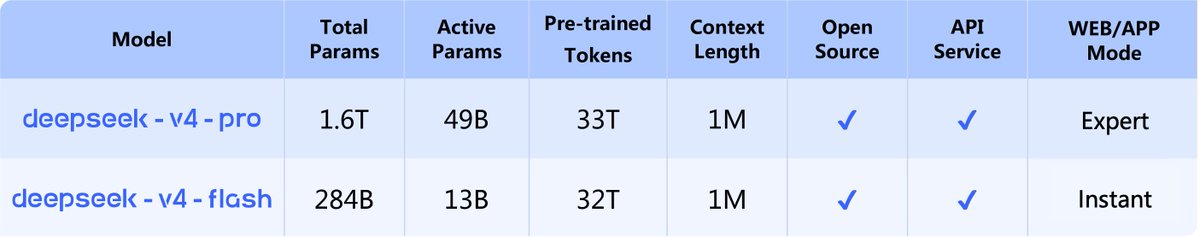
🔹 DeepSeek-V4-Pro: 1.6T total / 49B active params. Performance rivaling the world's top closed-source models.
🔹 DeepSeek-V4-Flash: 284B total / 13B active params. Your fast, efficient, and economical choice.
Try it now at https://t.co/GCdiMzk1Dl via Expert Mode / Instant Mode. API is updated & available today!
📄 Tech Report: https://t.co/drlDrxkYtp
🤗 Open Weights: https://t.co/T13Y8i7SDM
1/n