Stop wasting time typing long emails or docs. This AI tool lets you speak naturally and pastes the text directly into any application on your computer.
Unlike cloud-based competitors, Voice Typer runs entirely on your local hardware.
https://t.co/xVEUrCZTf5
Introducing Claude Sonnet 5.5, the second model in the Claude 5.5 family.
It’s a clear upgrade over Sonnet 5, runs more than 30% faster, and costs up to 30% less for most work.
Introducing Claude Opus 5.5, the first model in our new Claude 5.5 family.
It performs at the level of Claude Fable 5.1 for most tasks, and costs 40% less to run than Opus 5.
Thay gave GPT 5.6 Sol a business for 24 hours. It spammed users, paid testers to buy its own app, slashed prices 6 times, crashed its Mac and made $0 in revenue. 320.7M tokens, 1,129 tool calls, -$99.50. Frontier agents can be resilient AND dangerous. https://t.co/vmdRS0apy5
Opus 5 is a great model for coding, data analysis, design, biology, knowledge work.
More than any of these eval scores, what is most exciting to me is something else: Opus 5 is our least prompt injectable model yet. It is a bit buried in the system card, but across PI evals and red teaming, Opus 5 is very hard to prompt inject successfully.
And when layering defenses -- strong model alignment, combined with prompt injection probes, combined with Auto Mode in Claude Code -- the success rate for prompt injection attacks drops to ~0. This is new and exciting! More about this soon.
https://t.co/Tc7z2FqJhQ
Big news in AI today! 🚀 Anthropic just officially dropped Claude Opus 5 - delivering Fable-level reasoning and complex coding at half the price. It features enhanced self-correction, long-running agentic workflows, and deep document analysis.
https://t.co/AlDVfZW6Zx
🚀 The NVIDIA Vera Rubin platform is here, with 10x better performance per watt.
➡️ The NVIDIA ecosystem, including @CoreWeave, @GoogleCloud, @Microsoft, and @Oracle Cloud, are standing up NVIDIA Vera Rubin NVL72 to deliver the lowest token cost for the agentic era.
➡️ NVIDIA Vera Rubin NVL72 on CoreWeave demonstrates 10x more tokens per megawatt than Blackwell in their first measured performance.
➡️ Benchmark results from @DeepInfra show that the NVIDIA Vera CPU is more than 2x as fast and can support more concurrent AI agents compared with other CPUs.
🔗 Read more: https://t.co/zUiuLZli63
We've updated our "zoom tool" cookbook.
When large images get downscaled, important detail can be lost. A zoom tool lets Claude request a region and get that crop back from the full-res original.
One pattern I find useful for working with LLMs is a nice long ramble session. Sometimes the LLM needs more bits to understand what you're trying to achieve, but you're too lazy to type them. In these cases I like to lean back, switch to /voice and just ramble for like 10 minutes, total mess, anything goes, full stream of consciousness. Sometimes I declare it up top, something like "switching to speech recognition sorry for any typos...". Sometimes I turn it into a small interview of a few turns. But I find that the LLMs are somehow very good at reconstructing long incoherent rambles and often their echo of your own tangle of thoughts comes out quite a bit cleaner than what you started with. The result is that you improve the mind meld and have to correct things less from that point on.
We’re rolling out three new models to make AI agents faster, smarter, and cheaper at scale:
🔵 Gemini 3.6 Flash: It uses fewer tokens than 3.5 Flash to deliver higher quality work at the exact same cost.
🔵 Gemini 3.5 Flash-Lite: A fast, cost-effective option for everyday tasks like processing documents and agentic search.
🔵 Gemini 3.5 Flash Cyber: A cybersecurity model built to find and patch critical software vulnerabilities.
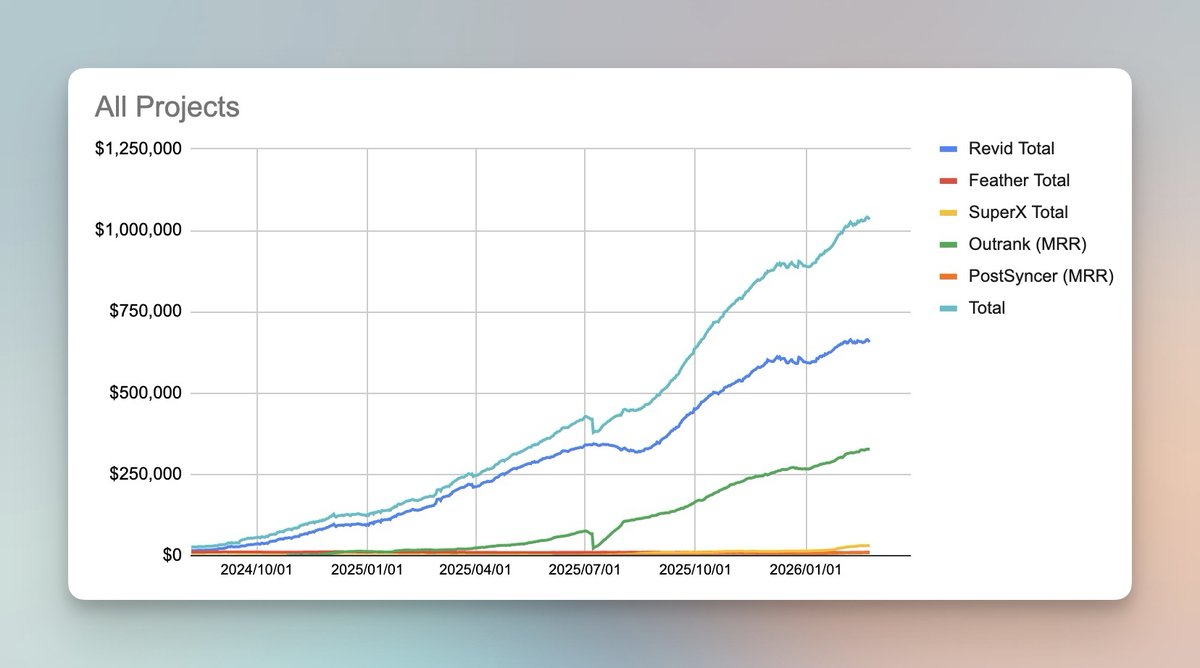
yes, I crossed $1,000,000 / month
was trying to keep it quiet but it got leaked on a pod so... let's go
quick backstory:
I sold Tweet Hunter and Taplio for $8m in 2024
then got back to work
and honestly, I was terrified
when you set a standard for yourself, you have to live by it and that pressure is real
every single thing I shipped felt scary - I felt like a fraud, "the lucky guy who got acquired once"
every launch, I kept thinking:
what if it flops?
what if I go from "the guy who exited" to just... a nobody?
so I forced myself to ship a ton
a lot failed
I was embarrassed by the bugs in my MVPs
but I kept going
Revid, Outrank, SuperX, PostSyncer, Feather -> five products thriving
today they do more than anything I've ever built before
grateful to my co-makers, to the team, and to everyone following along, giving feedback, using the products every day
thank you, genuinely 🙏
Qwen3.8 is launching and going open-weight soon!🌐
With a massive 2.4T parameters, this model is continuously evolving. We believe it’s one of the most powerful model available today, compatible to leading frontier AI models , second only to Fable 5.
You don't have to wait to test it. Just now, the Qwen3.8-Max-Preview made its debut on Alibaba’s Token Plan, Qoder, and QoderWork. Be among the very first to try it out.
Can't wait to hear what you build. Stay tuned! 🚀
Token Plan
international:https://t.co/YRvcGdB9Bv
China:https://t.co/PKMUNwUuRp
Meet Voice Typer, local speech to text for Windows that works wherever you write.
Use Quick Mode to speak and paste the final transcript straight into the active text field.
Or use Full Mode to follow a live transcript and edit it before using it.
https://t.co/epKhTROoQt
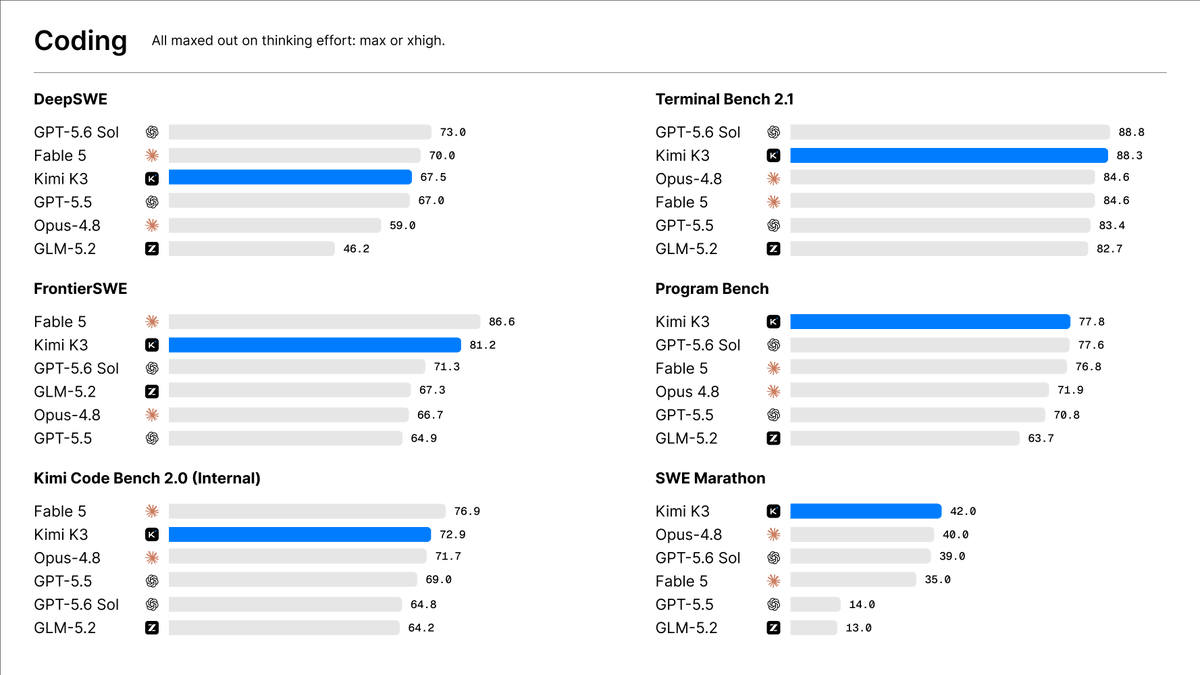
Introducing Kimi K3: Open Frontier Intelligence
🔹 2.8 Trillion Parameters, 1 Million Context, Native Multimodal
🔹 Kimi Delta Attention enables up to 6.3x faster decoding in million-token contexts
🔹 Attention Residuals deliver ~25% higher training efficiency at <2% additional cost
🔹 Built for long-horizon agentic coding and self-evolving workflows
Kimi K3 is now live on on https://t.co/zrk6zZxZUo, Kimi Work, Kimi Code, and the Kimi API.
Open Weights by July 27, 2026.
🔗 API: https://t.co/XCrgjXAqMw
🔗 Tech blog: https://t.co/YTfiMSNM1f
Moonshot AI unveils Kimi K3: 2.8T-parameter open-weight model, 1M-token context, native vision. Largest open model yet; weights by Jul 27. https://t.co/9f3VsbovUZ
Google DeepMind + Isomorphic Labs detailed their bioresilience plan: AI for prevention, detection & response to biological threats. 15+ partnerships in 12 months. https://t.co/Y0UbPbGbq3 https://t.co/Y0UbPbGbq3
Introducing GPT-Red
An internal automated red teamer on a mission to find our models’ prompt injection vulnerabilities at scale, helping us build stronger defenses before wider deployment.
https://t.co/GxnmxxcpSk
Fable 5 totally crushed our new contest, but it cost 6x more than Opus 4.8!
We gave 4 models the same prompt: build three self-contained HTML5 canvas scenes with real physics demos
Prompts:
— A train derailing off a broken bridge into the water
— Two cars jumping off ramps and colliding mid-air over a canyon
— A monster truck crushing a row of parked cars
Outputs:
Fable 5: 62,158 tokens, $3.12
GPT 5.5: 37,753 tokens, $1.14
Opus 4.8: 22,280 tokens, $0.56
GLM 5.2: 36,246 tokens, $0.08
Fable 5 did all three scenes at A+. The crashes looked real, things fell and broke the right way, and nothing went through the ground or floated. GPT 5.5 was the closest to Fable. In the Bigfoot show, we think GPT was even a little better. GLM 5.2 did not win any scene, but it was the cheapest by far. Fable is the best pick for quality, but you pay more for it.
Anthropic restores Claude Fable 5 globally after 19-day US export-control suspension. New multi-layer safety classifier added. Mythos 5 remains restricted to Glasswing partners.
https://t.co/QEmsDxFnus