🚨Our new paper is out: Model Casting and Low-Parameter Gating: Towards More Sparsely Activated FFNs
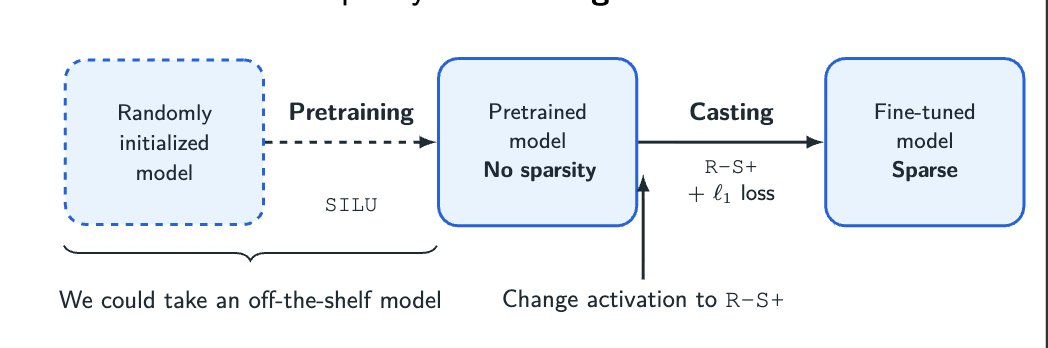
We present model casting, a mid-training recipe that drastically sparsifies the activations within the FeedForward Network layer of a transformer. Model casting consists of switching to an activation that outputs zeros for all negative inputs (R-S+) and using an L1 loss to set the required sparsity as a target at training time.
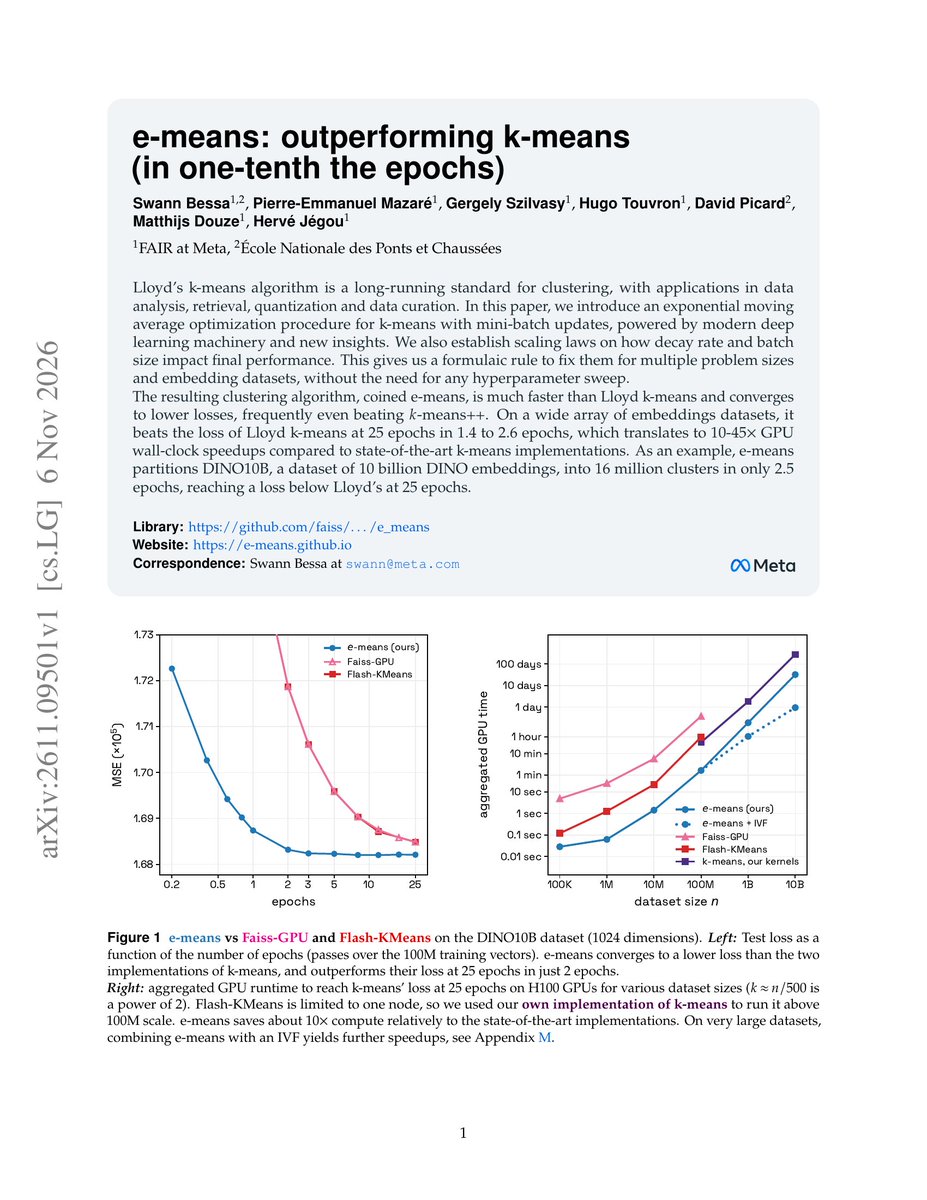
Introducing e-means, an algorithm beating k-means in 10x fewer epochs.
With order of magnitude wall-clock speedups, e-means is released in FAISS and needs no hyperparameter tuning beyond k. It is robust to various scales and datasets. Still skeptical ? Just try e-means [1/10]🧵
PhD applications at @GatsbyUCL are open!
Full funding available regardless of nationality.
Includes ✨new✨ Jump Trading studentships in AI with potential application to finance, eligible for employment opportunities with Jump Trading during PhD.
Deadline: 🚨November 9th🚨
📍 Paris · 24-week internship
You'll be following in the footsteps of @MekalaDheeraj, @ulyanapiterbarg , @nehzux and part of a vibrant team https://t.co/CORjaW4EgJ
Apply here: https://t.co/0yluUugGJB
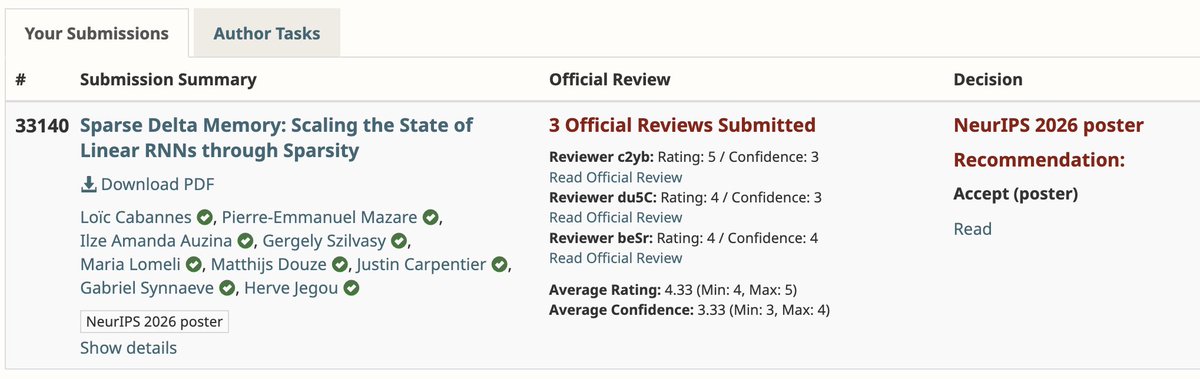
Very happy to announce that Sparse Delta Memory (SDM), has been accepted at #Neurips2026 and I'll be presenting it in Sydney at the main conf in December!
Very happy to announce that Sparse Delta Memory (SDM), has been accepted at #Neurips2026 and I'll be presenting it in Sydney at the main conf in December!
Very glad to share the technical talk @maryamfazel and I gave at Meta Connect on how we built Muse Glimmer, our open-weight AI for local agents: goals, pre-training, mid-training, post-training, distillation, quantization, inference and benchmarks: https://t.co/se9mhU0lid
🚨Our new paper is out: Model Casting and Low-Parameter Gating: Towards More Sparsely Activated FFNs
We present model casting, a mid-training recipe that drastically sparsifies the activations within the FeedForward Network layer of a transformer. Model casting consists of switching to an activation that outputs zeros for all negative inputs (R-S+) and using an L1 loss to set the required sparsity as a target at training time.
Furthermore, our technique works with off-the-shelf models such as Qwen3-1.7B and extends to MoE models. For further details please see our Arxiv paper: https://t.co/bP05y7Qzpy
AI4Maths: we’re hiring!
My team at Meta FAIR in Paris has postdoctoral and full-time research positions open.
Come join us if you’re excited about:
- Making frontier models better at maths
- Proof assistants and formalizing mathematics at scale
- Working hand in hand with the mathematical community to shape the future of mathematics—beyond “big model solves big problem”
Apply here:
Postdoc: https://t.co/ig4LQM0Tyd
Research Scientist: https://t.co/kwFwhOdhDo
Research Scientist: https://t.co/6H4k0VLnlW
@AIatMeta
Interested in a #PhD in machine learning & theoretical neuroscience?
Applications for 2027 entry to the Gatsby Unit PhD programme now open!
💰 Fully-funded 4-year programme
🤝 Close links to Sainsbury Wellcome Centre & the ELLIS Unit @ UCL (@uclcsml)
ℹ️ https://t.co/Im1iRIbQx2