At @datologyai we run thousands of data experiments. Two things keep biting us:
- Same run on 16 vs 8 GPUs → different evals
- Every pipeline change → re-materialize the dataset
Introducing Zephon, the data loader we built to process data on the fly, deterministically. 🧵
@lancedb@modal@josh_wills@datologyai New to Zephon?
It's @datologyai's open-source, elastically deterministic data loader: process data on the fly, get the same training batches on 8 GPUs or 16.
Why we built it: https://t.co/wg8gZzzlGf
Docs: https://t.co/SeX3rOykkM
Code: https://t.co/VO3KgF2hSe
Zephon launched two weeks ago. v0.2 is out today.
→ Use data stored in your @lancedb tables
→ Run on @modal & setups w/o a shared FS
→ Mixture weight redistribution
→ More zero-copy ops + reliability fixes
w/ @josh_wills & the @datologyai team
uv pip install -U zephon
Awesome to see Zephon, our recently open sourced data loader, integrated with @PyTorch TorchTitan!
Check out their blog, and congrats to @MaxiBoether, @josh_wills, and @SGui.
We're just getting started with Zephon!
Very happy that the Zephon team and Pytorch/Torchtitan are working together to make data loading more deterministic.
Check out our example integration: https://t.co/meybrF6wVi
Check out our blog post together with the folks at Meta 👇
Zephon’s TorchTitan integration preserves identical global batches when training resumes on a different GPU count.
In our latest blog’s 1B-parameter model test, training resumed from a 16-GPU checkpoint on 8, 32, and 64 GPUs, and the SHA-256 hash of every global batch matched the original run.
Zephon tokenizes, packs, shuffles, and mixes data inside the training job, avoiding a preprocessed copy of the corpus.
The data, tokenizer, seed, mixture, context length, and global batch size must stay unchanged when resuming. The lane count must divide evenly across data-parallel replicas, and each optimizer step’s batch must split evenly across lanes. Training losses can still differ because floating-point reduction order depends on GPU count.
✍️ @datologyai@josh_wills@MaxiBoether, Ties Robroek (@datologyai)
Read more: https://t.co/JKn45hQIgU
MosaicML’s Streaming dataloader was one of the most underrated pieces of ML infrastructure ever built imo. It spoiled me. One of my goals when founding Datology was to take all the best things about Streaming and build its torchbearer. Because well-designed dataloaders enable entire domains of data experimentation like real-time curricula, arbitrary mixing schedules, and seamless transitions between pre- and post-training. And even better-designed dataloaders enable productionizing and scaling those experiments. I am so excited that we're finally releasing Zephon. It leveled up Datology and we think it'll level you up, too.
A data loader is only as useful as the data it loads. This is why this week is so exciting: we're sharing our Curation Studio and how we use it to generate the best tokens (or raw strings to be tokenized and packed on-the-fly) possible. Check out our release announcement!
Today, we’re excited to launch the Datology Curation Studio, customizable frontier data curation for every team training its own models.
Data quality is the ultimate compute multiplier, and Curation Studio makes it easy for everyone.
thanks - great Q! first of all, we probably should dig a bit more into this (noted it down).
the problem here is that your MoE training framework can change the way it routes tokens when the GPU topology changes. Zephon can fully support elastic determinism but from the data loader end, we cannot influence what your training framework does. In our research paper, that's why we define elastic determinism as a data loader guarantee: loss curves may not fully overlap if the training framework doesn't do the right thing. It depends on the routing implementation and what changes during resizing.
We have example torchtitan and megatron integrations but we haven't validated this yet, the paper plots were generated using dense models. it's not strictly something Zephon can even influence, but let us check our example integrations! great question, and this is where the data loader <> training framework integration gets tricky.
@josh_wills wrote an article on that here: https://t.co/uBCO0NqHt1(what Zephon can influence and what it cannot)
At @datologyai we run thousands of data experiments. Two things keep biting us:
- Same run on 16 vs 8 GPUs → different evals
- Every pipeline change → re-materialize the dataset
Introducing Zephon, the data loader we built to process data on the fly, deterministically. 🧵
@vishaal_urao Thanks so much Vishaal! It‘s a niche but part of every training run indeed :) and even important for curation, curricula, active batch selection etc are all data loader problems
@EitanTurok@datologyai SPDL is also an interesting candidate to look at for GIL-free data loading -- it really depends on what you want and need :)
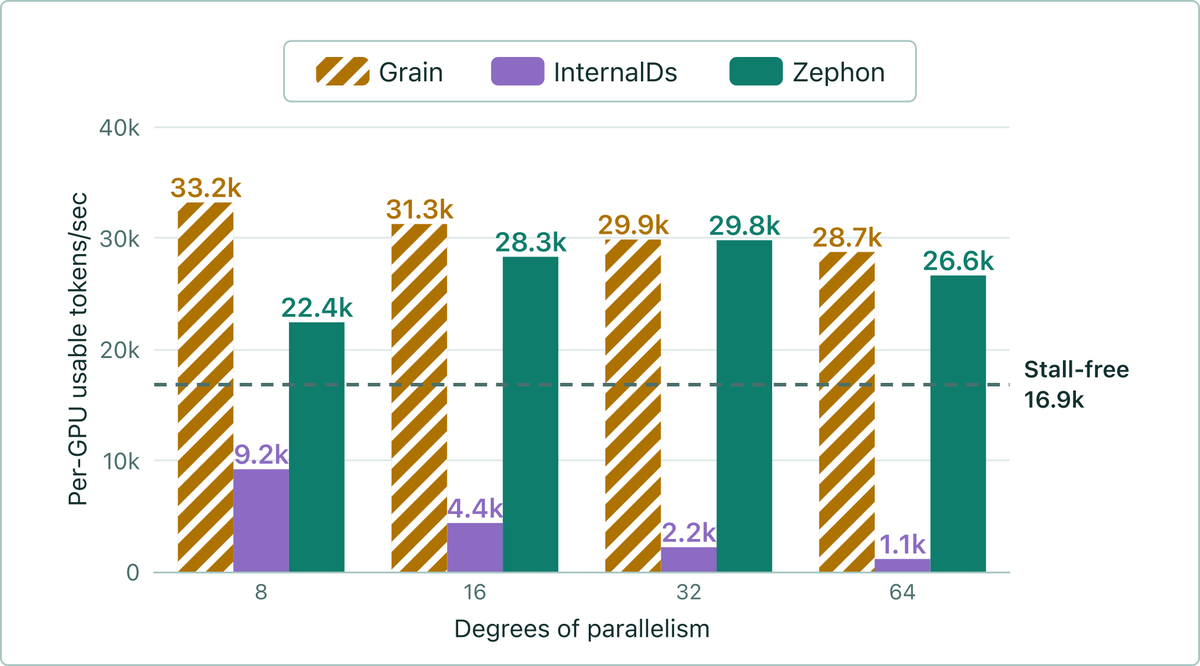
that being said, Zephon hits those trade-offs in a way we believe is sensible, and we've done a good amount of eng work to make it fast.
@EitanTurok@datologyai thanks Eitan! It's hard to say what's best: we really loved Mosaic Streaming, but Google Grain is also popular, and Megatron-Energon gets as close to elastic determinism as we have seen.
It's a trade-off between feature set and speed, and depends on how you write your pipeline.
@datologyai [10/] This is a collaboration with many amazing people at @datologyai: @josh_wills, Ties Robroek, @hurrycane, @arimorcos, and many more, but of course also my PhD supervisor @anaklimovic was a tremendous help over the course of the project.
Please reach out if you’re interested!
@datologyai [9/] Tweets are way too short to cover the pitfalls around state management in data loading and offline materialization. Hence we wrote a whole blog post around it: https://t.co/OXLMl0tS2D
We’re also excited to share our research paper: https://t.co/ftvnQwvYf8