Today we’re unveiling Odyssey-3, a big step forward for foundation world models.
It can control robots, power humanoids, drive cars (on the roads of India!), train AIs, pilot drones, and even play video games.
We can’t wait to see what intelligent systems it enables.
🚀Tired of floaters, flickering, and blur in 3DGS? We introduce a geometry-informed video generator that refines 3DGS renderings in the wild. 🎥✨
We let the video model actually "see" the rendering process using a Gaussian Primitive buffer. #CVPR2026@CVPR
Project page: https://t.co/IjE8h0QVuS
🔥 Highlights:
✅ Geometry-Buffer-conditioned video generator
✅ Refines optimization-based & feed-forward 3DGS
✅ Novel artifact simulation pipeline
✅ Highly efficient bidirectional processing ⚡
Thread 👇
Check out our #ICLR2026 paper Generative View Stitching!
I unfortunately couldn’t attend but @MichalStaryy will be presenting our poster tomorrow (Sat) morning at Pavillon 4 PA-#3016.
Shoutout to my other collaborators @BoyuanChen0, @gkopanas, and @vincesitzmann!
Check out our #ICLR2026 paper Generative View Stitching!
I unfortunately couldn’t attend but @MichalStaryy will be presenting our poster tomorrow (Sat) morning at Pavillon 4 PA-#3016.
Shoutout to my other collaborators @BoyuanChen0, @gkopanas, and @vincesitzmann!
Zhu et al., "GaussFusion: Improving 3D Reconstruction in the Wild with Geometry-Informed Video Generator"
Another diffusion "fixer" BUT with now a geometry buffer (providing all the info about what IS being rendered)
Makes sense. Matching and 3D reconstruction are inherently iterative computations; this nice paper gives hints on how DUSt3R's transformer achieves that. Now we can get on with figuring out how to do it tens or hundreds of times better/faster with a more specific architecture.
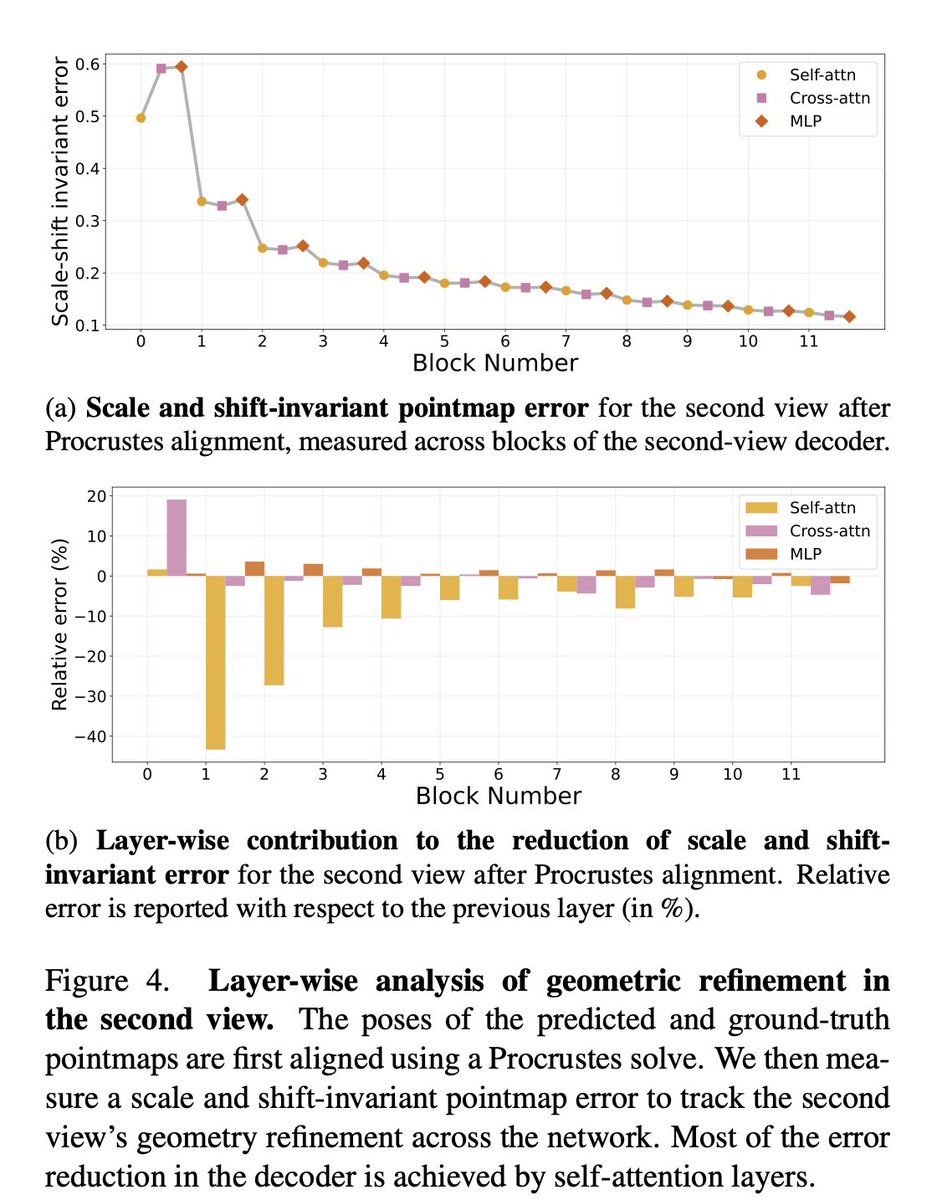
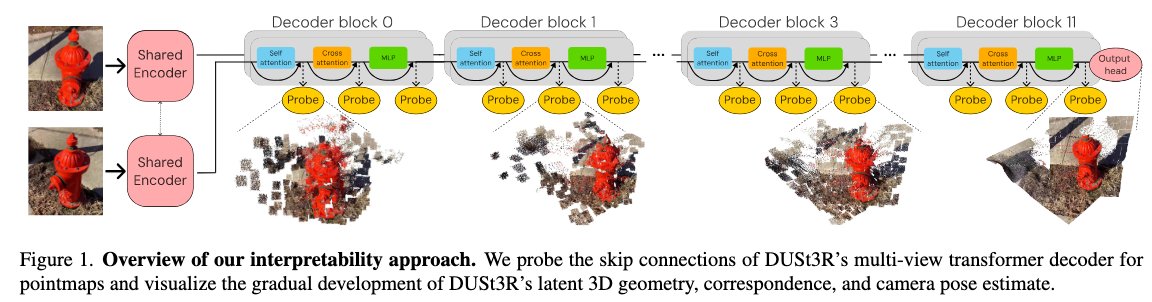
Understanding Multi-View Transformers
Michal Stary @jgaubil@_atewari@vincesitzmann
tl;dr: DUSt3R self-attention is it secretly a diffusion model, and cross-attention is matching.
https://t.co/UR9agpjD8M
Did you ever want to navigate an 18 story mansion? Well, now you can do that without even retraining your Diffusion Forcing video model.
Check the excellent work we did with @ndsong95@MichalStaryy@BoyuanChen0@vincesitzmann
https://t.co/K6dvZgTUUi
Stary and Gaubil et al., "Understanding multi-view transformers"
We use Dust3r as a black box. This work looks under the hood at what is going on. The internal representations seem to "iteratively" refine towards the final answer. Quite similar to what goes on in point cloud net
DUSt3R et al. are impressive, but how do they actually work?
We explored this, and share insights on iterative reconstruction, the roles of cross- and self-attention, and emerging correspondences across the network [1/8] ⬇️
Checkout our latest work on long-video generation! Contrary to autoregressive rollouts, GVS respects a predefined long-horizon camera trajectory and generates worlds that never collide. Unlocking generation of 18-floor houses without running through the walls and much more!
Introducing Generative View Stitching (GVS), a non-autoregressive sampling method for length extrapolation of video diffusion models. GVS enables collision-free camera-guided video generation for predefined trajectories, including Oscar Reutersvärd's Impossible Staircase (1/9).
Introducing Generative View Stitching (GVS), a non-autoregressive sampling method for length extrapolation of video diffusion models. GVS enables collision-free camera-guided video generation for predefined trajectories, including Oscar Reutersvärd's Impossible Staircase (1/9).